OpenCodeReview: A Hybrid Deterministic and Agentic Code Review CLI
Alibaba Open Code Review combines deterministic checks with a language-model agent to produce line-level findings for issues such as null access, concurrency errors, XSS, and SQL injection.
At a glance
- What is it?
- Alibaba's OpenCodeReview combines deterministic engineering with an LLM agent to deliver line-level findings on Git diffs. It prioritizes precision over recall, trading some issue discovery for fewer false alarms.
- Who is it for?
- Adopt OpenCodeReview if you run large Git-based codebases, want to reduce false positives in AI review, and can accept lower recall. It is not the right tool if you need maximum issue discovery regardless of noise, or if you cannot meet its Git >= 2.41 prerequisite.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
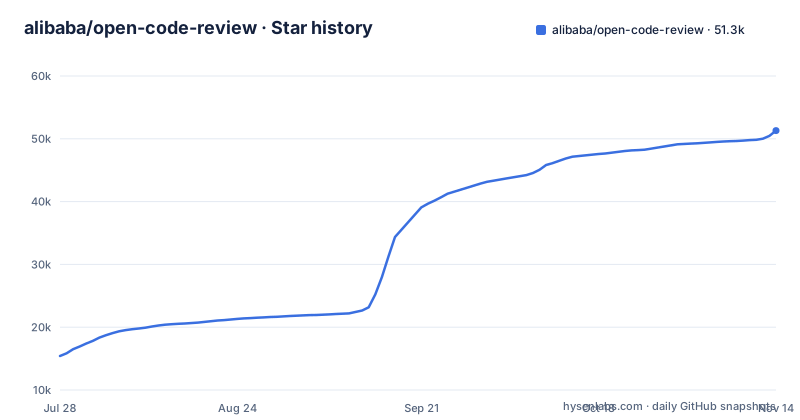
Star history
- alibaba/open-code-review51,300 ★ · +35,886
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| alibaba/open-code-review | 15.4k | 51.3k |
35,886 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: General-Purpose Agents Drift and Cut Corners
The README describes general-purpose agents like Claude Code with Skills as the baseline. It lists three documented pain points in the README: incomplete coverage on large changesets, position drift where line numbers do not match the actual code, and unstable quality from minor prompt variations. The root cause, as the project states, is that a purely language-driven architecture lacks hard constraints on the review process. OpenCodeReview addresses this by splitting the work. Deterministic engineering handles file selection, bundling, and rule matching. The agent only handles dynamic decisions like context retrieval. This separation is the core design bet, and it is a deliberate one.
Deterministic Engineering: Hard Constraints on the Review Process
The deterministic layer guarantees correctness for steps that must not go wrong. Precise file selection determines exactly which files need review and which should be filtered. Smart file bundling groups related files into a single review unit; the README gives the example of message_en.properties and message_zh.properties being bundled together. Each bundle runs as a sub-agent with isolated context, which is a divide-and-conquer strategy that stays stable on very large changesets and supports concurrent review. Fine-grained rule matching applies review rules to each file's characteristics, keeping the model's attention focused and eliminating information noise. There are also external positioning and reflection modules that improve location accuracy and content accuracy of AI feedback. These are not LLM-driven; they are engineering logic.
The Agent's Role: Dynamic Decisions and Tool Use
The agent side is scenario-tuned. Prompt templates are optimized for code review, which reduces token consumption. The toolset is distilled from analysis of tool-call traces in production data, including call frequency distributions and per-tool repetition rates. The agent can read full file contents, search the codebase, and inspect other changed files for context. That goes beyond surface-level diff feedback. The README claims this design consumes roughly one-ninth of the tokens of a general-purpose agent while achieving higher precision and F1 with the same underlying model. The trade-off is explicit: recall is lower. The project frames this as a deliberate choice favoring precision over noise.
Getting Started: Install, Configure, and Run
The CLI is installed via npm: npm install -g @alibaba-group/open-code-review. This makes the ocr command available globally. Before reviewing, you must configure an LLM, unless you use Delegation Mode. Configuration is done with the ocr config command. The prerequisite is Git >= 2.41, because the tool relies on Git for diff generation, code search, and repository operations. There is also an ocr scan command that reviews entire files, useful for auditing unfamiliar codebases or directories with no meaningful diff.
The Benchmark: Precision Over Recall, Measured on Real PRs
The project publishes a benchmark called AACR-Bench, available on Hugging Face. It is built from 50 popular open-source repositories, 200 real pull requests, and 10 programming languages, cross-validated by 80+ senior engineers with 1,505 annotated ground-truth issues. The metrics are F1, precision, recall, average time, and average token count. The README claims that compared to Claude Code, OpenCodeReview achieves significantly higher precision and F1 while consuming about one-ninth of the tokens and completing reviews faster. Recall is lower. This is a real trade-off. If your team is drowning in false positives from other tools, this design is attractive. If you need to catch every possible defect, the lower recall is a genuine limitation.
Limitations and Wrong-Tool Cases
The most obvious limitation is the deliberate recall trade-off. The README states it plainly: recall is lower than general-purpose agents. That means some real defects will be missed. The tool is also tied to Git; it requires Git >= 2.41, so any repository that does not use Git is out of scope. The deterministic layer depends on file bundling and rule matching, so unusual file groupings may not be bundled the way you expect. The tool also requires an LLM endpoint, which adds cost and latency, though the token reduction helps.
Alternatives: General-Purpose Agents vs. Dedicated Tools
The primary alternative is a general-purpose agent like Claude Code with Skills for code review. The README explicitly compares against this. General-purpose agents offer higher recall but suffer from position drift, incomplete coverage on large changesets, and unstable quality. They also consume more tokens, roughly nine times as many per review according to the benchmark. Another alternative is a traditional deterministic linter or static analysis tool, but those work from fixed rules rather than an agent reading the surrounding code. OpenCodeReview sits in between: deterministic for structure, agentic for semantics. If you already use Claude Code, you can compare the two on your own PRs using the AACR-Bench methodology. The choice depends on whether you value precision or recall more.
Maintenance and License Implications
The project is licensed under Apache-2.0, which permits commercial use, modification, and distribution, with the condition of retaining the license notice. The repository is actively maintained, with recent releases v1.13.4, v1.13.3, and v1.13.2 published between 2026-10-20 and 2026-11-02. The release cadence is frequent, suggesting ongoing fixes and improvements. Upgrade cost is low because the tool is a CLI; you can update via npm install -g @alibaba-group/open-code-review@latest. Check the release notes on GitHub for breaking changes before upgrading. The token reduction is a cost advantage, but you still pay for LLM API usage.
Editorial conclusion
Adopt OpenCodeReview if you run large Git-based codebases, want to reduce false positives in AI review, and can accept lower recall. It is not the right tool if you need maximum issue discovery regardless of noise, or if you cannot meet its Git >= 2.41 prerequisite. Before adopting, verify that your chosen LLM endpoint supports the tool-use calls the agent makes, and test the precision on a sample of your own pull requests against the AACR-Bench methodology. Confirm that the deterministic file bundling and rule matching behave as expected on your monorepo structure.
Frequently asked questions
how to use opencode review
Install with `npm install -g @alibaba-group/open-code-review`, which makes the `ocr` command available globally, then run `ocr config` to point it at an LLM endpoint. Git 2.41 or higher is required. The tool reads git diffs and generates structured review comments with line-level precision.
how to use opencode review command
Two of the commands named in the documentation are `ocr config`, which configures the model endpoint, and `ocr scan`, which reviews entire files rather than a diff for auditing unfamiliar code. A configured LLM is required before reviewing code unless you use Delegation Mode.
Does Open Code Review replace a general-purpose coding agent for review?
The project's own benchmark does not claim that. Against Claude Code on the same underlying model it reports higher precision and F1 with roughly a ninth of the tokens, while stating that its recall is lower, which it calls a deliberate trade-off favoring precision over noise.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/alibaba-open-code-review)Star history chart for your README
[](https://hysenlabs.com/projects/alibaba-open-code-review)Was this useful?