AnakinScraper's handler chain: HTTP first, Camoufox only when it fails
Open-source web scraping API. Turn any website into clean markdown or structured JSON. Anti-detect browser, proxy auto-selection, self-hosted. One command: make up
At a glance
- What is it?
- AnakinScraper is a self-hosted Go scraping API that turns pages into markdown or Gemini-extracted JSON, built for RAG pipelines and AI agents that need page text rather than a browser session. Its bet is that most pages never need a browser, and that only the hard remainder should cost money.
- Who is it for?
- Adopt it if you want one Go binary that returns LLM-ready markdown and you control the network it scrapes from. Do not adopt it if you need guaranteed structured extraction on JavaScript-heavy sites, because those sites pay the browser and API handler costs on every request.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 88 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
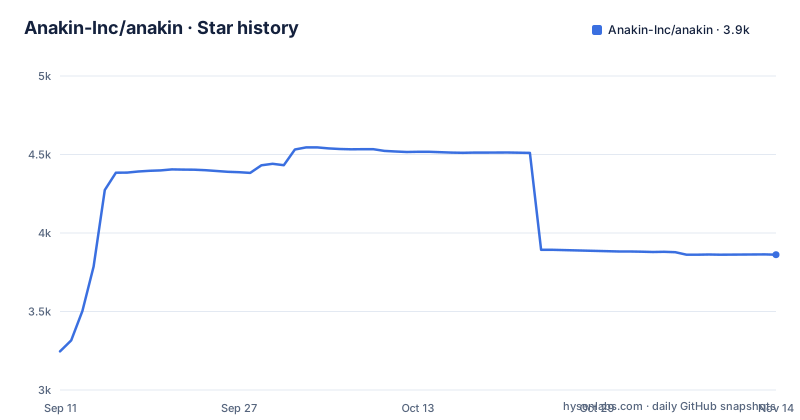
- Anakin-Inc/anakin3,862 ★ · +616
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| Anakin-Inc/anakin | 3.2k | 3.9k |
616 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The chain starts at HTTP and only escalates when a page breaks
Every scrape in AnakinScraper runs through an ordered list of handlers rather than a single fetch path. The first is a plain HTTP request. If that returns something the domain config considers unusable, the second handler opens a Camoufox browser, which is an anti-detect Firefox build with realistic fingerprints. If the browser handler also fails, a third handler can call out to an external scraping API. That third step is optional: it only exists if you set an API key for a provider, and the anakin.io handler is wired in that way.
The reason this ordering matters is cost. A paid scraping API charges per request whether or not the page was hard, so routing every URL through one burns money on the ordinary majority. AnakinScraper claims the free local HTTP handler resolves most pages and that paid calls land on roughly the five percent that genuinely need them. Nothing in the repository proves that ratio; it is a design estimate written into the README, and your traffic mix will decide whether it holds.
What the chain is not is a per-request policy engine. The order of handlers is configured per domain, not per individual request, so you cannot ask for a cheap HTTP-only attempt on one call and a browser on the next. You choose a domain config, and that config applies to every URL matching it.
Domain configs are where failure detection and handler choice collide
The interesting file is not the README but the per-domain config. For each domain you choose which handlers run, set timeouts and retries, attach custom headers, and mark some domains as blocked outright. Two fields carry the real weight: failure patterns and required patterns.
A failure pattern is a regex describing content that means the scrape did not really work, such as a CAPTCHA interstitial or a login wall. A required pattern describes content that must appear. Miss either check and the job is not returned as a successful scrape. It is retried with the next handler in the chain, so the browser gets a second attempt precisely because the cheap attempt came back with a challenge page rather than the article.
This is the mechanism that makes the chain more than a retry loop, and it is also where a domain config can hurt you. A required pattern tuned too tightly will reject pages that are legitimately fine, an article that is temporarily shorter, a product page that lost its price element, and every retry then pays for the browser handler. A failure pattern written too broadly does the same thing in the other direction by rejecting good HTML. There is no default tolerance here; the patterns are yours to write, and the README does not document any way to inspect why a particular job failed on a pattern match.
Because these configs are writable through the REST API, the write endpoints are the part of the surface that needs the most care.
Three containers, three ports, and a browser you only need sometimes
The full stack is defined in docker-compose.yml and it is small. PostgreSQL 16 on port 5432 holds job history, the browser service publishes the Camoufox WebSocket on 9222 plus a health port on 8090, and the Go server sits on 8080. The server waits for both dependencies to pass their health checks before starting, so a failed browser build delays the API rather than degrading it into a broken fallback chain.
You do not have to run any of that. The server is a single Go binary that starts with no database, which means an in-memory job store and no history across restarts. Set DATABASE_URL and the same binary persists jobs instead. That split is the deployment decision: the zero-config path is genuinely one process, but it forgets everything the moment it restarts, which matters if you are using the job list as an audit trail rather than a convenience.
The environment file also carries the knobs you would expect a scraping service to need. WORKER_POOL_SIZE defaults to 5 and JOB_TIMEOUT to 120 seconds, while the synchronous scrape endpoint defaults to a shorter 30 second timeout that a caller can raise through the timeout request field up to 120. BROWSER_LOAD_WAIT is set to 2, which reads like a fixed pause before the browser considers a page loaded, a small wait that is cheap for most sites and too short for some.
An empty API_KEY leaves the whole instance open, and domain configs are the prize
The .env.example ships with API_KEY= empty and a comment saying an empty value leaves the instance open, safe only when the port is not reachable by anything untrusted. Domain config writes always require a key regardless. The reasoning is sound because domain configs decide which handlers run, what headers get sent, and which domains are blocked, so an open write endpoint is a configuration takeover rather than a minor leak.
The same file documents a guard that is easy to miss. ALLOW_PRIVATE_TARGETS defaults to false, and with that setting any scrape target resolving to loopback, private, or link-local addresses is rejected with a 400, including the 169.254.169.254 cloud metadata endpoint. That is an SSRF guard aimed at exactly the attack a scraping service invites: the service is designed to fetch arbitrary URLs supplied by whoever calls it. Turning the flag to true is documented as safe only when the server is trusted to scrape your own network.
CORS_ALLOW_ORIGINS defaults to the webapp dev server and the file is blunt about the wildcard: setting it to * lets any website a browser visits drive this instance. Combined with an empty API_KEY, that pairing is an unauthenticated remote control surface, and the two defaults are individually reasonable while together they are not.
Thompson Sampling picks the proxy, which means the scraper learns from your failures
Proxy selection is not round robin. The pool uses Thompson Sampling, a bandit algorithm that weights each proxy by how it has performed and updates that weight from success or failure on every scrape, per domain. The dashboard exposes the resulting numbers on a Proxy Scores page. In practice this means the routing improves as a domain proves which proxies work, and it also means the algorithm's state is a function of traffic: a proxy that has never been tried sits at the prior and gets sampled eventually, but a proxy with a bad run early on is down weighted until it recovers.
PROXY_URL in .env.example accepts a single proxy, and the proxy pool is described as optional, so a deployment with no proxies configured has nothing for Thompson Sampling to select and falls back to direct connections.
Structured extraction is a separate concern from fetching. Setting generateJson on a scrape request routes the cleaned content through Gemini, which needs GEMINI_API_KEY and sends the page content to a third party. The scraping itself needs no keys, but the JSON extraction path does, and that is a data flow decision rather than a technical one: page content leaves your machine whenever generateJson is true.
Running it for the first time without Docker
The shortest path in the repository needs Go 1.25 or newer and nothing else. From a clone of the repository, start the server from the server directory:
cd server && go run cmd/server/main.goWith no DATABASE_URL set, the server keeps jobs in memory and starts listening on port 8080. The first scrape is a single synchronous request that returns the whole result, no polling involved:
curl -s -X POST http://localhost:8080/v1/scrape \
  -H "Content-Type: application/json" \
  -d '{"url": "https://example.com"}' | jq .
For long jobs the same API has an asynchronous pair: POST to /v1/url-scraper returns a job UUID, and GET on /v1/url-scraper/JOB_UUID returns the result once the worker is done. Batch mode accepts up to 10 URLs in one request.
To turn a page into structured fields rather than markdown, add generateJson and set GEMINI_API_KEY:
curl -s -X POST http://localhost:8080/v1/scrape \
  -H "Content-Type: application/json" \
  -d '{"url": "https://example.com", "generateJson": true}' | jq .generatedJson
Expect the .markdown field on the plain request to hold cleaned page text with boilerplate stripped, since markdown conversion happens inside the worker after the handler returns. The dashboard is a separate program on its own port: cd webapp, npm install, npm run dev, then open localhost:3000, where it proxies API calls to port 8080.
Where Firecrawl and Scrapy split from this design
The README sets up a comparison table against Firecrawl, Crawlee and Scrapy, and the rows that carry real weight are the handler chain and the proxy selection. Firecrawl and Crawlee both run headless Chrome and route through a single mode, so a site that blocks the browser is a failure rather than something the system tries harder on. Scrapy, as the table puts it, has no anti-detect browser at all, which means bot defences are an application problem you write yourself.
The difference in approach is where the fallback lives. AnakinScraper makes escalation an internal mechanism with per-domain pattern matching deciding when to escalate. Crawlee and Scrapy hand you a browser or an HTTP client and expect you to compose the retry policy, usually with the proxy rotation code on your side. Thompson Sampling applied per domain is the other structural difference: Crawlee and Scrapy treat proxy lists as configuration, while this treats them as learned state.
The self-hosting story also differs. AnakinScraper is one 30MB Go binary that starts with go run and no database. Firecrawl is Node.js and, per the table, Docker required. That is a real advantage for a small Go shop and a poor one if you already have a Node scraping pipeline and no appetite for a second language in the stack.
The gap between the marketing and the pattern matching
The description promises one command with make up and clean markdown from any website, and the repository backs most of that with a working compose file, a Makefile with up, down, build, test, logs and clean targets, and example directories for basic, batch and custom handler use. Two claims carry more weight than the rest.
First, the cost figure. Routing external API calls to roughly the hard five percent of pages saves a large fraction of what a pay-per-request service would cost, which is the commercial argument for the whole chain. That number is not measured anywhere in the repository, and a site mix dominated by JavaScript-rendered pages inverts the maths entirely, because then most requests reach the browser handler and the external API stage.
Second, zero-config start. It is accurate for the Go path and inaccurate for the Docker path, which starts three containers and a database. Both are in the README under different headings, and treating them as one claim is the easiest way to misjudge the deployment cost.
Two releases exist, v0.1.0 on 2026-03-18 and v0.1.1 on 2026-03-23, and the last push was on 2026-08-18. Version numbers this low mean interface changes are still possible, so pin your image tag rather than tracking a branch if you build around the JSON shape of /v1/scrape.
Editorial conclusion
Adopt it if you want one Go binary that returns LLM-ready markdown and you control the network it scrapes from. Do not adopt it if you need guaranteed structured extraction on JavaScript-heavy sites, because those sites pay the browser and API handler costs on every request. Verify first that a direct HTTP fetch of your target URLs succeeds, since the whole cost model rests on that step never failing. Before exposing the server on any shared network, set API_KEY and leave CORS_ALLOW_ORIGINS off the wildcard.
Frequently asked questions
What license is AnakinScraper released under?
The repository is licensed under AGPL-3.0. The project also ships a NOTICE file alongside the LICENSE.
Does AnakinScraper need a database to run?
No. The server runs with just Go 1.25 and stores jobs in memory, which means job history is lost on restart. Setting DATABASE_URL switches it to PostgreSQL persistence, and the Docker stack runs postgres:16-alpine for this.
How does AnakinScraper scrape JavaScript-heavy sites?
The Camoufox anti-detect Firefox browser runs as a separate service on port 9222, reachable by the server through BROWSER_WS_URL. It is the second handler in the chain, so it only runs when the plain HTTP fetch fails the domain's failure and required pattern checks.
What does generateJson do in a scrape request?
Setting generateJson to true routes the cleaned page content through Gemini to produce structured fields, returned as generatedJson. It requires GEMINI_API_KEY and sends page content to a third party, while ordinary markdown scraping needs no keys.
How does AnakinScraper choose a proxy?
It uses Thompson Sampling, which weights each proxy by observed success and failure per domain and updates those weights in real time. Scores are visible on the Proxy Scores page of the web dashboard.
Can AnakinScraper be pointed at an internal network address?
Not by default. With ALLOW_PRIVATE_TARGETS set to false, targets resolving to loopback, private or link-local addresses, including the 169.254.169.254 metadata endpoint, are rejected with a 400. The flag must be set to true to allow them, which is documented as safe only for a server trusted to scrape your own network.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/anakin-inc-anakin)Star history chart for your README
[](https://hysenlabs.com/projects/anakin-inc-anakin)Was this useful?