angr: a Python binary analysis framework for symbolic execution and CFG recovery
A powerful and user-friendly binary analysis platform!
At a glance
- What is it?
- angr loads a binary and exposes disassembly, IR lifting, symbolic execution, control-flow and data-dependency analysis through Python 3 libraries. It is aimed at reverse engineers and researchers who are comfortable writing scripts, not at users who want a point-and-click tool.
- Who is it for?
- Adopt angr if you write Python and your question about a binary can be phrased as a search over program states, or if you need CFG and value-set analysis in the same process as your own tooling. Do not adopt it if you need a GUI, a supported long-term release, or a one-command answer to "what does this binary do".
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
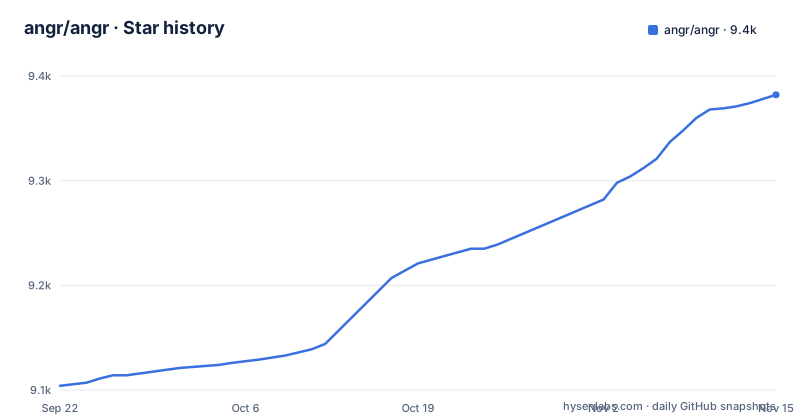
- angr/angr9,382 ★ · +278
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| angr/angr | 9.1k | 9.4k |
278 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What angr solves, and who writes scripts against it
Most binary tooling stops at disassembly. You get instructions, and the reasoning about which inputs reach which branch stays in your head. angr's stated purpose is to move that reasoning into Python: the README lists disassembly and intermediate-representation lifting, program instrumentation, symbolic execution, control-flow analysis, data-dependency analysis, value-set analysis and decompilation as things the suite does to a loaded binary.
The intended user is someone who can write a script and wants to ask a question about a program rather than read it. CTF players are the obvious case, and the README points at an examples page for CTF challenges. The same primitives apply to vulnerability research, where you want to know whether a particular memory access is reachable, and to academic work, since the project comes out of the Computer Security Lab at UC Santa Barbara and SEFCOM at Arizona State University.
It is a poor fit for anyone who wants a desktop application. angr is a library; the README's own framing is that you load a binary and then do things to it. If your workflow is "open the file, look at the graph", this is the wrong layer.
How angr works: a Project, a lifted IR, and states you step forward
The entry point is a Project object. The README gives the canonical line, `p = angr.Project('/bin/bash')`, and notes that in an enhanced REPL such as IPython you can tab-complete the top-level-accessible methods. Everything else hangs off that object.
Underneath, angr is not a single Python package. The pyproject.toml pins sibling components at the same development version, archinfo for architecture descriptions, cle for loading and pyvex for the VEX intermediate representation, and also depends on pypcode and on z3-solver for the constraint solving that symbolic execution depends on. The repository also carries a Rust workspace with members named native/angr, native/clarirs-core, native/clarirs-num, native/clarirs-vsa and native/clarirs-z3, so part of the analysis engine is compiled rather than interpreted. That split matters for installation, which is the next section.
The data flow for a symbolic run is: load the binary, lift its instructions into VEX, create a state that carries symbolic values for inputs, step that state through the program, and let the solver decide which paths are feasible. The README's example shows the other half of the pattern, instrumentation: a hook registered at a fixed address that fires when execution reaches it. Hooks are how you turn a symbolic search into an answer, because the callback runs Python at the moment of interest.
Installing angr and hooking your first address
The README gives the short version of installation as a virtualenv followed by a pip install. The package requires Python 3.12 or newer according to pyproject.toml, and the classifiers list 3.12, 3.13 and 3.14.
mkvirtualenv --python=$(which python3) angr && python -m pip install angrThe README's install instructions live at docs.angr.io/introductory-errata/install, which is where you should look if the one-liner fails. The build is not pure Python: setup.py contains a build_unicornlib step that shells out to make, gmake or nmake depending on platform, and it raises an error if pyvex is not already importable. On Linux the artifact is unicornlib.so, on macOS unicornlib.dylib, on Windows unicornlib.dll. A source install therefore needs a compiler and a Rust toolchain.
For a first real use, the README's example loads a binary without its shared libraries and hooks a specific address. Disabling library loading keeps the state space small, which is the usual reason to set it.
import angr

project = angr.Project("angr-doc/examples/defcamp_r100/r100", auto_load_libs=False)


@project.hook(0x400844)
def print_flag(state):
    print("FLAG SHOULD BE:", state.posix.dumps(0))
    project.terminate_execution()


project.execute()
What you should see is a line beginning with FLAG SHOULD BE followed by the bytes the symbolic execution resolved for file descriptor 0. The `state.posix.dumps(0)` call reads stdin from the symbolic state, and `terminate_execution()` stops the run once the hook has fired. Note the path in that snippet is a file inside the angr-doc examples repository, not something the angr package installs for you.
Where angr stops being the right tool
Symbolic execution over a real program does not terminate on its own schedule. Every branch that depends on symbolic input adds a state, and the solver has to decide satisfiability for each one. The README's own example is small and deliberately shaped for a CTF challenge, and it calls `terminate_execution()` from inside the hook rather than letting the search run to completion. That is the honest picture: you decide when to stop, and you decide which addresses are worth hooking.
The second limit is environmental. Because the build pulls in pyvex, a Rust workspace and a native unicornlib, a source install is a toolchain exercise before it is an analysis exercise. The pyproject.toml pins pyvex and z3-solver to exact versions, and the comment above the build requirements explains why grpcio-tools is pinned: the generated protobuf modules carry a gencode version stamp that the runtime validates at import, so the build-time and run-time protobuf versions have to agree on the major. Mixing angr into an environment that already has a different protobuf major will produce import-time failures rather than analysis-time ones.
Third, the repository has no GitHub releases. Its last push was on 2026-11-02 and it is not archived, but the dependency pins point at development versions such as pyvex==10.0.6.dev0 and archinfo==10.0.6.dev0. If your project needs a tagged, stable release line, that is a question to answer from PyPI before you start.
angr compared with Ghidra and other decompiler-first tools
The natural alternative is a decompiler-first reverse engineering suite. Ghidra is the common one, and the difference is structural rather than a matter of features. Ghidra presents a binary in a window: a disassembly listing, a decompiler pane, a function graph, and a scripting layer you reach for when the GUI is not enough. angr presents the same binary as objects in a Python process, with no interface at all.
That difference decides the workflow. In a decompiler you read code and form a hypothesis; the tool helps you read faster. In angr you state the hypothesis as a constraint and ask the solver whether a state exists that satisfies it, which is a question a listing cannot answer. Control-flow and value-set analysis in angr serve the same programmatic purpose: they produce data structures your script consumes, not a picture you look at. The README's own quick-start list points at the top-level-accessible methods and the API reference rather than at any UI.
There is overlap, and the choice is not exclusive. A reasonable pattern is to use a decompiler to find the address worth asking about, then encode that address as a hook in angr. The README's example hooks 0x400844, which is exactly that kind of address. What you cannot do is get angr's answer without writing the script.
Licence, maintenance and the cost of upgrading
angr is BSD-2-Clause. The licence identifier appears in pyproject.toml and in the Cargo workspace package metadata, and the repository ships a LICENSE file plus a COPYRIGHT file. A permissive two-clause BSD licence is generally straightforward to incorporate into commercial tooling, but the details of attribution and redistribution are for your own legal review; nothing here is legal advice.
The upgrade cost is real because of the pinning. pyproject.toml fixes pyvex and z3-solver to exact versions, requires Python 3.12 or newer, and depends on archinfo, cle and pyvex at matching development versions. The grpcio-tools comment shows the failure mode directly: if the protobuf runtime and the generated code disagree on major version, imports fail. In practice this means angr wants its own virtual environment rather than a shared one, which is also what the README's install line sets up.
Maintenance signals: the repository is not archived and its last push was on 2026-11-02. The README credits an open source community and a named maintainer alongside the two university labs, and the repository carries a SECURITY.md and a pre-commit configuration, which indicates a contribution process with review hooks. The repository has no published GitHub releases, so there is nothing here to say about a changelog or a deprecation policy.
Editorial conclusion
Adopt angr if you write Python and your question about a binary can be phrased as a search over program states, or if you need CFG and value-set analysis in the same process as your own tooling. Do not adopt it if you need a GUI, a supported long-term release, or a one-command answer to "what does this binary do". Before committing, verify that your Python is 3.12 or newer, that a Rust toolchain and the native unicornlib build will work on your platform, and that your analysis finishes on one real sample rather than only on a CTF binary.
Frequently asked questions
What does angr mean?
The README does not expand the name or give an etymology. It presents angr as a platform-agnostic binary analysis framework maintained by the Computer Security Lab at UC Santa Barbara, SEFCOM at Arizona State University, their CTF team Shellphish and the open source community.
How do I install angr?
The README gives the short version as `mkvirtualenv --python=$(which python3) angr && python -m pip install angr`. The package requires Python 3.12 or newer, and the README points to docs.angr.io/introductory-errata/install for the full install instructions.
Is angr hard to learn?
The README does not rate the learning curve. It does assume you are working in Python and suggests an enhanced REPL such as IPython so you can tab-complete the top-level-accessible methods and read their docstrings, and it points to a documentation site, an examples page and an API reference.
How does angr work?
You create a Project from a binary, for example `p = angr.Project('/bin/bash')`. From there the README lists disassembly and IR lifting, instrumentation, symbolic execution, control-flow analysis, data-dependency analysis, value-set analysis and decompilation as the operations available on that project.
Where can I find angr examples?
The README links an examples page at docs.angr.io/examples for using angr to solve CTF challenges, and an awesome-angr repository for further material. The README itself includes a short symbolic execution example that hooks address 0x400844 in a defcamp_r100 binary.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/angr-angr)Star history chart for your README
[](https://hysenlabs.com/projects/angr-angr)Was this useful?