pgsync: copying Postgres data between databases without pg_dump
Sync data from one Postgres database to another
At a glance
- What is it?
- pgsync is a Ruby command line tool that moves table data from one Postgres database to another, with parallel transfers, per-column masking rules and tolerance for schema drift. It is a data copy tool, not a replication system, and its defaults assume the destination is a local development database.
- Who is it for?
- Adopt pgsync if you need to pull a subset of production data into a local or staging Postgres and you want masking rules and partial table sync in one command. Do not adopt it if you need continuous replication, low-latency mirroring or a change data capture stream; pgsync runs when you invoke it and copies rows, it does not follow the write-ahead log.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
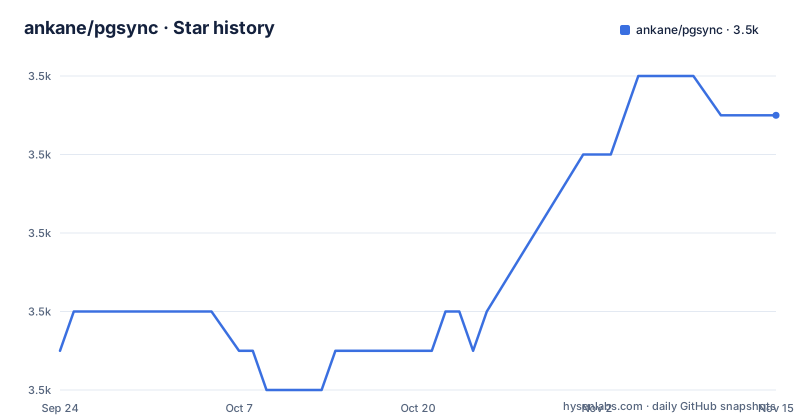
- ankane/pgsync3,481 ★ · +6
| Repository | 2026-09-24 | 2026-11-15 |
|---|---|---|
| ankane/pgsync | 3.5k | 3.5k |
6 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What pgsync is for, and who actually needs it
The README describes pgsync as a way to "Sync data from one Postgres database to another (like pg_dump/pg_restore)". The parenthetical is the honest framing. This is a bulk copy tool with a nicer interface than dumping and restoring, and it is aimed at developers who want production-shaped data in a local or staging database without dragging the whole cluster across the network.
The four properties the README lists are speed, security, flexibility and convenience. Speed comes from transferring tables in parallel. Security comes from data rules that rewrite sensitive columns before they leave the source. Flexibility means the tool tolerates schema differences such as missing columns and extra columns. Convenience covers partial tables, groups of tables and related records.
That combination points at one workflow in particular: refreshing a development database. A full dump of a large production database is slow to produce, slow to transfer and often contains personal data that should never sit on a laptop. pgsync lets you name the tables you want, filter the rows, and mask the columns that matter, in a single command.
It is less obviously suited to analytics loading, cross-region failover or anything that needs to keep running. The tool executes when you run it and stops when it finishes.
How pgsync moves rows: parallel table transfers and schema reconciliation
The README states that tables are transferred in parallel, and the `--jobs` flag controls that concurrency. Setting `--jobs 1` forces tables to be synced one at a time, which the documentation presents as the way to manually control order when foreign keys get in the way. So the model is: pgsync enumerates the tables in scope, opens connections to both databases, and copies each table as a unit, with several tables in flight at once.
Before any data moves, the schema must exist on both sides. The README is explicit about this: "First, make sure your schema is set up in both databases. We recommend using a schema migration tool for this." pgsync is not a schema migration tool that happens to copy data. It expects the destination to already have the tables, and it reconciles around the differences it finds, dropping columns that do not exist on the destination and ignoring extra ones.
There are two escape hatches for schema. `pgsync --schema-first` syncs the schema before the data and, per the README, wipes out existing data. `pgsync --schema-only` syncs the schema without data and also wipes existing data. Both are destructive, and the README says so twice. The README also notes that pgsync does not try to sync Postgres extensions.
Scope is controlled at several levels. By default only the search path is synced; `--all-schemas` or `--schemas public,other` widens it, and individual tables can be qualified as `public.table1,other.table2`. Tables can be excluded with `--exclude` or a default `exclude` list in `.pgsync.yml`. Groups defined in the config file bundle tables under one name, and groups with variables let you pull one record plus its related rows.
Installing pgsync and running a first sync
pgsync ships as a Ruby gem. The README gives the install command directly:
gem install pgsyncAfter that you should have a `pgsync` command on your PATH. The README notes that if installation fails you may need to install dependencies, and it also documents a Homebrew formula and a Docker image as alternatives. The Dockerfile in the repository builds from `ruby:3-alpine`, installs `build-base`, `libpq-dev` and `postgresql16-client`, installs the `pg` gem and `pgsync`, then sets `ENTRYPOINT ["pgsync"]`.
Setup happens per project directory:
pgsync --initThis creates `.pgsync.yml` for you to customize. The README recommends checking it into version control, provided it does not contain sensitive information. Commands can be run from that directory or any subdirectory.
With the schema already present on both databases, a full sync is one word:
pgsyncTo narrow it down, name the tables or use a wildcard:
pgsync table1,table2
pgsync "table*"
Row-level filtering uses a where clause in quotes. Existing rows are overwritten by default:
pgsync products "where store_id = 1"The README gives `--preserve` to keep existing rows and `--truncate` to clear them first. If something looks wrong, `pgsync --debug` prints the SQL that is run, and `pgsync --list` lists tables.
Masking sensitive columns before they leave the source
The data rules system is the part of pgsync with the most design thought behind it. Rules live under `data_rules` in `.pgsync.yml` and match column names, with `last_name` matching every column of that name and `users.auth_token` matching only that table's column. Wildcards are supported and the first matching rule wins.
data_rules:
  email: unique_email
  last_name: random_letter
  birthday: random_date
  users.auth_token:
    value: secret
  visits_count:
    statement: "(RANDOM() * 10)::int"
  encrypted_*: null
The available replacements are `unique_email`, `unique_phone`, `unique_secret`, `random_letter`, `random_int`, `random_date`, `random_time`, `random_ip`, `value`, `statement`, `null` and `untouched`. Two constraints matter. Rules starting with `unique_` require the table to have a single column primary key, and `unique_phone` requires a numeric primary key. If your tables use composite keys, the unique generators are not available to you.
The `statement` option is the flexible one, because it accepts arbitrary SQL evaluated on the source. That is also where a mistake is expensive: a statement that returns a value of the wrong type, or that references a column that does not exist, will fail at sync time rather than at config time. There is no dry run documented in the README, so the first place you see the effect of a new rule is a real sync.
Foreign keys, triggers and the limits of the safety net
Foreign keys are the friction point the README spends the most words on, and the three options it lists are not equivalent. Deferring constraints with `pgsync --defer-constraints` is the recommended path. Manually ordering tables with `--jobs 1` trades parallelism for predictability. Disabling foreign key triggers with `pgsync --disable-integrity` is described as able to "silently break referential integrity (not recommended)". That flag also needs superuser privileges on the destination, an `rds_superuser` role on Amazon RDS, and the README says there does not appear to be a way to disable integrity on Heroku.
The safety mechanism worth understanding is the destination restriction. By default the destination is limited to `localhost` or `127.0.0.1`, which prevents a mistyped command from overwriting production. To target another host you must add `to_safe: true` to `.pgsync.yml`. That is a deliberate friction, and it is the right default, but it means the protection is a config line away from being switched off permanently for a project.
Two other constraints are easy to overlook. `--in-batches` is the documented approach for extremely large append-only tables, and it requires a numeric, increasing primary key; the README notes the script resumes where it left off, which makes it suitable for backfills. Separately, `--disable-user-triggers` exists because triggers on the destination will otherwise fire during the copy, and `--no-sequences` skips sequence syncing.
Where pgsync is the wrong tool: any situation that needs continuous change propagation. There is no replication slot, no write-ahead log reading and no streaming mode in the README. If your requirement is that the two databases stay in step minute by minute, a batch copy tool is the wrong category.
pgsync against pg_dump, Debezium and the schema-diff tools
The most direct alternative is the pair the README names in its first sentence: `pg_dump` and `pg_restore`. Those are the standard Postgres utilities and they copy an entire database or a selected set of tables with no configuration file and no Ruby dependency. The difference in approach is that pg_dump has no concept of masking, no row-level where clause for a single table, and no built-in protection against pointing at a production host. pgsync adds all three. If your database is small, your data is not sensitive and your schema matches exactly, pg_dump is fewer moving parts.
Debezium takes the opposite architectural position. It reads the Postgres write-ahead log through logical decoding and emits change events continuously, which is what you want for keeping systems in step. pgsync reads tables at the moment you run it. That difference decides the use case: a one-off refresh of a development database is a batch problem, and a batch tool is simpler to operate than a connector with Kafka behind it.
The related searches around this project also surface PeerDB and Pgslice. PeerDB is a change data capture and mirroring product, which puts it in the Debezium category rather than pgsync's. Pgslice partitions large tables in place so that old data can be dropped cheaply; it operates on one database's storage layout, not on copying between two. Neither is a drop-in substitute for what pgsync does, and the README does not position pgsync against either.
One name collision is worth flagging. Searches for "PGSync OpenSearch", "pgsync elasticsearch" and "pgsync redis" refer to a different project, a Python tool that syncs Postgres to Elasticsearch and OpenSearch. ankane/pgsync is Ruby, targets Postgres on both ends, and has no Elasticsearch integration in its README.
Maintenance, licence and what an upgrade costs you
The repository is not archived, and the last push was on 2026-08-15. The README states that the project is battle-tested at Instacart, and the repository carries a GitHub Actions build workflow whose status badge is embedded in the README. The repository has no published GitHub releases, so version history has to come from the CHANGELOG.md that the repository does contain.
The licence is MIT, which is permissive and places few obligations on how you redistribute or modify the tool. That is a statement about the licence text as identified in the repository, not legal advice; if you are embedding pgsync in a commercial product, read LICENSE.txt and your own counsel's guidance.
Upgrade cost is low by construction. pgsync is a command line tool with a single YAML config file, so upgrading means installing a new gem version and re-running your commands. The risk surface is your `.pgsync.yml`. Data rules that reference column names or SQL statements are the part most likely to break when a schema changes, and the README documents no validation step for them. If you maintain a long `data_rules` block, treat it as code that needs review whenever the source schema moves.
There is also a dependency consideration. The gem installs the `pg` gem, which compiles against libpq, and the Dockerfile shows the Alpine build path: `build-base`, `libpq-dev` and `postgresql16-client` before the gem install, with `build-base` removed afterwards. Teams installing on minimal images should expect to need those build packages present at install time.
Editorial conclusion
Adopt pgsync if you need to pull a subset of production data into a local or staging Postgres and you want masking rules and partial table sync in one command. Do not adopt it if you need continuous replication, low-latency mirroring or a change data capture stream; pgsync runs when you invoke it and copies rows, it does not follow the write-ahead log. Before relying on it, verify three things: that to_safe is set correctly if the destination is not localhost, that your data_rules cover every sensitive column including wildcard matches, and that your foreign key strategy (defer-constraints, ordered jobs, or disabling integrity) behaves as expected on your schema.
Frequently asked questions
What is pgsync used for?
It syncs data from one Postgres database to another, similar in purpose to pg_dump and pg_restore. The README lists four design goals: speed through parallel table transfers, security through data rules that mask sensitive columns, flexibility around schema differences, and convenience for partial tables and related records.
How do I install pgsync?
Run gem install pgsync, which puts the pgsync command on your PATH. The README also documents a Homebrew formula and a Docker image built from the repository's Dockerfile.
How do I set up pgsync in a project?
Run pgsync --init in your project directory. This creates a .pgsync.yml file for you to customize, and the README recommends checking it into version control as long as it does not contain sensitive information.
Does pgsync sync the schema as well as the data?
Not by default. The README says to make sure the schema is set up in both databases first, ideally with a schema migration tool. The --schema-first and --schema-only flags exist as convenience methods, but both wipe out existing data on the destination.
Why does pgsync refuse to sync to a remote host?
By default the destination is limited to localhost or 127.0.0.1, which keeps you from accidentally overwriting production. To use another host you must add to_safe: true to your .pgsync.yml.
How does pgsync handle foreign keys?
The README gives three options: defer constraints with --defer-constraints (recommended), manually order tables with --jobs 1, or disable foreign key triggers with --disable-integrity, which it warns can silently break referential integrity and requires superuser privileges on the destination.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ankane-pgsync)Star history chart for your README
[](https://hysenlabs.com/projects/ankane-pgsync)Was this useful?