Robin: an AI-assisted dark web OSINT tool that filters search results before you read them
AI-Powered Dark Web OSINT Tool
At a glance
- What is it?
- Robin pairs a Tor-backed search and scrape pipeline with an LLM filtering stage, so an investigation returns a shortlist and a summary instead of a wall of onion links. The Docker image is the recommended install; the LLM filtering stage is the part worth judging.
- Who is it for?
- Adopt Robin if you already have a lawful investigative remit, a provider API key or a local Ollama instance, and you want the filtering and summary step handled for you. Do not adopt it if you cannot send your queries to a third-party model provider.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 43 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
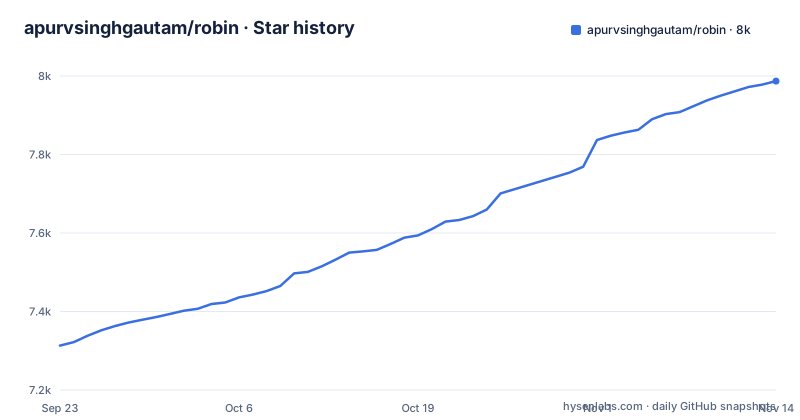
- apurvsinghgautam/robin7,987 ★ · +674
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| apurvsinghgautam/robin | 7.3k | 8k |
674 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Robin targets: dark web search results are cheap, triage is not
Dark web search engines return links, not answers. A query about a leaked dataset or a stolen credential dump produces a page of onion addresses whose titles are often misleading, duplicated across mirrors, or dead by the time you click. The expensive part of an OSINT investigation is not finding candidate pages. It is reading them, deciding which ones are relevant, and writing down what you found in a form someone else can check.
Robin is built for that second half. The README describes it as "an AI-powered tool for conducting dark web OSINT investigations" that uses LLMs to refine queries, filter search results from dark web search engines, and produce an investigation summary. The target user is someone with a lawful investigative remit: a threat intelligence analyst, a security researcher, a journalist working a specific story. It is not a general web search replacement, and the disclaimer in the README is explicit that accessing certain dark web content may be illegal depending on jurisdiction and that the author is not responsible for misuse.
How the search, scrape and LLM stages fit together
The repository layout matches the three-stage pipeline the README describes. search.py handles querying the dark web search engines, scrape.py fetches page content, and llm.py plus llm_utils.py wrap the model providers. config.py holds defaults, model_registry.py and models.json back the model discovery, and ui.py is the Streamlit front end. The file names support that reading, and pipeline.py, store.py and mcp_server.py sit alongside them.
The README's own description is that LLMs refine the query, filter results from dark web search engines and produce an investigation summary. `.env.example` also exposes persistent depth defaults shared by the web UI and the MCP server, such as `ROBIN_DEFAULT_PRESET` for the research domain and `ROBIN_DEFAULT_THREADS` for scrape workers (1 to 16).
The README states that one key is enough, because Robin lists models for whichever providers it finds, and a custom provider can be given a model name if it does not expose `/v1/models` for auto-discovery. Supported providers are OpenAI, Claude, Gemini, Mistral, OpenRouter, Ollama, and any OpenAI-compatible API such as LM Studio, llama.cpp or Groq. Two features sit on top of the pipeline: conversational follow-ups, answered from that investigation's own data without re-running the search, and one-click pivots that turn a suggested follow-up query into a fresh investigation.
Installing Robin with Docker and running a first investigation
The README recommends Docker and states that the tool needs Tor to do the searches. On Linux or Windows under WSL that is `apt install tor`; on Mac it is `brew install tor`. Confirm Tor is running in the background before you start.
You need at least one provider key. Copy `.env.example` to `.env` and fill in whichever of the supported keys you have. One key is enough, because Robin lists models for whichever providers it finds.
OPENAI_API_KEY=
ANTHROPIC_API_KEY=
GOOGLE_API_KEY=
MISTRAL_API_KEY=
OPENROUTER_API_KEY=
Pull the image, then run it with the `.env` file mounted. The `--add-host` flag is required for the Ollama path described below.
docker pull apurvsg/robin:latestdocker run --rm \
-v "$(pwd)/.env:/app/.env" \
--add-host=host.docker.internal:host-gateway \
-p 8501:8501 \
apurvsg/robin:latestOpen `http://localhost:8501`. Choose a provider and model and run the investigation. Saved investigations land in an `investigations/` folder; the README shows a second `docker run` with `-v "$(pwd)/investigations:/app/investigations"` so they survive a restart, and they can be reloaded from the Past Investigations panel in the sidebar.
To run your own build instead of the published image, the README has you clone the repository, run `docker build -t robin .`, and use the same run commands with `robin` in place of `apurvsg/robin:latest`.
Ollama and custom providers: where the setup actually bites
Running a local model is the option that keeps queries off a third-party API, and it is also the option with the most moving parts. The README states that nothing goes in `.env` for Ollama, because Robin defaults to `http://host.docker.internal:11434`, which is what the Docker install needs. Two things remain the user's responsibility.
First, the container needs `--add-host=host.docker.internal:host-gateway`, which the recommended command already includes. Second, Ollama binds to `127.0.0.1` by default and a container cannot reach that, so Ollama has to listen on all interfaces. Started by hand, that is `OLLAMA_HOST=0.0.0.0 ollama serve &`. Under systemd, the README's route is `sudo systemctl edit ollama.service`, adding `[Service]` and `Environment="OLLAMA_HOST=0.0.0.0"`, then `sudo systemctl daemon-reload && sudo systemctl restart ollama`.
If you run Robin directly with Python instead of Docker, the default is wrong for your setup and you override it with `OLLAMA_BASE_URL=http://127.0.0.1:11434`. The README points at TROUBLESHOOTING.md if the model still does not appear.
For any other OpenAI-compatible provider, the README says to use the Custom API Provider expander in the sidebar, entering a base URL, an optional API key, and optionally a model name if the provider does not expose `/v1/models` for auto-discovery. `.env.example` lists the corresponding overrides, including `CUSTOM_API_BASE_URL`, `CUSTOM_API_KEY` and `CUSTOM_API_MODEL`, plus `OLLAMA_NUM_CTX` for a RAM-constrained machine and `OPENROUTER_BASE_URL` for a custom OpenRouter gateway. The pattern is consistent: `.env` for defaults you want everywhere, the sidebar for one-off endpoints.
Where Robin is the wrong tool
The filtering step is the product, and it is also the failure mode. An LLM decides which search results are relevant before you ever see them. If the model's judgement is wrong in the direction of exclusion, you will not know what you missed, because the discarded links are not the ones that reach the summary. The tunable depth settings are a mitigation, not a fix: raising the number of results to filter and the pages to scrape widens the net at a direct token cost.
There is also a data-handling boundary. The README warns that Robin uses third-party APIs including LLMs and advises caution when sending potentially sensitive queries, with a review of the terms of service for any provider you use. If your investigation cannot leave your infrastructure, the only configurations that respect that are Ollama or another self-hosted OpenAI-compatible endpoint. Anything else sends your query text to a vendor.
How Robin differs from running a search engine and a summarizer yourself
The obvious alternative is to do the three stages by hand: query a dark web search engine, open the results in Tor Browser, and paste the pages you care about into a general-purpose LLM chat. That approach gives you full control over what the model sees and lets you read every candidate page. Its cost is time and consistency. You are the filter, and two analysts doing the same query will produce different shortlists.
Robin's difference is that the filter, the scraper and the summarizer share one configuration and one interface. The follow-up questions are answered from the stored investigation rather than from a fresh search, which keeps a conversation grounded in what was actually collected. The pivots turn a finding into a new query in one click. Neither of those is a capability a chat window has, because a chat window has no investigation object to be grounded in.
What you give up is transparency. A manual workflow lets you read the pages the model never saw. Robin's design assumes you would rather not. For a narrow, well-specified question that trade is reasonable; for exploratory work where you do not yet know what you are looking for, it is the wrong shape.
Maintenance, releases and the MIT licence
The repository is not archived and the last push was on 2026-10-03, the same day as the v3.1 release. The release history shows a steady cadence: v2.9 on 2026-09-11, v3.0 on 2026-09-26, v3.1 on 2026-10-03. Nothing in the README describes a support policy, a deprecation window or a compatibility guarantee between versions, so treat the release notes as the only record of what changed.
Upgrade cost is concentrated in the provider layer. Because Robin lists the models it finds for each provider, a provider retiring a model changes your dropdown without a Robin release. It also means the thing that breaks is outside the project's control, and the fix is usually to pick a different model rather than to change code. Pinning a specific model through the Custom API Provider fields is the way to avoid that class of surprise.
The project is MIT licensed. That is permissive in the usual sense: it allows commercial and closed-source use, modification and redistribution provided the copyright notice and permission notice are kept. It says nothing about the legality of the material you point the tool at, and the README's disclaimer separates those two questions deliberately. The licence covers the code, not your investigation.
Editorial conclusion
Adopt Robin if you already have a lawful investigative remit, a provider API key or a local Ollama instance, and you want the filtering and summary step handled for you. Do not adopt it if you cannot send your queries to a third-party model provider. Verify first that Tor is running and that your chosen provider appears in the model dropdown.
Frequently asked questions
How do I install Robin AI?
The README recommends Docker: install Tor, copy .env.example to .env and add at least one provider API key, then pull apurvsg/robin:latest and run it with the .env file mounted and port 8501 published. You can also build the image yourself with `docker build -t robin .` and run it the same way.
Does Robin need Tor to work?
Yes. The README states that the tool needs Tor to do the searches, installed with `apt install tor` on Linux or Windows under WSL, or `brew install tor` on Mac, and that you should confirm Tor is running in the background. The Dockerfile installs Tor as part of the image build.
Which LLM providers does Robin support?
OpenAI, Claude, Gemini, Mistral, OpenRouter, Ollama, and any OpenAI-compatible API such as LM Studio, llama.cpp or Groq. The README states that one key is enough, because Robin lists models for whichever providers it finds.
Can I run Robin with a local model instead of a cloud API?
Yes, through Ollama. The README notes that nothing goes in .env for Ollama because Robin defaults to http://host.docker.internal:11434 for the Docker install, but you must run the container with --add-host=host.docker.internal:host-gateway and make Ollama listen on all interfaces rather than 127.0.0.1.
What should I do if the model dropdown is empty or Tor reports resolve failed?
The README links TROUBLESHOOTING.md from its top navigation and points to it when an Ollama model still does not appear, so that file is the place to start.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/apurvsinghgautam-robin)Star history chart for your README
[](https://hysenlabs.com/projects/apurvsinghgautam-robin)Was this useful?