website-rebuild-skill: an agent skill that mirrors a site, rebuilds it from minified source, and diffs the result
An agent skill that mirrors a website, rebuilds it from the minified code line by line, and verifies the result with automated diffs.
At a glance
- What is it?
- This is a Node-only Agent Skill for line-by-line website reconstruction with automated acceptance gates, including per-pixel comparison. It is built for engineers who need to prove equivalence to a source site, not for anyone who wants a quick visual clone.
- Who is it for?
- Adopt it if you need a documented, evidence-backed reconstruction of a site you have the right to rebuild, and you can accept a session-long to multi-day run plus a read-only mirror you must never edit. Skip it if you want a fast visual approximation, if the target is a thin marketing page where a hand-written rebuild is cheaper, or if you cannot resolve the copyright question the skill deliberately leaves to you.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 20, 2026, and from our analysis. They are not legal advice.
Star history
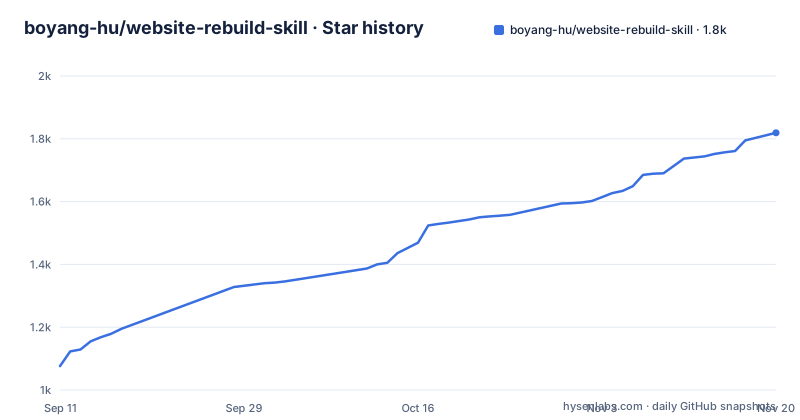
- boyang-hu/website-rebuild-skill1,819 ★ · +743
| Repository | 2026-09-11 | 2026-11-20 |
|---|---|---|
| boyang-hu/website-rebuild-skill | 1.1k | 1.8k |
743 Stars in the last 70 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem is not making a page look similar, it is proving it behaves the same
Most website cloning tools stop at visual resemblance. This skill treats the source site's own implementation as the specification. The README states the goal directly: it is not "making a page that looks very similar," it reconstructs the site line by line and can prove the reconstruction is correct. That distinction drives everything else in the project. The output is not a screenshot-matched mockup but a runnable project where, per the README, every line in the rebuild can point back to a specific line in the source bundle. The audience is engineers doing reverse engineering, migration, or archival work who need an auditable trail: a checksummed read-only mirror, a reverse-engineering note explaining how the site was built, a diff register, and a quantified acceptance report. The skill follows the Agent Skills open specification, so it is designed to run inside any agent runtime that supports skills, not only Claude Code. The README claims cross-runtime validation, citing a Codex run on a Hashgraph VC target with 166 of 166 responses byte-identical.
Seven stages, and the pixel diff is the judge that makes source-ification safe
The pipeline is a fixed sequence: triage, mirror forensics, reverse engineering, porting, acceptance, closure, and source-ification. Triage happens first and can end the job. The README says the agent probes what category the target belongs to and whether it can be done at all, and if it cannot, it states the reason rather than producing garbage. Sites that have disappeared but have an archive are routed into Wayback rescue. Mirror forensics captures the whole site as a read-only snapshot with a per-file sha256 ledger, reference closure validation, and an authenticity check, and the README notes the mirror runs offline. Reverse engineering expands the minified code so each line in the rebuild maps back to a source line, and it deliberately copies bugs, dead code, and odd idioms rather than fixing them. Porting produces a runnable project with a registered diff table. Acceptance compares both sides across five layers: console, network, DOM, geometry, and per-pixel. Closure audits modules for omissions and assembles copyright facts. Source-ification is last and only last, because by then a pixel-exact judge already exists, so every split and rename can be falsified. The README's own framing is blunt: refactoring without a judge is blind editing. Where there is no module container, the skill uses concatenation-style decomposition, cutting the artifact into semantically named parts that reassemble byte-for-byte.
Installation is a file copy with a checksum gate, and the runtime needs Node 22 plus Chrome
Prerequisites are Node.js 22 or newer (the README cites built-in fetch and WebSocket direct CDP connection), a locally installed Chrome or Chromium for headless comparison, and npx for the few steps that spawn pinned external tools. Installation has two paths that place the same directory. The npx route runs `npx website-rebuild-skill` to install into `~/.claude/skills/website-rebuild`, `npx website-rebuild-skill --project` for `./.claude/skills/website-rebuild`, or `npx website-rebuild-skill --dir <skills dir>` for other runtimes, where the directory name website-rebuild is appended automatically. The installer only copies files: it does not run the skill, open a browser, or touch the network, and it has zero dependencies itself. After copying, it verifies every file in both directions by sha256, and only a full match counts as success. If the target already exists, it prints the installed version and refuses unless `--force` is passed, and `--dry-run` shows what it intends to write. The manual route is `cp -R skills/website-rebuild ~/.claude/skills/website-rebuild` after cloning. Usage is conversational: give the agent a URL and say rebuild this site. The agent will ask you to decide the scope, the level (L1 mirror archive, L2 engineering rebuild, L3 source-ification), how to handle external dependencies, and every publication question. The README is explicit that these are your decisions, not the agent's.
Six disciplines, and the one that is hardest to accept is copying the bugs
The README lists six rules that are presented as lessons learned rather than style preferences, and it claims violating any of them resurfaces later as a bug. The mirror is read-only and never modified, because it is the project's only evidence baseline. Source code is the sole arbiter, so you do not tune effects by eye. Everything the source has must exist, and nothing the source lacks may be invented, with the README preferring an initially dissimilar result over a self-invented patch. Bugs, dead code, and odd idioms are copied, not fixed, on the reasoning that any oddity in minified code may itself be the behavior. Intentional differences must be registered with what the source does, what you did, and why, and an unregistered difference counts as a bug. Code and documentation ship in the same commit. Rule three has a stated boundary during source-ification: renaming, splitting modules, and adding comments in the human-readable source is not invention, because that source is an explicitly registered derivative rather than a claim about the source site. Two hard lines remain. No opportunistic refactoring, since merging duplicates, extracting shared functions, or changing algorithms makes equivalence undecidable, and any speculation in comments must be labeled as speculation. The Raycast keyboard showcase is the clearest illustration: an unloaded lazy-load placeholder bar above the keyboard appears identically on both sides, because the bug was copied rather than repaired.
The failure modes are real: dead sites, server components, and a copyright decision the skill refuses to make
Wayback rescue is explicitly a salvage operation, not a repair. The README describes selecting a coherent moment by anchor plus time window, writing original bytes into a standard mirror, and registering permanent holes honestly. Of five dead-site rescues, four were revived and one reached L3, while one lost its entire visual layer and the failure shape was recorded. That is the honest limit: if the archive did not capture the pixels, no amount of pipeline discipline recovers them. Server component frameworks are the second constraint. React Server Components and Next.js App Router do not ship component source to the client, so there is nothing to reverse in the usual sense. The skill reconstructs from the flight stream inlined in each page's HTML, which the README treats as the specification, and closes with flight semantic gates. Reported results include 18 of 18 routes semantically consistent on a Next 16/Turbopack blog and 144 of 144 on a larger site, plus a blind reverse against public source scoring roughly 95 percent structural and 98 percent behavioral. Those are the project's own claims, not independently reproduced here. The third constraint is legal. The skill only gathers evidence and presents it, and the README states the output is private by default, noindex, and not deployed. It does not decide whether you may publish. If you need that decision made for you, this is the wrong tool, and the README says so in its own section heading: what can be done and what should be made public are two different questions.
Against wget plus a hand rebuild, the difference is the acceptance gate, not the download
The obvious alternative is a standard archiving crawl with wget or the Wayback Machine's own replay, followed by a manual rebuild. That approach captures bytes and leaves you to judge correctness by eye. This skill's distinguishing mechanism is the five-layer comparison, and specifically the per-pixel layer. The README reports meanAbsDiff 0.00 on three routes of a custom WebGL engine site, 0.96 on a Theatre.js-driven WebGL piece where the difference falls inside the noise band, and identical frames on a Nuxt 3 plus Storyblok site after pinning the header video to the same frame. Those numbers are the project's, and the skill is the thing producing them, which is worth weighing. A second alternative is a screenshot-diffing tool such as a visual regression harness. That compares rendered output but has no opinion about network responses, console output, DOM structure, or geometry, and it cannot tell you whether a minified function was ported faithfully. The skill's own framing of the contrast is that it watches whether the result is correct, not whether it looks alike. The cost of that standard is time: the README says small to mid-size sites within a few dozen routes now complete unattended in a single session from triage through source-ification, while heavy WebGL or custom-engine sites take roughly one to three days.
Zero npm dependencies before source-ification, and 75 Node scripts you now maintain
The toolchain is 75 Node scripts: 51 pipeline and acceptance-gate scripts, 14 shared libraries, and 10 source-ification and reverse-reconstruction tools. The README states that the entire pipeline installs no npm packages before the source-ification stage, which is a meaningful supply-chain property for a tool that runs against arbitrary websites. It also means there is no package ecosystem to inherit maintenance from. Upgrades come from the npm package `website-rebuild-skill` or from re-copying the `skills/website-rebuild/` directory, and the installer's sha256 verification is what tells you whether the copy is intact. The licence is MIT, which permits commercial use, modification, and redistribution provided the copyright notice and permission notice are included. That is a statement about the skill's code, not about the sites you point it at. The README separates the two: the skill gathers copyright facts and hands you a deployment assessment to rule on, and it does not decide publication for you. It also notes that the deliverable carries a byte manifest and a reassembly gate, so after you fork the output you can tell precisely where you have diverged from the source site. That is the concrete handoff described in `skills/website-rebuild/references/beyond-the-rebuild.md`. The repository has no published GitHub releases, so version pinning should be based on the npm registry entry rather than a changelog. The README also carries a roadmap and update log, which is where upgrade cost will actually show up.
Editorial conclusion
Adopt it if you need a documented, evidence-backed reconstruction of a site you have the right to rebuild, and you can accept a session-long to multi-day run plus a read-only mirror you must never edit. Skip it if you want a fast visual approximation, if the target is a thin marketing page where a hand-written rebuild is cheaper, or if you cannot resolve the copyright question the skill deliberately leaves to you. Before starting, verify three things: that Node.js 22 or newer and a local Chrome/Chromium are installed, that the site is either live or has a coherent Wayback capture, and that your chosen level (L1 mirror, L2 engineering rebuild, or L3 source-ification) matches what you actually need, because the ladder is monotonic and starting lower only costs you a later continuation run.
Frequently asked questions
What does website-rebuild-skill need installed?
Three things: Node.js at version 22 or newer for its built-in fetch and direct Chrome DevTools Protocol access, Chrome or Chromium installed locally for the headless comparison, and npx, which some process steps use to spawn version-pinned external tools without importing them. The same Node floor is required by the engines field in package.json.
How do I install website-rebuild-skill?
Run `npx website-rebuild-skill` to install into the user-level skills directory, add the project flag for the project-level one, or pass a directory for another runtime. The installer only copies files, verifies each one by sha256 in both directions, and refuses to replace an existing target without the force flag. A dry run shows what it would write.
Will website-rebuild-skill publish or deploy anything?
No. The stated position is that the skill only collects evidence and hands it over, and that output defaults to private, noindex and not deployed. Every judgement about whether something can be made public is left to the user rather than decided by the agent.
What happens to bugs that exist on the original site?
They are copied rather than fixed, because a strange line in minified code may be the behaviour itself. The rule is illustrated by a lazy-load placeholder that never resolves on the keyboard page being rebuilt, which appears identically on both sides as a result.
Can website-rebuild-skill rebuild React Server Components sites?
From v0.3 it claims to, by treating the flight stream inlined in each page's HTML as the specification and reconstructing a buildable Next project closed by a flight semantic gate. The same page also lists the category among its conditional scenarios, where that evidence line stops partway through a figure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/boyang-hu-website-rebuild-skill)Star history chart for your README
[](https://hysenlabs.com/projects/boyang-hu-website-rebuild-skill)Was this useful?