cloud-init: what it does at boot, and when it gets in the way
Official upstream for the cloud-init: cloud instance initialization
At a glance
- What is it?
- cloud-init is the boot-time initializer that reads cloud metadata and user data on first launch. It is the right layer for instance identity and networking, and the wrong layer for ongoing configuration management.
- Who is it for?
- Adopt cloud-init if you build images for a public cloud, a private-cloud provisioning system or bare metal and you need instance identity, SSH keys and networking set before your own tooling runs. Do not adopt it as a replacement for Ansible or another configuration management system: cloud-init runs at boot, and the README describes it as instance initialization, not ongoing state enforcement.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
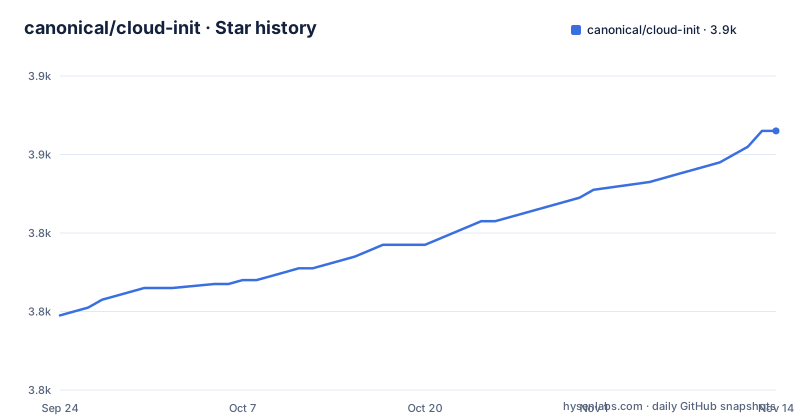
- canonical/cloud-init3,866 ★ · +47
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| canonical/cloud-init | 3.8k | 3.9k |
47 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The boot-time gap cloud-init fills
An image is generic. The instance is not. Between the moment a hypervisor hands a disk image to a virtual machine and the moment that machine is useful, something has to decide its hostname, write its SSH authorized keys, bring up its network interfaces, and apply whatever the person who launched it asked for. cloud-init is that something. The README frames the problem precisely: instances are initialized from a disk image plus instance data, where instance data is cloud metadata, optional user data and optional vendor data. The project describes itself as the multi-distribution method for cross-platform cloud instance initialization, and the supported lists cover most public clouds, private-cloud provisioning systems and Linux and Unix distributions. The audience is therefore narrow but deep: image builders, platform engineers running private clouds, and anyone who has to make one image behave correctly on several providers. If you never launch instances from images, this project is not aimed at you.
How cloud-init decides what it is running on
The mechanism is a search, not a configuration file you fill in. On boot, cloud-init identifies the cloud it is running on, reads the metadata that cloud provides, and initializes the system accordingly. That identification is done by datasources, and the repository layout makes the set concrete: cloudinit/sources contains DataSourceEc2, DataSourceGCE, DataSourceAzure helpers, DataSourceOpenStack, DataSourceNoCloud, DataSourceConfigDrive, DataSourceHetzner, DataSourceScaleway, DataSourceExoscale, DataSourceOVF, DataSourceRbxCloud and DataSourceSmartOS, among others. Each one knows how to find its platform's metadata service or attached seed volume. Once a datasource answers, cloud-init moves through stages: it sets up network and storage devices, configures SSH access keys, and then parses the optional user data and vendor data. Vendor data matters because it lets the platform owner inject configuration that the instance user cannot see or override. The ordering is the design: identity and network first, user payload afterwards. That is also why debugging cloud-init problems usually means reading boot logs rather than inspecting a running service.
Installing cloud-init and a first cloud-config
Most supported distributions ship cloud-init already, so the first check is whether it is present rather than how to add it. The README's guidance when your distribution or cloud is not supported is to contact that distribution, which tells you the project treats packaging as a downstream responsibility. For development work, the repository expects Python 3 and a Makefile-driven flow: the contributing guide is the entry point the README points to. The Makefile shows the local shape of that flow, including a unit test target and a dependency helper.
python3 -m pytest -v tests/unittests cloudinitThe dependency helper resolves what a given distribution needs, which is the honest answer to "how do I install cloud-init on Red Hat" or on Ubuntu: you install the distribution's package, and the tools here are for building from source.
python3 tools/read-dependencies --distro ubuntu --test-distroFor a first real use, the payload you write is user data. cloud-config is the YAML format cloud-init understands. The repository renders its own default configuration from a template, which is the closest thing to a worked example of the format.
python3 ./tools/render-template --is-yaml config/cloud.cfg.tmpl config/cloud.cfgAfter boot, the instance should have applied the configuration you injected. If it does not, the failure is in the boot log, not in a service you can restart, which is the single most important operational fact about this project.
cloud-init versus Ansible, and why the split is real
The comparison people keep making is cloud-init against Ansible, and the difference is timing and state. cloud-init runs during instance initialization, driven by data the platform hands the instance at boot. Ansible connects to a machine that already exists and converges it toward a described state, repeatedly, on demand. cloud-init has no ongoing agent model in the README's description; it initializes, then it is done. That makes it good at the things that must be true before anything else can connect: hostname, keys, network, and a bootstrap package set. It makes it poor at drift correction, at coordinating across a fleet, and at anything you want to re-run next Tuesday. The practical split is to use cloud-init to make the machine reachable and to install whatever your configuration management system needs, then hand off. Trying to express a full application deployment in user data produces a long, order-dependent script with boot-time failure semantics, which is exactly the shape Ansible exists to avoid.
Where cloud-init is the wrong tool
The clearest failure mode is treating user data as a general purpose provisioning language. Commands in user data execute in sequence; there is no idempotence guarantee, no retry policy, and no reporting channel beyond the logs. A command that fails partway leaves an instance that looks booted and is not configured. The second limitation is validation. The requirements list includes jsonschema, described as being for validating cloud-config sections per schema definitions, which means a malformed document is caught against a schema rather than silently ignored, but the feedback arrives during boot on a machine you may be watching only through a console. Third, the datasource model is a discovery model: if your platform is not among the supported datasources, cloud-init has nothing to identify and no metadata to read, and the README's own answer is to talk to your distribution. Fourth, cloud-init is Linux and Unix oriented in the distributions the project lists; people searching for cloud-init on Windows are looking for a different mechanism, and nothing in this material describes Windows support. Finally, the project is mid-refactor by its own admission, with a WIP-ONGOING-REFACTORIZATION.rst at the repository root, so internal module boundaries are moving even while the external interface stays stable.
Licence, packaging and what maintenance costs
The repository root carries LICENSE, LICENSE-Apache2.0 and LICENSE-GPLv3, and the metadata marks the licence as NOASSERTION, meaning no single SPDX identifier was detected for the repository as a whole. For an adopter the practical reading is that the project is dual-licensed across Apache 2.0 and GPLv3 files, and which terms apply to your use depends on the specific files you redistribute or modify. That is not a legal opinion and you should not treat it as one; if you vendor cloud-init into a product image, have someone check the file-level headers. Maintenance cost is low for consumers and moderate for contributors. Consumers get releases on a roughly twice-a-year cadence, with 26.2 in July 2026 and 26.1 in February 2026, and the last push to main was on 2026-09-21, so the branch is live between releases. The upgrade surface is the part to watch: cloud-config keys accumulate, and an image pinned to an old cloud-init may not understand a key a newer one accepts. Verify against the docs for your version rather than assuming forward compatibility.
What to check before you put it in an image
Start with the two supported lists in the documentation: datasources and distributions. If your platform and your OS both appear, the remaining risk is in your payload. Keep user data small, keep the cloud-config header, and prefer structured keys over a shell script, because structured keys go through schema validation while a script does not. Decide deliberately whether vendor data will be used, since it is applied without the instance user's involvement and changes what "my user data is the only input" means. If you are debugging, remember that the interesting output is produced before your SSH session exists, so plan for console or serial access on the first boot of any new image. And if you are building from source rather than consuming a package, the Makefile targets are your map: unittest for the test suite, render-template for turning the templated config/cloud.cfg.tmpl into a concrete config/cloud.cfg, and the packaging targets for rpm and deb builds. The templating step is easy to skip and produces a config that does not match the distribution you think you are targeting.
Editorial conclusion
Adopt cloud-init if you build images for a public cloud, a private-cloud provisioning system or bare metal and you need instance identity, SSH keys and networking set before your own tooling runs. Do not adopt it as a replacement for Ansible or another configuration management system: cloud-init runs at boot, and the README describes it as instance initialization, not ongoing state enforcement. Before rolling it out, verify three things: that your distribution and cloud appear in the supported datasources and distributions lists, that your user data is valid YAML or a script (cloud-init validates cloud-config sections against schemas, and a malformed document fails at boot where you may not be watching), and that your image does not already ship a cloud-init configuration that overrides the one you plan to inject.
Frequently asked questions
What is the difference between cloud-init and cloud-config?
cloud-init is the program that runs at boot and initializes the instance. cloud-config is the YAML user-data format it parses, recognized by a leading #cloud-config line, which is why an ordinary shell script and a cloud-config document are treated differently.
How do I configure cloud-init?
You supply instance data: cloud metadata comes from the platform, and you add optional user data and vendor data. User data is where cloud-config YAML goes, and cloud-init reads it after it has identified the cloud and set up networking.
What are the key differences between cloud-init and Ansible?
cloud-init initializes an instance during boot from data the platform provides, and the README describes it as instance initialization rather than ongoing management. Ansible connects to a machine that already exists and converges it toward a described state on demand, which is why the common pattern is cloud-init for bootstrap and Ansible afterwards.
How do I install cloud-init on Ubuntu or Red Hat?
The README says most supported distributions ship with cloud-init, so installation is normally the distribution's package. The repository's own tooling is for building from source, for example python3 tools/read-dependencies --distro ubuntu --test-distro, and the README directs you to your distribution if it is not on the supported list.
Can cloud-init install packages on first boot?
The README does not enumerate cloud-config keys, so it does not document a packages key directly. What it does say is that cloud-init parses and processes user data passed to the instance, and the requirements list notes that cloud-config sections are validated against schema definitions.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/canonical-cloud-init)Star history chart for your README
[](https://hysenlabs.com/projects/canonical-cloud-init)Was this useful?