LongMemory: A local-first temporal memory engine for LLM agents
Local persistent memory store for LLM applications including claude desktop, github copilot, codex, antigravity, etc.
At a glance
- What is it?
- LongMemory is a TypeScript memory store that adds temporal truth, governance, and explainable recall to LLM applications. It targets developers who need more than vector search, but it brings real complexity.
- Who is it for?
- Adopt LongMemory if your LLM application needs point-in-time truth, supersession handling, and permission-scoped recall, and you are comfortable running a TypeScript service with SQLite. Do not adopt it if a simple vector store or a hosted memory service like Mem0 or Zep covers your needs, because LongMemory's temporal and governance features add operational overhead.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 4 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
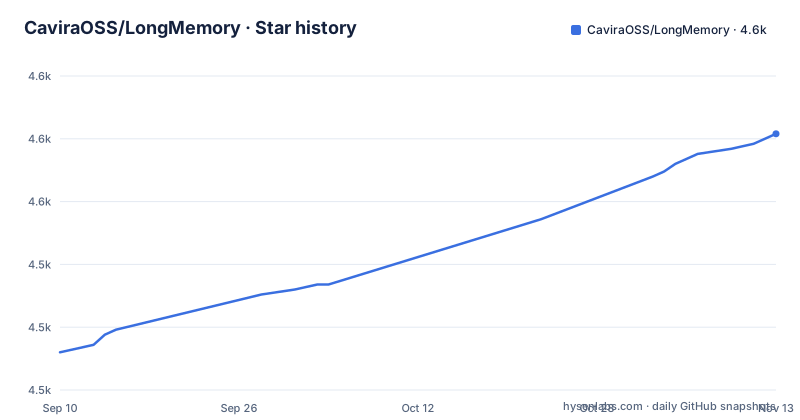
- CaviraOSS/LongMemory4,577 ★ · +87
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| CaviraOSS/LongMemory | 4.5k | 4.6k |
87 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem: retrieval pipelines do not remember
Most LLM memory systems are chunk, embed, and retrieve pipelines. They return nearest vectors, but they cannot answer whether a fact was true in January, which source is authoritative, or why a result belongs in context. LongMemory models those concerns directly. It is for developers building autonomous agents, coding assistants, or chat applications that need durable memory with temporal awareness and access control. The target user is someone who has hit the limits of naive RAG and wants a local-first alternative to hosted memory services.
Architecture: immutable nodes, executable edges, and temporal truth
LongMemory is built on what the README calls a Hydrograph memory substrate. It stores immutable nodes, executable edges, worlds, entities, facets, and traces in SQLite. Each piece of content has a recorded time and a separate valid time. That distinction lets the system keep superseded facts instead of overwriting them. Recall applies gates for temporal consistency, contradictions, confidence, grounding, permissions, and token cost. The design treats memory as a governed graph, not a flat vector index. This is a different assumption from most RAG tools, and it shows in the API.
Recall modes: strict, historical, associative, and world-grounded
The README shows four recall modes. Strict recall applies temporal, contradiction, contract, confidence, and grounding gates. Historical recall accepts a valid_time parameter so you can ask what was true at a past date. Associative recall follows semantic, lexical, entity, activation, and graph signals, which is closer to traditional similarity search. World-grounded recall requires current external evidence before returning a result. These modes are not just flags; they change the retrieval logic. A developer must choose the right mode per query, which adds design work but gives control over hallucination risk.
Getting started: library, CLI, and service
The fastest path is npm. Install longmemory, call createMemory(), ingest text, and recall with a mode. In-memory mode needs no external database. For persistence, pass store: 'sqlite' and a db_path. The CLI offers longmemory init and longmemory recall with a mode flag. To run as a service, clone the repo, run corepack enable, pnpm install --frozen-lockfile, pnpm build, and pnpm start. The API listens on http://127.0.0.1:7331. Docker is available through ghcr.io/caviraoss/longmemory, and a compose file includes an optional dashboard on port 3000. The .env.example file lists the server, request, memory and embedding settings.
Integrations: MCP, agent hosts, and the session porter
LongMemory serves MCP at the same address as its API, http://127.0.0.1:7331, and the Docker Compose file enables MCP over HTTP by default and requires LONGMEMORY_API_KEY. The README lists a session porter for Claude Code, Codex, OpenCode, Gemini CLI, Copilot Chat, Cline, and raw harness logs. That means you can import conversation history from those tools.
Governance and lifecycle: permissions, decay, and consolidation
LongMemory enforces scope at several levels: project, tenant, user, team, role, agent, task, and framework. The README states that these scopes are enforced. Lifecycle management includes deterministic decay, explicit reinforcement, consolidation, compression, and reconsolidation. That is a serious feature set for a local-first project. The trade-off is that you must design your scoping model up front. If you ingest everything under a single tenant and user, the governance machinery adds no value and only increases complexity.
Limitations and wrong-tool cases
LongMemory is not a drop-in vector database. Its recall modes require you to think about temporal validity and grounding, which is overkill for simple FAQ lookup. The README lists multilingual memory with script detection, code switching, transliteration and cross-language embeddings. Embedding providers include OpenAI-compatible APIs, Gemini, AWS Bedrock, Ollama, Siray, and local HTTP models. The project is in beta at v1.3.0, and the last push is dated 2026-10-18, which suggests active development, but also that APIs may still change. If you need a mature, widely adopted memory layer with a large community, this may not be it yet.
Alternatives: Mem0, Zep, and plain vector stores
Mem0 and Zep are other memory layers built for LLM agents. For teams that only need semantic search, a plain vector database like SQLite with sqlite-vec or a dedicated store like Qdrant is simpler and faster to operate. LongMemory's local-first, Apache-2.0 approach gives you full control, but you must run and maintain it yourself.
Maintenance and upgrade cost
LongMemory is Apache-2.0 licensed, so you can fork and modify it without commercial restrictions. The project is written in TypeScript and uses pnpm with a frozen lockfile, which suggests a reproducible build. The repository carries a MIGRATION.md at its root, and the beta status means upgrades could introduce breaking changes. The SQLite database stores nodes, worlds, entities, edges, temporal history, grounding, and lifecycle state, so you need to back up that file and understand its schema before upgrading. Plan to test each release in a staging environment. The dashboard and VS Code extension add more surfaces to update, so the maintenance cost is higher than a simple library.
Editorial conclusion
Adopt LongMemory if your LLM application needs point-in-time truth, supersession handling, and permission-scoped recall, and you are comfortable running a TypeScript service with SQLite. Do not adopt it if a simple vector store or a hosted memory service like Mem0 or Zep covers your needs, because LongMemory's temporal and governance features add operational overhead. Before committing, verify that the MCP surface and the recall modes match your agent's actual workflow, and test the multilingual and embedding provider paths with your data.
Frequently asked questions
What is LongMemory, the CaviraOSS memory engine?
It is a TypeScript engine for durable, temporal memory in LLM applications, backed by SQLite. It records time separately from validity time, keeps content immutable, and enforces project, tenant, user, team, role, agent and task scopes.
In LongMemory, how do short context and long-term storage differ?
Recall is bounded by relevance, contradictions, grounding, permissions and token cost, and the default max context is 2048 tokens, so an answer is a small excerpt. Storage is the durable side, kept in SQLite and restored on reopen along with temporal history and lifecycle state.
How do I improve what LongMemory keeps over time?
The lifecycle includes deterministic decay, explicit reinforcement, consolidation, compression and reconsolidation, with consolidation and the cold log switched off by default through LONGMEMORY_ENABLE_CONSOLIDATION and LONGMEMORY_ENABLE_COLD_LOG. Turning them on changes what survives between sessions.
What does a long memory mean in the LongMemory model?
Recorded time and valid time are separate, which is what lets historical recall preserve superseded truth while strict recall returns only what holds now. A historical query carries its own valid_time instead of asking the engine to guess the moment.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/caviraoss-longmemory)Star history chart for your README
[](https://hysenlabs.com/projects/caviraoss-longmemory)Was this useful?