Chaos Mesh: Kubernetes-Native Fault Injection with a Dashboard, but Mind the Privilege Model
Project brief: A Chaos Engineering Platform for Kubernetes. To lower the threshold for a Chaos Engineering project, Chaos Mesh provides you with a visualization operation.
At a glance
- What is it?
- Chaos Mesh brings chaos experiments into Kubernetes as custom resources, with a controller, a node-level daemon, and an optional dashboard. It covers many fault types, but its privileged daemon and multi-cluster design deserve scrutiny before adoption.
- Who is it for?
- Adopt Chaos Mesh if you run Kubernetes and need a broad, declarative chaos toolkit with a UI for teams that prefer not to write YAML by hand. Skip it if your clusters forbid privileged DaemonSets or if you only need simple pod deletion, where lighter tools or native kubectl suffice.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
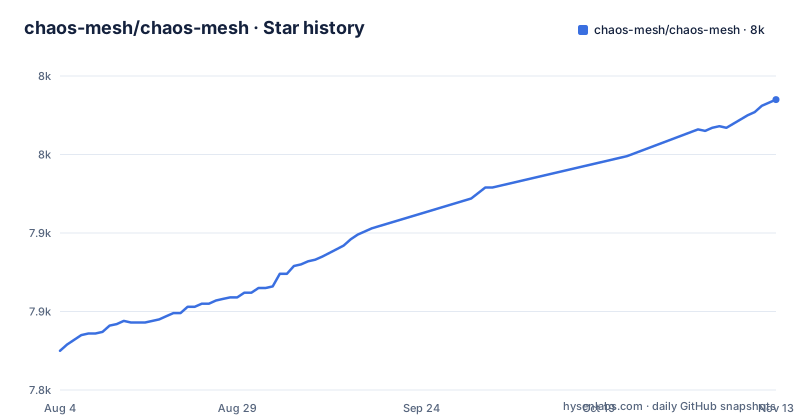
- chaos-mesh/chaos-mesh7,985 ★ · +160
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| chaos-mesh/chaos-mesh | 7.8k | 8k |
160 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Chaos Mesh Actually Solves
Chaos Mesh targets a specific gap: running controlled fault injection inside Kubernetes without bolting on external tooling. Instead of SSH-ing into nodes or scripting random kills, you declare an experiment as a Kubernetes custom resource. The project's README lists fault coverage across pod, network, DNS, HTTP, I/O, time, stress, kernel, block device, JVM, physical machine, AWS, Azure, and GCP. That range is unusually wide for an open source chaos tool, and it is the main reason to look at Chaos Mesh rather than a simple pod-killer script. The intended user is a Kubernetes operator or SRE who wants experiments to be auditable, repeatable, and managed through the same API as the workloads they test. The dashboard lowers the entry barrier for teams that do not live in kubectl, which matches the README's claim about visualization lowering the threshold for starting a chaos engineering project.
The Three-Runtime Architecture and How Faults Flow
Chaos Mesh splits into three components, and the split matters for understanding what happens when you create an experiment. The Chaos Controller Manager watches custom resources, validates requests through admission webhooks, and coordinates injection and recovery. The Chaos Daemon runs as a DaemonSet on every node and performs the actual privileged operations: touching runtimes, processes, networks, filesystems, clocks, and kernels. The Chaos Dashboard is optional and only provides an HTTP API and web UI. The data flow is straightforward: you create or update a resource through the Kubernetes API, either directly or via the dashboard, the controller reconciles the desired state, and it delegates node-level work to the daemon. This design keeps the control plane separate from the execution plane, which is clean, but it also means the daemon must run with elevated privileges on every node. That is a real operational constraint, not a cosmetic one. The README does not detail the exact privilege flags, but the mention of privileged node- and container-level operations is enough to signal that this is not a namespaced-only tool.
Getting It Running: Helm and the First Experiment
The README points to the production installation guide for Helm, and the artifacthub link confirms a Helm chart exists. The quick start path is to install via Helm, then create a chaos resource. The documentation, not the README, covers the exact `helm install` command, but the repository layout includes `helm/chaos-mesh/README.md` for chart details. For a first experiment, you would apply a YAML manifest that defines a `PodChaos` or `NetworkChaos` resource. The README mentions a Killercoda playground where you can try PodChaos and NetworkChaos on a real two-node cluster in about twenty minutes, which is a practical way to see the flow without setting up a cluster yourself. The dashboard is optional, so you can manage everything through kubectl if you prefer. The exact schema is in the docs, not the README, so plan to read those pages before writing your first manifest.
Experiment Orchestration: Schedules, Workflows, and Status Checks
Beyond single-shot experiments, Chaos Mesh offers three orchestration resources: `Schedule` for recurring experiments, `Workflow` for serial or parallel chains, and `StatusCheck` for application health checks. This is where Chaos Mesh moves from a fault injector to a testing framework. A workflow lets you define a sequence of failures, for example a network partition followed by a pod kill, and a status check can test application health. The README describes these as supporting recurring experiments and serial or parallel workflows. That design is useful for building a regression suite, but it also adds complexity. You are not just writing a single chaos YAML; you are composing a pipeline. Teams that only want a one-off test may find the orchestration layer overkill. The README also recommends a blog post on building an automated testing framework based on Chaos Mesh and Argo.
Multi-Cluster Execution and the Management Hub
Chaos Mesh supports managing remote clusters from a single management cluster. The README says you can manage remote clusters and dispatch supported chaos experiments from a management cluster. That is a significant feature for larger environments, but it comes with caveats. The README does not specify which fault types are supported remotely versus locally, so you must check the documentation for the exact matrix. This multi-cluster design is a differentiator compared to tools that only work in a single cluster, but it also increases the operational surface.
Limitations and Wrong-Tool Cases
The most obvious limitation is the privilege model. Chaos Daemon performs privileged node-level operations, which means it can affect other containers on the same node. The README even has a blog post about simulating clock skew without affecting other containers, which suggests that isolation is a known concern and not always guaranteed. If your security policy forbids privileged DaemonSets, Chaos Mesh is the wrong tool unless you can run it in a dedicated cluster. Another limitation is the learning curve for the full resource schema. The README lists many fault types, but each has its own configuration. A team that only needs to test pod restarts might find the CRD complexity excessive. Finally, the project is a CNCF incubating project, which signals maturity but not a guarantee of long-term maintenance, though the release cadence (v2.8.5, v2.8.6 and v2.8.7, all in October 2026) shows active development.
Alternatives and How They Differ
The most direct alternative is Litmus, another Kubernetes-native chaos platform. Another alternative is to skip a dedicated platform and use `kubectl delete pod` or `kubectl exec` to inject faults manually. That approach has zero install cost but no orchestration, no dashboard, and no audit trail. For network faults, you could use `tc` commands directly, but that requires node access and does not integrate with Kubernetes RBAC. The README does not mention Litmus, but the comparison is fair because both target the same problem.
Maintenance, Upgrades, and License Notes
Chaos Mesh is Apache-2.0, which means you can use it commercially without copyleft obligations, and the license is permissive for embedding or modifying. The project is a CNCF incubating project, which usually implies a governance structure and a path to graduation, but it is not a guarantee of API stability. The release history shows regular patch releases (v2.8.5, v2.8.6, v2.8.7) within about two weeks in October 2026, which suggests active bug fixes. Upgrading likely involves updating the Helm chart and the CRDs, and the README points to a supported-releases page that you should check before planning an upgrade. The admission webhooks are a critical part of the controller, so a failed upgrade could break experiment creation. There is no mention of a migration tool or a compatibility guarantee between minor versions, so you should test upgrades in a non-production cluster. The documentation is the primary source for upgrade steps, and the README does not provide a rollback procedure, so budget time for that.
Editorial conclusion
Adopt Chaos Mesh if you run Kubernetes and need a broad, declarative chaos toolkit with a UI for teams that prefer not to write YAML by hand. Skip it if your clusters forbid privileged DaemonSets or if you only need simple pod deletion, where lighter tools or native kubectl suffice. Before committing, verify your Kubernetes version against the supported-releases matrix, test the Helm chart in a staging cluster, and review the RBAC and admission webhook requirements, since the daemon's privileged node access is a real security boundary you must accept.
Frequently asked questions
What is chaos mesh?
An open source, cloud-native Chaos Engineering platform for Kubernetes. It uses Kubernetes custom resources to define, orchestrate and observe controlled fault injection against workloads, infrastructure, cloud services and applications, and it is a CNCF incubating project.
is chaos mesh open source
Yes, under the Apache License 2.0, and it is a Cloud Native Computing Foundation incubating project. The repository also carries a governance document, a maintainers file, a code of conduct and its own security policy.
how to install chaos mesh
With Helm, following the production installation instructions on the project site. There is also an interactive Killercoda playground that installs Chaos Mesh on a real two-node Kubernetes cluster in the browser and walks through PodChaos and NetworkChaos experiments in about twenty minutes.
how to use chaos mesh
Chaos experiments are custom resources managed through the Kubernetes API using standard tooling and RBAC, or through the Dashboard. The Controller Manager reconciles them and delegates node-level operations to the Chaos Daemon, and the Schedule, Workflow and StatusCheck resources support recurring experiments, serial or parallel sequences, and health checks.
chaos mesh alternatives
The README names no alternatives and makes no comparison. What it documents is its own coverage across pod, network, DNS, HTTP, I/O, time, stress, kernel, block device, JVM, physical machine and cloud faults, across three runtime components.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chaos-mesh-chaos-mesh)Star history chart for your README
[](https://hysenlabs.com/projects/chaos-mesh-chaos-mesh)Was this useful?