ChaosBlade: a CLI for injecting faults into hosts, JVMs and Kubernetes
An easy to use and powerful chaos engineering experiment toolkit, open-sourced by Alibaba.
At a glance
- What is it?
- ChaosBlade is Alibaba's open source chaos engineering toolkit, built around a single blade command and a set of per-domain exec projects. It suits teams that already run Kubernetes or JVM services and want scriptable fault injection, not a hosted dashboard.
- Who is it for?
- Adopt ChaosBlade if you already run Kubernetes or a JVM fleet and want fault injection expressed as CLI commands and CRDs that fit existing pipelines; the operator and the blade binary are the two pieces you must deploy first. Do not adopt it if you need a hosted control plane with built-in scheduling and reporting, because the repository's core is an execution tool and the platform layer lives in the separate chaosblade-box project.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
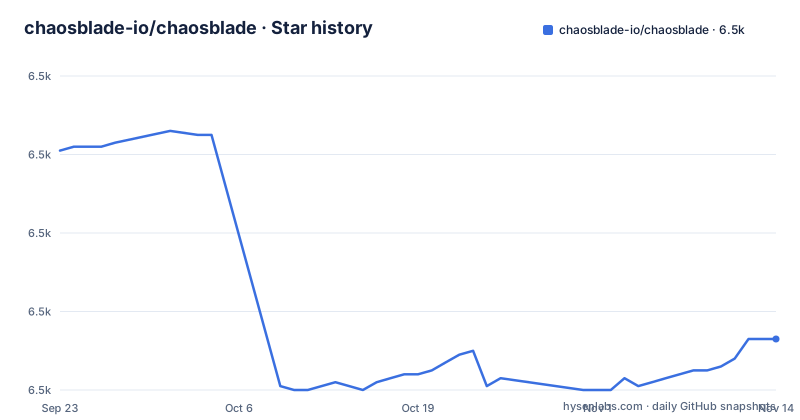
- chaosblade-io/chaosblade6,473 ★ · -48
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| chaosblade-io/chaosblade | 6.5k | 6.5k |
-48 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap ChaosBlade fills between a test suite and a real failure
Unit tests and integration tests check that code behaves when dependencies answer. They rarely check what happens when a dependency stops answering, when a node runs out of memory, or when a method returns a corrupted value. ChaosBlade exists to inject exactly those conditions on purpose, so a team can watch how a distributed system degrades before a real incident does it for them. The README frames the goal as helping enterprises improve fault tolerance while they move to cloud or cloud native systems, and states that the project draws on Alibaba's failure testing and drill practice.
The intended audience is not application developers writing their first service. It is site reliability engineers, platform teams and test engineers who own a cluster or a fleet of JVMs and need to reproduce a failure on demand. That shows in the scenario list: CPU, memory, network, disk and process on basic resources; databases, caches, messages and JVM internals for Java; arbitrary class methods for Java and C++; containers; and Kubernetes nodes, Pods and containers. A team that only wants to unit test a function has no use for any of this.
How the blade CLI and the per-domain exec projects fit together
ChaosBlade is not one binary that knows every fault. The README describes it as a set of projects packaged by domain, with the main chaosblade repository acting as the experiment management tool: it creates, destroys and queries experiments, and prepares or cancels the environment an experiment needs. Execution is exposed through both a CLI and HTTP, according to the README.
The domain logic lives elsewhere. chaosblade-exec-os implements basic resource scenarios, chaosblade-exec-docker talks to the Docker API, chaosblade-exec-cri talks to the CRI, chaosblade-exec-jvm mounts a Java Agent dynamically, and chaosblade-exec-cplus uses GDB to reach methods and code lines in C++ programs. chaosblade-operator defines Kubernetes experiments as CRDs, so a fault can be created, updated and deleted with kubectl or client-go. The go.mod file in the main repository confirms the split at the dependency level: it requires chaosblade-exec-cloud v1.8.0, chaosblade-exec-cri v1.8.1, chaosblade-exec-middleware v1.8.0, chaosblade-exec-os v1.8.2 and chaosblade-spec-go v1.8.0, alongside k8s.io/client-go and controller-runtime.
That modular layout is the design's main strength and its main cost. You get one command vocabulary across very different targets, but you also inherit a dependency chain: the version of the exec modules matters, and the operator is a separate release from the CLI.
Installing the blade CLI and running a first Kubernetes experiment
The README's Quick Start targets Kubernetes and claims a first fault injection in under five minutes. It lists three prerequisites: kubectl access to a running cluster, a target namespace with at least one running Pod, and ChaosBlade installed. Installation means two downloads. The chaosblade CLI toolkit comes from the chaosblade releases page and must be extracted so the blade binary is on your PATH. The chaosblade-operator comes from its own releases page and must be deployed to the cluster, because Kubernetes scenarios require it. The README begins the operator install with Helm:
helm install chaosblade-operator chaosblade-operator-<version>.tgz --namespace chaosblade --create-namespaceVerify the operator with `kubectl get pods -n chaosblade`. The Quick Start's minimal example then injects a CPU full-load fault into a Pod with `blade create k8s pod-cpu fullload --cpu-percent 80 --kubeconfig ~/.kube/config --names <pod-name> --namespace default`; on success ChaosBlade returns a JSON result containing an experiment `uid`, which you save to check status or destroy the experiment later.
The build path is documented separately. The Dockerfile shows a two-stage build using golang:1.20.5 as the builder and alpine:3.23.3 as the runtime, with BLADE_VERSION and MUSL_VERSION as build arguments, and it produces a directory under /usr/local/chaosblade. The Makefile derives BLADE_VERSION from a Git tag when the environment variable is not set, falling back to 1.8.0, and requires Git 1.8.5 or newer. If you build from source rather than download a release, those are the constraints you inherit.
Where ChaosBlade is the wrong tool
The most obvious limitation is operational scope. ChaosBlade injects faults; the core tool is not described as scheduling game days. The README points to chaosblade-box as the project that carries chaos engineering platform and resilience testing platform capabilities, which means the scheduling and reporting layer is a different repository with its own release cycle. If your requirement is a single system that plans experiments and shows you a dashboard, the core repository is only half of what you need.
There is also a safety surface to think about. The exec projects reach into running processes: chaosblade-exec-jvm mounts a Java Agent dynamically, and chaosblade-exec-cplus uses GDB to inject delays or tamper with variables and return values. Those are powerful mechanisms aimed at live applications, and the README describes the JVM agent as supporting uninstallation and full recycling of the resources it creates. Whether cleanup succeeds in your environment is something you have to confirm yourself.
ChaosBlade and Chaos Mesh: two answers to the same question
The natural comparison is Chaos Mesh, and the difference is architectural. ChaosBlade's Kubernetes support is expressed through chaosblade-operator, which defines experiments as CRDs so they can be created, updated and deleted with standard Kubernetes resource operations, per the README. The CLI remains the common entry point across domains: the same tool that injects a disk fault on a host can target a Pod.
ChaosBlade's scope reaches beyond the cluster by design. The exec projects cover OS-level resources, Docker and CRI containers, Java applications through a dynamically mounted agent, and C++ applications through GDB. If your failure testing stops at the cluster boundary, a Kubernetes-only tool is a simpler dependency. If you also need to inject a delay into a specific Java method or corrupt a variable in a C++ binary, ChaosBlade's model is the one that reaches there. The trade-off is that you are assembling more pieces: a CLI, an operator, and the matching exec modules.
Maintenance, licensing and what each release costs you
The repository is not archived, and the last push was on 2026-10-29. The most recent releases are v1.8.2 and v1.7.6, both on 2026-10-15, and v1.8.1 on 2026-09-29. The README also announces the Blade AI agent layer, released as blade-ai-v0.1.0, which it describes as invoking ChaosBlade for fault injection while adding intent understanding, security auditing, effect verification, safe recovery and structured reporting on top. That is a separate component from the classic blade CLI, and it is worth deciding early whether you want it in scope.
The licence is Apache-2.0, which permits commercial use and modification with the usual attribution and notice requirements; the repository ships a licenserc.toml, which suggests automated licence header checks. This is a description of the licence file, not legal advice, and you should have your own counsel review it for your distribution model.
Upgrade cost is real because the pieces version independently. The go.mod pins the exec modules between v1.8.0 and v1.8.2 while the Makefile defaults BLADE_VERSION to 1.8.0 and prefers a Git tag when one exists, so a source build can silently pick up a different version than a downloaded release. On Kubernetes, the operator is released separately from the CLI, which means an upgrade is two coordinated steps rather than one.
Editorial conclusion
Adopt ChaosBlade if you already run Kubernetes or a JVM fleet and want fault injection expressed as CLI commands and CRDs that fit existing pipelines; the operator and the blade binary are the two pieces you must deploy first. Do not adopt it if you need a hosted control plane with built-in scheduling and reporting, because the repository's core is an execution tool and the platform layer lives in the separate chaosblade-box project. Before trusting it in production, verify that the chaosblade-operator release matching your cluster version deploys cleanly, that the blade binary is on your PATH, and that you can create and then destroy one experiment in a non-production namespace.
Frequently asked questions
What is ChaosBlade used for?
It is a chaos engineering experiment toolkit for injecting faults into basic resources such as CPU, memory, network, disk and process, into Java and C++ applications, into containers, and into Kubernetes nodes and Pods. The README describes it as helping enterprises improve fault tolerance of distributed systems.
How do I install ChaosBlade?
Download the chaosblade CLI toolkit from its releases page and extract it so the blade binary is on your PATH, then deploy chaosblade-operator to your cluster from its own releases page, since Kubernetes scenarios require it. The README's Quick Start lists kubectl access and a namespace with a running Pod as the other prerequisites.
Does ChaosBlade work with Kubernetes?
Yes. chaosblade-operator implements Kubernetes platform scenarios by defining chaos experiments as CRDs, so they can be created, updated and deleted with kubectl or client-go, and the chaosblade CLI can also be used. The operator must be deployed separately from the CLI.
How is ChaosBlade different from Chaos Mesh?
ChaosBlade covers more than the cluster: its exec projects target OS resources, Docker and CRI containers, Java applications through a dynamically mounted agent, and C++ applications through GDB, with the CLI as a common entry point.
What is Blade AI in the ChaosBlade repository?
The README describes Blade AI as the intelligent agent layer of the ChaosBlade ecosystem: it invokes ChaosBlade to execute fault injection and adds intent understanding, security auditing, effect verification, safe recovery and structured reporting. The README links its release, blade-ai-v0.1.0, and a blade-ai-v0.1.0 code branch.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chaosblade-io-chaosblade)Star history chart for your README
[](https://hysenlabs.com/projects/chaosblade-io-chaosblade)Was this useful?