Langchain-Chatchat: A local-first RAG and Agent toolkit for Chinese LLMs
GitHub describes it as Langchain-Chatchat (formerly Langchain-ChatGLM), a local-knowledge-based LLM RAG and agent app (supporting models like ChatGLM, Qwen and Llama) built with LangChain. The repository metadata lists Python as its primary language. The metadata lists the Apache-2.0 license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- Langchain-Chatchat builds a knowledge-base Q&A app on Langchain, supporting local models like ChatGLM, Qwen, and Llama via Xinference, Ollama, and other frameworks. The 0.3.x rewrite shifts to an Agent-first architecture, but you must supply your own model serving and accept a setup that is not turnkey.
- Who is it for?
- Adopt Langchain-Chatchat if you need a Chinese-friendly, offline RAG and Agent interface and you are comfortable managing your own model serving stack via Xinference, Ollama, or FastChat. Do not adopt it if you expect a one-command install or want a stable, mature Agent pipeline; the latest release (v0.3.1) dates from July 2024 and the README itself marks 0.2.x Agent as unstable.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 12 months ago, on November 10, 2025.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
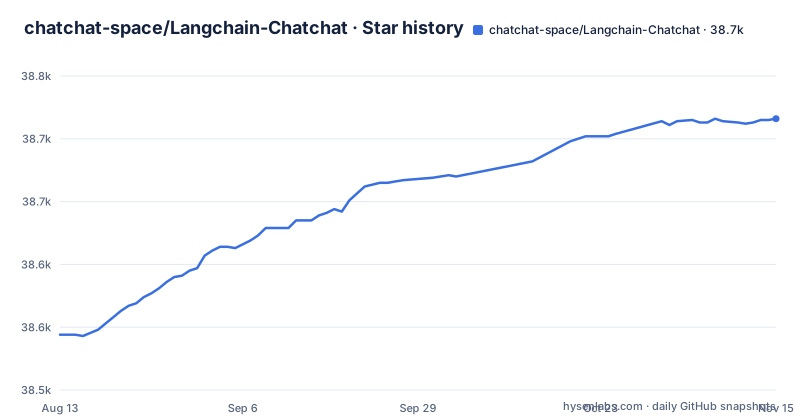
- chatchat-space/Langchain-Chatchat38,716 ★ · +172
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| chatchat-space/Langchain-Chatchat | 38.5k | 38.7k |
172 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What this project actually solves
Langchain-Chatchat targets a specific pain: building a knowledge-base Q&A system that runs entirely on open-source models, offline, with good support for Chinese. The README states this goal directly: a solution that is friendly to Chinese scenarios and open-source models, and that can run offline. It is not a hosted service or a model itself. It is an application layer that connects a document store, an embedding model, a vector database, and a chat LLM. The intended user is a developer or team that wants to deploy a private Q&A bot over their own documents, without sending data to a commercial API. The project also supports OpenAI GPT API calls, but the core value proposition is local deployment. If your corpus is mostly Chinese, the project's design choices, such as compatibility with ChatGLM and Qwen, make it more relevant than generic RAG frameworks that assume English-centric models.
The 0.3.x architecture: Agent-first, not just RAG
The 0.3.x version is a significant departure from 0.2.x. The README's feature table shows that 0.3.x moves Agent from 'unstable' to 'optimized for ChatGLM3 and Qwen', and it adds capabilities like database chat, multimodal image chat, ARXIV chat, Wolfram chat, and text-to-image. The core shift is that Agent is now the central mechanism, not an add-on. The table also explains that users can either let the LLM automatically choose tools (when using an Agent-capable model), or force a single tool and let the LLM only parse arguments, or skip Agent entirely and manually fill in tool parameters. This flexibility is practical because not all models have strong function-calling abilities. The underlying RAG flow remains the classic pipeline: load files, read text, split text, vectorize, match top-k chunks, then stuff the context into a prompt for the LLM. That is standard Langchain territory. The novelty is the orchestration layer that ties multiple tools, including search and image generation, into one interface.
Getting it running: pip, source, or Docker
The README lists three installation paths: pip, source, and Docker. For source installation, you clone the repository and follow the development guide in docs/contributing/README_dev.md. Docker deployment is mentioned, but the README notes that the Docker image is 'will be updated soon' and the AutoDL image for 0.3.0 is available. A critical detail is that Langchain-Chatchat does not include model weights. You must separately start a model serving framework like Xinference, Ollama, or FastChat, then edit configuration files to point the app to those endpoints. The README's table shows that all these frameworks align with the OpenAI API, which simplifies integration. For embeddings and rerankers, you also need to run a serving framework that supports those model types. This is not a single-command install; it is a multi-component setup.
Model serving frameworks and their constraints
The project supports four local model deployment frameworks: Xinference, LocalAI, Ollama, and FastChat. Each has different capabilities. Xinference and LocalAI support the widest range of model types, including LLM, Embedding, Rerank, Text-to-Image, Vision, and Audio. Ollama supports LLM, Text-to-Image, and Vision, but not Embedding or Rerank directly. FastChat supports LLM and Vision, but lacks function calling, which is a hard blocker for Agent use. The README also lists acceleration engines: Xinference supports GPTQ, GGML, vLLM, TensorRT, and mlx; Ollama uses GGUF and GGML; FastChat uses vLLM. This matters because the model format you choose affects performance and hardware requirements. If you want to use the Agent features with a local model, you must pick a framework that supports function calling, which rules out FastChat. The README recommends qwen-vl-chat for multimodal image chat, so that is another model you need to serve separately.
The Agent tool selection matrix
One of the most useful parts of the README is the table that maps four operation modes to model capabilities. If you enable Agent and select multiple tools, the LLM automatically decides which tool to call; this works with ChatGLM3, Qwen, or online APIs that have Agent abilities. If you enable Agent but select a single tool, the LLM only parses arguments, which suits models with weak tool-selection ability. If you disable Agent and select one tool, you manually fill in the parameters, which works for models with no Agent capability at all. Finally, if you select no tools and upload an image, you get image chat with a multimodal model. This design acknowledges that not all models are equal. It is a pragmatic compromise, but it also means the user must understand their model's capabilities before configuring the UI.
Limitations and failure modes
The most obvious limitation is that this project is not a model, and it does not fine-tune or train anything. The README explicitly says: 'This project does not involve fine-tuning or training, but fine-tuning can be used to optimize the project's effects.' That means retrieval quality depends entirely on your chunking, embedding, and vector database choices. Another limitation is that the latest release, v0.3.1, dates from July 2024 and the last push was on 2025-11-10. The releases show v0.3.0 in June 2024 and v0.3.1 in July 2024, with a gap of several months after v0.2.10. The README's own table marks 0.2.x Agent as unstable, and while 0.3.x claims improvement, there is no evidence of maturity beyond the project's own claims. The Docker image is 'will be updated soon', which suggests the containerized path lags behind the source releases. If you need a production-ready system with support contracts, this project is not that.
Alternatives and how they differ
A direct alternative is to build a RAG pipeline using Langchain directly, without this project's UI and Agent layer. That gives you full control over each component, but you lose the pre-built WebUI, the multi-tool orchestration, and the Chinese-oriented model compatibility that Chatchat provides.
Maintenance and license considerations
The project is licensed under Apache-2.0, which is permissive and allows commercial use, modification, and distribution, with the condition of preserving copyright notices. That is a plus for teams that need to embed the code in proprietary products. The maintenance cadence is visible in the release history: v0.2.10 in January 2024, then a jump to v0.3.0 in June 2024, and v0.3.1 a few weeks later. That shows a major rewrite between versions; the latest release is v0.3.1 from July 2024 and the last push was on 2025-11-10. Upgrading from 0.2.x to 0.3.x is not trivial because the model access layer changed from fastchat to model_provider and the Agent architecture changed. The README notes that the AutoDL image for 0.3.0 uses the v0.3.0 code, so you can use that as a reference for deployment. The project has a contributing guide. If you adopt this, plan to test upgrades carefully.
Editorial conclusion
Adopt Langchain-Chatchat if you need a Chinese-friendly, offline RAG and Agent interface and you are comfortable managing your own model serving stack via Xinference, Ollama, or FastChat. Do not adopt it if you expect a one-command install or want a stable, mature Agent pipeline; the latest release (v0.3.1) dates from July 2024 and the README itself marks 0.2.x Agent as unstable. Before committing, verify that your chosen model framework supports function calling (FastChat does not) and that your hardware meets the VRAM and RAM demands of your selected models. Then test the file RAG path with your actual documents, because retrieval quality depends on chunking and embedding choices you must configure yourself.
Frequently asked questions
What is ChatChat?
ChatChat is the package name recorded in pyproject.toml for Langchain-Chatchat, a self-hosted RAG and Agent application formerly known as Langchain-ChatGLM. It pairs a local model server with langchain, exposes a FastAPI service and ships a Streamlit WebUI.
Which Python versions does Langchain-Chatchat support?
pyproject.toml declares python = ">=3.8.1,<3.12,!=3.9.7", so 3.12 and newer are outside the range and 3.9.7 is excluded by name. The repository's last push was on 2025-11-10.
How do I deploy Langchain-Chatchat?
The README gives three routes: a pip installation, a source installation for development, and Docker, with contributor detail in docs/contributing/README_dev.md. The model serving framework has to be started separately by you and then connected through configuration, and the README says the Docker image will be updated in the near future.
Which model serving frameworks can Langchain-Chatchat connect to?
Xinference, LocalAI, Ollama and FastChat, all aligned to the OpenAI API interface. Ollama covers LLM, Text-to-Image and Vision, FastChat covers LLM and Vision with no Function Call support, and only Xinference lists the mlx acceleration engine.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/chatchat-space-langchain-chatchat)Star history chart for your README
[](https://hysenlabs.com/projects/chatchat-space-langchain-chatchat)Was this useful?