Hubble reads Cilium's eBPF flow data as one event stream
Hubble - Network, Service & Security Observability for Kubernetes using eBPF
At a glance
- What is it?
- Hubble turns the flow records Cilium collects with eBPF into a queryable stream, a service map and network metrics for Kubernetes clusters. The core components are stable and the graphical UI is not.
- Who is it for?
- Adopt Hubble if your cluster already runs Cilium and you want to know why a call between two pods failed without inserting a sidecar into the path. Do not adopt it as a replacement for a tracing backend, and do not expect answers about traffic that never crosses the Cilium hooks, because no flow record is created for it.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Makefile, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
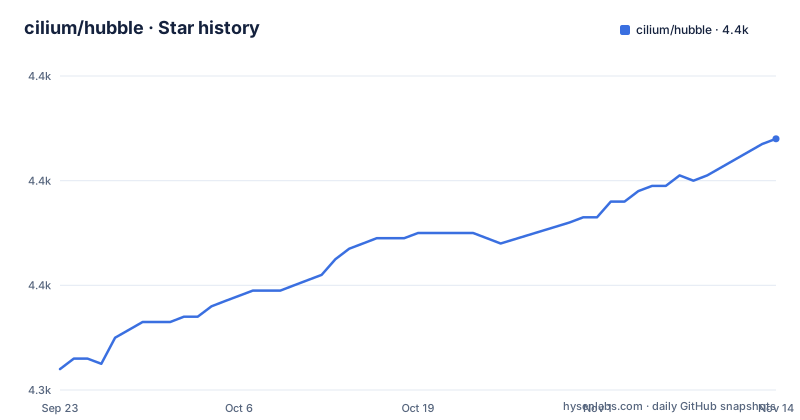
Star history
- cilium/hubble4,388 ★ · +44
| Repository | 2026-09-23 | 2026-11-14 |
|---|---|---|
| cilium/hubble | 4.3k | 4.4k |
44 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The flow record that eBPF produces and Hubble makes queryable
Every Hubble command is a query against the same object: a flow record emitted by the Cilium datapath. That record carries source and destination as pod name plus namespace, the layer of the exchange, the verdict, and a decoded L7 payload depending on protocol. DNS queries, TCP connection state changes, HTTP request and response pairs, and Kafka traffic all arrive in that shape.
The same fields answer the questions the README puts forward, from the rate of 4xx and 5xx responses for one service across all clusters to 95th and 99th percentile latency between two of them. Because those answers are filters over one record type rather than separate subsystems, an operator can move from a latency spike to the specific DNS failure that preceded it without switching tools.
The point of the design is that you do not change your application to get it. Cilium attaches its eBPF programs to the kernel networking path, so a sidecar proxy never has to parse or forward traffic on Hubble's behalf. If a packet never reaches the Cilium hooks, no record exists, and Hubble has nothing to show you.
That dependency cuts both ways and it is the single most important thing to understand before adopting the project. Hubble is not a standalone network monitor you can point at any Kubernetes cluster. Without the Cilium datapath underneath it, the stream is empty.
A service map derived from observed traffic rather than from manifests
Hubble builds its service dependency map from observed flows, not from Deployment and Service objects in your manifests. The README makes the gap explicit: looking at kubectl get pods does not tell you which services talk to which, or which ones reach an external API or a database. The map appears at L3 and L4 and extends to L7 where protocol decoding is available.
That distinction matters during an incident. A dependency drawn from a manifest is what you intended. A dependency drawn from a flow is what happened, which includes the shadow traffic nobody declared: a client falling back to a hardcoded IP, a pod reaching a database that no Service object declares, a sidecar reaching a metadata endpoint.
The flip side is that the map is only as complete as the traffic you observe. A dependency exercised once a week may not appear in a window you happened to be looking at, and a service that has never run has no edge at all.
Relay is what turns per-node records into a cluster-wide stream
Flow records originate on individual nodes. Hubble Relay exists to move them between nodes so a single hubble observe invocation against one relay returns events from across the cluster.
This is the part of the architecture that surprises an operator first. A per-node Hubble setup answers questions about one node. The relay is what makes the service map a cluster object rather than a per-node object, and it is also the component that has to be sized and monitored once traffic volume grows.
The stability table splits the project along exactly this line. Four of the five components, the CLI, the server, the metrics pipeline and Relay, are listed as stable in the Core and Multinode areas. Hubble UI, which consumes that same stream, is the only component marked Beta and is flagged as needing caution in critical production workloads.
Getting the CLI and reading your first DNS failure
The README points at GitHub Release artifacts for the supported line, so the first step is downloading a prebuilt hubble binary. Building from a clone is the other route, since the repository's Makefile drives a Go build with CGO disabled and produces a single executable named hubble.
Once that binary is on your path and your cluster already runs Hubble-enabled Cilium, the first useful thing to do is ask which pods received a failed DNS answer in the last minute. The README gives this exact pipeline, which selects on the DNS rcode field of the JSON output, maps each record to namespace and pod name, and counts repeats so a chatty pod stands out.
hubble observe --since=1m -t l7 -o json \
   | jq 'select(.l7.dns.rcode==3) | .destination.namespace + "/" + .destination.pod_name' \
   | sort | uniq -c | sort -r
In the output shown in the README, one pod in the starwars namespace accounts for 42 NXDOMAIN responses while the rest of the workload resolves cleanly, which is the kind of single-line answer that is hard to get from kubectl describe.
Only the newest CLI is maintained, so version skew lands on you
The README states that the Hubble CLI is backward compatible with all supported Cilium releases and that, for this reason, only the latest Hubble CLI version is maintained. That is a deliberate choice with a cost. There is no supported older binary to fall back to when a new CLI misbehaves against your cluster.
The version table in the README lists a single row, v1.20 (v1.20.2, released 2026-10-01), marked maintained and covering Cilium 1.20 and older. That matches go.mod, which requires github.com/cilium/cilium v1.20.2.
Check that pairing before you upgrade anything.
Where Hubble stops and your metrics backend takes over
Hubble is a flow and topology tool with a metrics export attached. Its four listed metric areas are networking behavior, network policy observation, HTTP request and response rate and latency, and DNS request and response monitoring. Those become counters and histograms, and the natural home for them is an existing Prometheus-style stack that stores and alerts on them.
The real alternative to Hubble for network debugging is packet capture on the node, tcpdump or an equivalent, and sometimes a full service mesh such as Istio. The difference in approach is what each one samples. Hubble reads structured records the kernel datapath already produced for policy enforcement, and it can be correlated with policy verdicts and pod identity without reassembling packets. Packet capture sees every byte including plaintext inside the node, which is more complete and far more expensive to store and to search.
A service mesh proxy architecture gets similar L7 telemetry by inserting a proxy per workload, and it also brings retry budgets, circuit breaking and mTLS as part of the same insertion. Hubble adds none of those. It observes what Cilium already does.
What a team gets and loses when it turns Hubble on
The strongest case is security forensics inside the cluster. The README lists questions the flow record answers directly: which connections were blocked by network policy, which services were reached from outside the cluster, and which of them hit DNS resolution errors in the last 5 minutes. The blocked-verdict field is already there because enforcement needed it, so an audit question becomes a flow filter rather than a log archaeology exercise.
The weakness is coverage outside the datapath. Traffic that does not traverse Cilium's hooks is not in the stream, and Hubble will report nothing about it rather than reporting an error. A cluster whose egress runs through a gateway outside the Cilium range will look quieter than reality.
There is also a cost floor before any question gets answered. Running the CLI against a remote Hubble instance means enabling Hubble in Cilium, running a Relay for a cluster-wide view, and having somewhere for the metrics to land. Teams that only want HTTP latency percentiles are paying for that plumbing to answer a question Prometheus alone can answer from application instrumentation.
Editorial conclusion
Adopt Hubble if your cluster already runs Cilium and you want to know why a call between two pods failed without inserting a sidecar into the path. Do not adopt it as a replacement for a tracing backend, and do not expect answers about traffic that never crosses the Cilium hooks, because no flow record is created for it. Before anything else, check the version pairing: the README's table covers Cilium 1.20 and older and go.mod requires cilium v1.20.2, so confirm your cluster version against that before deploying the CLI.
Frequently asked questions
What problem does Hubble solve in a Kubernetes cluster?
It exposes the flow records Cilium collects with eBPF as a queryable stream, a service dependency map and network metrics, so you can see which services talk to which and why an individual connection failed. Visibility comes from the kernel datapath, so applications need no changes.
Does Hubble require Cilium to be installed?
Yes. Hubble is built on top of Cilium and eBPF and depends on the Cilium datapath to produce the flow records it queries. Without that datapath there is nothing for Hubble to read.
Which Hubble components are still beta?
The component stability table lists Hubble UI as Beta, while Hubble CLI, Hubble Server, Hubble Metrics and Hubble Relay are all listed as stable. The README warns that beta components should be used with caution in critical production workloads.
How do I install the Hubble CLI?
The README links to prebuilt artifacts on GitHub. Building from a clone is the other route, since the repository's Makefile drives a Go build with CGO disabled that produces a single executable named hubble.
How do I find pods that are failing DNS resolution with Hubble?
Run hubble observe over a recent window with JSON output, select records whose l7.dns.rcode equals 3, and count them per namespace and pod name with jq, sort and uniq -c. The README shows this producing a count of 42 for a single pod in the starwars namespace.
Which Cilium versions does the Hubble CLI support?
The README's version table shows the v1.20 line supporting Cilium 1.20 and older. The CLI is backward compatible with all supported Cilium releases and only the newest CLI version is maintained, so there is no older supported binary to fall back to.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/cilium-hubble)Star history chart for your README
[](https://hysenlabs.com/projects/cilium-hubble)Was this useful?