Zod v4: parse, safeParse, z.infer and the new z.compile fast path
TypeScript-first schema validation with static type inference
At a glance
- What is it?
- Zod validates untrusted data against a schema and hands back a value whose TypeScript type is inferred from that same schema. Version 4 adds ahead-of-time compilation for hot paths, with trade-offs around CSP, async refinements and refinements that run twice.
- Who is it for?
- Use Zod when data crosses a trust boundary in a TypeScript or plain JavaScript app, such as request bodies, form input or third-party API responses, and you want one schema to produce both the runtime check and the static type. It is the wrong fit if you only need compile-time types for data you already trust, since the schemas then add code without catching anything.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
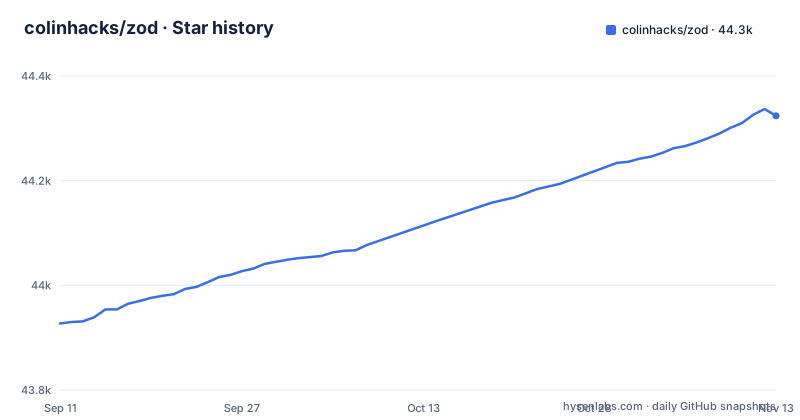
- colinhacks/zod44,324 ★ · +397
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| colinhacks/zod | 43.9k | 44.3k |
397 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One schema yields both the runtime check and the TypeScript type
Zod's central move is that you write the shape of your data once, as a schema object, and get two things out of it. At runtime, .parse validates an input and returns a strongly typed deep clone of it. At compile time, z.infer extracts a static type from the same schema, so the type and the validation logic cannot drift apart.
const Player = z.object({
  username: z.string(),
  xp: z.number(),
});

// extract the inferred type
type Player = z.infer<typeof Player>;

// use it in your code
const player: Player = { username: "billie", xp: 100 };
The deep clone matters. The value returned by parse is a new object, not the input you passed in, so later code should use the returned value. Schemas follow the same rule: Zod's API is immutable, and every method returns a new instance rather than modifying the schema it was called on.
safeParse returns a discriminated union instead of throwing ZodError
When validation fails, .parse throws a ZodError whose issues array carries one entry per problem. Each issue has a code such as invalid_type, the expected type, a path pointing at the failing field and a readable message like Invalid input: expected string, received number. A payload with two bad fields produces two issues, so a form can mark both fields at once.
For code that should not rely on exceptions, .safeParse returns a plain result object:
const result = Player.safeParse({ username: 42, xp: "100" });
if (!result.success) {
  result.error; // ZodError instance
} else {
  result.data; // { username: string; xp: number }
}
Because the result is a discriminated union on success, TypeScript narrows result.data to the parsed type only inside the success branch. That is the pattern to reach for in request handlers, where a validation failure is an expected outcome and should become a 400 response rather than an unhandled throw.
An async refinement forces every call site onto parseAsync
Refinements and transforms can be async, and that choice spreads. A schema that contains an async refinement or transform has to be validated with .parseAsync() or .safeParseAsync(), and every caller has to await the result:
const schema = z.string().refine(async (val) => val.length <= 8);

await schema.parseAsync("hello");
// => "hello"
The consequence shows up in shared schemas. If one field deep inside a large object schema gains an async check, say a uniqueness lookup against a database, every place that parses that object must switch to the async methods. Keeping async checks out of shared schemas, and running them as a separate step after a synchronous parse, avoids that ripple. The same schema is also excluded from z.compile, covered below.
z.compile builds a fast path with new Function, which strict CSP rules out
For hot validation paths, z.compile(schema) returns a clone of the schema with an ahead-of-time compiled fast path. Valid inputs take the compiled path. Invalid inputs fall back to the regular parser, so error reporting stays identical to an uncompiled schema.
const CompiledPlayer = z.compile(Player);

CompiledPlayer.parse({ username: "billie", xp: 100 });
The project's own numbers come from a 55-schema benchmark with a median speedup of 2.4x. Gains scale with the work a schema does per parse: around 9x for a large array of objects or a 20-key object, around 4.5x for a nested object, and nothing for a bare z.string(), since a single typeof check has no dispatch or allocation to remove. A global switch compiles every schema constructed after the import:
import "zod/compile"; // place before modules that define schemasCompilation relies on new Function. Environments with a Content Security Policy that forbids it need z.config({ jitless: true }), which disables global mode. Calling z.compile() directly remains an explicit opt-in, so in a CSP-restricted app that call is the one to remove.
Compiled schemas fall back silently, and refinements can run twice
z.compile has failure modes that do not announce themselves. Schemas with async refinements or transforms cannot be compiled, and neither can a few other constructs. That is not an error: z.compile() hands the schema back unchanged and it keeps using the regular parser. A team can wrap a schema in z.compile, see no error, and get no speedup at all. Passing { strict: true } makes the call throw ZodCompileAsyncError or ZodCompileUnsupportedError instead, which is the only way to find out at build time.
The second trap concerns side effects. On invalid input, refinements and transforms may run twice, once on the fast path and once on the fallback. A refinement that increments a counter, writes a log line or calls an external service will do so twice for every rejected payload.
The third is ordering. Deriving a schema from a compiled one with .refine(), .extend() or similar returns an uncompiled schema. Compile the final schema, not a base that other schemas extend.
Transforms split a schema's input type from its output type
A schema does not always accept and return the same type. The .transform() API converts a value during parsing, so a schema can accept a string and produce a number. Zod exposes both sides:
const mySchema = z.string().transform((val) => val.length);

type MySchemaIn = z.input<typeof mySchema>;
// => string

type MySchemaOut = z.output<typeof mySchema>; // equivalent to z.infer<typeof mySchema>
// number
z.infer returns the output type. That is the right type for code that consumes parsed data, and the wrong one for a function that builds the raw payload before it is sent for validation. Form libraries and API clients that type the unparsed input should use z.input.
npm install zod, zero dependencies, and why plain TypeScript types are not a substitute
Installation is one package with no external dependencies:
npm install zodImport it as import * as z from "zod". Zod runs in Node.js and all modern browsers, works from plain JavaScript as well as TypeScript, ships a core bundle of 2kb gzipped, and includes built-in JSON Schema conversion for teams that need to hand a schema to tooling outside JavaScript.
The usual alternative is no library at all: declaring a TypeScript interface and casting incoming JSON to it. TypeScript types are erased at compile time, so that cast checks nothing when a malformed payload arrives. Zod exists for exactly that gap. If every value in your program is constructed by your own code, plain types are enough and Zod adds weight for no benefit.
The project is MIT licensed. The last push was on 2026-10-30, and releases are frequent: v4.6.5 on 2026-09-13, v4.6.6 on 2026-10-11 and v4.6.7 on 2026-10-12. The repository is a monorepo with packages under packages/, and its dev dependencies pin zod3 to npm:zod@~3.24.0, keeping the version 3 line around inside the build.
Editorial conclusion
Use Zod when data crosses a trust boundary in a TypeScript or plain JavaScript app, such as request bodies, form input or third-party API responses, and you want one schema to produce both the runtime check and the static type. It is the wrong fit if you only need compile-time types for data you already trust, since the schemas then add code without catching anything. Before turning on import "zod/compile" globally, check two things: whether your Content Security Policy blocks new Function, and whether any refinement or transform has side effects that would misbehave if it ran twice on invalid input.
Frequently asked questions
What is Zod and why do we use it?
Zod is a TypeScript-first validation library. You define a schema, parse untrusted data with it, and get back a validated, strongly typed result, so the runtime check and the static type come from one definition.
Can Zod be used with TypeScript?
Yes. Zod is built TypeScript-first and infers static types from schemas through z.infer, z.input and z.output. It also works from plain JavaScript.
What is Zod validation and how does it work?
You call .parse or .safeParse on a schema with some input. Valid input returns a typed deep clone, and invalid input produces a ZodError listing each issue with its code, path and message.
How do I use Zod?
Install it with npm install zod, import it with import * as z from "zod", define a schema such as z.object({ username: z.string() }), and call .parse or .safeParse on incoming data.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 2 in the last 30 days; newest first.
- I Compared 6 TypeScript Validation Libraries. Here's What Surprised Me 🤔dev.to · Oct 28, 2026 · 79 points · 39 comments
- Zod maintainer refuses v3 CVE backport because advisory is agent-writtenHacker News · Oct 26, 2026 · 1 points · 1 comments
- Zod 4.6.6 compromised by malware?Hacker News · Oct 12, 2026 · 183 points · 52 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/colinhacks-zod)Star history chart for your README
[](https://hysenlabs.com/projects/colinhacks-zod)Was this useful?