postgres-operator: two kubectl commands, one forked examples repo, and the machinery PGO owns
Production PostgreSQL for Kubernetes, from high availability Postgres clusters to full-scale database-as-a-service.
At a glance
- What is it?
- PGO is CrunchyData's Go operator for Postgres on Kubernetes, and it folds backups, monitoring, pooling and TLS into the same cluster definition. The two kubectl commands that install it also pull Crunchy Data's own Postgres distribution from its Developer Portal.
- Who is it for?
- PGO earns a place on a cluster that already treats GitOps as the way infrastructure changes, because it turns Postgres into a declared resource instead of something an operator runs by hand.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
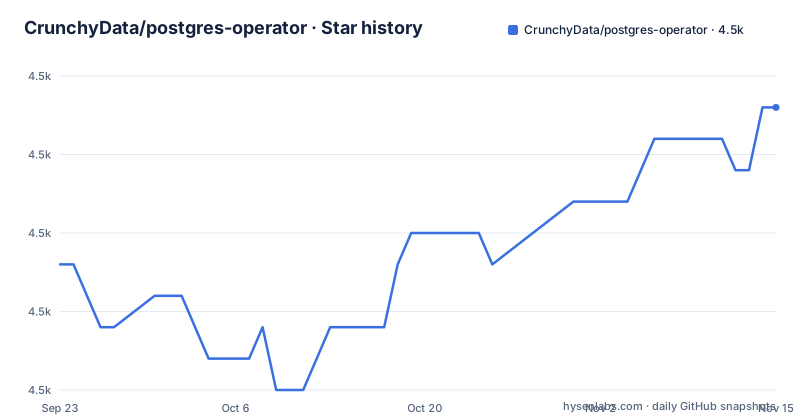
- CrunchyData/postgres-operator4,459 ★ · +5
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| CrunchyData/postgres-operator | 4.5k | 4.5k |
5 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two kubectl commands install Crunchy Postgres, not PGO alone
The quickest documented path to a running cluster is two commands, applied in this order:
kubectl apply -k kustomize/install/namespace
kubectl apply --server-side -k kustomize/install/default
The two flags are not interchangeable. The first carries no `--server-side` flag and does one thing: create the namespace that the second overlay writes into. The second hands every object to the API server's apply path rather than building the diff on the client.
Read what those overlays actually install before running them. PGO is offered as the orchestration behind Crunchy Postgres for Kubernetes, and this route downloads container images from Crunchy Data's Developer Portal rather than from a public registry. Running the operator without that distribution means editing these instructions and building the PostgreSQL containers yourself, which is what the `components/` directory is for: one `README` per subdirectory, with every image built from packages maintained by the PostgreSQL Global Development Group.
A forked examples repository is the source of every manifest
Nothing can be applied until the examples repository is forked into an account you control:
YOUR_GITHUB_UN="<your GitHub username>"
git clone --depth 1 "[email protected]:${YOUR_GITHUB_UN}/postgres-operator-examples.git"
cd postgres-operator-examples
Both lines assume the remote is your own fork, so the first step is a fork and not a download. That has a consequence worth stating plainly: the kustomize overlays that land in your cluster come from a repository you now own, and every later edit to a cluster definition begins as a commit in that fork. For a team that is GitOps working as intended, which is the workflow the project says it was designed for. For one engineer evaluating the operator it adds a GitHub account step and a second repository to maintain. The clone is shallow, which keeps the first apply cheap and leaves the local clone with no history to diff a later change against.
This repository also carries example manifests as `examples/postgrescluster/` and `examples/pgadmin/`, and nothing in the installation text says which of the two trees wins when they disagree about a field.
Consensus failover sits beside topology rules you write
High availability is delegated, not reimplemented. Failover is backed by a distributed consensus solution, failed primaries heal automatically, and you choose between asynchronous and synchronous replication depending on whether losing a committed transaction is acceptable for the workload.
Placement stays your responsibility in every other respect. Pod anti-affinity is supported and its aggressiveness is configurable rather than fixed, alongside node affinity and tolerations for steering a cluster onto particular nodes.
Standby clusters work within a single Kubernetes cluster and across several of them, which is what turns a second region into a target rather than a rebuild.
pgBackRest carries backup type, schedule and destination
Backup handling is one open source utility wrapped in a manifest. pgBackRest provides full, incremental and differential backups plus delta restores, you set how long backups are retained, and each cluster declares its backup type and how often it runs. Destinations named in the README include local storage, S3 and GCS.
What that section does not say matters more than what it does say. In the README, restores are a feature line linking to the hosted documentation rather than a command. Anyone planning a recovery drill ends up reading the hosted documentation and upstream pgBackRest instead. Scheduling is in the same position, offered as a per-cluster feature with no schedule syntax shown.
TLS is enforced, and the certificate source is replaceable
TLS is not a setting you can leave off. PGO enforces that all connections are over TLS, and you can bring your own certificate infrastructure instead of the defaults. Containers run with locked-down settings, and Postgres credentials reach applications through a mechanism the README describes only as secure and convenient.
No key names come with any of that. The TLS and monitoring sections link into the hosted documentation. Connection pooling through pgBouncer sits in the same cluster definition and arrives with no pool size, mode or database keys. That is the real cost here: behaviour is described in prose while the knobs live somewhere you have to go and read, which turns auditing a manifest you did not write into following links instead of reading YAML.
Monitoring SQL is vendored out of pgmonitor at a pinned tag
Cluster health tracking uses the pgMonitor library, and the queries behind it are not written in this repository. The Makefile clones a second project, pins it to a tag, and copies its exporter queries into a local directory that the operator image then ships:
PGMONITOR_DIR ?= hack/tools/pgmonitor
PGMONITOR_VERSION ?= v5.2.1
QUERIES_CONFIG_DIR ?= hack/tools/queries
The copy step is explicit about what moves. The contents of `postgres_exporter/common/` land in that directory and `queries_backrest.yml` is copied beside them, so backup metrics and server metrics travel together, and the Dockerfile then places the whole tree at `/opt/crunchy/conf` in the final image. Change the tag and your monitoring queries change with it, which makes the v5.2.1 pin the point where a pgmonitor update enters an operator build.
The module file also shows what kind of controller this is. `go.opentelemetry.io/otel v1.45.0` arrives with an autoexport collector and an otelhttp instrumented HTTP client, so the controller carries tracing and metrics plumbing of its own, and `github.com/pganalyze/pg_query_go/v6 v6.2.2` with `github.com/itchyny/gojq v0.12.19` suggest it parses Postgres SQL and runs jq expressions.
The runtime image ships as uid 2 on debian bookworm
The repository layout explains where a build starts and where configuration is supposed to live:
Dockerfile
Makefile
cmd/
components/
config/
conf/
hack/
licenses/
testing/
examples/
docs/
The final image is assembled from a Debian bookworm base and runs as a non-root user:
FROM docker.io/library/debian:bookworm
COPY --from=build /usr/src/app/licenses /licenses
COPY --from=build /usr/src/app/hack/tools/queries /opt/crunchy/conf
COPY --from=build /usr/src/app/postgres-operator /usr/local/bin
USER 2
CMD ["postgres-operator"]
The notices under `/licenses` are generated during the build by `go run ./hack/extract-licenses.go licenses postgres-operator`, so they are resolved from the module graph on every build rather than checked in and edited by hand. Immediately before the last stage, both `hack/tools/queries` and `licenses` are chmodded read-only, directories to 0555 and files to 0444, which matches data the operator reads and never rewrites.
Building your own is a documented path rather than a fork. The first stage compiles `go build ./cmd/postgres-operator` from a golang bookworm image, and the Makefile expects `buildah` for container work, so a team that wants its own Postgres distribution edits the recipes under `components/` and rebuilds rather than maintaining a patch set against the upstream binary.
v5 documentation links sit beside v6 tags and newer libraries
Two version lines sit next to each other without explaining each other. The homepage, the quickstart link and the tutorial link all name the v5 documentation path, while the components link names `https://access.crunchydata.com/documentation/postgres-operator/latest/references/components`, and the tag history already carries v6.0.2 and v5.8.8 dated 2026-06-02 along with v6.0.1 from 2026-02-26. Following the quickstart puts you on the previous major line.
The build tooling disagrees more quietly. `go.mod` declares `go 1.26.6` and requires `k8s.io/api v0.36.3` with `sigs.k8s.io/controller-runtime v0.24.1`, while the Makefile runs the environment test harness from the 0.22 line. Known issues live in comments marked BUGS, FIXME, NOTE or TODO carrying a name in parentheses, printed by the `notes` target. The repository is not archived, and the last push to main landed on 2026-10-21.
Editorial conclusion
PGO earns a place on a cluster that already treats GitOps as the way infrastructure changes, because it turns Postgres into a declared resource instead of something an operator runs by hand. Anyone evaluating it should read the v6 documentation rather than following the v5 quickstart the links point at, decide first whether pulling Crunchy Data's images from its Developer Portal is acceptable in your environment, and rehearse a real restore against pgBackRest before any workload depends on the backups.
Frequently asked questions
What is the postgres operator from CrunchyData?
The postgres operator (PGO) is a Go controller that manages Postgres clusters declaratively on Kubernetes, covering provisioning, failover through a distributed consensus solution, backups through pgBackRest, health tracking through pgMonitor, pooling through pgBouncer and TLS enforced on every connection. Installation forks the postgres-operator-examples repository and applies two kustomize overlays, which also pull Crunchy Data's own Postgres distribution from its Developer Portal.
What is the difference between the CrunchyData postgres operator and CloudNativePG?
What PGO specifies for itself is consensus-backed failover with self-healing primaries, full, incremental and differential backups through pgBackRest with delta restores, standby clusters within and across multiple Kubernetes clusters, and a choice of asynchronous or synchronous replication.
How does the CrunchyData postgres operator compare with the Zalando postgres operator?
The approach PGO documents is to ship a Postgres distribution alongside the operator, install that pairing from a forked examples repository with two kustomize overlays, and build the PostgreSQL containers yourself from the recipes under the components directory if you want a different distribution.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/crunchydata-postgres-operator)Star history chart for your README
[](https://hysenlabs.com/projects/crunchydata-postgres-operator)Was this useful?