Databasus: PostgreSQL PITR with Restore Verification, Built for Self-Hosting
PostgreSQL backup tool with Point-In-Time-Recovery and restore verification.
At a glance
- What is it?
- Databasus is a self-hosted PostgreSQL backup tool that combines physical, incremental, and WAL streaming backups with automated restore verification. It targets low RPO/RTO disaster recovery, but its feature breadth comes with operational complexity.
- Who is it for?
- Adopt Databasus if you run PostgreSQL 14-18 and need a self-hosted backup system that verifies restores automatically and supports PITR with WAL streaming. It is a poor fit for MySQL, MariaDB, or MongoDB primary workloads, since those only get logical backups with no PITR.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
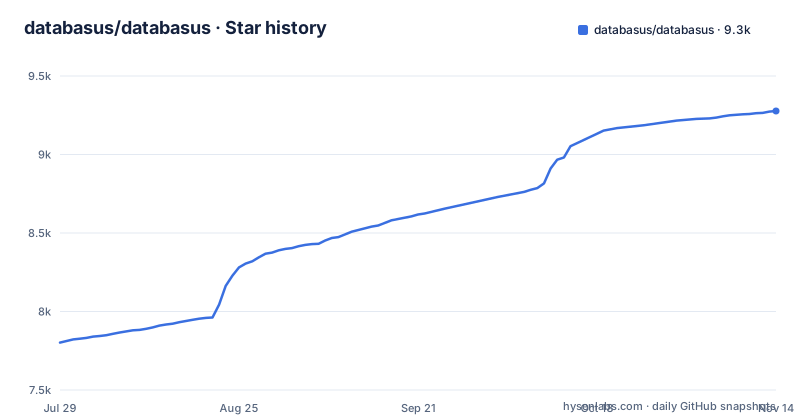
- databasus/databasus9,277 ★ · +1,475
| Repository | 2026-07-29 | 2026-11-14 |
|---|---|---|
| databasus/databasus | 7.8k | 9.3k |
1,475 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Databasus Actually Solves
Databasus addresses a specific operational pain: PostgreSQL backups that you cannot trust until you restore them. Most backup tools stop at writing files and checking checksums. Databasus goes further by spinning up a real database container, running the restore, and comparing the restored size against the backup. That is the core value proposition. It is aimed at teams running PostgreSQL who want point-in-time recovery (PITR) with low recovery point objective (RPO) and recovery time objective (RTO). The README lists support for PostgreSQL 14 through 18 for both physical and logical backups. If you run MySQL, MariaDB, or MongoDB, Databasus supports them, but only with logical backups. That means no WAL streaming and no PITR for those engines. The tool is designed for self-hosting: Docker-based, with all data staying on your infrastructure.
The Backup Mechanism: Physical, Incremental, and WAL Streaming
Databasus uses PostgreSQL's native incremental backup mechanism for physical backups. A full backup is a complete copy of the cluster. An incremental backup stores only what changed since the previous full backup. WAL streaming continuously captures the database write stream, which enables PITR. This is the mechanism that gives near-zero data loss. The documentation describes these three layers as separate backup types. The distinction matters. A full backup alone gives you a restore point. Incremental backups reduce storage and speed up the backup window. WAL streaming fills the gap between backups. For a low RPO, you need all three running together. The README also mentions logical backups, which are native dumps in engine-specific binary format, compressed and suitable for parallel restore. Logical backups are useful for schema changes or cross-version migrations, but they do not support PITR.
Restore Verification: Not Just a Checksum
The restore verification feature is the most distinctive part of Databasus. According to the README, it performs a real restore to confirm backups are usable. It spins up a database container, runs the restore, and checks the restored size against the backup. The report lists every table with its row count. Verification can trigger after each backup or on a flexible schedule, including hourly, daily, weekly, monthly, or cron. You can send the full report or failure-only alerts through any configured notifier. This is a genuine differentiator. Most backup tools verify integrity at the file level, not at the database level. The size comparison is a heuristic, not a guarantee of data correctness. It will catch a truncated backup or a corrupt file, but it will not catch logical corruption where the data is intact but wrong. The row count report gives you a per-table view, which helps spot missing tables or dropped data. Still, the verification is only as good as the restore environment. If the container image differs from your production environment, you might miss compatibility issues.
Getting It Running: Installation Paths
Databasus offers four installation methods: an automated script, a simple Docker run, Docker Compose, and Kubernetes with Helm. The automated script is recommended for Linux. It installs Docker with Docker Compose if needed, sets up Databasus, and configures automatic startup on reboot. The command is a curl pipe to bash, which is convenient but requires trust in the script source. For a simple Docker run, the README gives this command: docker run -d --name databasus -p 4005:4005 -v ./databasus-data:/databasus-data --restart unless-stopped databasus/databasus. The Docker Compose and Kubernetes with Helm options are covered in the installation docs at databasus.com/installation. All four listed installation methods run Databasus in containers.
Retention Policies and Storage Flexibility
Retention is where Databasus shows its enterprise ambitions. You can keep backups for a fixed time period, keep a fixed count of the most recent backups, or use GFS (Grandfather-Father-Son) retention. GFS lets you keep hourly, daily, weekly, monthly, and yearly backups independently. That is a layered approach for long-term history. Additionally, you can set per-backup and total storage size caps. This gives you fine-grained control over storage growth. On the storage side, Databasus supports local storage, S3, Cloudflare R2, Google Drive, NAS, Dropbox, SFTP, and Rclone. The README says all data stays under your control, which is true for self-hosting. The combination of GFS and multiple cloud destinations is useful for compliance-heavy environments that need archival tiers. Because an incremental backup stores only what changed since the previous full backup, check how retention treats that chain before relying on it.
Security and Encryption: Zero-Trust Storage
Databasus claims AES-256-GCM encryption for backup files. The README describes this as zero-trust storage, meaning backups are useless to attackers even if stored in shared storage like S3 or Azure Blob Storage. Sensitive data, including secrets, is encrypted and never exposed in logs or error messages. The tool uses a read-only user by default for backups, so it cannot modify your data. This is a strong security posture. The read-only user is a good practice, but it means Databasus cannot perform certain operations that require write access. Restore verification, for example, needs to spin up a container and load data, which is separate from the backup user. The README does not detail key management. You need to know where the encryption keys are stored and how to rotate them. If you lose the keys, the backups are unrecoverable. The Apache-2.0 license means you can inspect the code and verify these claims.
Limitations and Trade-Offs
The biggest limitation is that PITR and physical backups are PostgreSQL-only. The README lists MySQL, MariaDB, and MongoDB as supported, but only for logical backups. If you run a mixed database environment, you cannot get the same low RPO for all engines. Another limitation is the container dependency. Every installation path the README lists runs Databasus in containers. That excludes environments where containers are not allowed, such as some regulated or air-gapped systems. The restore verification uses a database container, so you need a working container runtime in your restore environment. The size comparison is a coarse check; it will not detect row-level corruption. The README also mentions smart compression with 4-8x space savings and about 20% overhead. The scheduling supports cron expressions, which is flexible but requires cron knowledge. The UI has dark and light themes and mobile adaptation, which is nice but not a technical feature. The tool is complex enough that the README points to separate docs for storages, notifiers, and security. That suggests a learning curve.
Alternatives: What Else Is Out There
The most direct alternative is pgBackRest, a dedicated PostgreSQL backup tool that also supports full, incremental, and WAL archival. pgBackRest has been around longer and is widely adopted in production. Its approach is different: it is a command-line tool with no web UI, no restore verification by default, and no built-in notification channels. You write your own scripts for scheduling and alerting. Databasus gives you a managed UI, restore verification, and out-of-the-box notifiers. The trade-off is that pgBackRest is more transparent and scriptable, while Databasus is more integrated but adds a web service to your stack. Another alternative is WAL-G, which focuses on WAL archiving and PITR, but it does not provide a UI or verification. For teams already using Kubernetes, the Helm chart in Databasus is an advantage, but pgBackRest has operators as well. The choice comes down to whether you want a self-contained tool with a GUI or a scriptable utility you can embed in your own automation.
Maintenance and Upgrade Cost
The release cadence is active. The most recent release is v3.64.0, published on 2026-10-24, with v3.63.3 and v3.63.2 on the same day. That suggests frequent updates, which is good for bug fixes but means you need to track releases. The project is not archived, and the default branch is main. The README does not specify a migration path for upgrades, but the Docker image tagging suggests you can pin versions. Tracking the newest image without pinning a version is risky for production because you get breaking changes without notice. The Apache-2.0 license is permissive, so you can modify the source, but you are responsible for maintaining your fork. The OpenTelemetry log export means you can integrate with your monitoring stack, but that adds configuration overhead. Further documentation is on the website (databasus.com).
Editorial conclusion
Adopt Databasus if you run PostgreSQL 14-18 and need a self-hosted backup system that verifies restores automatically and supports PITR with WAL streaming. It is a poor fit for MySQL, MariaDB, or MongoDB primary workloads, since those only get logical backups with no PITR. Before committing, verify the restore verification actually matches your recovery workflow, test the encryption key management, and confirm the Docker-based deployment meets your security requirements.
Frequently asked questions
What happens if I don't backup my data?
Without a backup there is no full cluster copy, no incremental chain and no captured WAL stream, so point-in-time recovery is not available and a restore verification run has nothing to restore into a container. The write stream is what allows recovery to a chosen moment, and it only exists once backups are being taken.
What is the best backup tool for a PostgreSQL database?
Databasus covers PostgreSQL 14, 15, 16, 17 and 18 with both physical and logical backups: full copies, incrementals of what changed, and continuous WAL streaming for point-in-time recovery. On top of that it adds scheduled runs, retention policies, and verification that performs a real restore and reports a row count for every table.
What are the top 10 data backup software?
The repository does not rank backup tools or publish comparisons, so it is not a place to answer that. What it does describe is its own scope: PostgreSQL 14 to 18 with physical and WAL-streamed backups, MySQL, MariaDB and MongoDB as logical only, storage to local disk, S3, Cloudflare R2, Google Drive, NAS, Dropbox, SFTP or Rclone, and notifiers from email through Slack, Discord, Teams, Mattermost, Telegram and webhooks.
What are the three main types of database backups?
Databasus documents two top-level types. Physical covers a full self-contained cluster copy, an incremental holding only what changed since the previous full, and WAL streaming of the write stream for point-in-time recovery. Logical is a native dump in the engine's own binary format, compressed and suitable for parallel restore.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/databasus-databasus)Star history chart for your README
[](https://hysenlabs.com/projects/databasus-databasus)Was this useful?