Databend rebuilds the cloud warehouse as an agent runtime on your own object storage
Data Agent Ready Warehouse : One for Analytics, Search, AI, Python Sandbox. — rebuilt from scratch. Unified architecture on your S3.
At a glance
- What is it?
- A Rust data warehouse unifying analytics, vector search and full-text search on S3-compatible storage, now adding sandboxed Python UDFs and SQL orchestration aimed at AI agents.
- Who is it for?
- Databend fits data teams that want warehouse-scale analytics plus retrieval workloads on their own object storage, and that are ready to run agent logic inside sandboxed SQL functions with branching as the safety net. Skip it if a fully managed warehouse matches your staffing reality, if you already run a dedicated vector store you like, or if the Elastic License's service-provider restrictions touch your business model.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
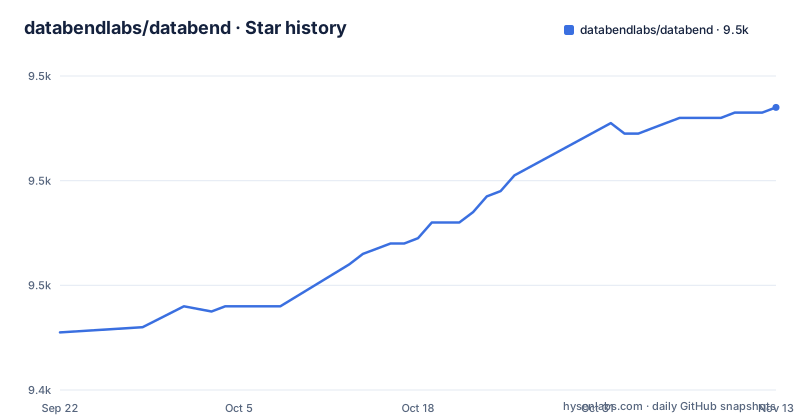
- databendlabs/databend9,494 ★ · +43
| Repository | 2026-09-22 | 2026-11-13 |
|---|---|---|
| databendlabs/databend | 9.5k | 9.5k |
43 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A warehouse rebuilt for agents, not just dashboards
Databend has years of history as an open-source, cloud-native analytics warehouse, and its README now leads with a repositioning: an enterprise data warehouse for AI agents, rebuilt from scratch, with the description calling it a Data Agent Ready Warehouse. The engine is written in Rust, stores data on your own object storage, S3, Azure or GCS, and unifies four jobs that usually require four products: SQL analytics, vector search, full-text search and auto schema evolution, with transactions underneath.
The agent framing is not a sticker on the website. It corresponds to concrete machinery: sandboxed Python UDFs that can hold agent logic, SQL as the orchestration layer that calls that logic at scale, transactions for reliability, and git-like branching so an agent can experiment on a production snapshot without touching production. That combination is the actual product thesis, and the README documents each piece.
Quick start: a pip one-liner and a Docker container
Two entry paths are documented. Databend Cloud is the recommended route: sign up, create a warehouse, and run SQL in the worksheet. For local development, a Python driver runs an embedded instance; the README specifies Python 3.12 or 3.13 and databend-driver 0.34.0 or later:
pip install "databend-driver[local]>=0.34.0"and then two lines of Python get you a query:
from databend_driver import connect

conn = connect("databend+local:///./local-state")
print(conn.query_row("SELECT 'Hello, Databend!'").values())
The full warehouse runs locally in one Docker command:
docker run -p 8000:8000 datafuselabs/databendThe Sandbox UDF: agent logic as a SQL function
The agent architecture has three named planes. A control plane handles resource scheduling, permission validation and sandbox lifecycle. The execution plane is Databend itself, orchestrating through SQL and issuing work over Arrow Flight. The compute plane consists of isolated sandbox workers running your agent code.
The SQL shape is the part worth staring at, because it is unusual:
CREATE FUNCTION my_agent(input STRING) RETURNS STRING
LANGUAGE python HANDLER = 'run'
AS $$
def run(input):
    # Your agent logic: LLM calls, tool use, reasoning...
    answer = f"processed: {input}"
    return answer
$$;

SELECT my_agent(question) FROM tasks;
A Python function becomes a SQL function; SQL then fans it out across a table of inputs. The README's example comment lists LLM calls and tool use as the intended body, which means warehouse rows can drive agent invocations with the engine handling scheduling and isolation. For data teams, that moves agent workloads into the same governance and audit perimeter as every other query.
Branching and transactions: the safety story
Two older warehouse virtues are repositioned as agent safety features, and the reframe holds up. Branching is described as git-like data versioning: an agent that needs to try an aggressive transformation can work on a branch, compare results, and be discarded without contaminating production data. Transactions mean multi-step operations either land completely or not at all, which is the difference between an agent that corrupts a table halfway through a plan and one that simply fails.
The README's use-case table makes the pairing explicit: sandbox UDFs give agents somewhere to run, SQL orchestration gives them scale, and branching gives them a safety net on production snapshots. For anyone who has watched an autonomous script mutate the wrong table, that trio, not the vector search, is the reason to take the agent positioning seriously.
One engine, four workloads
The unification claim deserves its own accounting. Analytics is the heritage: large-scale SQL with elastic compute over object storage. Vector search and full-text search cover the retrieval half of RAG pipelines, so embeddings and keyword indexes live beside the structured tables they join against, instead of in a separate specialty store. Auto schema evolution reduces the friction of semi-structured sources that change shape under you.
The practical consequence is architectural: a RAG pipeline can ingest documents, chunk and embed them, index them for both retrieval modes, and join retrieved chunks against operational tables in one system, governed by one permission model. The README's search and RAG use case links to documentation for exactly this pattern. The README publishes a search benchmark on Databend Cloud (10M docs: vector p50 41 ms, full-text p50 35 ms); whether that matches a dedicated vector database at your scale is answerable on your own data.
Licence: Apache 2.0 plus Elastic 2.0
Databend is licensed under Apache 2.0, while a small set of enterprise features is under Elastic License 2.0, with both texts in the repository, a LICENSING.md and a licensing FAQ in the documentation. The distinction matters for anyone planning to build on it.
The short version, without legal advice: Apache 2.0 is the permissive licence most users expect, while the Elastic License restricts offering the software itself as a managed service, which is the standard open-core boundary for infrastructure companies. If you are a data team adopting Databend internally, the question barely arises. If you are a cloud provider or startup planning to sell it as a service, read the Elastic text and the FAQ before writing a business plan around it. The repository also carries an AI_POLICY.md and its own AGENTS.md file, a small sign the maintainers run AI tooling against this codebase under a stated policy.
Against Snowflake, ClickHouse and DuckDB
The README benchmarks Databend against Snowflake, and the structural difference is control: Snowflake is a managed commercial service where the vendor runs everything; Databend runs on your own S3-compatible storage, with an open codebase you can read. Teams with data-residency requirements or existing storage contracts weigh that differently than teams that just want zero operations.
Against column-oriented engines like ClickHouse, the difference is scope rather than speed: ClickHouse remains a specialist at high-throughput analytics, while Databend bundles vector and full-text search, branching and the Python sandbox into the same engine. DuckDB occupies the embedded analytics slot rather than the warehouse one. Databend's defensible middle is the combination: warehouse scale, retrieval workloads, and agent execution in one governed place.
Editorial conclusion
Databend fits data teams that want warehouse-scale analytics plus retrieval workloads on their own object storage, and that are ready to run agent logic inside sandboxed SQL functions with branching as the safety net. Skip it if a fully managed warehouse matches your staffing reality, if you already run a dedicated vector store you like, or if the Elastic License's service-provider restrictions touch your business model. Verify the claims on your data, not the README's: run the Docker one-liner, load a real table, try the vector and full-text paths, and only then measure what a sandboxed UDF agent would actually cost you in compute.
Frequently asked questions
Can Databend run locally?
Yes. The self-hosted route runs the all-in-one image with docker run -d -p 127.0.0.1:8000:8000 datafuselabs/databend and connects with bendsql -u root.
What licence does Databend use?
Databend is licensed under Apache 2.0; a small set of enterprise features is under Elastic License 2.0, with both texts in the repository, a LICENSING.md and a licensing FAQ in the docs.
What makes Databend agent-ready?
Sandboxed Python UDFs hold agent logic as callable SQL functions, SQL orchestrates them at scale over Arrow Flight, transactions guarantee atomic multi-step operations, and git-like branching lets agents work safely on production snapshots.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/databendlabs-databend)Star history chart for your README
[](https://hysenlabs.com/projects/databendlabs-databend)Was this useful?