GraphJin: One Governed Graph for AI Agents Over Your Existing Data Stack
One governed graph for AI agents, GraphQL + MCP over your databases, files, APIs, and code.
At a glance
- What is it?
- GraphJin is a Go-based compiler and runtime that exposes databases, files, APIs, and code through GraphQL and MCP, with a built-in agent and execution ledger. It targets teams that want AI agents to act on real systems without raw credentials.
- Who is it for?
- Adopt GraphJin if you need to give AI agents governed access to diverse data sources and want a built-in agent with discovery and audit trails, especially if you already run GraphQL. Skip it if your stack is single-database and you have no agent use case, or if you require a full SaaS control plane.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
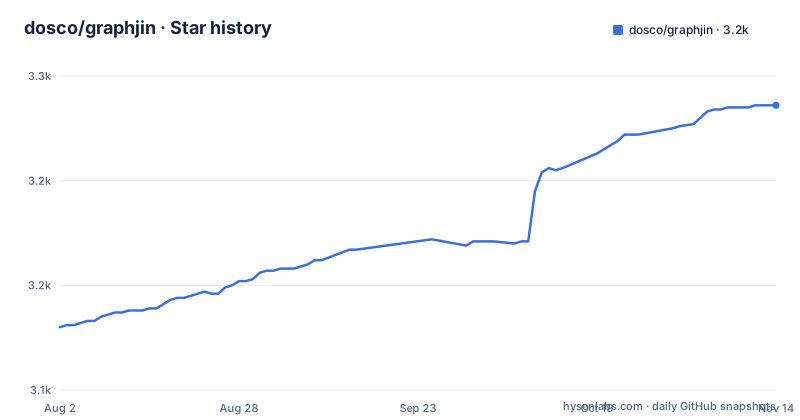
Star history
- dosco/graphjin3,236 ★ · +106
| Repository | 2026-08-02 | 2026-11-14 |
|---|---|---|
| dosco/graphjin | 3.1k | 3.2k |
106 Stars in the last 104 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Agents Need Guardrails, Not Credentials
GraphJin addresses a specific pain: handing an AI agent raw database credentials and hoping it writes correct queries. The README frames it as giving agents 'one governed graph' over systems a company already has. That graph spans operational databases, warehouses, object stores, local files, source code indexes, and workflows. The target user is a team that wants agents to act on real infrastructure without granting direct access. The project has two faces: it remains a GraphQL-to-database compiler for regular applications, and it adds an agent layer on top. That dual identity matters. If you already use GraphQL, the agent functionality is an extension of a familiar tool. If you do not, you are adopting two systems at once.
How the Agent Loop Works: Discovery Before Action
The documentation describes a built-in agent that runs a discovery loop server-side. You POST an instruction to /api/v1/agent or call the ask_graphjin_agent MCP tool. The agent operates under the caller's permissions, not a superuser account. Before writing any query, it can call query_catalog with a search term, use graphql_help, inspect relationship evidence, and read examples and config recipes. That discovery phase is the core safety mechanism. After the agent acts, the server checks every answer against an execution ledger before returning it. The response shape is {status, answer, data, evidence, actions, next}. This is a concrete data flow: instruction in, typed answer with evidence out. The ledger is a differentiator; most agent tools stop at logging, but GraphJin gates the response on it.
Getting Started: One Command to a Demo with SQLite
Installation is straightforward. The README lists npm, Homebrew, Scoop, and Docker. The npm route is graphjin install -g graphjin. For a quick start, graphjin serve --demo runs a built-in SaaS demo on SQLite with seeded data. The output shows endpoints: Web UI on port 8083, GraphQL, REST, Workflows, and MCP. To enable the agent, you need a model API key in ./.env, either OPENAI_API_KEY, ANTHROPIC_API_KEY, or GOOGLE_APIKEY. Then you can send a curl request to /api/v1/agent with an instruction like 'Which account is most at risk of churning?' The demo state lives under ./graphjin-demo/demo/, and deleting that folder resets the data. This is a practical onboarding path. You can also clone the repo and use --path to run larger demos, such as examples/webshop for Postgres or examples/coffee-roastery for a Postgres plus BigQuery-emulator setup.
MCP Integration: Streamable HTTP and Client Helpers
GraphJin exposes an MCP endpoint at /api/v1/mcp using Streamable HTTP. The README is explicit that Claude must use --transport http, not SSE, because SSE is only for older or custom MCP servers. There is a helper command: graphjin mcp add codex or graphjin mcp add claude, which normalizes the server URL and installs the right config. You can also add the endpoint manually, for example codex mcp add graphjin --url http://localhost:8080/api/v1/mcp. The helper defaults to client=codex and server=http://localhost:8080. For project scope, use --global to make the connection available outside the current directory. The documentation notes that local non-TLS HTTP is correct for loopback development, while hosted servers should use HTTPS. That distinction is practical and prevents a common misconfiguration.
Guarded Actions: Allow-lists, Read-only Boundaries, and Encrypted Secrets
The project's safety model goes beyond discovery. The README lists source-mode access, query allow-lists, read-only boundaries, policy-aware MCP tools, and local encrypted secrets. These are concrete mechanisms, though the README does not detail how each is configured. The gj_config preview/apply flow keeps changes auditable, meaning an agent can propose a config change but not apply it blindly. Operational awareness comes from gj_security and gj_runtime endpoints, plus a built-in console. For durable memory, saved queries and workflows live in an owner-scoped gj_artifacts store. The gj_watch mechanism runs standing questions under the owner's permissions and delivers events to an inbox or webhook. This is a strong design for agents that need to monitor state over time, not just answer one-off questions.
Limitations and Wrong-Tool Cases
The biggest limitation is that the agent requires an external model API key. If you do not have OpenAI, Anthropic, or Google keys, the agent mode is disabled, and you are left with the GraphQL compiler only. The README does not mention local model support in the main install path, despite the tagline about local 7B models. That gap is worth verifying. Another limitation is the breadth of supported databases. While the list is impressive, each database likely has different SQL dialect handling. The README gives no performance benchmarks, so claims about being 'high-performance' are unverified. For a single small database, GraphJin is overkill. You could use PostgREST or a simple GraphQL server. Also, the execution ledger adds latency to every response, which may be unacceptable for high-throughput non-agent workloads.
Alternatives: PostgREST and Hasura
A direct alternative is PostgREST, which turns a PostgreSQL database into a REST API with row-level security. It is simpler, has no agent or MCP layer, and no GraphQL. The approach differs fundamentally: PostgREST gives you HTTP endpoints that map to SQL, while GraphJin compiles GraphQL and adds an agent loop on top. Another alternative is Hasura, which provides GraphQL over Postgres with a permission system. Hasura has a richer console and ecosystem, but it does not natively expose MCP or a built-in agent. If your goal is only GraphQL over a database, Hasura is a mature choice. GraphJin's edge is the bundled agent and the multi-source support, which Hasura does not match for files, code, and warehouses. Choose based on whether you need the agent layer or just a data API.
Maintenance and License Considerations
GraphJin is licensed under Apache-2.0, which is permissive for commercial use. The project is actively developed, with releases three days in a row in August 2026, suggesting a fast release cadence. That means you should expect frequent updates and potential breaking changes between minor versions. The Go library is at pkg.go.dev/github.com/dosco/graphjin/core/v3, so the module path indicates a major version 3. The README mentions a Docker image and npm package, so there are multiple distribution channels to track. The active push schedule implies a maintenance cost: you will need to monitor releases and test upgrades, especially given the breadth of database support. For a production deployment, plan for version pinning and a CI test suite that exercises your specific database and agent flows.
Editorial conclusion
Adopt GraphJin if you need to give AI agents governed access to diverse data sources and want a built-in agent with discovery and audit trails, especially if you already run GraphQL. Skip it if your stack is single-database and you have no agent use case, or if you require a full SaaS control plane. Verify first: confirm your database is in the supported list (PostgreSQL, MySQL, MongoDB, SQLite, Oracle, MSSQL, Snowflake, Redshift, BigQuery, Cassandra, S3/GCS), check the agent's model key requirements, and test the execution ledger output against your compliance needs. The demo command gives you a working SQLite instance in minutes, so start there before committing.
Frequently asked questions
How do I try GraphJin without installing anything else?
Run graphjin serve --demo. It extracts a built-in SaaS operations demo on SQLite with seeded data, saved queries and workflows, and prints five endpoints on port 8083. Its state lives under a demo subdirectory, so deleting that folder resets the data.
What does the built-in GraphJin agent return?
You POST one instruction to the agent endpoint, or call the equivalent MCP tool, and it returns a typed answer with status, answer, data, evidence, actions and next fields. It runs the discovery loop as the caller and under the caller's permissions, and answers are grounded by server-side protocol guards.
What are gj_watch subscriptions in GraphJin?
Standing questions rather than one-off answers. You hand a cursor-paginated subscription to gj_watch and GraphJin keeps answering it under the owner's permissions, resumes from persisted cursors across restarts, treats absence as a first-class event, and files findings into a durable inbox, a webhook or a workflow.
Which databases can GraphJin compile GraphQL against?
PostgreSQL, MySQL, MongoDB, SQLite, Oracle, MSSQL, Snowflake, Redshift, BigQuery, Apache Cassandra and Amazon Keyspaces, plus object stores, local files and CodeSQL source indexes. The test targets in the build file cover nine of those engines.
How do I install GraphJin on macOS or Windows?
Homebrew uses a tap and Windows uses a Scoop bucket added by URL followed by an install. Linux uses Debian or RPM packages from the releases page, Docker pulls the image, and npm installs a wrapper globally whose postinstall step fetches the platform binary.
Does GraphJin need a language model to run watches?
Not after they are written. Evaluation runs on database polls rather than model calls: a model writes the watch once, and nothing calls a model again unless you enable optional per-watch triage. The agent endpoint itself does need a model key in the environment file.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/dosco-graphjin)Star history chart for your README
[](https://hysenlabs.com/projects/dosco-graphjin)Was this useful?