PG Back Web: Docker-based PostgreSQL backups with a web interface
🐘 Effortless PostgreSQL backups with a user-friendly web interface! 🌐💾
At a glance
- What is it?
- PG Back Web wraps pg_dump in a Go web application with scheduling, S3 or local destinations and a restore button. It suits small teams that want backups without writing cron scripts, and it is the wrong tool if you need point-in-time recovery.
- Who is it for?
- PG Back Web can schedule logical PostgreSQL backups and provide a web interface for monitoring them. Decide whether the resulting recovery point and restore time meet your requirements, and use a separately designed physical-backup and WAL strategy where point-in-time recovery is required.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Go, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
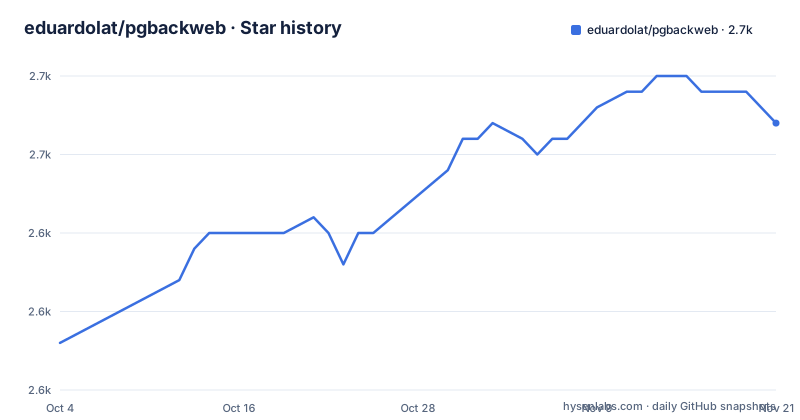
- eduardolat/pgbackweb2,652 ★ · +14
| Repository | 2026-10-04 | 2026-11-21 |
|---|---|---|
| eduardolat/pgbackweb | 2.6k | 2.7k |
14 Stars in the last 48 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What PG Back Web actually replaces
The problem it targets is unglamorous: a PostgreSQL database that matters, and no reliable backup job attached to it. The usual answer is a cron entry calling pg_dump, a shell script that uploads the file somewhere, and a vague hope that the script still works. PG Back Web puts that workflow behind a web interface. You register a database connection, register a destination, create a backup task with a schedule, and read the execution logs afterwards.
The intended user is stated plainly in the README: "From individual developers to teams." That is a fair description of the scope. A solo developer running a side project on a VPS gets a scheduling interface and a download link instead of a crontab. A small team gets shared visibility: whoever is on call can see whether last night's dump succeeded without asking the person who wrote the script.
What it does not replace is a physical backup strategy. The README describes the project as "backed by the robust pg_dump tool", and pg_dump is a logical export. It produces a consistent snapshot of the data as of the moment it runs, not a continuous stream of write-ahead log. That distinction decides most of the adoption questions below.
How the Go service, scheduler and S3 client fit together
The repository layout makes the architecture readable without running anything. The entry point is under cmd/, the application logic under internal/, and the Go module declares the pieces: Echo for HTTP, gocron for scheduling, gronx for cron expression parsing, the AWS SDK for Go v2 with the S3 manager for uploads, lib/pq for talking to PostgreSQL, and nodxgo with its htmx and alpine bindings for server-rendered HTML. There is no separate frontend application. The package.json lists only build tooling, Tailwind, daisyUI, esbuild and Prettier.
The data flow is conventional for a self-hosted tool. PG Back Web keeps its own state in a PostgreSQL database named by PBW_POSTGRES_CONN_STRING: users, database connections, destinations, backup tasks, executions and logs. Credentials for the databases it backs up, and S3 secret keys, are encrypted with PBW_ENCRYPTION_KEY before being written there, which the .env.example describes as covering "database credentials, secret keys, etc."
When a task fires, the service runs pg_dump against the target connection, writes the dump to local storage or streams it to an S3 bucket, and records the outcome. The README lists webhooks for backup completion, failure and health check failures, so an external system can react without polling. Health checks run against both databases and destinations, which matters more than it sounds: a destination that has quietly become unwritable is the failure mode that turns a backup tool into decoration.
One design consequence worth naming. The control-plane database also needs a recovery plan. A backup task may be configured against it if connectivity and permissions allow, but recovering the service from its own backup creates a bootstrap dependency; keep an independently accessible backup and test restoration. Nothing in the README claims otherwise, but it is easy to overlook when planning.
Installing PG Back Web with Docker Compose
The README states the project ships as a Docker image and that three environment variables are enough to start. The Compose example below is adapted from the one in the README, keeping the image name, the port and the variable names as published. The web interface is served on port 8085, and the ./backups volume is only needed if you use local destinations rather than S3.
The upstream Compose example includes a PostgreSQL health check and persistent storage; use the current upstream example as a starting point. Its sample key and password are placeholders. Generate a strong encryption key, use a strong database password, persist the PostgreSQL data directory appropriate to the image version, and bind the web interface to a trusted network. The sample uses `sslmode=disable`, which is appropriate only where the connection is protected by other means.
Open the [project README](https://github.com/eduardolat/pgbackweb#readme) and copy its current Compose example into a local `compose.yaml` file.
Review the downloaded file and current project documentation before running it; image tags, paths and configuration can change.
Replace the encryption key and the database password before starting anything. The README is explicit that the key protects sensitive data and should be stored safely. Bring the stack up with docker compose up -d, then open http://localhost:8085 in a browser. You should see the login screen, and on first run the flow for creating an initial account.
The optional variables are documented in .env.example and in the configuration section: PBW_LISTEN_HOST defaults to 0.0.0.0, PBW_LISTEN_PORT defaults to 8085, PBW_PATH_PREFIX lets you serve the interface under a subpath such as /pgbackweb, and TZ sets the timezone used for logging, backup filenames and the default timezone in the interface. If you forget the password, the README gives one recovery command:
docker exec -it CONTAINER_NAME sh -c change-passwordReplace CONTAINER_NAME with the actual name or ID. After that, the first real task is: add your production database as a connection, add a destination, create a backup task with a cron schedule, and run it once manually to confirm the dump lands where you expect.
The recovery gap: full dumps, no point-in-time recovery
PG Back Web schedules pg_dump. The README lists its features as scheduled backups, monitoring, download and restore, multi-version support for PostgreSQL 13 through 18, local and S3 destinations, health checks, webhooks and PGP encryption. Point-in-time recovery is not among them, and it cannot be, because pg_dump does not capture the write-ahead log.
The practical consequence: if a table is dropped at 14:03 and the last dump ran at 02:00, that dump alone restores a snapshot from its backup run. Later writes require another independent recovery source, such as a properly configured physical backup and WAL archive. For a content site or an internal tool, that may be acceptable. For anything where losing hours of transactions is a business event, this tool is the wrong layer, and no amount of interface polish changes it.
There is a second limitation that follows from the same design. A typical whole-database pg_dump is a logical dump; selected objects and options affect its contents. On a large database, the dump takes time and space proportional to the data size, and running it frequently multiplies storage consumption at the destination. The README does not document incremental backups or deduplication. Retention policy is therefore a capacity decision, not just a housekeeping one.
A third point concerns the encryption key. Because credentials are encrypted with PBW_ENCRYPTION_KEY, losing that value means the stored connection details become unreadable. The README tells you to store it safely but does not document a rotation procedure or a rollback path for a changed key. Treat it as part of your disaster recovery material, alongside the dumps themselves.
PG Back Web compared with pgBackRest and pg_basebackup
The closest serious alternative is pgBackRest. The difference is not interface quality, it is the backup model. pgBackRest performs physical backups and manages WAL archiving, which is what makes point-in-time recovery and much smaller incremental backups possible. It is driven by configuration files and a command line, and it expects you to understand its repository layout and retention settings. PG Back Web provides a browser interface, but operators still need to plan retention, access control, monitoring and tested restores.
That trade is the whole decision. If you need recovery to within minutes, or you are backing up a database measured in hundreds of gigabytes where full dumps are impractical, consider a physical backup and WAL archiving solution such as pgBackRest, then validate that the complete recovery process meets the objective. If you have a 20 GB database, a weekly or daily window is acceptable, and nobody on the team wants to own a pgBackRest configuration, PG Back Web delivers most of the practical value for far less setup.
pg_basebackup occupies a third position: it takes a physical base backup of a running cluster, which is closer to pgBackRest in kind but without the repository management and retention features. It is a building block rather than a complete backup system. Choosing between these tools is really choosing your recovery point objective first and picking the tool that meets it second.
Maintenance, licensing and the rename to UFO Backup
The repository is not archived, and the last push was on 2026-09-02, which is recent. Releases are less even: v0.5.2 arrived on 2026-08-28, while v0.5.1 came out on 2025-10-06, so roughly eleven months separate those two releases. The version numbers suggest the project is still pre-1.0, and the README does not promise interface or configuration stability across upgrades. Budget for reading release notes before pulling a new image, and pin a specific tag rather than tracking latest if you care about reproducibility.
The README announces a rename: "PG Back Web is becoming UFO Backup!" with a stated intention to expand beyond PostgreSQL. It points to a community space for roadmap discussion. A rename affects image names, documentation links and any automation that references them. The README does not state a cutover date or whether the existing image name will keep receiving updates, so verify the published image tags before you build deployment scripts around eduardolat/pgbackweb.
The licence is AGPL-3.0, as stated in the README and present as LICENSE at the repository root. The practical implication for most readers: if you run PG Back Web as a service for your own organisation, the copyleft obligations are the ordinary ones for internal use. If you intend to offer it to third parties as a hosted service, or to embed it in a product, the network-use clause of the AGPL is the part to read carefully. This is not legal advice; the LICENSE file and your own counsel are the references that matter.
Upgrade cost is mostly operational. The application state lives in the PostgreSQL database you configured, so a new image runs migrations against that database on start. The README does not document a downgrade path, so a database snapshot before upgrading is the cheap insurance.
Editorial conclusion
PG Back Web can schedule logical PostgreSQL backups and provide a web interface for monitoring them. Decide whether the resulting recovery point and restore time meet your requirements, and use a separately designed physical-backup and WAL strategy where point-in-time recovery is required. Preserve the application database, encryption key and backup credentials securely, and rehearse restores into an isolated target, including cluster-wide objects that pg_dump does not export.
Frequently asked questions
What is PG Back Web and who is it for?
It is a self-hosted web application that schedules and monitors PostgreSQL backups, built in Go and distributed as a Docker image. The README describes it as designed for everyone from individual developers to teams.
How do I install PG Back Web?
Pull the eduardolat/pgbackweb image and run it with PBW_ENCRYPTION_KEY and PBW_POSTGRES_CONN_STRING set, either directly or through Docker Compose. The web interface is then reachable on port 8085.
Which PostgreSQL versions does PG Back Web support?
The README lists compatibility with PostgreSQL 13, 14, 15, 16, 17 and 18.
Where does PG Back Web store the backups it creates?
It supports local storage, mounted in the Compose example at /backups, and S3 buckets, of which the README says you can add as many as you want. If you only use S3 destinations, the local volume is not needed.
How do I reset the PG Back Web password?
The README documents `docker exec -it CONTAINER_NAME sh -c change-password`; replace CONTAINER_NAME with the actual container name or ID and follow the prompts. Restrict access to this administrative operation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/eduardolat-pgbackweb)Star history chart for your README
[](https://hysenlabs.com/projects/eduardolat-pgbackweb)Was this useful?