Elasticsearch 9.x: What the Repository Actually Tells You About Running It
Elasticsearch is a distributed, RESTful search and analytics engine and vector store for near-real-time full-text and vector search, logs, and metrics at scale.
At a glance
- What is it?
- Elasticsearch is a distributed search and analytics engine with vector search and RAG support. This review focuses on what the repository and README show: local setup via start-local, REST API access, and the limits of the free tier.
- Who is it for?
- Adopt Elasticsearch if you need a distributed search and analytics engine that also handles vector search and RAG workloads, and you are comfortable with the Java-based, REST-driven model. Do not adopt it if you need a lightweight embedded search library, or if you cannot accept the license shift after the one-month trial, which reverts to the Free and open - Basic tier.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
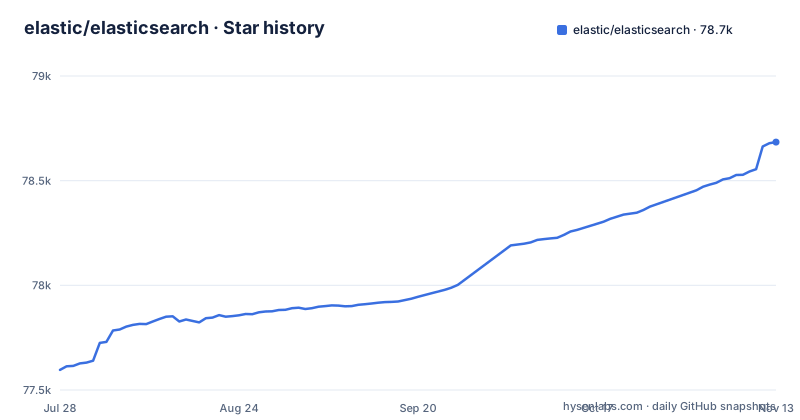
- elastic/elasticsearch78,684 ★ · +1,088
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| elastic/elasticsearch | 77.6k | 78.7k |
1,088 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Elasticsearch Solves and Who It Is For
Elasticsearch is a distributed search and analytics engine, a scalable data store, and a vector database. The README lists use cases: retrieval augmented generation (RAG), vector search, full-text search, logs, metrics, APM, and security logs. The target user is a developer or team that needs near real-time search over large datasets, with the ability to combine traditional text search with vector similarity. It is not a toy. The repository is the foundation of Elastic's open Stack platform, which means it is designed to be the core of a larger deployment. If your problem is simple full-text search on a single machine, Elasticsearch is overkill. But if you need a distributed, scalable engine, this is the tool the README is aimed at.
The Core Mechanism: REST APIs, Indexing, and Near Real-Time Visibility
The README describes the data flow clearly. You send JSON documents through REST APIs. A POST to a target index creates the index if it does not exist, stores the document, and indexes its fields. The README states that the new document is available immediately from any node in the cluster. That is the near real-time promise. For timestamped data like logs and metrics, you add documents to a data stream, which is made up of multiple auto-generated backing indices. You can send requests through REST APIs. You can use curl, a language client, or Kibana's Dev Tools console. The README gives a concrete example: POST /customer/_doc/1 with a JSON body, then a GET request to retrieve it by ID. That is the entire mental model: index, search, retrieve.
Getting It Running: The start-local Script and Docker
The README offers the start-local script as a way to run Elasticsearch and Kibana locally in Docker; its simplest setup path is a managed Elasticsearch Service deployment on Elastic Cloud. You run curl -fsSL https://elastic.co/start-local | sh. That script creates an elastic-start-local folder, starts Elasticsearch and Kibana in Docker, and generates a random password for the elastic user. It also stores an API key in the .env file as ES_LOCAL_API_KEY. You access Elasticsearch at http://localhost:9200 and Kibana at http://localhost:5601. The README warns that this setup is for local development only: HTTPS is disabled, Basic authentication is used, and the services are only accessible through localhost. To verify the connection, you source the .env file and run curl $ES_LOCAL_URL -H "Authorization: ApiKey ${ES_LOCAL_API_KEY}". For a language client, you set the ES_LOCAL_PASSWORD environment variable and use basic auth. The README shows a Python example using the elasticsearch client with basic_auth=(username, password). This is a real, reproducible path, but it is not a production deployment. The README is explicit: DO NOT USE THESE INSTRUCTIONS FOR PRODUCTION DEPLOYMENTS.
The Trial License and the Free Tier: What You Actually Get
The start-local setup comes with a one-month trial license that includes all Elastic features. After the trial, the license reverts to Free and open - Basic. The README points to the Elastic subscriptions page for details, but it does not list what is in the Basic tier. That is a gap. You need to verify which features you rely on are still available after the trial. The README does say that HTTPS is disabled in the local setup, and Basic authentication is used. If your use case requires encrypted transport or role-based access control, you need to check the subscription details before committing. The trial license is a way to test the full feature set, but the production reality may be more limited.
A Genuine Limitation: The Local Setup Is Not Production-Ready
The README is unusually blunt about this. It says the start-local setup is for local development and testing only, and it warns that HTTPS is disabled and Basic authentication is used. That means the default local deployment is insecure for anything beyond a single-user dev machine. If you follow the README's instructions and expose the ports, you are risking data exposure. Also, the script uses Docker, so you need Docker (the README links Docker Desktop), and on Windows you need WSL. That is an extra dependency. So the wrong tool is any scenario where you need a search engine embedded in your application, because Elasticsearch is a standalone server, not an embedded library.
Alternatives: How They Differ in Approach
A real alternative is Apache Solr, which is also a Java-based, distributed search engine built on Lucene. Another alternative is OpenSearch, which is a fork of Elasticsearch's older versions. The choice depends on whether you want the Elastic ecosystem (Kibana, Beats, etc.) or a more open governance model.
Maintenance and Upgrade Cost: What the Repository Shows
The repository shows active maintenance. The default branch is main, and recent releases include v9.5.6, v8.19.24, and v9.4.9 (all 2026-11-02), with the latest push on 2026-11-02. That suggests a regular release cadence. The README mentions that the start-local content is replicated from the run-elasticsearch-locally.asciidoc file, and that the source of truth is the start-local GitHub repository. That means the local setup instructions are maintained separately, which is a small maintenance overhead for you if you rely on them. The license is listed as unknown in the repository metadata, but the README refers to Free and open - Basic and Elastic subscriptions. You need to verify the exact license terms for your use case, especially if you are building a commercial product.
What the README Does Not Tell You
The README is a quick start, not a reference. If you are evaluating Elasticsearch for a serious project, you should download the latest version from elastic.co and run it in a test environment that mimics your expected load. The README gives you a fast path to a local instance, but it stops there.
Editorial conclusion
Adopt Elasticsearch if you need a distributed search and analytics engine that also handles vector search and RAG workloads, and you are comfortable with the Java-based, REST-driven model. Do not adopt it if you need a lightweight embedded search library, or if you cannot accept the license shift after the one-month trial, which reverts to the Free and open - Basic tier. Before production, verify which features in the trial license are not in the Basic tier, and check the Elastic subscriptions page for what the Basic tier includes.
Frequently asked questions
Does Elasticsearch is free?
The local setup described here comes with a one-month trial licence that includes all Elastic features, and after the trial period the licence reverts to what the documentation calls Free and open - Basic. So the answer depends on which tier you are on and when, rather than being a flat yes or no. The repository itself ships LICENSE.txt, NOTICE.txt and a licenses directory, while its metadata does not resolve a single licence name.
how to install elasticsearch
For local work, the documented path is a single command that pipes a script into a shell and starts Elasticsearch and Kibana in Docker, creating an elastic-start-local folder. Elasticsearch is then on http://localhost:9200 and Kibana on http://localhost:5601. A random password for the elastic user and an API key called ES_LOCAL_API_KEY are written to a .env file in that folder.
how to install elasticsearch on windows
The prerequisites call for Docker Desktop, and on Microsoft Windows they also call for the Windows Subsystem for Linux. The local setup is then the same script as on other systems, running Elasticsearch on port 9200 and Kibana on port 5601, both bound to localhost with HTTPS disabled.
how to use elasticsearch in python
Use the Python elasticsearch client with basic auth against the local endpoint. The connection details are the http://localhost:9200 endpoint, the username elastic, and the password held in the ES_LOCAL_PASSWORD environment variable, which the sample code reads with os.getenv and passes to the client as basic_auth. Calling client.info() is the check that the connection works.
Is Elasticsearch SQL or NoSQL?
You index data by sending JSON objects, described as documents, through the REST APIs, and Elasticsearch stores and indexes them. For timestamped data such as logs and metrics you are pointed at a data stream made up of multiple auto-generated backing indices rather than a single index you name yourself. A new document is available immediately from any node in the cluster.
how to use elasticsearch api key
The local setup generates an API key and stores it in the .env file as ES_LOCAL_API_KEY. You check the connection by sourcing that file and sending it as an ApiKey header, which is a different mechanism from the basic auth path that uses the elastic username and ES_LOCAL_PASSWORD. Use the key when a client wants an ApiKey credential and basic auth when it wants a username and password pair.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/elastic-elasticsearch)Star history chart for your README
[](https://hysenlabs.com/projects/elastic-elasticsearch)Was this useful?