Kibana: the browser interface for data stored in Elasticsearch
Your window into all of your data
At a glance
- What is it?
- Kibana is the open source UI layer over Elasticsearch, and it is not a standalone product. This review covers what it does, how to install it, the version rules that govern it, and when Grafana is the better pick.
- Who is it for?
- Adopt Kibana when your data already lives in Elasticsearch and you want one interface for Discover, dashboards, and cluster management without writing a front end. Skip it if you need a single pane over Prometheus, Graphite or other non-Elasticsearch backends, because Kibana does not connect to them.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
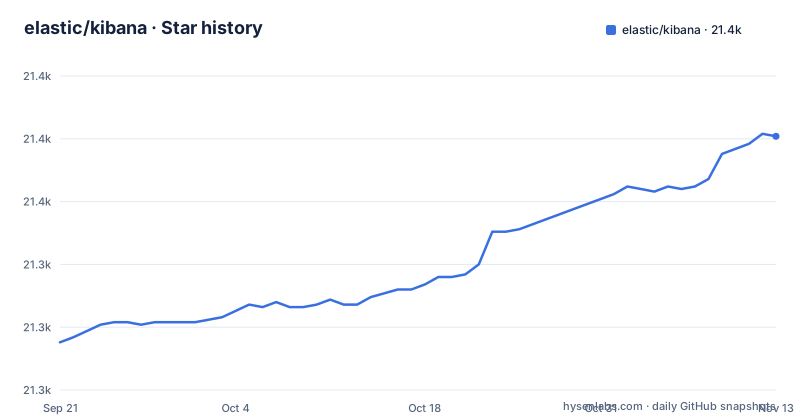
- elastic/kibana21,376 ★ · +82
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| elastic/kibana | 21.3k | 21.4k |
82 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Kibana is for, and who it is not for
Kibana is the open source interface to query, analyze, visualize, and manage data stored in Elasticsearch. That sentence from the README is also the constraint: Kibana has no storage engine of its own. Every dashboard, saved search and visualization reads from an Elasticsearch cluster. If you do not run Elasticsearch, Kibana has nothing to show you.
The audience follows from that. Teams already indexing logs, metrics or application events into Elasticsearch use Kibana to look at them without building a query UI. Operators use it to inspect cluster state and index mappings. Developers use Dev Tools to send raw queries against the cluster. The package.json keywords list analytics, visualizations, dashboards and dashboarding, which matches the shape of the product.
It is the wrong tool if your telemetry is spread across Prometheus, Graphite, InfluxDB and a cloud provider's metrics API. Kibana does not federate those sources. It is also a poor fit if you want a static reporting layer that runs without a live cluster behind it, because visualizations are rendered from queries at view time.
How Kibana sits on top of Elasticsearch
The architecture is a server plus a browser application. Kibana runs as its own process, holds configuration and saved objects, and talks to Elasticsearch over HTTP. The browser talks to Kibana, not to Elasticsearch directly. That is why the version compatibility rules matter: the server component and the cluster have to agree on the API surface they speak.
The repository is a large TypeScript monorepo. The package.json is marked private and named kibana, with the version field at 9.7.0 on the main branch. Saved objects (dashboards, visualizations, index patterns) live in Elasticsearch indices that Kibana manages, which is why an upgrade can require migrations before the new version will start cleanly.
The examples/ directory shows the plugin surface rather than the product surface: hello_world, embeddable_examples, expressions_explorer, data_view_field_editor_example, locator_examples, esql_ux_example and others. If you are evaluating Kibana as a platform to extend, that directory is a more honest map of what is supported than the marketing pages. The presence of AGENTS.md, AI.md, STYLEGUIDE.mdx and TYPESCRIPT.md at the repository root also tells you the project expects contributors to follow a defined style and typing discipline.
Installing Kibana and opening Discover for the first time
The README does not give a package-manager install. It points to the Kibana Download Page for a release, and to CONTRIBUTING.md if you want to build from source. There is no npm install line to copy, because the package is private and not published.
For a source checkout, the scripts in package.json are the entry points. The preinstall check runs automatically, and scripts/kibana starts the server in development mode:
node scripts/kibana --devThe README does not document the port, so read the console output from the server rather than assuming one. A development start compiles and watches the source tree, which is why CONTRIBUTING.md exists as a separate document.
For a release build, download the archive from the Kibana Download Page, point it at an Elasticsearch cluster using the configuration in config/, and start it. Once it is up, the first real use is Discover: pick a data view over an index, then query it with Kibana Query Language. The README links the Kibana Getting Started Page for this flow rather than reproducing it, and the product page describes the feature set.
For a container workflow, the README does not include a Docker command, so treat any compose file you find elsewhere as outside this repository's documented path.
Version compatibility is a hard constraint, not a suggestion
The README devotes a full section to Elasticsearch and Kibana compatibility, and the table is worth reading before you upgrade anything. Major versions must strictly match, with an exception for prevmajor.last. Three mismatches are fatal: an Elasticsearch major number newer or older than Kibana's, and an Elasticsearch minor number older than Kibana's. Everything else in the table is a logged warning.
The asymmetry is deliberate. Kibana can run on a newer patch than Elasticsearch, so a Kibana-only patch can ship without touching the cluster. Kibana can also run a minor version behind Elasticsearch, which simplifies rolling upgrades. But Kibana cannot run ahead of the cluster on a minor, and no combination survives a major mismatch.
The README states the practical consequence plainly: if you hit issues on mismatched versions, you will first be asked to upgrade before support or troubleshooting begins. In a support context that is a gate, not advice. Plan cluster and UI upgrades as one operation, and check the minor direction before you roll the cluster forward.
Where Kibana is the wrong tool
The clearest limitation is the one stated at the top: Kibana manages data stored in Elasticsearch. It does not ingest. You need Logstash, Beats, an Elastic Agent or your own indexing code to get data in. Teams that expect Kibana to collect logs will be disappointed, and the README does not claim otherwise.
Second, the licence is listed as NOASSERTION, meaning the repository metadata does not declare a recognised SPDX identifier. The repository carries LICENSE.txt and NOTICE.txt at the root, and there is a checkLicenses script in package.json, but nothing in the README tells you which features are free and which sit behind a paid Elastic subscription. Anyone adopting Kibana for a commercial product has to read LICENSE.txt and the product page themselves.
Third, the monorepo is heavy. The root contains build tooling for multiple package managers and linters, a Moon workspace, devcontainers, and separate style guides for TypeScript and MDX. Building from source is a contributor workflow, not a quick evaluation path. If you only want to see the product, use a release download.
Kibana vs Grafana: the difference is the data source
The most common comparison question is Kibana vs Grafana, and the split is architectural rather than cosmetic. Grafana is a dashboard front end designed to query many data sources through plugins, so a single instance can graph Prometheus, Graphite, SQL databases and cloud monitoring APIs side by side. Kibana is built around one: Elasticsearch. It does not present a plugin model for arbitrary backends in the README, and the product is described entirely in terms of Elasticsearch data.
That makes the choice mostly about where your data already is. If logs, metrics and traces are indexed in Elasticsearch, Kibana gives you Discover, Kibana Query Language, visualizations and cluster management in one place, with no extra query translation layer. If your metrics live in Prometheus and your logs live in Elasticsearch, Grafana covers both and Kibana covers one.
A second common comparison is whether Kibana is like Splunk. Both present a search bar over indexed machine data, but Splunk ships its own indexing and search engine, while Kibana depends on Elasticsearch for storage and query execution. That dependency is the defining property of the project, not a footnote.
Maintenance, releases and upgrade cost
The repository is not archived, and the last push was on 2026-11-02, so it is under current development. Recent releases include v9.5.6, v9.4.9 and v8.19.24, all dated 2026-11-02. Three patch lines receiving releases on the same day is the pattern to expect: maintenance branches are kept alive in parallel.
That cadence has a cost. Because saved objects and migrations live in Elasticsearch indices, a Kibana upgrade is not just swapping a binary. The compatibility table means the cluster and the UI move together, and the fatal combinations mean a partial upgrade can leave you with a UI that refuses to start. The README's instruction to upgrade before troubleshooting turns that into a support precondition.
On licensing, nothing here is legal advice. The repository metadata reports NOASSERTION, and LICENSE.txt and NOTICE.txt are the authoritative files. Read them before you ship Kibana inside a commercial product, and check the product page for which capabilities require a subscription, since the README does not enumerate them.
Editorial conclusion
Adopt Kibana when your data already lives in Elasticsearch and you want one interface for Discover, dashboards, and cluster management without writing a front end. Skip it if you need a single pane over Prometheus, Graphite or other non-Elasticsearch backends, because Kibana does not connect to them. Before committing, verify that your Elasticsearch major version matches your Kibana major version, check the licence file in the repository, and confirm whether the features you need sit in the free tier or behind a paid subscription, since the README points to the download page and the product page but does not list which features are free.
Frequently asked questions
What is Kibana and what is it used for?
Kibana is the open source interface to query, analyze, visualize, and manage data stored in Elasticsearch. It is used for dashboards, log search in Discover, visualizations, and cluster management, and it depends on an Elasticsearch cluster for storage and query execution.
Are Kibana and Grafana the same?
No. Grafana is a dashboard front end that queries many data sources through plugins, while Kibana is built around Elasticsearch and does not present a plugin model for arbitrary backends in its README. The choice usually follows where your data already lives.
Are Elasticsearch and Kibana the same?
No. Elasticsearch stores and queries the data; Kibana is the browser interface over it. The README states that Kibana is the interface to query, analyze, visualize, and manage data stored in Elasticsearch, and the two must run compatible versions.
Is Kibana like Splunk?
Both present a search interface over indexed machine data, but Splunk ships its own indexing and search engine while Kibana relies on Elasticsearch. That dependency shapes deployment, versioning and upgrade planning.
How do I install Kibana?
The README points to the Kibana Download Page for a release, or to CONTRIBUTING.md if you want to build from source. There is no published package to install, since the package.json is marked private.
How do I use Kibana with Elasticsearch?
Kibana runs as its own process and talks to Elasticsearch over HTTP, so you point it at a cluster and query the data through Discover, visualizations or Dev Tools. The README requires the two to run compatible versions, with major versions strictly matching.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/elastic-kibana)Star history chart for your README
[](https://hysenlabs.com/projects/elastic-kibana)Was this useful?