toapi: Declaring a JSON API on Top of Someone Else's HTML
Every web site provides APIs.
At a glance
- What is it?
- toapi turns a web page into a JSON endpoint by pairing CSS selectors with Flask routes. It suits small, read-only extractions where you control the deployment, and it is the wrong tool for anything that needs a schema contract or a crawl you can resume.
- Who is it for?
- Adopt toapi when you need a handful of read-only fields out of a page you do not control, the selectors are stable, and a Flask process you already run is an acceptable place to put it. Do not adopt it when the output has to satisfy a schema contract for other teams, when the source needs a login flow or pagination you cannot express as a route placeholder, or when you need to resume a crawl after a crash.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 86 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
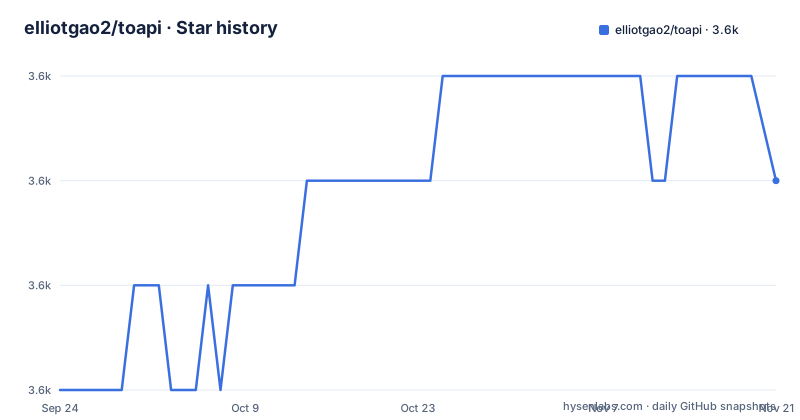
- elliotgao2/toapi3,557 ★ · +2
| Repository | 2026-09-24 | 2026-11-21 |
|---|---|---|
| elliotgao2/toapi | 3.6k | 3.6k |
2 Stars in the last 58 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem toapi addresses, and who actually has it
A page you do not own contains a list you want as data. The conventional answer is a scraper: a script that walks pages, holds state, and writes rows somewhere. That answer drags in a scheduler, a store, and a retry policy, and it produces data only when the job runs. toapi takes the opposite position. It treats the page as a data source that is queried on demand, the way you would query an API, and it exposes the result over HTTP so the consumer never sees the scraping at all.
The audience is narrow and specific. You already run Python, you are comfortable with CSS selectors, and the extraction is small enough that you can name the fields by hand. The README's own example is a Hacker News front page reduced to two fields, title and url, served at /posts. That is the scale the project is designed around. If you are building a data pipeline with thousands of URLs, a queue, and a schema that other teams depend on, the declarative model here is a constraint rather than a convenience.
Routes, fetch, parse: the four stages in the request path
The README draws the flow as route, then fetch, then parse, then JSON. Each stage maps to something concrete in the code.
The route decorators bind an API path to a source URL. @api.route("/posts", "/news") means a request to /posts is served by fetching /news on the site declared with @api.site. A second route with a placeholder, @api.route("/posts?page={page}", "/news?p={page}"), passes the query parameter through to the source, so your consumers get a clean parameter name while the upstream site keeps its own.
Fetching is handled by requests, and the README states that pages are cached in memory. Parsing is delegated to htmlparsing, which supplies the Text and Attr field types used in the Item class. @api.list(".athing") tells toapi which repeating element on the page becomes one record, and each field declaration names a selector relative to that element. Serving is Flask; api.run(host="127.0.0.1", port=5000) starts it.
The design consequence is worth stating plainly. Because the fetch happens inside the request, latency at your API is the latency of the upstream page on a cache miss. The README describes the cache as in-memory, and it does not document a Redis backend, a disk cache or a TTL setting, so a process restart empties it and two workers do not share it.
Installing toapi and serving your first endpoint
The package is on PyPI and the README gives a single install command. It requires Python 3.10 or newer, which matches the requires-python field in pyproject.toml.
pip install toapiA minimal app imports Api and Item from toapi and the field types from htmlparsing. The decorators are stacked on the class: site first, then the list selector, then the routes.
from htmlparsing import Attr, Text
from toapi import Api, Item

api = Api()

@api.site("https://news.ycombinator.com")
@api.list(".athing")
@api.route("/posts", "/news")
class Post(Item):
    title = Text(".titleline > a")
    url = Attr(".titleline > a", "href")

api.run(host="127.0.0.1", port=5000)
Save that as app.py and start it with python app.py, as the README instructs. A request to http://127.0.0.1:5000/posts returns a JSON object keyed by the class name, with a Post array inside it, and each element carrying the title and url fields. The README shows exactly that shape, with the title string and the absolute href for each story.
If a value needs reshaping before it leaves the API, define a method named clean_ followed by the field name. The README's example rewrites a next-page link so that the upstream query string is preserved but the path is replaced with the local one.
@api.route("/posts", "/news")
class Page(Item):
    next_page = Attr(".morelink", "href")

    def clean_next_page(self, value):
        return f"/posts?{value.split('?', 1)[1]}"
The method receives the parsed value and returns whatever you want serialized. That is the only extension point the README documents for transforming output.
Where toapi stops being the right tool
The most consequential limitation is the cache. The README says pages and parsed results are cached automatically, and describes the cache as in-memory. It does not document an eviction policy, a maximum size or a way to inspect entries. In a single-process deployment that is fine. Behind a load balancer with several workers, each worker holds its own copy and each one will fetch the same page independently on a cold start. There is no documented way to warm or share that state.
JavaScript rendering is a second boundary. The README offers one escape hatch: pass Api(browser="/path/to/geckodriver") for JS-heavy sites. It does not describe how that path behaves under concurrency, how many browser instances are kept, or what happens when the driver crashes. Treating it as a drop-in replacement for the requests path is an assumption the documentation does not support.
Schema stability is the third. The output shape is derived from your class name and field names, and the values come from selectors that live in someone else's markup. When the source site renames a class, the field returns nothing and the endpoint keeps returning 200 with an empty or null value. The README does not document validation, a fallback selector, or an alert when a selector stops matching.
Finally, there is no crawl state. Routes are stateless mappings, so there is no queue, no resume point, and no record of which pages have been visited. If your job is to enumerate a site systematically, this is not the layer for it.
How toapi differs from Scrapy
Scrapy is the obvious comparison, and the difference is architectural rather than cosmetic. Scrapy is a crawling framework: you define spiders, it schedules requests, applies a concurrency model, feeds items into pipelines, and writes them to an export or a database. The unit of work is the crawl. State lives in the engine, and you can stop and resume it.
toapi inverts that. The unit of work is a single HTTP request to your own Flask process. There is no scheduler, no pipeline abstraction, and no export step; the JSON response is the output. You get a service you can point a frontend at, and you give up the machinery that makes large crawls tractable.
That trade is defensible when the extraction is a handful of fields and consumers want them live. It is a poor trade when you need to walk thousands of pages, deduplicate, or retry failures across a long run. The two tools are not competing for the same job, and choosing toapi for a bulk crawl will leave you rebuilding the parts Scrapy already provides.
Maintenance, packaging and what the MIT licence leaves you with
The repository is not archived and the last push was on 2026-08-27, which is recent enough that the project is being touched. That is the only maintenance signal available here, and it says nothing about how quickly issues are answered.
The toolchain is modern and pinned in pyproject.toml. Packaging uses hatchling with uv for dependency management and lockfile, ruff for lint and format at a line length of 100, and pre-commit to run both. The README's development section is git clone, uv sync, uv run pytest, uv run ruff check ., which means a contributor can reproduce the environment from uv.lock without guessing versions. Runtime dependencies are small: requests, flask, click, cssselect, htmlparsing, htmlfetcher, charset-normalizer and colorama.
The version in pyproject.toml is 2.2.4, and the project installs a console entry point named toapi that maps to toapi.cli:cli. The README does not document what that CLI does, so the entry point exists without usage guidance.
The licence is MIT, declared in pyproject.toml with license-files pointing at LICENSE. MIT permits commercial use and modification with the copyright notice retained. It provides no patent grant, and it does not cover the terms of service of the sites you point the tool at. What you scrape, and whether you are allowed to, is outside the licence entirely.
Editorial conclusion
Adopt toapi when you need a handful of read-only fields out of a page you do not control, the selectors are stable, and a Flask process you already run is an acceptable place to put it. Do not adopt it when the output has to satisfy a schema contract for other teams, when the source needs a login flow or pagination you cannot express as a route placeholder, or when you need to resume a crawl after a crash. Before committing, check three things against the repository: whether the pages you care about render their content without JavaScript, since the README only offers a geckodriver path for that case; whether the in-memory cache is acceptable for your traffic, because the README does not document a shared or persistent backend; and whether the version on PyPI matches the 2.2.4 in pyproject.toml, since the repository has no published releases.
Frequently asked questions
How do I install toapi?
The README gives a single command, pip install toapi, and states that it requires Python 3.10 or newer. The package is published on PyPI.
Does toapi cache the pages it fetches?
Yes. The README states that pages and parsed results are cached automatically, and describes the cache as in-memory, so it is not shared between processes and does not survive a restart.
Can toapi handle sites that render content with JavaScript?
The README offers one option for this: pass browser="/path/to/geckodriver" when constructing Api. It does not document how that path behaves under concurrent requests.
How do I change a value before toapi returns it?
Define a method named clean_ followed by the field name on the Item class. It receives the parsed value and returns the transformed one, as shown in the README's next_page example.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/elliotgao2-toapi)Star history chart for your README
[](https://hysenlabs.com/projects/elliotgao2-toapi)Was this useful?