balance: a Python package for weighting biased survey samples to a target population
The balance python package offers a simple workflow and methods for dealing with biased data samples when looking to infer from them to some target population of interest.
At a glance
- What is it?
- balance is a beta-stage Python package from Meta's research group for fitting survey weights that adjust a biased sample to a known target population. It offers a simple workflow, but its dependency constraints and beta status deserve attention before adoption.
- Who is it for?
- Adopt balance if you are a survey methodologist, demographer, or data scientist who needs a Python-native way to fit survey weights under the missing-at-random assumption and you can tolerate a beta package with strict dependency pins. Do not adopt it if you need production-grade stability, require support for Python versions outside 3.9 to 3.14, or cannot accept the risk of API changes before a 1.0 release.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
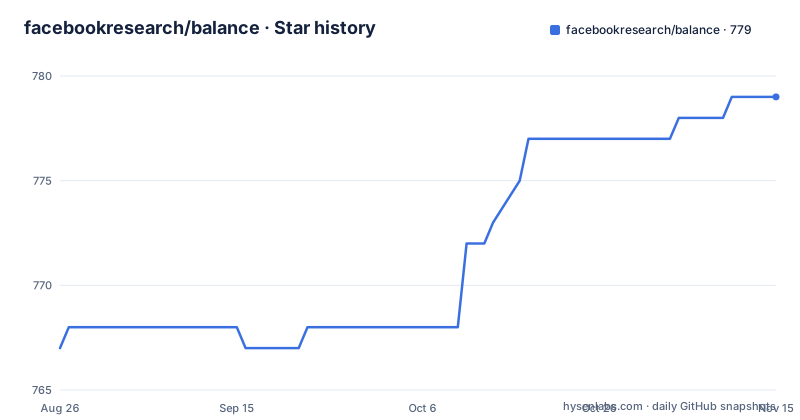
- facebookresearch/balance779 ★ · +12
| Repository | 2026-08-26 | 2026-11-15 |
|---|---|---|
| facebookresearch/balance | 767 | 779 |
12 Stars in the last 81 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What balance actually solves
balance addresses a specific statistical problem: when you have a sample that is not representative of a target population, and you want to make inferences from that sample to the population. This happens with survey non-response, sampling bias, and selection bias in observational studies. The package works under the missing-at-random (MAR) assumption, meaning that bias can be mitigated using auxiliary information, or covariates, that are available for both the sample and a reference sample from the population. For example, a survey of volunteers might over-represent younger people; if age and gender are known for both the respondents and the population, balance can compute weights that make the sample look like the population on those covariates. The intended users are researchers in survey methodology, UX research, market research, and any data science role dealing with biased samples. The package does not solve bias that is missing not at random, where the missingness depends on unobserved factors. That boundary is stated in the documentation and is worth remembering before you apply it to your data.
The weighting workflow: from sample to target
The core workflow in balance is fitting weights to each unit in the sample. Each weight is loosely interpreted as the number of people from the target population that this respondent represents. The README outlines seven steps: load sample data, load target population data, run diagnostics to see if weighting is needed, adjust the sample to the target, evaluate the results, use the weights for population-level estimates, and save the output weights. The package provides a Sample object that holds both the sample and the target. The example code shows how to load simulated data, create Sample objects, set the target, and then call the adjust() method. The adjust() method uses inverse probability weighting (ipw) by default, as shown in the quickstart snippet. The workflow is deliberately simple: you do not need to specify a model formula unless you want to. The package handles the fitting internally, and the adjusted object contains the weights. The documentation also mentions pre-adjustment diagnostics, which let you compare the sample and target covariate distributions before you commit to weighting. This step is useful because it tells you whether weighting is even necessary, and it can reveal covariates where the sample is already balanced.
Getting balance installed and running
Installation is straightforward via pip. The README recommends installing the latest stable version from PyPI with python -m pip install balance. The package supports Python 3.9 through 3.14, and wheels are available for OSX, Linux, and Windows. For the latest development version, you can install from Git with python -m pip install git+https://github.com/facebookresearch/balance.git, or from a local clone using python -m pip install . For development, you can install with dev dependencies using python -m pip install .[dev]. The dependency list is strict and versioned. For Python versions below 3.12, numpy must be at least 1.21.0 and below 2.0, pandas at least 1.5.0 and below 4.0.0, scipy at least 1.7.0 and below 1.14.0, and scikit-learn at least 1.0.0 and below 1.4.0. For Python 3.12 and above, the lower bounds change, but the upper bounds for scipy and scikit-learn are not specified in the README snippet. This strict pinning is a double-edged sword: the bounds are intended to support compatibility, but it can conflict with other packages in your environment that require newer scikit-learn versions. The README shows a quickstart that loads simulated data with load_data(), creates a Sample from a DataFrame, sets a target, and calls adjust(). The code also mentions a plotting method for diagnostics, covars().plot(), which is commented out in the example.
Limitations and failure modes you should know
balance is explicitly in beta, and the README says it is actively supported, but beta status implies potential API changes and less mature error handling. The most significant limitation is the missing-at-random assumption. If your sample is biased in a way that depends on unobserved variables, balance cannot fix it. The package only works when the covariates that explain the bias are present in both the sample and the target population. This is a common constraint in survey weighting, but it is easy to overlook in practice. Another limitation is the strict dependency pinning. The README shows that for Python 3.11 and below, scikit-learn must be below 1.4.0. If you are using a modern machine learning stack that requires scikit-learn 1.4 or later, you cannot install balance without downgrading other packages. This can break your environment or force you to use a separate virtual environment. The package also requires patsy, seaborn, plotly, and matplotlib as dependencies, which are heavy for a weighting library. If you only need the weights, you still pull in a full plotting stack. The documentation does not mention any built-in support for complex survey designs, such as stratification or clustering, which are common in official statistics. This is a gap if your sample comes from a multi-stage survey.
A real alternative: the R survey package
The most direct alternative to balance is the R package survey, which has been the standard tool for survey weighting for years. The difference in approach is fundamental. survey is built around complex survey designs, with explicit handling for strata, clusters, and finite population corrections. balance, by contrast, is a Python package that focuses on the weighting step itself, using methods like inverse probability weighting and presumably other methods that are not detailed in the README. The survey package provides a full suite of functions for descriptive statistics and regression models that take the survey design into account after weighting. balance also provides weighted outcome estimates, including weighted means and outcome-model and AIPW estimators. Check the release-specific documentation for each estimator's assumptions and uncertainty support. If you need design-based inference, such as standard errors that account for clustering, survey is the more complete tool. If you are embedded in a Python ecosystem and need a quick weighting solution without switching to R, balance is more convenient. The trade-off is that you lose the design-based variance estimation that survey provides. For a non-response adjustment with demographic covariates, balance can be useful when the assumptions and diagnostics support the analysis. For a national survey with a complex sampling design, survey is the safer choice.
Maintenance, release cadence, and license
The repository is actively maintained. The last push was on 2026-08-04, and there are recent releases at a monthly-ish cadence: 0.21.0 on 2026-06-02, 0.22.0 on 2026-07-15, and 0.23.0 on 2026-08-04. This regular release pattern suggests that the project is being actively developed, but it also means that APIs may shift between minor versions. The package is licensed under the MIT license, which is permissive and allows commercial use, modification, and redistribution with attribution. There is no copyleft requirement, so you can embed balance in proprietary software without releasing your own code. The README mentions a paper (arXiv:2307.06024) that describes the methodological background, which is useful for understanding the statistical foundations. The project also has a website at import-balance.org with tutorials and a general framework page. The maintenance cost for users is moderate: you need to track releases for API changes, and you must be careful with dependency upgrades. The strict scipy and scikit-learn pins might force you to stay on older versions of those libraries, which could conflict with other packages in your environment. There is no indication of long-term support or a stability guarantee, so you should plan for the possibility of breaking changes before a 1.0 release.
Editorial conclusion
Adopt balance if you are a survey methodologist, demographer, or data scientist who needs a Python-native way to fit survey weights under the missing-at-random assumption and you can tolerate a beta package with strict dependency pins. Do not adopt it if you need production-grade stability, require support for Python versions outside 3.9 to 3.14, or cannot accept the risk of API changes before a 1.0 release. Before adopting, verify that your target population data includes the same covariates as your sample, and confirm that your scipy and scikit-learn versions satisfy the constraints in pyproject.toml. Also, check the current GitHub issues for any unresolved weighting method bugs, since the package is still in beta.
Frequently asked questions
What problem does the balance Python package solve?
It fits weights for a biased sample so that estimates can be read as coming from a target population, for example weighting survey respondents up to population demographics such as age, gender and education. The mitigation is described as relying on the missing at random assumption and on covariates present both for the sample and for a population sample.
How do I install balance from source?
From the Git remote with python -m pip install git+https://github.com/facebookresearch/balance.git, from a local clone with python -m pip install ., or with python -m pip install .[dev] to add pytest, coverage, sphinx, notebook, nbconvert and pre-commit. The stable release is python -m pip install balance from PyPi.
What Python versions does balance support?
Python 3.9 through 3.14, declared as requires-python >=3.9, buildable and runnable on Linux, OSX and Windows. Dependency floors differ by interpreter, with numpy at 1.21 then 1.24, pandas 1.5 then 2.0, scipy 1.7 then 1.11 and scikit-learn 1.0 then 1.3.
How does balance fit its weights?
The quickstart builds a Sample from a frame with an outcome column, sets the target population on it with set_target, and calls adjust(), which the sample code labels as fitting ipw weights. Pre-adjustment diagnostics are available as sample_with_target.covars().plot(), commented out in the shipped snippet.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/facebookresearch-balance)Star history chart for your README
[](https://hysenlabs.com/projects/facebookresearch-balance)Was this useful?