oh-my-agent: A Multi-Agent Harness That Verifies Work by Checking Artifacts, Not Narratives
Portable, vendor-agnostic agent harness for project-specific skills, workflows, and agent teams aligned with your codebase, conventions, and engineering standards.
At a glance
- What is it?
- oh-my-agent is a portable, vendor-agnostic harness that enforces verification of agent output through mechanical gates, independent judges, and an append-only event log. It targets engineering teams that run multi-agent workflows and need to trust that the work was actually done.
- Who is it for?
- Adopt oh-my-agent if your team runs multi-agent workflows and needs to verify that agents actually completed the work, not just claimed it. It is especially suited for projects with existing typecheck, test, and lint scripts, and for teams that want to enforce budgets and auditability.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
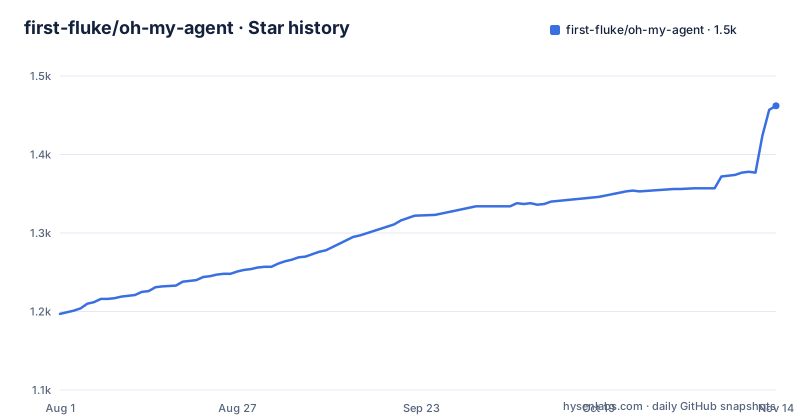
- first-fluke/oh-my-agent1,462 ★ · +265
| Repository | 2026-08-01 | 2026-11-14 |
|---|---|---|
| first-fluke/oh-my-agent | 1.2k | 1.5k |
265 Stars in the last 105 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Problem: Agents Narrate Success, but Narration Is Not Evidence
oh-my-agent addresses a specific failure mode in multi-agent workflows: an agent can say "tests pass, all criteria met" without any mechanism to contradict that claim within the same session. The README states that "Agents narrate success. oh-my-agent checks the artifacts." This is the core problem the project solves. It is for engineers who run parallel agents and need to know whether the work actually happened. The harness makes the claim falsifiable by introducing mechanical checks that do not rely on an LLM's opinion. A command either exits 0 or it does not. A file is on disk or it is not. This is a different approach from simply asking an agent to self-report. The target audience is teams that have already adopted agent-based development and are now facing the trust problem: how do you know the agent did what it said? The project's answer is to move verification out of the agent's context and into the file system and process exit codes.
Mechanisms: Stop Hooks, Gate Commands, and Independent Judges
The harness uses several distinct mechanisms, each with a specific mechanical check. The Stop hook refuses to end a session while a persistent workflow is active and runs a configured gate script before allowing a stop. Only typecheck, test, and lint are executable; an agent that writes anything else into the state file gets it ignored, never run. The hook is capped at 5 reinforcements, so a permanently red gate cannot trap you. The Anti-Circumvention Gate, invoked via `oma ralph:verify --json`, checks four artifacts: ultrawork's phase records, the plan JSON, a distinct QA agent's result file, and a distinct refactor agent's result file. Missing artifacts mean the phase did not run, regardless of narration. The independent judge is spawned as a separate agent with fresh context, briefed only on the criteria, never on what the implementer claims. It re-verifies every criterion each iteration, including prior passes, because fixing C2 can silently regress C1. These mechanisms are documented in the repository, and the README points to specific files like `.agents/hooks/core/persistent-mode.ts` and `.agents/workflows/ralph.md`.
Event-Sourced State: An Append-Only Log for Auditing
Every gate pass, gate failure, and decision appends one JSON line to `.agents/state/sessions/{sid}/events.jsonl`, stamped with vendor and runtime session id. This is an append-only, cross-vendor log that you can read after the run. The event-sourced state is not just for debugging; it is part of the verification story. Because the log is append-only, you can audit what happened after the fact. The README describes the event spec at `.agents/skills/_shared/runtime/event-spec.md`. This design choice means that the state is not a mutable database but a sequence of facts. For a team that needs to trace why a workflow passed or failed, this log is the source of truth. The budget enforcement also writes to this log: when the wall-clock budget runs out, the Stop hook stops honestly with partial status recorded, rather than pretending completion. This is a concrete way to handle resource limits without losing information.
Getting Started: Install Scripts and Presets
The README provides three installation paths. For macOS and Linux, you run `curl -fsSL https://raw.githubusercontent.com/first-fluke/oh-my-agent/main/cli/install.sh | bash`. For Windows PowerShell, you run `irm https://raw.githubusercontent.com/first-fluke/oh-my-agent/main/cli/install.ps1 | iex`. Both scripts auto-install bun, uv, and serena if they are missing. The manual method, for any OS, requires bun, uv, and serena, and you run `bunx oh-my-agent@latest`. There is also an option to install skills via Microsoft's Agent Package Manager (APM), but the README warns that APM ships skills only; for workflows, rules, `oma-config.yaml`, keyword-detection hooks, and the `oma agent:spawn` CLI, you must use `bunx oh-my-agent@latest`. The README advises picking one distribution per project to avoid drift. After installation, you choose a preset: All, Backend, Content, DevOps, Frontend, Fullstack, Fullstack Mobile, Fullstack Web, Mobile, or Research. Each preset includes a specific set of agents and skills, such as `architecture`, `backend`, `brainstorm`, `db`, `debug`, `dev-workflow`, `pm`, `qa`, `scm`, and others. This makes it easy to start with a curated set rather than everything.
Vendor Agnosticism: One .agents Directory, Multiple Runtimes
The harness keeps `.agents/` as the single source of truth and projects it into each runtime's native layout. The README states that every supported tool shares the same skills, workflows, rules, and gates, and that switching vendors is a config change, not a migration. The README mentions `.claude`, `.cursor`, `.codex`, `.opencode`, `.github`, and `.agents` as detected runtimes in the APM install command. This is a meaningful design choice: instead of writing separate configs for each agent tool, you define once and project. The benefit is reduced drift and easier vendor migration. The trade-off is that you depend on the projection logic to be correct for each runtime. If a runtime changes its config format, the projection may break. The README does not detail how the projection works, but the fact that it exists is a core value proposition. For teams that are not locked into a single vendor, this is a practical advantage.
Limitations and Failure Modes
One limitation is that the stop-hook gate only executes `typecheck`, `test`, and `lint` scripts. If your project uses a different verification command, such as a custom build check or a security scanner, you cannot use the stop hook for that. The README says that an agent that writes anything else into the state file gets it ignored, never run. This is a deliberate security measure, but it also means the gate is limited to those three script names. Another failure mode is the 5-reinforcement cap. If a gate is permanently red, the session will end after 5 reinforcements, which means you can end up with a session that stopped without passing the gate. The README says the cap prevents a permanently red gate from trapping you, but it also means you might get a false sense of completion if you do not check the event log. The anti-circumvention gate requires specific artifacts: phase records, plan JSON, and result files from distinct QA and refactor agents. If your workflow does not produce those exact artifacts, the gate will fail. This is a strict requirement, and it means the gate is not generic. It is designed for the `ralph` workflow, not for any arbitrary agent team.
Alternatives and Comparison
The most direct alternative is to rely on the agent runtime's built-in verification, such as running tests manually after each agent run. That approach lacks the mechanical enforcement and audit trail that oh-my-agent provides. Another alternative is to use a CI pipeline to run checks after the agent finishes, but that does not prevent the agent from claiming success before the pipeline runs. oh-my-agent's difference is that it integrates verification into the agent session itself, blocking termination until gates pass. A more specific alternative is Microsoft's Agent Package Manager (APM), which the README mentions. APM can install skills but does not provide workflows, rules, or the CLI. oh-my-agent uses APM as a distribution channel for skills but requires its own CLI for the full harness. So if you only need to distribute skills, APM alone is lighter. If you need the verification gates and event log, oh-my-agent is the more complete package. The README explicitly warns against using both distributions in the same project to avoid drift.
Maintenance, Upgrade Cost, and License
The project is under the MIT license, which is permissive and allows commercial use, modification, and distribution. The repository is actively maintained, with recent releases on 2026-08-28 and 2026-08-27, including cli-v12.8.0 and web-v4.2.5. The version numbers suggest a mature project with frequent updates. The maintenance cost for a user is moderate: you need to keep up with CLI and web releases, and the README warns against mixing APM and CLI distributions in the same project, which implies you must choose one and stick with it. Upgrading likely involves running the install script again or updating the npm package, but the README does not detail the upgrade process. The event log format is specified in `event-spec.md`, which suggests that the log schema is versioned and may change between releases. You should check that file before upgrading to ensure your audit tooling still works. The dependency on bun, uv, and serena is a real cost: you must have those tools installed, and the install scripts auto-install them, but that means your environment changes during installation. If you are in a locked-down environment, that could be a problem.
Editorial conclusion
Adopt oh-my-agent if your team runs multi-agent workflows and needs to verify that agents actually completed the work, not just claimed it. It is especially suited for projects with existing typecheck, test, and lint scripts, and for teams that want to enforce budgets and auditability. Do not adopt it if you are happy with trusting agent summaries or if your project lacks the artifact-producing scripts that the gates rely on. Before adopting, verify that your build scripts exit 0 on success, that your runtime (bun, uv, serena) is available, and that you understand the 5-reinforcement cap on the stop hook, which may allow a session to end despite a red gate. Also confirm that the skill evaluation harness (oma skills eval) fits your workflow, as it requires held-out tasks to measure utility lift.
Frequently asked questions
What is oh-my-agent and what problem does it solve?
It is a vendor-neutral agent harness for project-specific skills, workflows and agent teams. Its stated problem is that an agent claiming its tests pass costs it nothing to say, and nothing in the same session can contradict that claim.
How does oh-my-agent stop an agent from claiming success it did not achieve?
A stop hook refuses to end the session until your project's own typecheck, test or lint script exits zero, and a gate command decides whether a workflow really ran by looking for the artefacts it should have left behind, returning a JSON verdict rather than a summary.
How do I install oh-my-agent?
Skills only, with npx skills add first-fluke/oh-my-agent. The full harness needs bun, uv and serena and installs through bunx oh-my-agent@latest or a script fetched from the main branch. A fifth path uses Microsoft's agent package manager, which ships skills only. The page advises picking one path per project to avoid drift.
Which coding agents does oh-my-agent support?
Twelve appear in the table, at six integration levels: native plus an adapter for Claude Code, Codex CLI and Cursor, native single source of truth for Antigravity, native dispatch for Qwen Code, native-compatible for Reasonix, Pi, OpenCode and Amp, symlinked skills for GitHub Copilot, native hooks for Grok Build, and native hooks plus agents for Kiro CLI.
What do the oh-my-agent skill presets contain?
Ten rows covering everything or a named stack, naming twenty-three distinct skills. One skill appears in every preset, three appear in all seven engineering presets and neither writing preset, and the content and research presets share exactly three skills with each other.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/first-fluke-oh-my-agent)Star history chart for your README
[](https://hysenlabs.com/projects/first-fluke-oh-my-agent)Was this useful?