insane-search: a Claude Code plugin that escalates past 403s without API keys
Auto-bypass for blocked websites in Claude Code — Phase 0→3 adaptive scheduler, no API keys
At a glance
- What is it?
- insane-search adds an adaptive Phase 0 to 3 fetch scheduler to Claude Code, so blocked public pages get retried through feeds, TLS impersonation and a headless browser. It stops at logins and paywalls, and it ships as a plugin rather than a library.
- Who is it for?
- Adopt insane-search if your Claude Code sessions regularly stall on 403s from Reddit, X, YouTube, Hacker News or news sites, and you accept that a login wall ends the attempt. Do not adopt it if you need authenticated or paywalled content, or if you want a Python library you call from your own code rather than a plugin inside Claude Code.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
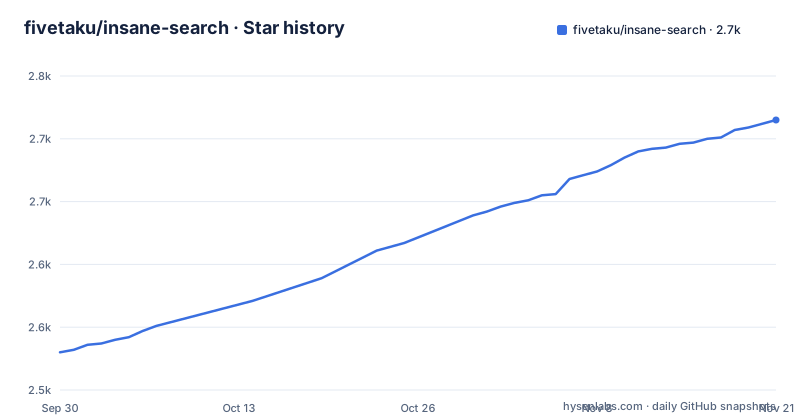
- fivetaku/insane-search2,715 ★ · +185
| Repository | 2026-09-30 | 2026-11-21 |
|---|---|---|
| fivetaku/insane-search | 2.5k | 2.7k |
185 Stars in the last 52 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem insane-search targets: a fetch that gives up on the first 403
A coding agent that cannot read a page is not much use for research tasks. Ask Claude Code to summarize a Reddit thread and the ordinary fetch path often returns a 403, a WAF challenge or an empty body, and the session ends with a statement that the page could not be read. The README frames the plugin's purpose as exactly this gap: it is a reader for public content that keeps trying routes until one works, rather than reporting failure after a single attempt.
The audience is narrow and identifiable. You already run Claude Code, you already ask it to pull in outside pages, and you do not want to register for API keys or configure a proxy to do it. The README's install section promises no commands to learn: you ask Claude Code normally and the plugin activates when a fetch is blocked. That is a different product shape from a scraping library. There is no function to call, no session object to construct, and no return value to handle in your own code. The unit of use is a conversation.
It is worth being blunt about what that means. If you want programmatic control over retry policy, headers or timeouts, this is the wrong layer. If you want an agent to stop shrugging at 403s during ordinary work, it is the right one.
Phase 0 to 3: how the escalation scheduler actually decides what to try
The README describes an adaptive scheduler where each phase runs only if the previous one fails or detects a blocking signal. Phase 0 covers special public endpoints the plugin cannot discover generically, which in practice means platform APIs and feeds. Phase 1 runs lightweight probes: public API readers, syndication gateways, and mobile, `.json` or `/rss` URL variants. Phase 2 moves to TLS impersonation through `curl_cffi`, cycling safari, chrome and firefox fingerprints alongside a full browser identity rather than a swapped User-Agent. Phase 3 launches a real headless browser for pages that need JavaScript to render.
The exit condition is the interesting design choice. When a login or paywall is detected, the plugin reports "authentication required" instead of continuing to escalate. That is a deliberate boundary, and it is stated twice: once in the pipeline description and again in a Boundaries section that says insane-search never logs in as you and never stores or transmits credentials.
A second mechanism runs alongside the phases. Every response is scanned for OGP and JSON-LD, so a partially blocked page can still yield a title, a summary or a price. This is why the README can claim that metadata still comes back when the article body does not. The v0.16.2 release note mentions reaching portal hosts through their `m.` twin via `m_prefix_subdomain`, which is a concrete example of the Phase 1 URL-variant idea rather than a generic claim about mobile sites.
One thing the README does not document is rollback. There is no described way to undo an escalation that returns the wrong content, or to force a specific phase for a specific domain. The scheduler decides; you observe the result.
Installing insane-search as a Claude Code plugin and reading a first blocked page
Installation goes through the Claude Code plugin marketplace rather than pip or npm. The README gives three commands and a reload. The marketplace points at the gptaku_plugins repository, and the plugin is installed from the `gptaku-plugins` marketplace name.
/plugin marketplace add https://github.com/fivetaku/gptaku_plugins.git
/plugin install insane-search@gptaku-plugins
/reload-plugins
After the reload, there is nothing to configure. The README states that dependencies such as `curl_cffi` and `yt-dlp` are auto-installed on first use, so the first blocked fetch may pause while that happens. If your environment forbids package installation at runtime, that is a blocker worth knowing before you rely on the plugin.
The first real use is an ordinary prompt. The README's own example asks Claude to find what people are saying about Claude Code on Reddit and summarize the top threads. Expected behavior, per the README, is that Claude reaches Reddit's feed with no login and no API key. A second example asks for X posts about insane-search; the README says the free route uses Brave and Yahoo discovery plus tweet-result validation, and that if xAI credentials already exist the X keyword discovery is augmented with native `x_search` while the free route stays active.
That augmentation can be turned off. The README names the environment variable `INSANE_SEARCH_XAI` and the value `off` to force the free route. For diagnostics, v0.16.3 introduced `--json-content`, which returns metadata, trace and the wrapped untrusted text in one fetch, so you do not request the same URL twice to see what happened. The older `--json` output still omits the body.
Where insane-search stops: logins, paywalls and the cost of auto-installed dependencies
The clearest limitation is stated by the project itself. A login wall or paywall is a hard stop. The plugin reports authentication required and does not attempt to defeat the gate. If your work depends on content behind a subscription or an account, this tool will not help, and the README's comparison table marks that row with a cross on both sides.
The second constraint is environmental. Auto-installing `curl_cffi` and `yt-dlp` on first use is convenient on a developer laptop and awkward in a locked-down container, a CI runner or a corporate machine with an allowlist. The README does not document an offline install path or a way to pre-provision those dependencies, so verify your environment before assuming the zero-setup claim holds for you.
The third is legal and ethical rather than technical. The README is explicit that the plugin is a dual-use developer tool and that you are responsible for lawful, authorized use, including each site's terms of service, `robots.txt`, rate limits and applicable law. TLS impersonation and headless browsers are standard techniques, but standard does not mean permitted everywhere. The project does not audit your target list for you.
Finally, the README does not document rollback, per-domain phase overrides, or a way to inspect why a particular phase was chosen beyond the trace returned by `--json-content`. Debugging a wrong result means reading that trace rather than setting a flag.
insane-search compared with writing your own curl_cffi and yt-dlp pipeline
The obvious alternative is a small Python script: call `curl_cffi` with a browser impersonation target, fall back to `yt-dlp` for media pages, and parse OGP tags yourself. The difference in approach is where the decision logic lives. A script has a fixed order you wrote, and it fails in the way you anticipated. insane-search evaluates blocking signals between phases and chooses the next route adaptively, which the README describes as escalating rather than pre-judging.
The trade-off runs the other way too. A script is inspectable line by line, testable in CI, and versioned with your application. insane-search lives inside a Claude Code session, installs its own dependencies at runtime, and exposes no documented API for calling a phase directly. You get less control and less reproducibility in exchange for not maintaining the escalation ladder.
A second alternative is simply using Claude Code's built-in fetch and accepting the failures. For sites that never block, that is the correct choice: no plugin, no auto-installed packages, no escalation. insane-search only earns its place when blocked fetches are a recurring interruption rather than an occasional one.
A third route is a hosted scraping or reader API. That moves the problem to a vendor, adds a key and a bill, and contradicts the README's no-API-key premise. It may still be the better answer for authenticated content, which insane-search explicitly refuses to touch.
Maintenance, licence and what the repository layout tells you
The repository is not archived, and the last push was on 2026-09-28. The most recent release listed is v0.16.3 from 2026-09-08, with v0.16.2 and v0.16.1 landing earlier that month. The changelog entries are specific and small: masking credentials in logged URLs, reaching portal hosts through their `m.` twin, and combining content with trace in one fetch. That pattern suggests incremental maintenance rather than a rewrite in progress. The README does not publish a support window or a compatibility matrix for Claude Code versions, so pinning to a known-good release is not something the project documents how to do.
The project is MIT licensed. In practical terms that permits commercial use, modification and redistribution provided the licence and copyright notice are retained. It says nothing about the terms of the sites you fetch, which is where the real constraint sits. The README points to a separate DISCLAIMER.md for acceptable-use and user-responsibility terms, and that file is the one to read before deploying this inside an organisation. This is not legal advice; if your use is commercial and high-volume, a lawyer should look at the disclaimer and at the target sites' terms together.
The repository layout includes a `skills/` directory and a `setup/` directory alongside `.claude-plugin/`, plus translated READMEs in Korean, Chinese, Japanese and Spanish and a PLATFORMS.md listing the supported sites and methods. The README's platform list names X, Reddit, YouTube, Hacker News, Naver, Coupang, LinkedIn, Medium, Substack, arXiv, GitHub, Stack Overflow, Bluesky and Mastodon, and says any site with a public page, feed or `/rss` is also in scope. PLATFORMS.md is where the per-site method is documented, and it is the file to check when a specific domain matters to you.
Editorial conclusion
Adopt insane-search if your Claude Code sessions regularly stall on 403s from Reddit, X, YouTube, Hacker News or news sites, and you accept that a login wall ends the attempt. Do not adopt it if you need authenticated or paywalled content, or if you want a Python library you call from your own code rather than a plugin inside Claude Code. Verify first that your Claude Code install accepts the marketplace command, that the auto-installed curl_cffi and yt-dlp dependencies are permitted on your machine, and that the sites you fetch allow the routes described in PLATFORMS.md under their terms of service.
Frequently asked questions
Does insane-search need an API key?
No. The README states that no API keys and no signup are required, and that the free route for X discovery stays active even when xAI credentials are present. The xAI path only augments keyword discovery when those credentials already exist, and it can be forced off with INSANE_SEARCH_XAI=off.
Can insane-search get past a login wall or a paywall?
No. The README states that it stops at logins and paywalls and reports authentication required instead of attempting to defeat them. It also says the plugin never logs in as you and never stores or transmits credentials.
How do I install insane-search in Claude Code?
The README gives three commands: add the gptaku_plugins marketplace from its GitHub URL, install insane-search@gptaku-plugins, then run /reload-plugins. Dependencies such as curl_cffi and yt-dlp are auto-installed on first use.
What does the Phase 0 to 3 scheduler do?
Each phase runs only if the previous one fails or detects a blocking signal. Phase 0 handles special public endpoints, Phase 1 runs lightweight probes against public APIs, syndication gateways and URL variants, Phase 2 uses curl_cffi TLS impersonation, and Phase 3 launches a real headless browser for JavaScript-rendered pages.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fivetaku-insane-search)Star history chart for your README
[](https://hysenlabs.com/projects/fivetaku-insane-search)Was this useful?