Fluent Bit 5.1: A C-based telemetry pipeline that trades breadth for speed
Fast and Lightweight Logs, Metrics and Traces processor for Linux, BSD, OSX and Windows.
At a glance
- What is it?
- Fluent Bit is a CNCF-graduated telemetry agent that collects logs, metrics, and traces with a small memory footprint. This review covers its architecture, build steps, plugin model, and where its lightweight design becomes a constraint.
- Who is it for?
- Adopt Fluent Bit if you run edge devices, containers, or any environment where CPU and memory are scarce and you need a single agent for logs, metrics, and traces. Skip it if you need complex stream processing beyond SQL or if your team prefers a higher-level language for plugin development.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
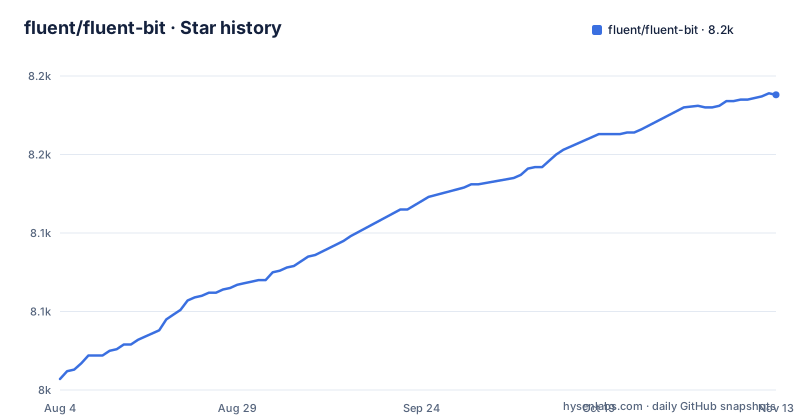
- fluent/fluent-bit8,188 ★ · +181
| Repository | 2026-08-04 | 2026-11-13 |
|---|---|---|
| fluent/fluent-bit | 8k | 8.2k |
181 Stars in the last 101 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Fluent Bit solves and who it targets
Fluent Bit solves a specific operational problem: collecting telemetry from resource-constrained environments without eating the host. The README describes it as a lightweight and high-performance telemetry agent for logs, metrics, and traces. That three-type support is a differentiator. Many agents handle logs only, or logs and metrics as an afterthought. Fluent Bit puts all three on equal footing in one binary, written in C. The target user is an engineer running Kubernetes nodes, edge gateways, or embedded Linux devices who cannot afford a Java or Ruby agent. The project is a CNCF graduated project, which means it has passed governance and adoption checks, not that it is bug-free. The README claims over 10 million daily deployments and 15 billion downloads, but those numbers are vendor claims, not independent measurements. Treat them as marketing context, not a technical signal.
How the pipeline works: inputs, filters, outputs
The core mechanism is a pipeline with three plugin categories. Input plugins collect data, filter plugins transform it, and output plugins deliver it. The README lists 70+ built-in plugins across those categories. The data flow is linear: an input produces records, filters modify them in sequence, and an output sends them to a destination. What makes this different from a general-purpose stream processor is that Fluent Bit is designed for forwarding, not for arbitrary computation. It does include SQL stream processing, which lets you run analytics and transformations with SQL queries. That is a real feature, but it is not a replacement for a dedicated stream processor. The project supports async I/O and TLS.
Build and run: real commands from the README
The quick start gives a concrete path. You need CMake 3.0 or newer, Flex and Bison, and YAML and OpenSSL headers. The build sequence is: cd build, then cmake .., then make. That produces a binary at bin/fluent-bit. The example invocation is bin/fluent-bit -i cpu -o stdout -f 1. That command reads CPU metrics and writes them to standard output. The -f 1 flag sets a flush interval of one second. This is a minimal smoke test. For real deployments, you would use a configuration file, but the README does not show one. The build is straightforward for anyone who has compiled C projects. The requirement for Flex and Bison is worth noting: those are parser generators, and they are not common dependencies for a telemetry agent. If your build environment lacks them, you will need to install them first.
The plugin model: C, Lua, and Go
Extensibility is a key design decision. The README states you can write plugins in C, filters in Lua, and outputs in Go. Lua is easier for filter logic, but it runs in an embedded interpreter, so it adds a dependency. Go outputs are interesting because Go is not typically embedded in a C project. The documentation does not explain how the Go runtime is linked or whether it increases binary size. This is a trade-off: a single binary with three language runtimes is no longer as lightweight as the marketing implies. If you never write custom plugins, the built-in 70+ set covers most common endpoints, so you may not need the extension paths at all.
Where it is the wrong tool
Fluent Bit is not a good fit for complex stream processing. Its SQL feature is described as analytics and transformations, but it is not a full query engine. If you need windowed aggregations, joins across multiple streams, or stateful event-time processing, you should look elsewhere. The README does not mention exactly-once semantics or exactly-once delivery, so do not assume it for critical data paths. Another limitation is the fast release cadence: major releases every 3-4 months. That means you will be upgrading frequently to stay on a supported version. The README points to MAINTENANCE.md for version-specific timelines, but it does not state those timelines in the README itself. For long-lived embedded devices, a 3-4 month major release cycle can force you to choose between staying current and freezing on a version that may lose support. The project does maintain a stable branch, but you must read MAINTENANCE.md to understand the support window.
Alternatives and the difference in approach
The most direct alternative is Fluentd, the project Fluent Bit is part of. Fluentd is written in Ruby and uses a plugin architecture that is easier to extend but heavier at runtime. Fluent Bit is the lightweight sibling. The README explicitly calls Fluent Bit part of the Fluentd ecosystem, so the two are not competitors in the usual sense. A true alternative is Vector, a Rust-based agent that also handles logs, metrics, and traces. Vector uses a different data model: it has a topology of sources, transforms, and sinks, and it provides more built-in transforms for data shaping. The key difference is that Vector is written in Rust, so it has a different deployment footprint and a different plugin language story. The choice depends on whether you prioritize minimal resource use or configuration flexibility.
Maintenance and license implications
The license is Apache-2.0, which is permissive. You can use Fluent Bit in commercial products, modify it, and redistribute it, as long as you preserve the license notices. That is a low-friction license for most companies. The maintenance story is more complex. The project follows a fast-paced cycle with major releases every 3-4 months. The master branch tracks development of v5.2.0, while the current stable series, v5.1, is tracked in the 5.1 branch. The repository also lists v5.0.11 as a recent release alongside v5.1.4 and v5.1.5, which suggests that multiple series are maintained in parallel. You need to check MAINTENANCE.md to know which series get security fixes and for how long. The README does not give that detail. The CI status table shows unit tests, integration tests, Arm builds, and a release pipeline, so there is automated testing. But the fast release cadence means you should budget time for regression testing on each upgrade, especially if you use custom plugins.
Editorial conclusion
Adopt Fluent Bit if you run edge devices, containers, or any environment where CPU and memory are scarce and you need a single agent for logs, metrics, and traces. Skip it if you need complex stream processing beyond SQL or if your team prefers a higher-level language for plugin development. Before adopting, verify that the 70+ plugins cover your specific input and output endpoints, and check the MAINTENANCE.md for version-specific support timelines, since the project releases major versions every 3-4 months and you will need to plan upgrades accordingly.
Frequently asked questions
What is a Fluent Bit?
A lightweight, high-performance telemetry agent that collects, processes and forwards logs, metrics and traces from any source to any destination. It is part of the graduated Fluentd ecosystem and a CNCF project, and it supports Linux, Windows, macOS, BSD and embedded environments.
Why use Fluent Bit?
The stated reasons are high performance with a low memory footprint, a pluggable architecture with more than seventy built-in plugins across inputs, filters and outputs, SQL stream processing for analytics and transformations, built-in TLS support with asynchronous I/O, internal metrics exposed over HTTP or Prometheus, and unified handling of logs, metrics and traces.
how to install fluent bit
The readme links three installation routes: Linux packages covering distributions such as Debian, Ubuntu and RHEL, Docker images, and Windows binaries. Building from source is documented separately and needs cmake, make, a parser generator pair, and the YAML and OpenSSL headers.
how to use fluent bit
The pipeline is three plugin stages: inputs collect, filters enrich and transform, outputs deliver. The quick start builds from source with cmake and make and then runs the binary with an input plugin, an output plugin and a flush interval, which is the whole configuration model in one argument list. The full plugin list lives in the documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/fluent-fluent-bit)Star history chart for your README
[](https://hysenlabs.com/projects/fluent-fluent-bit)Was this useful?