Omni: A self-hosted agent stack that puts Postgres at the center
The open agent stack for enterprise - connect any AI model to internal apps and data
At a glance
- What is it?
- Omni is an open-source, self-hosted AI agent that connects to workplace tools like Google Drive, Slack, and Jira. Its architecture uses Postgres with ParadeDB and pgvector for search, Rust for orchestration, and sandboxed code execution, but early releases and a young project mean you should verify maturity before adopting.
- Who is it for?
- Adopt Omni if you need a self-hosted agent that respects source permissions and you are comfortable running Postgres with ParadeDB and pgvector as your only data layer. Do not adopt it if you require a mature, battle-tested system or if your team lacks Rust and Python operational skills.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
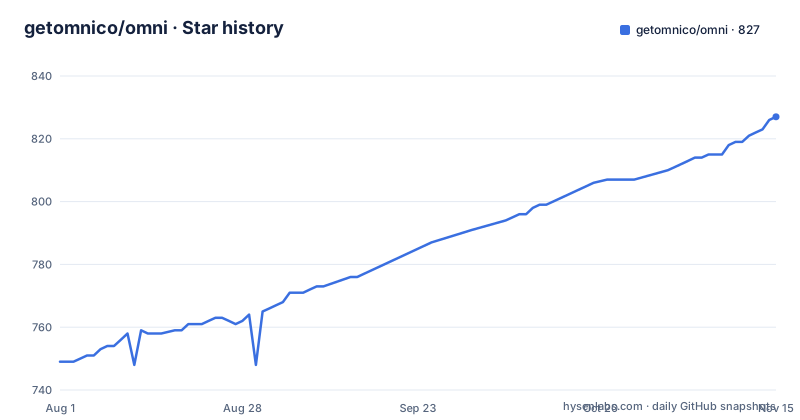
Star history
- getomnico/omni827 ★ · +78
| Repository | 2026-08-01 | 2026-11-15 |
|---|---|---|
| getomnico/omni | 749 | 827 |
78 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What problem Omni solves and who it targets
Omni addresses a specific pain: employees need to ask questions and run tasks across many company systems without leaving a single conversation. The README describes it as an open-source, self-hosted AI agent for company-wide work. It connects to Google Drive, Gmail, Slack, Confluence, Jira, HubSpot, and internal file systems. The intended user is an enterprise team that wants to give its staff an agent that gathers context, analyzes information, and carries out supported actions while respecting existing permissions. This is not a personal assistant or a toy. It is built for organizations that already have a sprawl of SaaS tools and want a unified interface without sending data to a third-party cloud. The target user is an engineering or IT team that can operate its own infrastructure and is willing to tune a Postgres database.
The architecture: one database, three languages, isolated connectors
The architecture is deliberately different from many agent frameworks that bolt on a vector database and a search engine. Omni uses Postgres with ParadeDB for BM25 full-text search and pgvector for semantic search, all inside the same database. The README states: No Elasticsearch. No dedicated vector database. One database to tune, backup, monitor, and operate. This is a strong simplification argument. Core services are written in Rust for search, indexing, and connector orchestration. Python runs the agent runtime and model orchestration. SvelteKit provides the web frontend. Each connector runs as its own lightweight container, which means a connector can use its own language and dependencies without affecting the rest of the system. That isolation is a real design choice: a bug in the Slack connector does not crash the search service. The agent runtime can execute Python and bash in a sandboxed container on an isolated Docker network, with no access to internal services or the internet. It uses Landlock filesystem restrictions, resource limits, and a read-only root filesystem. This is a concrete security posture, though the README does not specify which kernel versions or Docker configurations are required.
How retrieval and permissions work
Omni's retrieval combines two search methods: BM25 full-text search via ParadeDB and semantic search via pgvector. Both live inside Postgres, so there is no separate index to sync. The README mentions hybrid search and retrieval, which typically means combining keyword and vector results, but it does not detail the fusion algorithm. More important is the permission model. The feature list says: Permission-Aware Company Context: Keep indexed information scoped by the permissions inherited from each source system. This means that when a user asks a question, the agent should only retrieve documents that the user can already access in the source system. That is a critical design constraint. The README does not explain how permissions are propagated from each connector to the index. It is a hard problem. For example, a Google Drive file shared with a specific person should not be visible to others. The documentation link points to docs.getomni.co/architecture, but the README itself gives no implementation details. This is a gap you must investigate before trusting the system with sensitive data.
Deployment: Docker Compose for small, Terraform for production
The README describes two deployment paths. For single-server deployments, use Docker Compose. For production deployments on AWS and GCP, use Terraform. There is also an Omni CLI for Docker Compose upgrades and diagnostics. The commands are not listed in the README, but the documentation links point to deploy guides. The Terraform option suggests the project expects serious production use. A single Postgres database means backup and monitoring are simpler than a multi-component stack. However, the README does not specify hardware requirements, minimum Postgres versions, or whether ParadeDB is a Postgres extension or a fork. You will need to read the deployment guides to know exact commands. The release cadence is active: v0.1.18 was pushed on 2026-08-29, with v0.1.17 and v0.1.16 in the weeks before. That suggests rapid development, but also that the project is young and APIs may change.
Model flexibility and MCP extensibility
Omni does not lock you into one model provider. The README lists Anthropic, OpenAI, Gemini, AWS Bedrock, Vertex AI, Azure AI Foundry, and any OpenAI-compatible endpoint such as vLLM, Ollama, LM Studio, and LiteLLM. This is a practical choice for enterprises that already have contracts or data residency requirements. For extending the system, Omni supports MCP tools and provides Connector SDKs in Python and TypeScript. MCP, or the Model Context Protocol, is a standard way to expose tools to AI models. Using MCP means you can bring your own tools without waiting for Omni to build a native connector. The connector SDKs let you build company-specific integrations. This extensibility is a strong point: you are not limited to the listed connectors. However, the README does not show an example of how to write a connector or what the SDK looks like. You would need to consult the documentation to assess the effort.
Limitations and failure modes
The biggest limitation is the lack of detail on the permission model. The README claims permission-aware context, but it does not explain how permissions are enforced at query time. If the index stores documents with metadata about who can see them, then a bug in that metadata could leak information. The sandboxed code execution is another area of concern. The README says the sandbox uses an isolated Docker network with no access to internal services or the internet, plus Landlock and resource limits. That is a solid set of controls, but Docker sandboxes are not bulletproof. A determined attacker might find a kernel escape. For a production system, you would need to run your own security review. Another limitation is the project's maturity. The latest release is v0.1.18, which means the API is not stable. Upgrades between minor versions may break. The README does not mention a migration path or a long-term support policy. If you deploy Omni today, you should expect to follow releases closely and test each upgrade.
Alternatives and how they differ
A direct alternative is a custom retrieval-augmented generation stack built on LangChain or LlamaIndex, combined with a vector database like Pinecone or Weaviate. The difference is in architecture. LangChain is a framework you assemble yourself. You choose the vector store, the embedding model, and the orchestration logic. Omni gives you a complete system with connectors, a search layer, and a sandbox already integrated. The trade-off is control versus convenience. With LangChain, you can fix a permission bug by writing your own code. With Omni, you depend on the project's implementation. Another alternative is a commercial platform like Glean or Coveo, which offer enterprise search with AI. Those are closed-source and hosted, so they violate the self-hosted requirement. Omni's advantage is that you can run it entirely in your cloud or on-premises. The disadvantage is that you take on the operational burden. For a team that already runs Postgres and wants a single database for search, Omni's approach is simpler than spinning up a separate vector database.
License, maintenance, and upgrade cost
Omni is licensed under Apache-2.0. That is a permissive license that allows commercial use, modification, and redistribution, with the requirement to preserve the license notice. It does not require you to open-source your changes. This is favorable for enterprises that want to fork and customize. The maintenance cost is tied to the architecture. Because everything runs on Postgres, you only need to tune one database. But you also need to maintain Rust and Python services, plus a SvelteKit frontend. Each connector runs as a container, so you have many images to update. The release cadence is fast, with three releases in August 2026. That means you should expect frequent updates. The README mentions an Omni CLI for upgrades and diagnostics, which suggests the project is trying to reduce the pain of upgrades. Still, with a v0.1.x version, you should not assume backward compatibility. Plan for breaking changes and budget time for testing each new release.
Editorial conclusion
Adopt Omni if you need a self-hosted agent that respects source permissions and you are comfortable running Postgres with ParadeDB and pgvector as your only data layer. Do not adopt it if you require a mature, battle-tested system or if your team lacks Rust and Python operational skills. Before committing, verify the current release v0.1.18 against your exact connector list, test the sandbox isolation on your Docker network, and confirm that the Terraform modules match your AWS or GCP setup. Omni is a promising architecture, but it is early and you must validate its behavior with your own workloads first.
Frequently asked questions
What is the omni agent stack and what language is it written in?
A self-hosted AI agent that connects to company systems such as Google Drive, Gmail, Slack, Confluence, Jira and internal file systems, gathers context, and carries out supported actions across them. Core services are Rust for search, indexing and connector orchestration, Python for the agent runtime and model orchestration, and SvelteKit for the web frontend. The licence is Apache-2.0.
Which integrations does omni support?
The visible tables cover Google Workspace with Drive, Gmail and Chat, Microsoft 365 with SharePoint, OneDrive, Outlook and Calendar, and Teams, a knowledge base group of Confluence, Notion, Nextcloud, Paperless-ngx, Web and local files, communication through Slack, Fireflies and IMAP, and project management through Jira, GitHub, ClickUp and Linear. The example environment reserves ports for twenty connectors in total, including HubSpot, Salesforce, Snowflake and Google Ads.
Does omni need Elasticsearch or a separate vector database?
No. The architecture section states that Postgres through ParadeDB is the core data layer for BM25 full-text search, pgvector semantic search and application data, with no Elasticsearch and no dedicated vector database. The example environment does still configure Redis at redis://redis:6379 and gives it a CPU allowance of 0.2 cores, so a second stateful service remains part of the deployment.
How does omni isolate the code its agent runs?
The agent runtime can execute code in a sandboxed container on an isolated Docker network with no access to internal services or the internet. That container uses Landlock filesystem restrictions, resource limits and a read-only root filesystem, and it is assigned its own port, 8090, separate from the 4001 to 4020 block reserved for connectors.
Which AI models can omni use?
Anthropic, OpenAI, Gemini, AWS Bedrock, Vertex AI, Azure AI Foundry, or any OpenAI-compatible endpoint, with vLLM, Ollama, LM Studio and LiteLLM given as examples. A fully local path is also reserved in the example environment, with ports for llama.cpp on 8000, TEI for embeddings on 8001 and Docling for document conversion on 8003.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/getomnico-omni)Star history chart for your README
[](https://hysenlabs.com/projects/getomnico-omni)Was this useful?