ClusterFuzz: Google's Fuzzing Infrastructure, Deployed by You
Scalable fuzzing infrastructure.
At a glance
- What is it?
- ClusterFuzz is the Apache-2.0 fuzzing backend Google runs for its own products and for OSS-Fuzz. The README documents the feature set and points elsewhere for setup, so the real question is what you inherit when you deploy it.
- Who is it for?
- Adopt ClusterFuzz if you already run fuzz targets and need deduplication, bisection and automatic bug filing at a scale no single CI job can reach. Do not adopt it if one libFuzzer binary in a nightly CI job is enough, or if you cannot operate a cluster and a Firebase-backed web interface.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
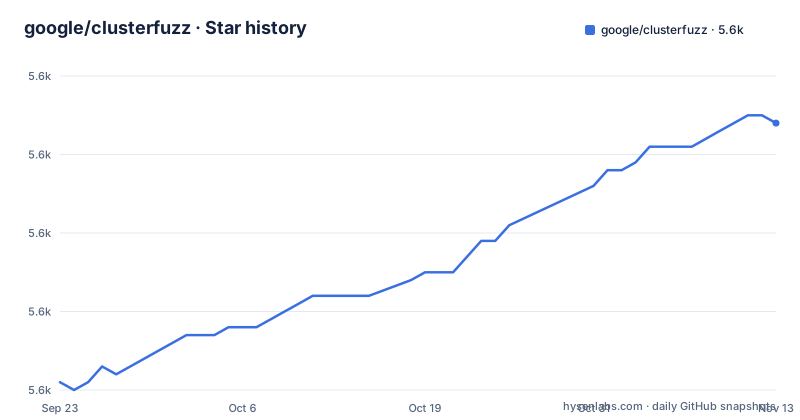
- google/clusterfuzz5,634 ★ · +33
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| google/clusterfuzz | 5.6k | 5.6k |
33 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What ClusterFuzz actually replaces
Running a fuzzer is easy. Running one for months is not. The hard parts are deduplicating the same crash reported thousands of times, minimizing a testcase until it is small enough to debug, and finding the commit that introduced the bug. ClusterFuzz exists to absorb that work. The README describes it as "a scalable fuzzing infrastructure that finds security and stability issues in software," and lists the jobs it takes over: accurate deduplication of crashes, fully automatic bug filing, triage and closing for issue trackers such as Monorail and Jira, testcase minimization, and regression finding through bisection. The audience is a team that already has fuzz targets and wants the surrounding machinery, not a team that has never written a harness. ClusterFuzz fuzzes the target you give it; it does not write the target for you.
Engines, deduplication and the bot fleet
ClusterFuzz is not a fuzzer. It is the layer above several. The README lists support for libFuzzer, AFL, AFL++ and Honggfuzz, with ensemble fuzzing and fuzzing strategies on top, plus blackbox fuzzing for targets without coverage instrumentation. That distinction matters when you plan capacity: the fuzzing engines do the mutation, and ClusterFuzz decides where jobs run, collects crashes, and groups them. Deduplication is the feature that changes daily life. A single parser bug can produce thousands of crashing inputs, and without grouping, the issue tracker fills with duplicates until people stop reading it. The repository layout reflects the split between control plane and workers: src/ holds the application code, bot/ holds the bot side that runs on fuzzing machines, and infra/, configs/ and deploy/ hold the deployment material. The README states ClusterFuzz can run on any size cluster and that the OSS-Fuzz instance runs on 100,000 VMs. That is a statement about the upper bound, not a requirement. A small deployment uses far fewer.
Installing ClusterFuzz: what the README gives you and what it does not
The README does not contain setup steps. It points to detailed documentation at google.github.io/clusterfuzz, and the repository ships deploy/, configs/ and docker/ directories that the documentation covers. Treat the README as a feature list and the documentation site as the installation guide. The repository's top level also includes butler.py, Pipfile and Pipfile.lock, and a .devcontainer/ directory. Once a deployment is running, the README describes the interface you actually use day to day as "a web interface for management and viewing crashes," with authentication handled through Firebase. Expect to configure an authentication provider before anyone can log in.
Where ClusterFuzz is the wrong tool
The README itself answers this one, by pointing elsewhere: "For a more lightweight version of ClusterFuzz that runs on CI/CD systems, check out ClusterFuzzLite." That is a direct signal that full ClusterFuzz is more than most projects need. The costs are structural. A cluster of bots, a web interface, Firebase authentication, and an issue-tracker integration are all components you now operate. The automatic bug filing is only valuable if your team works out of Monorail or Jira and wants machine-filed issues there; if your workflow is a pull request comment, the integration is overhead. Deduplication and bisection pay off when crash volume is high enough that manual triage breaks down. For a project with one fuzz target and a handful of crashes a week, ClusterFuzz is a second system to keep alive. The README does not document a rollback path for a deployment, and it does not describe a single-node mode, so plan for the operational surface before you start.
ClusterFuzz compared with ClusterFuzzLite and OSS-Fuzz
The three names get confused, and the README separates them. ClusterFuzz is the infrastructure you deploy and run yourself. ClusterFuzzLite is the lightweight variant that runs on CI/CD systems, which means the compute is your existing CI rather than a bot fleet you provision. OSS-Fuzz is not a product you install: it is a service Google runs, and the README states ClusterFuzz serves as its fuzzing backend. The practical difference is who owns the machines and the uptime. With ClusterFuzzLite, a fuzzing run ends when the CI job ends. With ClusterFuzz, bots persist, corpora accumulate, and the system keeps fuzzing between commits, which is what makes long-running campaigns and reliable bisection possible. If your goal is to catch regressions on each pull request, ClusterFuzzLite matches that shape. If your goal is continuous fuzzing of a codebase over months, full ClusterFuzz is the one designed for it.
Licence, maintenance and upgrade cost
ClusterFuzz is licensed under Apache-2.0, which permits commercial use, modification and redistribution, and includes an explicit patent grant. It also carries the usual obligations: keep the licence and notices, and state significant changes. That is a summary of the licence text, not legal advice; read LICENSE in the repository for the terms that bind you. On maintenance, the repository is not archived and the last push was on 2026-10-31, with releases v2.46.1, v2.46.2 and v2.46.3 published between 2026-10-23 and 2026-10-28. That cadence is the upgrade cost you should budget for. This is a large Python application with an infrastructure footprint, so a version bump can touch the bot code, the web application and the deployment configuration together. The README points to the clusterfuzz-announce Google Group for announcements, which is where release-level changes are communicated. Pin a release, read the changelog, and upgrade deliberately rather than tracking master.
Editorial conclusion
Adopt ClusterFuzz if you already run fuzz targets and need deduplication, bisection and automatic bug filing at a scale no single CI job can reach. Do not adopt it if one libFuzzer binary in a nightly CI job is enough, or if you cannot operate a cluster and a Firebase-backed web interface. Before committing, read the setup pages at google.github.io/clusterfuzz and confirm which Google Cloud services the deployment expects, because the README names none of them.
Frequently asked questions
What is ClusterFuzz used for?
It is a scalable fuzzing infrastructure that finds security and stability issues in software, and it handles the work around fuzzing: crash deduplication, testcase minimization, regression bisection, and automatic bug filing and triage in issue trackers such as Monorail and Jira.
How do I install ClusterFuzz?
The README does not include installation steps. It points to the detailed documentation at google.github.io/clusterfuzz, and the repository ships deploy/, configs/ and docker/ directories that the documentation covers.
Which fuzzing engines does ClusterFuzz support?
The README lists libFuzzer, AFL, AFL++ and Honggfuzz as coverage guided fuzzing engines, with ensemble fuzzing and fuzzing strategies on top, plus support for blackbox fuzzing.
What is the difference between ClusterFuzz and ClusterFuzzLite?
The README describes ClusterFuzzLite as a more lightweight version of ClusterFuzz that runs on CI/CD systems, while full ClusterFuzz is the scalable infrastructure Google uses for its own products and as the fuzzing backend for OSS-Fuzz.
What license is ClusterFuzz released under?
It is licensed under Apache-2.0, which permits commercial use, modification and redistribution with the usual notice and change-statement obligations. The LICENSE file in the repository holds the binding terms.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 1 in the last 30 days; newest first.
- State of AI Instruction Quality: Coding Agent Comparisondev.to · Oct 21, 2026 · 6 points · 0 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-clusterfuzz)Star history chart for your README
[](https://hysenlabs.com/projects/google-clusterfuzz)Was this useful?