Magika: Google's Deep Learning File Type Detector, Reviewed for Adoption
Fast and accurate AI powered file content types detection
At a glance
- What is it?
- Magika replaces magic-byte sniffing with a small neural network that classifies files by content, not by name. It is fast and well documented, but it returns confidence-scored labels rather than a guaranteed MIME type, and that distinction decides whether it fits your pipeline.
- Who is it for?
- Adopt Magika if you route untrusted uploads to scanners and can act on a confidence score, and if you want a Rust CLI or a Python API rather than a C library. Magika can emit MIME types with `--mime-type`, but threshold fallbacks and output formatting may differ from `file --mime-type`; test downstream compatibility on your own corpus.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
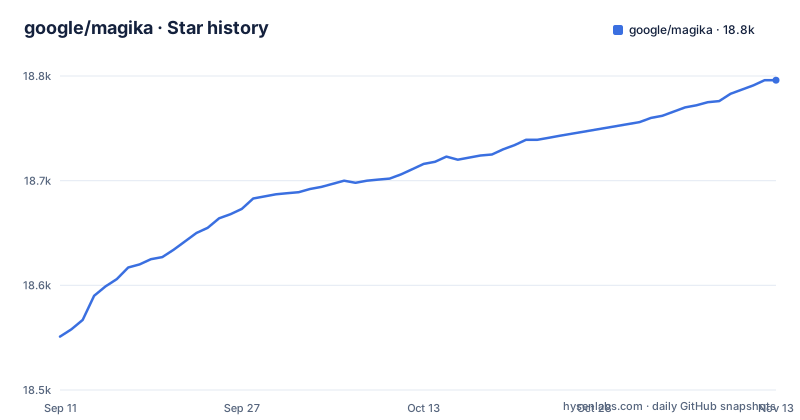
- google/magika18,796 ★ · +245
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| google/magika | 18.6k | 18.8k |
245 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Magika targets: extensions lie, magic bytes are shallow
File type detection usually rests on two weak signals. The filename extension is user-controlled and trivially wrong. Magic bytes are a short prefix match, and they break down on formats that share headers, on text formats that have no signature at all, and on files that have been truncated or padded. The README frames Magika as an answer to that gap: a detector that reads a limited subset of the file's content and classifies it with a trained model rather than a signature table.
The audience is narrow and specific. The README states Magika is used inside Google to route Gmail, Drive, and Safe Browsing files to the appropriate security and content policy scanners, and that it is integrated with VirusTotal and abuse.ch. That is the shape of the intended user: a system that receives files it did not create, must decide what each one is before handing it to a parser or a sandbox, and cannot trust the client's declared type. If you are building an upload endpoint, a malware triage queue, or a document ingestion pipeline, the problem statement matches yours. If you only need to pick an icon for a file browser, the model is more machinery than the job requires.
How the model classifies a file and why you get a score back
Magika ships a custom model that the README describes as weighing about a few MBs. It was trained and evaluated on roughly 100M samples spanning 200+ content types, covering both binary and textual formats, and the README reports about 99% average precision and recall on the project's own test set. Those numbers come from the project and its test distribution; they are not a measurement of your files.
The mechanism that matters for integration is the threshold system. Magika does not simply emit the top-scoring class. It applies a per-content-type threshold that decides whether the prediction is trustworthy enough to report, or whether the result should be downgraded to a generic label such as "Generic text document" or "Unknown binary data". The JSON output exposes this: `dl` (the raw deep learning output) and `output` (the value after thresholds are applied). In the README's JSON example for a Python source file, `dl` and `output` carry the same description, extensions and group.
That split between `dl` and `output` is the part worth designing around. A caller that reads `output` gets the conservative answer. A caller that reads `dl` gets the model's raw opinion and takes on the job of deciding what to do with a low score. The README also notes that inference is near-constant regardless of file size, because only a limited subset of the content is used, and that once the model is loaded, inference is about 5ms per file on a single CPU. The model load is described as a one-off overhead, which matters if you plan to invoke the CLI per file rather than keep a process or API object alive.
Installing the CLI, the Python package, and the JavaScript binding
The README lists several installation paths for the Rust CLI. Through the Python package manager: `pipx install magika`. Through Homebrew on macOS and Linux: `brew install magika`. Through the installer script: `curl -LsSf https://securityresearch.google/magika/install.sh | sh`, or on Windows `powershell -ExecutionPolicy Bypass -c "irm https://securityresearch.google/magika/install.ps1 | iex"`. Through Cargo: `cargo install --locked magika-cli`.
The Python API is a separate install, `pip install magika`, and the JavaScript package is `npm install magika`. The README labels the npm package as experimental and notes it powers the browser demo. The Go bindings are marked WIP. If your stack is Python or Rust, you are on the well-trodden path. If it is Go, you are on a path the README itself describes as incomplete.
Basic invocation is a single command. `magika -r *` walks a directory recursively; the README's sample output pairs each path with a human-readable label and group, for example `docx/doc.docx: Microsoft Word 2007+ document (document)` and `empty/empty_file: Empty file (inode)`. For machine consumption, `magika ./tests_data/basic/python/code.py --json` returns an array of objects, each with `path` and a `result` containing `status` and `value`. The `value` object carries `dl` and `output`. Parse `result.status` before you parse the label: the README's example shows `"status": "ok"`, which implies other statuses exist.
Prediction modes are the knob that decides your false-positive rate
The README states that tolerance to errors is controlled through prediction modes: `high-confidence`, `medium-confidence`, and `best-guess`. This is the single most consequential configuration decision. What can be said is the direction of the trade. A stricter mode pushes more files into the generic buckets, so downstream code that switches on a specific label will see more "Generic text document" and "Unknown binary data" results. A looser mode produces more specific labels and accepts more mistakes.
Because the thresholds are per content type, the error profile is not uniform. A format with a distinctive header may be reported confidently at a strict setting while a plain-text format that overlaps with several siblings gets downgraded. If you are evaluating Magika, the useful exercise is to run your own sample set through each mode and count how often `output` diverges from the label you expected, rather than trusting the aggregate accuracy figure. The README's accuracy claim is an average across 200+ types; averages hide the per-type behavior that will actually break your pipeline.
The `is_text` flag in the JSON output is easy to overlook and useful. For a pipeline that must decide whether to hand a file to a text parser or a binary analyzer, it gives a coarse routing signal that survives even when the specific label is downgraded to a generic bucket.
Where Magika is the wrong tool
Magika is not a security scanner and the README does not present it as one. It answers what a file appears to be, not whether it is malicious. A file that is correctly identified as a PDF can still be a malicious PDF. If your requirement is detection of harmful content, Magika belongs upstream of the scanner as a router, which is exactly how the README describes its use at Google.
It is also a poor fit where you need deterministic, reproducible classification tied to a specification. A signature-based tool and a neural classifier will disagree, and when they do, Magika's answer is a probability, not a standard. If your downstream parser keys off an exact MIME string, the generic-label fallback is a real failure mode: the file is not misclassified so much as deliberately abstained on, and your code must handle that branch. Teams that treat the label as guaranteed will see intermittent failures on exactly the ambiguous text formats where Magika is supposed to be strongest.
There is a resource dimension too. The README notes the model load is a one-off overhead. A workflow that shells out to the CLI once per file pays that cost every time, which undercuts the 5ms inference figure. The README notes you can invoke Magika with thousands of files at once, or to use `-r` for a directory. Batching is not an optimization here; it is the intended usage pattern.
Magika versus libmagic: signatures against a trained classifier
The obvious alternative is libmagic, the C library behind the `file` command, which matches byte patterns and rules against a database. The difference in approach is fundamental. libmagic encodes human-written rules per format; Magika learns a decision boundary from roughly 100M examples. libmagic is deterministic and inspectable, and you can read the rule that produced a result. Magika gives you a score and a threshold policy you cannot audit rule by rule.
The README claims Magika outperforms existing approaches, particularly on textual content types. That claim is plausible on its face, because text formats have no reliable magic bytes for libmagic to match, and it is consistent with Magika's design of reading content rather than a prefix. Treat the margin against libmagic as unverified.
The practical split is this: libmagic is the right choice when you need a stable, spec-anchored answer and your formats have signatures. Magika is the right choice when your inputs are text-heavy, adversarial, or renamed, and when your pipeline can consume a confidence score. Running both and treating disagreement as a signal is a reasonable use of a classifier that exposes its raw `dl` output next to its thresholded `output`.
Licence, maintenance, and upgrade surface
Magika is Apache-2.0. That is a permissive licence with an explicit patent grant, and it imposes no copyleft obligation on your own code. It does require that you preserve the licence and attribution notices for the parts you redistribute. This is a description of the licence text, not legal advice; if you are embedding the model or the CLI in a distributed product, have counsel review the NOTICE requirements.
The repository is not archived and shows a recent push. The release list shows three channels moving at different speeds: `cli/v1.1.0` and the `cli-latest` tag in April 2026, and `python-v1.0.2` in February 2026. The CLI and the Python package are versioned separately, so an upgrade to one does not imply a matching upgrade to the other, and a pinned Python version may lag the CLI by months. The README also states that the model is versioned: the content type list is documented under `assets/models/standard_v3_3/`, which means a model revision can change the label set and the per-type thresholds. If you cache labels or persist them in a database, a model upgrade is a data migration, not just a dependency bump.
The bindings carry their own risk. The README calls the npm package experimental and the Go bindings WIP. Depending on either means tracking a surface the project has not declared stable. The Rust CLI and the Python package are the two paths the README presents without that caveat.
Editorial conclusion
Adopt Magika if you route untrusted uploads to scanners and can act on a confidence score, and if you want a Rust CLI or a Python API rather than a C library. Magika can emit MIME types with `--mime-type`, but threshold fallbacks and output formatting may differ from `file --mime-type`; test downstream compatibility on your own corpus. Before committing, verify two things on your own corpus: whether the `high-confidence` prediction mode suppresses too many labels for your file mix, and whether the 200+ supported content types cover the formats you actually receive.
Frequently asked questions
What does magika mean?
In this repository Magika is an AI powered file type detection tool from Google, written in Rust with a command line interface, a Python API and bindings for other languages. It is trained and evaluated on a dataset of about 100 million samples across more than 200 content types, and it is used to route files in Gmail, Drive and Safe Browsing to the appropriate security and content policy scanners.
Can Magika output MIME types?
Yes. Use `magika --mime-type` to print MIME types, or `--json` to include the MIME type in structured output.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-magika)Star history chart for your README
[](https://hysenlabs.com/projects/google-magika)Was this useful?