google/wuffs: a memory-safe language for parsing untrusted file formats
Wrangling Untrusted File Formats Safely
At a glance
- What is it?
- Wuffs is a C-family language and standard library for writing decoders that are safe against buffer overflows, integer overflows and null dereferences at compile time. It suits engineers who need C-speed parsing of untrusted bytes, and it is a poor fit for anything that needs I/O or general application logic.
- Who is it for?
- Adopt google/wuffs when you need a parser for untrusted image, audio, video, font or archive bytes and you want compile-time safety proofs rather than runtime checks. Do not adopt it as a general purpose language or for anything that performs I/O; Wuffs code is hermetic and makes no syscalls, so the caller owns all reading and writing.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 12 days ago.
- What is it written in?
- Mainly C, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
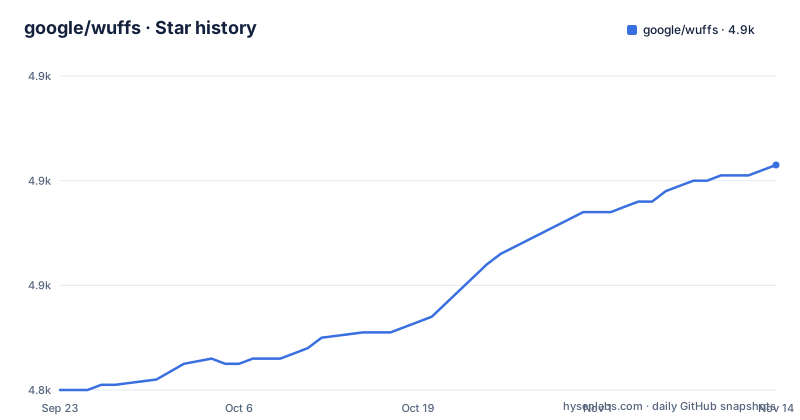
Star history
- google/wuffs4,882 ★ · +42
| Repository | 2026-09-23 | 2026-11-13 |
|---|---|---|
| google/wuffs | 4.8k | 4.9k |
42 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem google/wuffs targets: parsing hostile bytes in C
Every application that opens a user-supplied image, font, audio file or compressed archive is running a parser over bytes it did not produce. In C and C++ those parsers are where buffer overflows, integer wraparound and null dereferences live, and the usual remedy is fuzzing plus a long tail of patched CVEs. Wuffs takes a different route: it is a language for writing those parsers, and the compiler refuses to emit C unless it can prove the three bug classes above cannot occur. The README states the goal plainly, libraries that are "as safe as Go or Rust, roughly speaking, but as fast as C", usable anywhere a C library is used, including web browsers and operating systems.
The audience is narrow on purpose. This is not a language for applications. The README says Wuffs is "for writing libraries, not programs", and that the sensible scope is "only the parts that are both performance-conscious and security-conscious". If you are writing a CLI tool, a service, or anything that opens a socket, Wuffs is the wrong layer.
How the compile-time proofs work in Wuffs the Language
The mechanism is annotation plus a solver, not a runtime guard. A statement like `x += 1` is a compile error unless the compiler can prove `x` is not already at the maximum of its type, so `x` cannot be `255` when `x` is a `base.u8`. Division is the same shape: `x / y` fails to compile unless `y` is provably non-zero. The README's worked example is a one-line edit to the LZW decoder in `std/lzw/decode_lzw.wuffs`, changing `this.suffixes[save_code] = c as u8` to `(c + 1) as u8`. Running `wuffs gen std/gif` then fails with a bounds message: the expression's bounds are `[1 ..= 256]`, outside the target range `[0 ..= 255]`, and the compiler prints the facts it used to reach that conclusion, including `n_bits < 8` and `c < 256`.
The instructive part is the second edit in the README. Guarding the same line with `if use_save_code and (c < 200)` compiles cleanly, because the added condition gives the prover what it needs. But `wuffs test std/gif` then fails at runtime: `test_lzw_decode: bufs1_equal: wi: got 19311, want 19200`, with a hex dump showing the first divergence at byte 3. Safety and correctness are separate properties, and Wuffs only proves the first. That is the honest boundary of the design, and it is worth internalising before you trust a green build.
Hermeticity, Sans I/O and why the caller owns every byte
Wuffs code cannot make syscalls. It has no ambient authority to read your files, which means it cannot allocate or free memory either, and the README notes this makes it trivially safe against leaks, use-after-frees and double-frees. The output is described as Sans I/O style libraries, in C rather than Python, agnostic to function colours so they compose with synchronous or asynchronous I/O.
The practical consequence is an inversion of the usual API. A Wuffs decoder receives a destination buffer, a source buffer and a flag such as `src_final`, and returns a status. Your code decides whether the next chunk arrives from a file, a socket or a test fixture. That is a good fit for a browser's image pipeline or a sandboxed thumbnail service, where the buffer comes from an untrusted source and the surrounding process already has an I/O policy. It is a bad fit if you wanted a library that takes a path and returns pixels, because that library does not exist here by design.
Installing google/wuffs and running a first generation
The repository is a Go module, `module github.com/google/wuffs` with `go 1.25.0`, and the command line tool lives under `cmd/`. The README's workflow is to run `wuffs gen` on a standard library target and then `wuffs test` on it, which transpiles the `.wuffs` sources to C and runs the generated tests. A clone is the first step:
git clone https://github.com/google/wuffs.git
cd wuffs
With the wuffs tool available, generate and test the GIF codec. The README shows both commands and the kind of output to expect: `gen wrote:` for a newly written file, `gen unchanged:` when nothing moved, then per-test lines naming the compiler and the result.
wuffs gen std/gif
wuffs test std/gif
If you only want to consume the library, you do not need any of this. The README states that Wuffs the Library is available under `release/c` as transpiled C code, and that other C/C++ projects can use it "without requiring the Wuffs the Language toolchain". Those projects treat it like any other third party C library, with the caveat the README attaches: it is just not hand-written C. The `example/` directory holds the intended integration shapes, including `example/gifplayer/`, `example/imageviewer/`, `example/zcat/` and `example/mzcat/`.
What the benchmarks claim, and what they do not
The README links to `/doc/benchmarks.md` and to blog posts for the numbers, and it quotes the headline figures directly: bzip2 decoding 1.3x faster than `/usr/bin/bzcat`, deflate up to 1.4x faster than zlib-the-library, GIF 2x to 6x faster than giflib, Go's `image/gif` and Rust's `gif`, and PNG 1.2x to 2.7x faster than libpng, Go's `image/png` and Rust's `png`. Those are the project's own measurements. They are not independent results, and the README does not present them as such.
The repository has no published GitHub releases, so there is no versioned artefact to pin against. The repository was last pushed on 2026-11-02 and is not archived, so the code is current, but a consumer pinning to a commit should plan to re-run generation themselves rather than expect a tagged drop.
Where google/wuffs is the wrong tool
The trade-off is stated in the README without softening: Wuffs programs "take longer for a programmer to write, as they have to explicitly annotate their programs with proofs of safety". You are paying authoring time up front to remove a class of runtime bugs. For a format you parse once, in a trusted context, on data you generated, that trade is bad. Fuzzing a conventional C parser, or using a memory-safe language with runtime checks, will get you to working code sooner.
The second limit is scope. Wuffs is not general purpose, and the README says it is unlikely that a Wuffs compiler would be worth writing entirely in Wuffs. If your task involves network access, filesystem layout, threading, configuration or anything else outside byte transformation, that logic lives in the host language. The third limit is the one the GIF test failure demonstrates: a compiling program is memory-safe, not correct. Compile-time proofs say nothing about whether your decoder produces the right pixels, so the test suite under `test/` still has to carry that weight.
How google/wuffs differs from zlib, libpng and Go's image packages
zlib, libpng, giflib and Go's `image/png` are hand-written or conventionally written libraries that perform runtime bounds checks, or in C's case often rely on the caller and the fuzzer to find what slips through. Wuffs inverts that: the checks happen when the Wuffs source is transpiled, and the shipped artefact under `release/c` is C code that already carries the prover's conclusions. The README frames the difference as safety without a runtime tax, which is why the benchmark comparisons are against exactly these libraries.
The second difference is the interface. zlib and libpng present functions that manage their own state and, in libpng's case, can read from a FILE pointer. A Wuffs library is Sans I/O and hermetic, so it never touches a file descriptor and never allocates. That makes it easier to embed in a sandbox and harder to drop into an existing codebase that expects a path-in, pixels-out call. If you want the conventional interface, the `example/` directory shows the adapter code you will write yourself.
Licence and the cost of keeping up
The repository root contains both `LICENSE-APACHE` and `LICENSE-MIT`, and the licence field reported for the project is NOASSERTION, which means no single SPDX identifier was detected automatically. Read both files before you ship generated C, because the terms that apply to the transpiled output under `release/c` are the terms you actually distribute under. This is a description of what is in the repository, not legal advice.
Upgrade cost is unusual here. Because consumers can take `release/c` and never run the toolchain, upgrading is a matter of replacing generated files, exactly as with any vendored C dependency. If you author `.wuffs` sources yourself, upgrades can break at compile time rather than at runtime, which is the point: a stricter prover rejects code that previously passed. Budget for that, and keep your own `.wuffs` edits small enough to re-annotate.
Editorial conclusion
Adopt google/wuffs when you need a parser for untrusted image, audio, video, font or archive bytes and you want compile-time safety proofs rather than runtime checks. Do not adopt it as a general purpose language or for anything that performs I/O; Wuffs code is hermetic and makes no syscalls, so the caller owns all reading and writing. Before committing, verify three things: that the format you need is already covered under std/ or that you are willing to annotate the safety proofs yourself, that your build can consume the transpiled C under release/c without pulling in the Wuffs toolchain, and that the licence files in the repository root (LICENSE, LICENSE-APACHE and LICENSE-MIT) match how you intend to ship the generated code.
Frequently asked questions
What is google/wuffs?
It is a memory-safe programming language, plus a standard library written in that language, for wrangling untrusted file formats safely. Wrangling covers parsing, decoding and encoding of formats such as images, audio, video, fonts and compressed archives. The language transpiles to C, and the resulting library can be used without the Wuffs toolchain.
Does google/wuffs need the Wuffs toolchain to be used from C or C++?
No. The README states that Wuffs the Library is available under release/c as transpiled C code, and that other C/C++ projects can use it without requiring the Wuffs the Language toolchain. Those projects treat it like any other third party C library.
Can google/wuffs read a file or allocate memory?
No. Wuffs code is hermetic and cannot make syscalls, so it cannot read your files and cannot allocate or free memory. The README describes the output as Sans I/O libraries, where the caller is responsible for the actual I/O.
If a google/wuffs program compiles, is the decoder correct?
No. Compile-time proofs cover buffer overflows, integer arithmetic overflows and null pointer dereferences. The README shows a two-line edit that compiles successfully but then fails wuffs test std/gif with a buffer mismatch, so correctness still depends on the test suite.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/google-wuffs)Star history chart for your README
[](https://hysenlabs.com/projects/google-wuffs)Was this useful?