Graylog2/graylog2-server: what the SSPL log platform actually gives you
Free and open log management
At a glance
- What is it?
- Graylog is a free, open log management platform written in Java and released under SSPL v1. Its repository splits the server, web interface and storage adapters, and the licence, not the code, is the first thing to check.
- Who is it for?
- Graylog fits teams that need to collect logs and search them centrally, and that accept SSPL v1 terms. It does not fit anyone who needs to offer log management as a hosted service without complying with that licence, and it is the wrong tool if you only need a single-node log tail.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
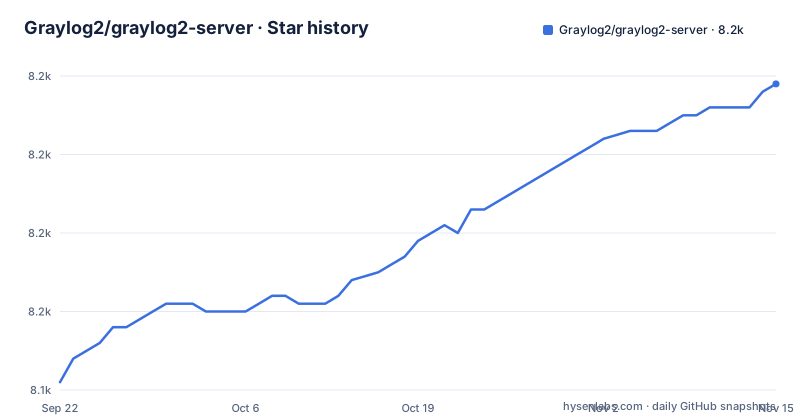
- Graylog2/graylog2-server8,179 ★ · +38
| Repository | 2026-09-22 | 2026-11-15 |
|---|---|---|
| Graylog2/graylog2-server | 8.1k | 8.2k |
38 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Graylog2/graylog2-server is for, and who should care
Graylog is a central place to send logs and search them. The README describes it as a "free and open log management platform".
The people who get value from this repository are the ones running more than a handful of machines. If you have a fleet producing syslog and you need a shared search box for incidents, Graylog is built for exactly that. If you have one server and read its logs with tail, this is a large amount of infrastructure for a problem you do not have.
The README also points to the project website and documentation site for the actual product description. That is a deliberate split: the repository is the source tree, not the manual. Expect to leave the README quickly and read the documentation site for anything operational.
How the repository is laid out and where logs flow
The top-level entries show a multi-module Maven build. graylog2-server holds the Java server, graylog2-web-interface holds the browser UI, and graylog-storage-elasticsearch7, graylog-storage-opensearch2 and graylog-storage-opensearch3 are separate storage adapters. That separation is the clearest architectural statement in the tree: the search backend is pluggable, and each supported backend gets its own module rather than a version check buried in shared code.
data-node/ appears alongside the server. The name, and its position next to the storage modules, indicates that part of the data path runs in a separate process from the main server. The README does not describe this component, so treat the layout as a hint about deployment topology rather than a specification.
api-specs/ and distribution/ also sit at the top level.
One design consequence is worth stating plainly: because storage is split into backend-specific modules, the Elasticsearch or OpenSearch version you run is a first-class deployment decision, not an implementation detail you can ignore.
Installing Graylog from the graylog2-server repository
The README does not give installation steps. It links to the website and the documentation site, and those are where the project says to get the product. What the repository does give you is the build tooling: a pom.xml at the root and a Maven wrapper, mvnw, checked in at the top level. The wrapper is the intended entry point for building from source, because it pins the Maven version instead of relying on whatever is installed on your machine.
The wrapper is the only build entry point visible in the tree, and the repository does not document any flags or subcommands for it. Because the README offers no worked example, there is no command here to copy. Follow the documentation site for the install itself, and treat the repository as the place you go once you have decided to build from source.
The tree also contains distribution/ and docs/ directories.
If you are evaluating rather than building, the honest path is: read the documentation site first, decide which storage backend you will run, and only then come back to this repository to build or to read the module you care about.
The SSPL licence is the real adoption constraint
The README's licence section states that Graylog is released under version 1 of the Server Side Public License, and the licence badge in the README links to the SSPL text. The repository metadata reports the licence as NOASSERTION, which is a machine-readable classification failure rather than a contradiction: the README is unambiguous about SSPL v1, and the automated detector simply does not recognise that licence string.
SSPL is the part of this project that most often decides an evaluation. It is a source-available licence with obligations that go beyond a permissive licence, and the practical question for a company is whether the way it operates Graylog triggers those obligations. That is a question for your own legal review, not for a review of the code.
There is a second licence signal in the README. The licence badge image URL points at MongoDB's server-side public licence page, which is a reminder that SSPL originated outside this project. Nothing in the repository changes the terms; the LICENSE file at the top level is the authoritative copy.
If your organisation has a blanket ban on SSPL dependencies, the rest of this article is moot. Check that first, before you spend time on storage backends.
What the repository does not tell you
The README is short and does not document rollback, backup, sizing or failure recovery. UPGRADING.md exists at the top level, which means upgrades are treated as a documented concern, but the README itself says nothing about how to reverse one. If you need a downgrade path, the README is silent.
The repository has no published GitHub releases, so there is no version cadence to reason about. The changelog directory exists in the tree, so change history is kept in the repository rather than only in release notes, but you should read it directly rather than trusting a summary.
The last push to the default branch was on 2026-11-02. That is a fact about repository activity, not a statement about support, and it says nothing about whether a given version is maintained.
Finally, the README's community links are stale in one visible way: it points at a #graylog channel on freenode IRC alongside one on libera. That is a small thing, but it is a signal that the README is not the document being carefully maintained. Read it for orientation, then go to the docs.
Graylog against a plain Elasticsearch or OpenSearch setup
The closest alternative is running Elasticsearch or OpenSearch directly and putting a dashboard tool in front of it. The difference in approach is where the log-specific work happens. With a raw search cluster, you own the ingest pipeline, the field mapping, the parsing of syslog and GELF, and the retention rules. Graylog ships storage adapters for Elasticsearch 7, OpenSearch 2 and OpenSearch 3, so the search engine is a component rather than the product.
The repository structure reflects this: graylog-storage-elasticsearch7 and the two OpenSearch modules exist so that the server can talk to whichever backend you standardised on.
If your team already operates an Elasticsearch cluster and has strong opinions about index templates, adding Graylog on top means accepting its model. If your team has no search cluster and wants logs searchable this week, Graylog removes a category of work. The decision is about who owns parsing and retention, not about which search engine is faster.
Editorial conclusion
Graylog fits teams that need to collect logs and search them centrally, and that accept SSPL v1 terms. It does not fit anyone who needs to offer log management as a hosted service without complying with that licence, and it is the wrong tool if you only need a single-node log tail. Verify first which storage backend matches your version, since the repository ships separate modules for Elasticsearch 7, OpenSearch 2 and OpenSearch 3, and read UPGRADING.md before any version jump.
Frequently asked questions
Is Graylog free or paid?
The README describes Graylog as a free and open log management platform and states that it is released under version 1 of the Server Side Public License. The repository does not describe paid tiers or pricing.
Can Graylog be used as a Syslog server?
The README does not mention syslog; it describes Graylog as a free and open log management platform and points to the documentation site for details.
What is Graylog used for?
It is a central log management platform: logs are sent to it and queried through the web interface. The repository separates the server, the web interface and the storage adapters that connect to Elasticsearch or OpenSearch.
Is Graylog still open-source?
The source is published in this repository under SSPL v1, which the README states explicitly. SSPL is a source-available licence with obligations beyond permissive licences, so whether it counts as open source for your purposes is a licensing question rather than a code question.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/graylog2-graylog2-server)Star history chart for your README
[](https://hysenlabs.com/projects/graylog2-graylog2-server)Was this useful?