Obscura: a Rust headless browser that speaks CDP without Chromium
The headless browser for AI agents and web scraping
At a glance
- What is it?
- Obscura is an Apache-2.0 headless browser engine written in Rust, positioned as a drop-in replacement for headless Chrome under Puppeteer and Playwright. The README claims a much smaller footprint and built-in anti-detect behaviour, but the numbers in its comparison table are the author's own and the project is still pre-1.0.
- Who is it for?
- Obscura is worth a look if you already drive a browser through the Chrome DevTools Protocol and the cost of shipping a Chromium runtime is the thing that hurts, for example in a container per scrape or one browser per agent. It is the wrong tool if you need a browser whose rendering you can trust against arbitrary production sites, or if you depend on Chrome-only behaviour, because the project is pre-1.0.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
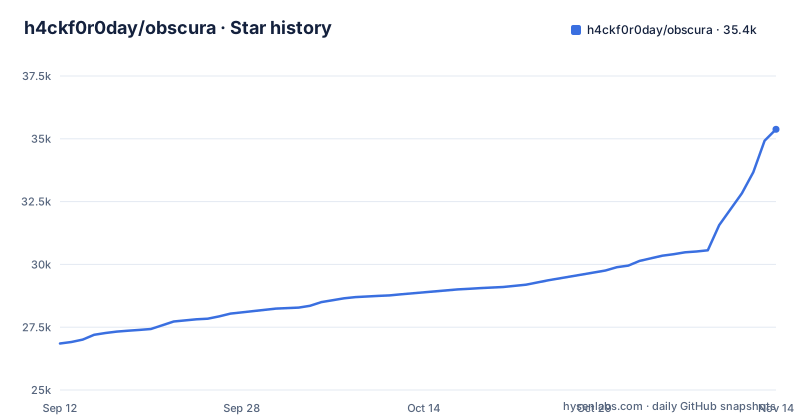
Star history
- h4ckf0r0day/obscura35,378 ★ · +8,528
| Repository | 2026-09-12 | 2026-11-14 |
|---|---|---|
| h4ckf0r0day/obscura | 26.9k | 35.4k |
8,528 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The cost of shipping Chromium for every scrape
The problem Obscura targets is not scraping itself, it is the runtime you have to carry to scrape a page that needs JavaScript. The README's comparison table puts headless Chrome at 200+ MB of memory and a 300+ MB binary, against 30 MB and 70 MB for Obscura. Those are the project's own figures and nothing in the README says how they were measured, so treat them as a claim rather than a benchmark. The direction is still plausible: a full Chromium build bundles a rendering engine, a media stack, a GPU abstraction layer and a lot of code that a scraper never touches. Obscura's pitch is that you can drop the parts you do not need and keep the parts you do, specifically V8 for JavaScript execution and the Chrome DevTools Protocol for control.
The intended audience is narrow and clearly stated. The README names web scraping and AI agent automation. That is a developer who already has working automation scripts and wants them to run somewhere cheaper, not someone looking for a general purpose browser to embed in a desktop application. If your scripts are written against Playwright's own API rather than the CDP layer underneath it, the drop-in claim is the part you need to check first. The README asserts compatibility with both Puppeteer and Playwright, so test the specific calls your scripts make.
V8 plus CDP, with the rendering engine swapped out
The architecture described in the README is a browser engine in Rust that runs real JavaScript through V8 and exposes the Chrome DevTools Protocol. That combination is what makes the drop-in claim possible. Puppeteer and Playwright both ultimately talk CDP to a Chromium instance, so an engine that implements the same protocol on the same port can in principle be driven by the same client code. Obscura also states it handles screenshots, screencasts and PDF export natively, which the README frames as the arrival of native rendering with no Chromium required.
The interesting part is what is not in the description. For a project whose value proposition is substitution, the compatibility surface is the whole product. The anti-detect layer is a stealth transport that ships only in the -stealth archives and stealth builds, which use wreq/BoringSSL instead of rustls. Anti-detect behaviour changes what a site sees, and whether that is appropriate depends entirely on what you are doing and where. A scraping team pulling public data has a different answer than someone automating a login flow.
The README also links a Cloudflare engineering blog post stating that Cloudflare ported Obscura to Workers while developing its own agent-first browser, described there as Kitesurf's first prototype. That is a third-party signal about the codebase being legible enough to port, not evidence about how Obscura performs in production.
Getting it running: what the README actually gives you
The README gives several install paths. Release archives for Linux x86_64, Linux ARM64 and macOS Apple Silicon are fetched with curl and unpacked with tar, NixOS users can run nix-env -iA nixpkgs.obscura, and a Docker image runs with port 9222 published to host loopback and an OBSCURA_CDP_TOKEN environment variable. Building from source uses cargo build --release -p obscura-cli --bins with render or stealth features, requires Rust 1.75+, and the first build takes about 5 minutes because V8 compiles from source.
What the README does establish is the integration surface: Puppeteer and Playwright, both checked as supported in the comparison table. In practice that means pointing an existing client at Obscura's CDP endpoint instead of launching Chrome, which is the same shape as connecting to a remote browser over a websocket. The Docker example publishes the CDP endpoint on 127.0.0.1:9222, and the README warns that -p 9222:9222 exposes the port on every interface.
The releases give a sense of cadence: v0.2.4 on 2026-10-04, v0.2.5 on 2026-10-17, v0.2.6 on 2026-10-31, with the last push to main on 2026-11-02. Three releases in about a month at the 0.2 line is a project moving quickly, which cuts both ways. Fixes arrive fast. So do breaking changes, and there is no 1.0 to anchor an upgrade policy to.
Where a from-scratch engine will break first
The obvious failure mode is rendering fidelity. A browser engine that is not Chromium will not render every page the way Chromium does, and the pages that break are usually the ones doing something unusual: heavy CSS, canvas work, WebGL, complex layout, or JavaScript that sniffs the user agent and branches. The README does not claim full Chrome parity, and the comparison table's checkmarks are about Puppeteer and Playwright support, not about rendering equivalence. If your pipeline scrapes a handful of well-understood sites, you can test those sites and know your answer. If it scrapes the open web, you are signing up to discover the gaps one site at a time.
The second failure mode is subtler. Anti-detect behaviour that is built in is hard to reason about when something goes wrong. If a request is rejected, you cannot easily tell whether it was the fingerprint modification, a missing browser feature the site detected, or ordinary rate limiting. With headless Chrome you at least know what you are sending, because you configured it. Here the defaults are the project's, though the README says the default archive renders without the stealth transport, which ships only in the -stealth builds.
The third is maturity. At v0.2.x with releases weeks apart, the API and the protocol coverage are both moving. A dependency you pin today may need attention sooner than you would like. That is a cost, not a disqualification, but it belongs in the decision.
Against headless Chrome, and against staying put
The real alternative is the thing Obscura is replacing: headless Chrome or Chromium, driven by the same Puppeteer or Playwright client. The difference is not in the API you write against, it is in what runs underneath. Chrome gives you the reference implementation of the rendering engine, complete CDP coverage by definition, and a decade of production hardening. You pay for that in image size and memory, and you get a browser whose behaviour on any given page is the behaviour the page was tested against. Obscura trades that certainty for a smaller runtime and a faster start, which the README puts at 85 ms page load and instant startup against roughly 500 ms and about 2 s for Chrome. Again, those are the project's numbers.
There is a second alternative worth naming, which is not replacing the browser at all but replacing the browser automation: fetching the page and parsing it without executing JavaScript. That works until it does not, and the moment a target site renders its content client-side it stops working. Obscura exists precisely because that moment is common now, so it is not really a substitute for this project. It is a reminder that the cheapest browser is the one you do not launch.
The choice between Obscura and Chrome comes down to whether your bottleneck is the runtime or the rendering. If you are running thousands of short-lived browser sessions and the image size is what limits your density, the trade is worth investigating. If a single failed page costs you more than the memory you saved, it is not.
Licence, hosting and the upgrade path
Obscura is Apache-2.0, which permits commercial use, modification and redistribution, and includes a patent grant. The README states plainly that the open-source engine stays Apache-2.0 and fully featured, with no feature gating, and that Obscura Cloud is a hosted version still being worked on, with a waitlist, managed infrastructure, residential proxies and support. That is a clean split on paper. It is also a promise about the future made by the same people who control the roadmap, so the thing to watch over time is whether new capabilities land in the engine or only in the hosted product. Nothing in the README suggests gating is happening, and the README is explicit that it will not. I am not giving legal advice here; if you are embedding this in a product, read the licence text and your own obligations.
The maintenance cost is the pre-1.0 cadence. Three releases in a month means you should expect to track the project rather than pin it and forget it, and you should have a way to test your own scripts against a new version before it reaches production. Read the release notes before each upgrade to see what changed in the defaults. If your environment builds from source, the Rust toolchain becomes part of your build pipeline's maintenance burden as well.
Who should try it, and what to check first
Adopt Obscura if you already speak CDP, your scripts are Puppeteer or Playwright based, and the runtime cost of Chromium is a real constraint in your deployment. The clearest case is a container per scrape job or one browser per agent, where 30 MB against 200+ MB changes how many you can run on the same machine. The Cloudflare port suggests the codebase is structured well enough for someone else to build on, which is a better signal than a feature list.
Do not adopt it if your scraping targets are arbitrary and you cannot afford silent rendering differences, if you rely on Chrome-specific behaviour. At v0.2.x, this is a project you pilot against your own targets, not one you put behind a customer-facing pipeline without a fallback to Chromium.
What to verify before you commit: run your existing Puppeteer or Playwright scripts against Obscura's CDP endpoint unmodified and count how many pass. Read the README's install section and the documentation at docs.obscura.sh for the install path and configuration. Then read the anti-detect code or its documentation to find out what it changes, and decide whether that is something you want sent on your behalf. Until those three answers are in hand, the README's comparison table is a hypothesis, not a result.
Editorial conclusion
Obscura is worth a look if you already drive a browser through the Chrome DevTools Protocol and the cost of shipping a Chromium runtime is the thing that hurts, for example in a container per scrape or one browser per agent. It is the wrong tool if you need a browser whose rendering you can trust against arbitrary production sites, or if you depend on Chrome-only behaviour, because the project is pre-1.0. Before adopting, verify three things yourself: that your existing Puppeteer or Playwright scripts run unmodified against the CDP endpoint, what the anti-detect layer actually changes and whether that is acceptable for your use case, and how the binary is built and updated in your environment.
Frequently asked questions
how to install obscura browser
Grab a release archive and unpack it: the README gives curl and tar lines for Linux x86_64, Linux ARM64 and macOS Apple Silicon, plus nix-env -iA nixpkgs.obscura for NixOS. A Docker image is published too, and no Chrome, Node.js or other dependency is needed. Linux builds target Ubuntu 22.04 so the binary stays usable on LTS servers with glibc 2.35 or newer.
how to use obscura browser
The README's first command is ./obscura fetch https://example.com --eval "document.title", which fetches a page and evaluates an expression against it. Release archives include both obscura and obscura-worker, and the two must stay in the same directory for the parallel scrape command. Because the engine speaks the Chrome DevTools Protocol, it is presented as a drop-in replacement for headless Chrome under Puppeteer and Playwright.
Does Obscura need Chrome or Node.js installed?
No. The README states no Chrome, no Node.js and no dependencies, and explains that the renderer is native: real JavaScript runs through V8, and screenshots, live page screencasts and PDF export are produced without Chromium. The layout and rasterization stack is pure Rust, with taffy, tiny-skia and ab_glyph behind the render layer.
What is the difference between the Obscura release archives?
The suffix selects two independent capabilities. An archive with no suffix has rendering and no stealth transport, -stealth has both, -no-render has neither, and -no-render-stealth leaves out the renderer while keeping the stealth transport. So the default build renders natively but does not alter its network path.
Is Obscura a drop-in replacement for Puppeteer and Playwright?
That is the claim the README makes, on the basis of Chrome DevTools Protocol support, and its comparison table lists Puppeteer and Playwright support for Obscura and for headless Chrome alike. The table's memory, binary size, page load and startup figures come without any stated methodology, so they are claims to measure yourself rather than published benchmarks.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/h4ckf0r0day-obscura)Star history chart for your README
[](https://hysenlabs.com/projects/h4ckf0r0day-obscura)Was this useful?