Headroom: A Local-First Context Compression Layer for AI Agents
Compress tool outputs, logs, files, and RAG chunks before they reach the LLM. 20% fewer tokens for coding agents, 60-95% fewer tokens for JSON, same answers. Library, proxy, MCP server.
At a glance
- What is it?
- Headroom compresses tool outputs, logs, and RAG chunks before they reach the LLM, claiming 60-95% token savings on JSON and 20% on coding agents. This review covers its architecture, installation, trade-offs, and who should adopt it.
- Who is it for?
- Headroom is for engineering teams running coding agents or RAG pipelines that hit token limits or cost ceilings on JSON-heavy workloads; the 60-95% savings on structured data are the strongest argument. It is not for teams that need lossless context or distrust local caching of conversation history, since the reversible CCR still stores originals on disk.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
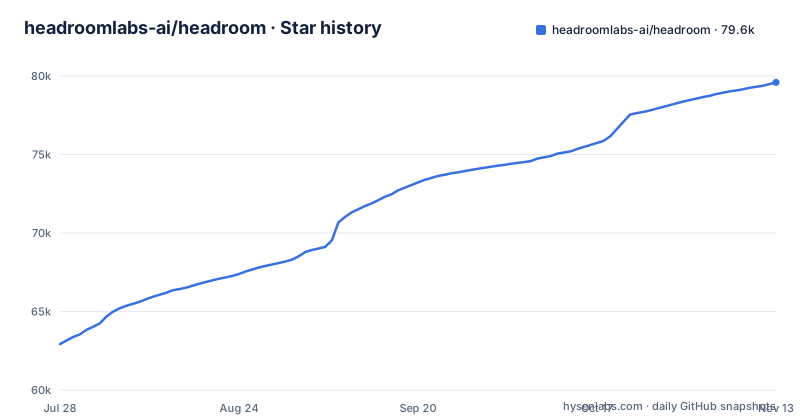
- headroomlabs-ai/headroom79,594 ★ · +16,670
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| headroomlabs-ai/headroom | 62.9k | 79.6k |
16,670 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Headroom Solves and Who It Targets
Headroom addresses a specific cost: LLM context windows fill with verbose tool outputs, logs, and RAG chunks, driving up token usage and latency. The README targets AI agents like Claude Code, Cursor, Codex, and LangChain-based apps. The core claim is that you can compress this material before it reaches the model and still get the same answers. The savings are not uniform: 60-95% fewer tokens for JSON data, 20% for coding agents. The project positions itself as a 'context compression layer' that runs locally, which matters for teams with data privacy constraints. It is not a general-purpose prompt optimizer; it is specifically for the high-volume, structured data that agents ingest.
The Compression Pipeline: ContentRouter, SmartCrusher, and CCR
The architecture diagram in the README shows a pipeline: CacheAligner, ContentRouter, and CCR. ContentRouter detects the content type and selects a compressor. There are three named compressors: SmartCrusher for JSON, CodeCompressor for AST, and Kompress-v2-base for text, the latter hosted on Hugging Face. CacheAligner detects volatile content that could break provider KV cache prefixes, but it never rewrites prompts. The reversible CCR stores originals locally; if the LLM needs the full text, it can call `headroom_retrieve`. This design is a trade-off: originals are cached locally and retrievable on demand. The README gives a live example: 10,144 tokens compressed to 1,260, with the same 'FATAL found' result. That example is a single anecdote; the README shows 10,144 tokens reduced to 1,260 with the same FATAL found.
Installation and Modes: Library, Proxy, Wrap, and MCP
You can install via `uv tool install --python 3.13 "headroom-ai[all]"` or `pip install "headroom-ai[all]"`, both of which ship the `headroom` CLI. The npm package `headroom-ai` is only a TypeScript SDK, not a CLI, so pick the Python route for the full tool. After install, there are four modes. The library: call `compress(messages)` in Python or TypeScript. The proxy: run `headroom proxy --port 8787` to intercept traffic without code changes. The agent wrap: `headroom wrap claude` or other tools, and undo with `headroom unwrap`. The MCP server: expose `headroom_compress`, `headroom_retrieve`, and `headroom_stats`. The README warns that a wrapped agent session is recommended each time, because wrapping starts a local proxy and installs Serena for semantic code navigation. For Claude Code, Serena is registered for the wrapped project only (as a local-scope MCP server in `~/.claude.json`); `--code-memory-scope user` makes it available in every project. You can skip it with `--code-memory none`.
Configuration and Extras: What You Need to Know
pyproject.toml requires Python >=3.11 (classifiers list 3.11 through 3.14) and builds with maturin, because the package includes a Rust extension built from a Cargo workspace (crates/headroom-core, headroom-proxy, headroom-py and others). The core dependencies include tiktoken, pydantic, litellm, click and rich, and the README installs with the `[all]` extra. The npm `headroom-ai` package is only the TypeScript SDK and provides no `headroom` command.
Output Token Reduction and `headroom learn`
Beyond input compression, Headroom claims to trim what the model writes back. The README says it trims what the model writes back, not only what you send. This is a more aggressive feature, because it alters the model's output, not just the context. The `headroom learn` command mines failed sessions and writes corrections to `CLAUDE.local.md` by default, or to `CLAUDE.md`, `AGENTS.md`, `GEMINI.md`, or `GROK.md`. This is a feedback loop: the system learns from failures and adjusts future behavior. Because it writes corrections into files such as CLAUDE.md, review what it writes before keeping it. This feature is optional, but it is a notable departure from a pure compression tool, because it writes persistent files that affect agent behavior.
Limitations and Failure Modes
The most obvious limitation is that compression is lossy. The README says 'same answers' but also describes a reversible CCR that stores originals, implying that the compressed form may not always suffice. If the LLM needs a detail that was stripped, it must call `headroom_retrieve`, which adds latency and requires the client to support that call. The README also notes that the npm package does not include the CLI, so a team expecting a unified install might be confused. The proxy mode intercepts traffic, which could introduce a single point of failure; if the proxy crashes, the agent loses access. Resilience in production is something to test yourself.
Alternatives and How They Differ
A direct alternative is to use a rule-based token truncation library, such as `tiktoken` for counting and then slicing context to a fixed budget. That approach is simpler and lossless in the sense that you keep the first N tokens, but it discards information arbitrarily. Headroom's content-aware compressors preserve semantic structure, which is better for JSON where field names repeat. Another alternative is a dedicated RAG chunking tool like `LlamaIndex` or `LangChain` text splitters, which break documents into chunks before embedding. Those tools do not compress; they segment. Headroom compresses after retrieval, which is a different stage. The closest comparison is to a semantic compression model like `Kompress-v2-base`, which Headroom itself uses for text. If you want to avoid a dependency on a Hugging Face model, you could use a pure JSON minifier, but that would not handle prose or code. The choice depends on whether your workload is JSON-heavy, code-heavy, or prose-heavy.
Maintenance, Licensing, and Upgrade Cost
The project is under Apache-2.0, which permits commercial use and modification without copyleft obligations. The last push was on 2026-11-02, and the newest release is v0.42.0 (2026-10-26), so the project is actively maintained. The release cadence (v0.40.0 on 2026-10-06, v0.41.0 on 2026-10-14, v0.42.0 on 2026-10-26) suggests rapid iteration, which is good for bug fixes but means you should pin versions in production. The README references a CI workflow, and the repository includes a CHANGELOG.md. The cost of maintenance is that the system has multiple moving parts: a proxy, an MCP server, a model (Kompress-v2-base), and optional vector backends. Each component needs updates when the underlying model or protocol changes. The `headroom unwrap` command exists to remove agent wrapping, which helps, and per the README `headroom unwrap` removes the Serena registration.
Editorial conclusion
Headroom is for engineering teams running coding agents or RAG pipelines that hit token limits or cost ceilings on JSON-heavy workloads; the 60-95% savings on structured data are the strongest argument. It is not for teams that need lossless context or distrust local caching of conversation history, since the reversible CCR still stores originals on disk. Before adopting, verify that the compression preserves answer quality on your specific workloads by running `python -m headroom.evals suite --tier 1` and comparing outputs with and without compression. Also check that your environment meets the Python 3.11+ requirement in pyproject.toml. If you need simple, lossless context trimming, a rule-based token truncation library may be simpler; if you need semantic compression with retrieval, consider a dedicated RAG chunking tool.
Frequently asked questions
how to install headroom
Three routes are given: `uv tool install --python 3.13 "headroom-ai[all]"` for a self contained CLI environment, `pip install "headroom-ai[all]"` for Python, and `npm install headroom-ai` for the TypeScript SDK. The npm package provides no headroom command, so the deploy, wrap, proxy and learn subcommands require the PyPI package.
how to use headroom ai
Pick one of four modes: `headroom deploy` for a turnkey local deployment plus agent configuration, `headroom wrap claude` to wrap a coding agent, `headroom proxy --port 8787` as a drop in proxy needing no code changes, or importing `compress` from the package and calling it inline in your own code. Compression runs on your machine rather than on a remote service.
how to use headroom with claude code
`headroom wrap claude` starts a local proxy, installs Serena for semantic code navigation, registers it for the wrapped project only (as a local-scope MCP server in `~/.claude.json`; `--code-memory-scope user` makes it available in every project), and launches the agent configured to route through Headroom. You undo it with `headroom unwrap <tool>`, or pass `--code-memory none` to skip Serena entirely.
how to use headroom with cursor
`headroom wrap cursor` is one of the listed wrap targets, alongside claude, codex, grok, copilot, aider, opencode, cline, continue, goose, openhands, openclaw, vibe, omp and zcode. The wrapper starts a local proxy and launches the agent configured to route through Headroom, and the wrapper is removed with `headroom unwrap <tool>`.
how to use headroom with opencode
`headroom wrap opencode` is in the list of wrap targets. The README says `headroom wrap` also installs Serena for semantic code navigation; for Claude Code it is registered for the wrapped project only, and `--code-memory-scope user` makes it available in every project. `headroom unwrap` removes either registration, and `--code-memory none` skips the step.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/headroomlabs-ai-headroom)Star history chart for your README
[](https://hysenlabs.com/projects/headroomlabs-ai-headroom)Was this useful?