Crawler_Illegal_Cases_In_China: A Case Archive for Crawler Developers Working in Mainland China
Collection of China illegal cases about web crawlers. Organizes news, materials and relevant laws and regulations on legal cases and violations involving web crawler developers in mainland China, to help practitioners understand the law and avoid compliance red lines.
At a glance
- What is it?
- The repository collects Chinese court cases and statutes that apply to web scraping. It is a reading list for compliance awareness, not a tool, and its value depends on how you use the case folders.
- Who is it for?
- Adopt this repository if you write or review crawlers that touch mainland Chinese sites and need the case law and statute text in one place; it is a reading resource, not a library, so no code dependency is created. Do not adopt it if you need an automated compliance check, a rate limiter, a robots.txt parser, or any executable component, because none of those exist here.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly HTML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
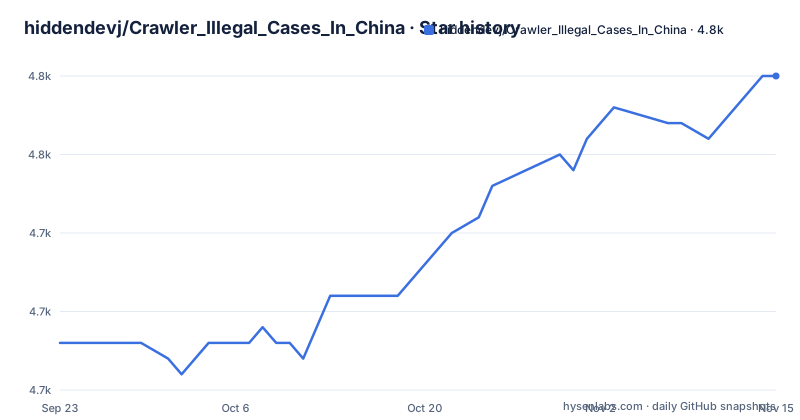
Star history
- hiddendevj/Crawler_Illegal_Cases_In_China4,755 ★ · +17
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| hiddendevj/Crawler_Illegal_Cases_In_China | 4.7k | 4.8k |
17 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the repository is, and who it is written for
This is a curated reading list. The README states the project's purpose plainly: it collects news, materials and legal provisions related to lawsuits and violations involving crawler developers in mainland China, so that practitioners in the data industry can understand the relevant law and avoid crossing data compliance lines. There is no crawler, no library, no CLI and no API. The primary language of the repository is HTML, which matches the link-list structure: the top level holds README.md and a set of case directories (case1/, case2/, case3/, case6/, case7/, case10/, case11/, case12/, case14/, case15/).
The intended reader is a developer or data engineer whose crawler touches Chinese sites, or a team lead who signs off on that work. The framing is defensive. Each case is filed under a heading that names a prohibited zone rather than a technology, so the reader is meant to recognise a pattern of behaviour and stop, not to learn a technique. That is a deliberate editorial choice and it shapes everything else about the repository.
How the case taxonomy is organised
The README groups the cases into five zones. Zone 1 covers providing crawler-related services to illegal organisations, and the examples given are selling CAPTCHA-recognition services and SEO manipulation. Zone 2 covers scraping and selling personal privacy data, with cases about resume data, social insurance apps, business registration data and a stored credential database. Zone 3 covers profiting from commercial data without rights, including a transit app, a court-document site, a shopping platform data interface and a web novel site. Zone 4 has a single case: a target website going down under load, described as 183 requests per second against a residence-permit site, with both the CTO and a programmer sentenced. Zone 5 is labelled with a question mark and holds one case, which is a fair admission that the taxonomy is not closed.
That structure is the useful part. It maps legal exposure onto decisions an engineer actually makes: what service you sell, whose data you take, whether you have rights to the data, and how much load you put on the target. The fifth zone being unresolved is honest rather than sloppy; the maintainers did not invent a category to make the list look complete.
The statute summaries and what they pin down
Below the cases, the README reproduces the text of the offences that recur in Chinese crawler prosecutions. Article 286 of the Criminal Law covers destroying or illegally intruding into computer information systems, and the README adds an editorial note pointing at case14: the note says the direct supervisor's penalty is heavier than the developer's. Article 285 covers illegally obtaining computer system data, and the README quotes the sentencing bands: up to three years, or three to seven years where the circumstances are especially serious. Article 253 as amended by Amendment (IX) covers infringing citizens' personal information, and the README quotes the judicial interpretation's thresholds for serious circumstances: 50 or more items of location, communication, credit or property information; 500 or more items of accommodation, communication records, health, or transaction information; or 5,000 or more items of other personal information.
Those numbers are the most concrete thing in the repository. A developer can read them and understand that the offence is counted in records, not in intent. The README also summarises the Anti-Unfair Competition Law Article 9 on trade secrets, Cybersecurity Law Article 44, and Article 111 of the General Provisions of the Civil Law on lawful collection of personal information. It is a summary, not a legal opinion, and it says so by linking out to the full statutes.
Installing it and a first real use
There is nothing to install. The repository is a document collection, so the only setup is getting a local copy and reading it. Cloning is the whole procedure:
git clone https://github.com/hiddendevj/Crawler_Illegal_Cases_In_China.git
cd Crawler_Illegal_Cases_In_China
After the clone you get README.md at the top level plus the case directories. The README does not document a build step, a package manifest or a test command, and none is needed for a document collection. A first real use is to read the two cases the README links to as readme.md files:
ls case14 case15
cat case14/readme.md
cat case15/readme.md
case14 is the overload case and case15 is the stored-credential case. Reading those two first gives you the two extremes: a crawler that broke a target through request volume, and a crawler that accumulated personal data at scale. If your team is reviewing a scraper design, those two files are the shortest path to the parts of the repository that describe consequences rather than definitions.
Where the repository stops being useful
It is not a compliance tool and cannot become one. There is no robots.txt parser, no rate limiter, no request scheduler, no data-classification helper and no checklist you can run in CI. If your question is "will this particular crawl be lawful", the repository gives you analogous cases and statute text, and the answer still depends on facts it does not have: the terms of the target site, the nature of the data, the volume, and the jurisdiction. The README itself frames the goal as helping readers avoid red lines, not as certifying any specific crawl.
Two smaller limitations matter too. Several case entries are external links rather than in-repository files, and some of those point to news sites that can go offline; the first case is marked as deleted in the README. And the case list is a sample, not a census. A repository that collects prosecutions will always lag the docket, so absence of a case in this list says nothing about whether a behaviour is lawful. Treat it as a starting point for a conversation with counsel, not as the end of one.
How it compares with a scraper framework's compliance features
Scrapy, for example, ships settings and middleware aimed at polite crawling: an AutoThrottle extension, a RobotsTxtMiddleware, and per-domain concurrency limits. Those are mechanisms that change what your crawler does. This repository is the opposite kind of artefact: it changes what you know. A team using Scrapy can obey robots.txt and still end up in the personal-information category, because robots.txt says nothing about whether the scraped records are personal data or how many of them trigger the judicial interpretation's thresholds.
The two are complementary rather than competing, and the difference in approach is worth stating precisely. A framework enforces a policy you have already decided on. This repository is where the policy comes from. If you only adopt one, adopt neither blindly: a rate limit without the legal thresholds is a guess, and the thresholds without a rate limit are a document.
Maintenance, licence and what to verify
The repository is not archived, and the last push was on 2026-03-12. The repository has no published GitHub releases, and the README does not describe versioning or a changelog, so there is no upgrade path to plan for. The cost of keeping current is editorial, not technical: someone has to add new cases and re-check the statute links as the underlying laws and judicial interpretations change. The README links to the Criminal Law, the Anti-Unfair Competition Law, the Cybersecurity Law, the Civil Code, and the judicial interpretation on personal-information criminal cases, all via encyclopedia entries rather than official gazettes, which is a weak point if you need citable text.
The licence is not stated. The repository does not declare one and has no licence file at the top level, and that matters if you intend to redistribute the case summaries inside a company wiki or a training deck. Check the repository for a licence file before you copy content, and treat the legal summaries as secondary sources regardless of what the licence says.
Editorial conclusion
Adopt this repository if you write or review crawlers that touch mainland Chinese sites and need the case law and statute text in one place; it is a reading resource, not a library, so no code dependency is created. Do not adopt it if you need an automated compliance check, a rate limiter, a robots.txt parser, or any executable component, because none of those exist here. Before relying on it, open case14/readme.md and case15/readme.md, confirm the statute links still resolve, and check whether the project's unknown licence matters for how you redistribute the case summaries inside your own organisation.
Frequently asked questions
Is Crawler_Illegal_Cases_In_China a crawler framework or a software tool?
No. It is a document collection: the README describes it as a compilation of news, materials and legal provisions about crawler-related lawsuits and violations in mainland China. The repository holds README.md and case directories, not runnable code.
What kinds of cases does Crawler_Illegal_Cases_In_China cover?
The README sorts them into five zones: providing crawler services to illegal organisations (CAPTCHA cracking, SEO manipulation), scraping and selling personal privacy data, profiting from commercial data without rights, and causing a target site to go down through request volume. A fifth zone is left as an open question with one case.
What are the personal-information thresholds mentioned in Crawler_Illegal_Cases_In_China?
The README quotes the judicial interpretation: 50 or more items of location, communication, credit or property information; 500 or more items of accommodation, communication records, health or transaction information; or 5,000 or more items of other personal information constitute serious circumstances.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hiddendevj-crawler-illegal-cases-in-china)Star history chart for your README
[](https://hysenlabs.com/projects/hiddendevj-crawler-illegal-cases-in-china)Was this useful?