nsfwjs: client-side image classification in five classes
NSFW detection on the client-side via TensorFlow.js
At a glance
- What is it?
- nsfwjs runs a TensorFlow.js model in the browser or in Node to sort images into Drawing, Hentai, Neutral, Porn and Sexy. It is a classifier with a small vocabulary, not a moderation policy, and the README's own accuracy numbers are the place to start.
- Who is it for?
- Adopt nsfwjs when you want a pre-filter that runs on the visitor's device, where images never leave the browser and there is no per-image server cost, and when a five-class probability vector is enough for your product.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 18 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
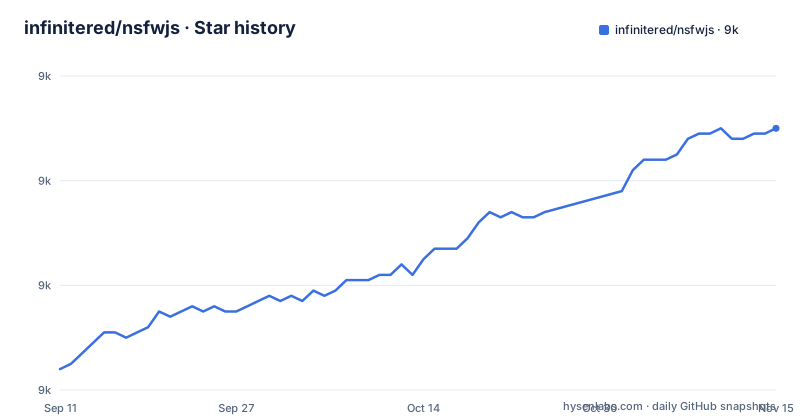
- infinitered/nsfwjs9,030 ★ · +46
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| infinitered/nsfwjs | 9k | 9k |
46 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem nsfwjs addresses, and who ends up using it
Upload flows, chat clients, marketplace listings and user profile editors all accept images before a human ever sees them. The usual answer is to POST the file to a moderation service and wait. That costs money per image, adds a network round trip to the upload, and means the picture leaves the user's device. nsfwjs takes the opposite position: the model runs where the image already is, in the browser or in a Node process, and returns probabilities without a server call. The README frames the library as a way to 'quickly identify unseemly images; all in the client's browser'. The audience that follows from that is front-end and React Native developers, and Node developers who want a first pass before anything reaches a paid API. The five output classes are Drawing, Hentai, Neutral, Porn and Sexy, with the README noting that Drawing covers safe-for-work drawings including anime and that Sexy means sexually explicit images that are not pornography. That label set already tells you the model was built with illustrated and photographic material in mind, and that its notion of explicit is narrower than a typical trust and safety taxonomy.
What the model actually returns, and why the class list matters more than the score
classify returns predictions, and the quick-start example prints them with console.log. Nothing in the API decides that an image is unacceptable; you read the probabilities and apply your own cutoff. That is the single most important design fact about nsfwjs, because it means the accuracy discussion belongs to your product decision, not to the library. Where you set the cutoff decides what you miss and what you over-block. The README states roughly 90 percent accuracy with the small model and roughly 93 percent with the midsized one, and describes the library as not perfect. Those figures are aggregate, so a 93 percent overall number can hide a much weaker result on the class you care about most. Treat per-class behaviour as something you measure yourself. The claim that it is getting more accurate over time is a statement about the project's direction, not a guarantee attached to the version you install.
Three bundled models and the size you pay for them
load takes an optional first argument naming one of three built-in models: MobileNetV2 (the default), MobileNetV2Mid, and InceptionV3. The bundled MobileNetV2 is described as 3.5MB, against 2.6MB for the same model served as binary files from your own host, because the packaged version carries the weights as base64. That 33 percent difference only matters when the model is fetched on every page load rather than cached, since a server process loads it once at startup. MobileNetV2 expects 224x224 input, InceptionV3 expects 299x299 and needs the size passed in options, and MobileNetV2Mid is distributed as a graph model. Graph models are a genuine constraint: the README states that with a graph model you cannot use the infer method and must declare the type when loading. If you plan to reach past classify into lower-level TensorFlow.js calls, that restriction decides which model you can use. The InceptionV3 path also means larger input tensors and more work per image, which is a cost you accept on the client's hardware, not on a server you control.
Getting it running: install, load, classify, dispose
The quick path in the README is four lines of application code. Import the package, grab an image element, await nsfwjs.load(), then await model.classify(img) and log the predictions. Selecting a different bundled model is a string argument: nsfwjs.load('MobileNetV2Mid'), with the README listing 'MobileNetV2' | 'MobileNetV2Mid' | 'InceptionV3' as the accepted values. To load from your own host, pass a path instead of a name, for example nsfwjs.load('/path/to/mobilenet_v2/'). The README also documents a dispose method for releasing a loaded model, which is the counterpart to load and matters in long-lived single-page apps where you may swap models. For a smaller application bundle, import load from 'nsfwjs/core' rather than 'nsfwjs'; the core entrypoint omits the built-in model definitions so bundlers do not pull the model assets in. If you go that route with named models you must supply the definitions yourself, passing modelDefinitions with imports such as MobileNetV2Model from 'nsfwjs/models/mobilenet_v2'. The README is explicit that an empty registry breaks named loads: await load('MobileNetV2', { modelDefinitions: [] }) throws. Caching is mentioned for browser use, with the README warning that model size may be too large for local storage, so IndexedDB is the path it points at.
The hosted-model note is a warning about depending on someone else's CDN
The README carries a note at the top: if you are hitting an error against the Cloudfront-hosted model, the model has moved, and you should host your own. It says the model will be returned after some hotlinkers have been dealt with. Read that as an operational fact rather than a temporary glitch. Loading the model from the project's Cloudfront host is a dependency on infrastructure the project controls and has already pulled once. Any application that cannot tolerate that endpoint disappearing should serve the model files itself and pass a path to load. The README gives you the numbers to make the decision: hosted binary files are smaller than the base64 bundled copies, and a server-side process loads the model once regardless. The trade is that you now own the storage, the cache headers and the version pinning of the weight files.
Where nsfwjs is the wrong tool
The five-class output is the hard boundary. If your policy distinguishes categories the model does not have, such as violence, gore, self-harm, hate symbols or CSAM, nsfwjs cannot express them, and no amount of threshold tuning will produce a label that was never trained. The README's own accuracy figures also mean the library is a filter, not a gate: at roughly 90 percent with the small model, a meaningful share of decisions are wrong, and the cost of a false negative in a user-facing upload flow is usually higher than the cost of a false positive. Client-side execution has a second failure mode. Anything running in the browser is inspectable and bypassable, so an adversary who wants to upload prohibited material can modify the page or call your API directly. If your threat model includes a motivated user rather than an accidental one, client-side classification is a convenience layer and the enforcement has to happen server-side. There is also the bundle question. Shipping a multi-megabyte model to every visitor, including those who never upload an image, is a real cost on mobile connections, and the README's caching note concedes that local storage may not be large enough to hold it.
How this differs from calling a hosted moderation API
The obvious alternative is a server-side moderation service: you send the image, you get labels back. The difference is not accuracy, it is where the pixels go and who pays per call. A hosted API can afford a larger model and a broader taxonomy than anything you would ship to a browser, and it can be updated without redeploying your client, but every image crosses the network, the latency lands inside your upload path, and the bill scales with volume. nsfwjs inverts all three: no image leaves the device, classification happens alongside the upload, and the marginal cost per image is zero. What you give up is taxonomy breadth, the ability to update the model without shipping new client code, and any guarantee against a user who controls the client. A reasonable architecture uses both, with nsfwjs as the pre-filter that stops the obvious cases before they are uploaded and a server-side check as the authority. The README does not describe such a pipeline, so treat that as a design you would build around the library rather than something it provides.
Maintenance, licensing and what to check before you depend on it
The project is MIT licensed, which permits commercial use, modification and redistribution provided the copyright notice and permission notice are preserved. That is a permissive licence, but it says nothing about the provenance of the model weights or the training data, and if your organisation has requirements about where model weights come from or what data trained them, check those before shipping. On maintenance, the release history shows a gap: v4.2.0 in October 2024, v4.2.1 in November 2024, then v4.4.0 in August 2026. A roughly twenty-month quiet period followed by a release is normal for a library of this size, but it means you should not assume rapid response to issues. The v4.2.0 release was titled 'Updating ESM Bundling', which is the kind of change that can alter how the package resolves in your bundler, so pin your version and re-test after upgrades rather than floating on a caret range. Before adopting, the concrete step is to load a hosted MobileNetV2 model, run model.classify over a sample of your own images, and look at the per-class probabilities against your existing labels. The README's aggregate accuracy figures are not a substitute for that measurement.
Editorial conclusion
Adopt nsfwjs when you want a pre-filter that runs on the visitor's device, where images never leave the browser and there is no per-image server cost, and when a five-class probability vector is enough for your product. Do not adopt it as a legal or compliance gate: the README's own numbers are roughly 90 percent for the small model and roughly 93 percent for the midsized one, which leaves a real error rate in both directions, and the classes are defined by the model's training, not by your policy. Do not adopt it either if you need to classify text or anything outside the five labels, or if you cannot ship a multi-megabyte model to the client. Before committing, load a hosted MobileNetV2 build and run your own image set through model.classify, then compare those predictions against your existing moderation labels rather than trusting the headline accuracy figure.
Frequently asked questions
What is an NSFW filter?
In nsfwjs it is a TensorFlow.js classifier that runs in the browser and returns a probability for each of five classes: Drawing, Hentai, Neutral, Porn and Sexy. The library returns probabilities only, so deciding what passes is left to the application.
Which nsfwjs model should I load?
The default is MobileNetV2 at 224x224, with MobileNetV2Mid and InceptionV3 as the other two bundled models. The midsized one needs the graph type passed in options and cannot use infer, while InceptionV3 needs its size passed as 299.
How do I keep nsfwjs out of my app bundle?
Import load from nsfwjs/core, which does not include built-in model definitions, and pass the models you want in modelDefinitions. Passing an empty registry makes a named bundled model load throw.
Can nsfwjs cache the model in the browser?
Yes. Save the underlying model after an initial load with initialLoad.model.save("indexeddb://exampleModel") and load from that IndexedDB path afterwards. The README warns that the model size may be too large for local storage.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/infinitered-nsfwjs)Star history chart for your README
[](https://hysenlabs.com/projects/infinitered-nsfwjs)Was this useful?