jonaslejon/malicious-pdf: 67 callback PDFs from one Python script
💀 Generate malicious PDF test files for testing phone-home callbacks, SSRF, XSS, NTLM credential theft, and data exfiltration in PDF viewers, converters, and web applications. Can be used with Burp Collaborator or Interact.sh
At a glance
- What is it?
- A single-file Python generator that writes PDFs carrying GoToE, XFA, Launch and JavaScript actions, aimed at defenders testing upload endpoints, converters and PDF parsers. Its obfuscation levels and its own file counts do not line up, so read the README carefully before you trust the count.
- Who is it for?
- Adopt it if you own a PDF upload path and need a corpus of callback files today, since two commands produce the whole matrix. Skip it if you need to generate one payload at a time, because the script emits the whole payload matrix on every run.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 29 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
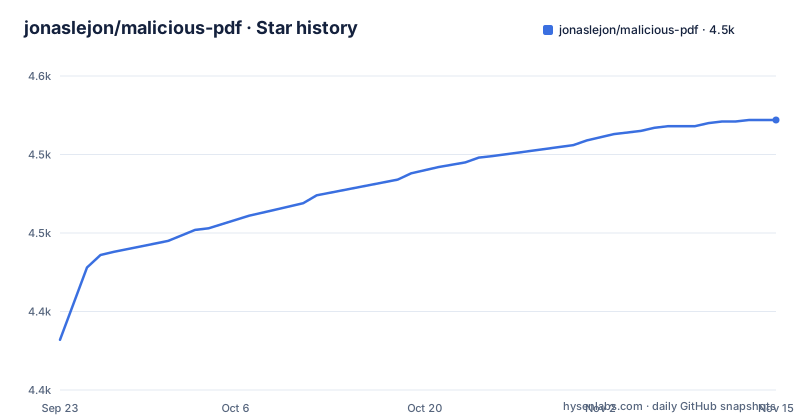
- jonaslejon/malicious-pdf4,522 ★ · +140
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| jonaslejon/malicious-pdf | 4.4k | 4.5k |
140 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Why anyone needs a file that phones home on open
The problem this solves is narrow and real: a defender who handles PDF uploads has no safe way to prove whether the parser in front of them makes an outbound request. A benign PDF proves nothing, because a clean file exercises none of the code paths where SSRF, external entity resolution or credential relay hides. This script writes that test file for you, once, for every payload class the author cared to encode.
The audience is the person with access to a test environment: a penetration tester, a bug bounty hunter working inside a program's scope, or a red team running detection checks. The README states its own purpose plainly, listing PDF viewers, PDF converters, server-side processing libraries such as PDFBox and iText, and static analysis tools. It also names the specific bugs it is meant to surface: SSRF, XXE, blind callbacks and NTLM leaks in upload endpoints and document pipelines.
One Python file does all of it. The repository top level holds malicious-pdf.py, requirements.txt, and documentation files; there is no package, no plugin API and no fixture format. That narrowness is the design. A responder who needs one callback file in the next five minutes runs a script rather than assembles a template.
Every payload rides on a PDF action dictionary
The payloads are not exploits against the PDF format. They are ordinary PDF structures that viewers already honour, pointed at a URL the tester controls. The test matrix names the structure for each file: test1.pdf uses a /GoToE action with a UNC path, test1_1.pdf the same action with an HTTPS URL, test5.pdf a /URI action, test6.pdf a /Launch action, and test7.pdf a /GoToR action that loads a remote document.
Form handling carries the rest. test2.pdf builds an XFA form with a submit event so the viewer posts the form data out on its own, and test4.pdf points XFA at an external XSLT stylesheet reachable over a UNC path. test3.pdf attaches /OpenAction with app.openDoc() to load an external document. Each file is a small dictionary difference from a well-formed PDF, which is exactly why these files pass shape checks that only count objects and pages.
Staged JS payloads also exist, in form field /V values and in a base64 decoder stub. The README says those forms exist to defeat naive /JS regex scanners in static analysis products. So the tool has two audiences at once: parsers that execute the action, and scanners that read the bytes looking for something to flag.
Two commands between a clean checkout and an output directory
Installation is a requirements file with one entry, validators. The script then takes the callback endpoint as its positional argument.
pip install -r requirements.txt
python3 malicious-pdf.py burp-collaborator-url
Output lands in a directory called output/ as test1.pdf, test2.pdf, test3.pdf and so on. Nothing is asked for interactively, and the endpoint placeholder in the README is a literal word rather than a flag, so a reader who forgets to substitute it will get files pointing at nothing.
Three options change what gets written. --output-dir DIR moves the destination, --no-credit drops the credit and attribution metadata, and --obfuscate takes a level. The README shows an obfuscation example like this:
python3 malicious-pdf.py https://your-interact-sh-url --obfuscate 2The endpoint can be a Burp Collaborator URL or an Interact.sh URL. That is the whole dependency model: no account inside this project, just an HTTP listener you already run somewhere else and hand the address to the script.
Obfuscation levels that contradict the option list
The option list gives four values and says level 0 is the default. Level 1 hex encodes PDF names and octal or hex encodes strings. Level 2 adds bracket notation for JavaScript plus case and whitespace obfuscation of javascript: URIs. Level 3 adds FlateDecode stream compression on top. Immediately after the option block, the README documents a level 4 that wraps JavaScript payloads in a base64 decoder stub so the original API calls never appear as literal substrings, and gives it its own example:
python3 malicious-pdf.py https://your-interact-sh-url --obfuscate 4Level 4 is outside the range the option block claims. If you script against level 3 as the ceiling, or hand a colleague who assumes the list is complete, you will mispredict what the files contain. The generator itself is the only source that settles it, and the README does not reconcile the two.
A second mismatch sits at the top of the same file. The description says 67 test files. The test matrix in the README is collapsed behind a summary line reading "Click to expand all 70 test cases". Three files, or seventy, changes what you tell a stakeholder about coverage. The credit line names ExpMon analysis from April 2026 as the inspiration for test33_13, test33_14, test33_15 and for level 4, so the count moved after the headline was written.
Credit metadata embedded in every file by default
The --no-credit flag exists because the generated PDFs carry attribution metadata unless you ask them not to. Files that identify their own author as a public tool are worse at slipping past a gateway and worse at sitting in an incident queue as someone else's problem. For a lab corpus you want that metadata; for anything that crosses a boundary into a third party's environment, you usually do not.
The flag is a generation-time switch, not a post-processing step, so it has to be present on the run that produces the file. Regenerating a corpus later without repeating it changes the bytes of every output, which is a nuisance if you are comparing one set of files against a scanner's results over time.
Nothing else in the options controls naming or content selection. You get the whole matrix or you get it again. There is no flag to emit a single payload and no seed; the README's test matrix is what maps each test file to its action. For a targeted check against one upload handler, you generate everything and pick the file yourself.
Where the callbacks land and who reads them
Because the endpoint is yours, the generator tells you nothing about the finding. That is deliberate division of labour: this side writes files, and Burp Collaborator or Interact.sh tells you which file was opened, from which address, and when. The README links both and describes them as the sink for generated traffic.
That split has a consequence for anyone planning a campaign. Correlation comes from your callback listener rather than from the generator, which takes a single endpoint argument. If you need to know which of the 67 files a viewer executed, generate with distinguishable endpoints yourself.
For static tooling the loop closes differently. Level 1 to level 3 rewriting and the staged form-field payloads exist so a scanner that looks for the literal string javascript or for a /JS key misses payloads that are still valid. A corpus that defeats your scanner is a corpus you can use to measure the scanner.
Bad-Pdf and Mod0BurpUploadScanner take a different route
The credits list names Bad-Pdf and Mod0BurpUploadScanner as prior art, and the difference is one of shape rather than ambition. This script targets the surrounding infrastructure: the upload endpoint, the converter, the parser's outbound requests.
Here you hand the script a URL and it produces files.
For defensive work the practical gap is reproducibility. A scanner run against files it has never seen tells you about the scanner. The same set regenerated on a different day, with a different collaborator URL and possibly different metadata, tells you less. Pin the endpoint, keep the flags identical across runs, and archive the output directory alongside the scanner report.
Nothing in the options pins a Python version or a file manifest
Licensing is BSD-2-Clause, two clauses over redistribution and disclaimer, with no condition attached to publishing changes or to derived corpora. That matters if a generated set of files leaves your lab.
Beyond that, the tool tells you very little about its own boundaries. If you need to prove later which payload a given finding came from, keep your own record of the endpoint and the run date.
The last push was on 2026-10-17, while both release tags date from 2026-04-20, so pinning a tag does not pin today's output.
Editorial conclusion
Adopt it if you own a PDF upload path and need a corpus of callback files today, since two commands produce the whole matrix. Skip it if you need to generate one payload at a time, because the script emits the whole payload matrix on every run. Before the first run, verify what the obfuscation levels actually produce, because the README documents levels 0 to 3 in its option list and then describes a level 4 the list never mentions. Generate one batch, diff the output directory against the last one, and keep that archive with your scanner report.
Frequently asked questions
Can a PDF file really contain a malicious payload?
Yes. The generated files use standard PDF structures such as /GoToE, /URI, /Launch, /GoToR and XFA form submission, so the callback behaviour comes from actions viewers already honour rather than from a broken file format.
How does jonaslejon/malicious-pdf generate its test files?
You install the single requirement with pip install -r requirements.txt and pass a callback URL as the argument to python3 malicious-pdf.py, for example a Burp Collaborator or Interact.sh address. Files are written to output/ as test1.pdf, test2.pdf and onward.
Can jonaslejon/malicious-pdf files evade static PDF scanners?
Partly, by design. Obfuscation levels add name hex encoding, string octal or hex encoding, bracket notation for JavaScript, javascript: URI case and whitespace changes, FlateDecode compression, and at the highest documented level a base64 decoder stub, plus staged payloads placed in form field /V values.
What does the --no-credit flag change in malicious-pdf output?
It stops the generator embedding credit and attribution metadata in the PDF files it writes. Without it, the default output carries that metadata.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/jonaslejon-malicious-pdf)Star history chart for your README
[](https://hysenlabs.com/projects/jonaslejon-malicious-pdf)Was this useful?