Xyne Spaces: An Org Context Layer With a Three-Tier Agent Sandbox
The AI Org-OS, a collaborative platform for humans and agents.
At a glance
- What is it?
- Xyne Spaces is a self-hostable TypeScript platform that normalizes organizational data into a permission-aware context store, with collaborative apps and agent workflows built around it. Its key architectural bet is a three-tier agent sandbox that separates secrets, code execution, and shell access.
- Who is it for?
- Adopt Xyne Spaces if you need a self-hosted context store that unifies Slack, Google Workspace, and Microsoft 365 data behind a permission-aware API, and if you want agents that run real code without holding credentials. Skip it if your organization cannot commit to Node.js 22.x, pnpm 10.15.0, and Docker Compose, or if you expect a plug-and-play SaaS with no infrastructure work.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
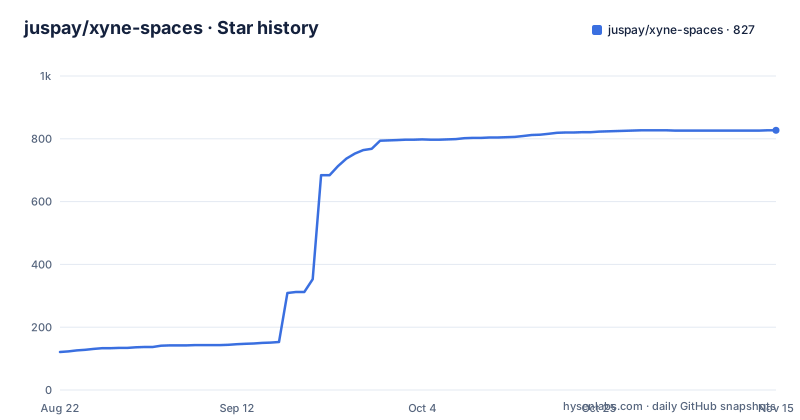
- juspay/xyne-spaces827 ★ · +706
| Repository | 2026-08-22 | 2026-11-15 |
|---|---|---|
| juspay/xyne-spaces | 121 | 827 |
706 Stars in the last 85 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What Problem It Solves and Who It Is For
Xyne Spaces addresses a specific pain: organizational context scattered across Slack, Google Workspace, Microsoft 365, Jira, and Confluence. Every conversation, ticket, and document lives in a different tool, and both humans and agents need to query across all of them. The project's answer is a central context store that normalizes, deduplicates, threads, and indexes everything, then serves it through permission-aware APIs. The intended users are engineering teams inside organizations that want to build their own context layer, not buy a proprietary platform. It is also for teams that want to run AI agents with access to real work data, but without giving agents standing credentials. The README frames it as an 'org OS' with a context layer at the center, and that is a useful mental model: it is not a single app but a platform on which you can run collaborative apps and agent workflows.
The Architecture: A Context Store, Apps, and a Three-Tier Agent Plane
The architecture has three distinct planes. First, the context store: connectors pull data from external services, normalize it, and index it for hybrid retrieval. Second, the org apps: Call, Claw, Agentic Search, Automations, Customer Support Desk, Chat, Canvas, and Tickets. These apps read and write to the same context store, with every operation filtered through the same permission model. Third, the agent plane, which is the most distinctive part. The README describes a three-tier split: the gateway, the runtime, and the hypervisor. The gateway holds all secrets and credentials, verifies HMAC-signed webhooks, and executes every external tool call through an MCP endpoint. The runtime pod runs the LLM agent loop but has no secrets and no shell; it posts tool calls back to the gateway. Bash commands run inside a Kata Containers QEMU microVM with egress closed. The security model is explicit: the tier that runs untrusted code holds no secrets, and the tier that holds secrets runs no untrusted code. This is a thoughtful separation, but it also means you need to operate three distinct components, each with its own failure modes.
How the Agent Sandbox Works: No Secrets in the Runtime
The agent sandbox is the project's core security claim. Agents run real code, execute shell commands, and write files, which is inherently risky. The design mitigates that by splitting the agent plane. The gateway, protected by claw-auth, verifies an HMAC-signed webhook from Spaces, resolves the agent's credentials, and dispatches the run. Every external tool call goes through the gateway's /mcp/call endpoint. The runtime pod, xyne-claw, runs the LLM loop and path-scoped filesystem tools. It cannot reach connected systems directly; it sends a tool name and parameters back to the gateway with a short-lived HMAC session token. A compromised runtime yields no reusable secret because none is stored there. For shell access, the gateway drives a Kata Containers QEMU microVM with its own kernel, and that VM has no network egress and no gateway credentials. The README states: 'Bash lives behind a hypervisor.' That is a strong isolation claim, but it depends on Kata Containers being configured correctly, and the README points to infra files under apps/xyne-claw/infra/kata/ for setup. You should verify that your host supports Kata's requirements before relying on it.
Getting It Running: Quickstart and Prerequisites
The quickstart section lists specific prerequisites: Node.js 22.x, pnpm 10.15.0, and Docker (or OrbStack or Podman) with Compose. The stack is clear: a Node.js and pnpm project with containerized dependencies. The repository layout includes apps like xyne-claw, and the gateway uses Postgres, Redis, BullMQ, and GCS for storage. The quickstart likely involves cloning the repository, installing dependencies with pnpm, and starting the stack with Docker Compose. Because the README is truncated, I cannot confirm the exact commands, but the prerequisites give a concrete starting point. You should expect to configure connectors for Slack, Google Workspace, and Microsoft 365, and to set up the permission model before use. The project is not a hosted service; it is a self-hosted platform, so you need to manage the infrastructure yourself.
Connectors and the Permission Model: The Real Value
The connectors are the entry point for bringing in organizational context. The README mentions Slack, Google Workspace, Microsoft 365, and 'more' with a link to a connectors section that is not fully visible. It also mentions bulk import from Jira, Confluence, and Slack. The normalisation process includes deduplication, threading, and indexing for hybrid search. The permission model is enforced at the data layer: reads are scoped to the acting user, writes go through a central permission layer, and agents inherit the user's access. There is no privileged bypass. This is a meaningful design choice because many agent platforms give agents broad access or a separate identity. Here, an agent acting on behalf of a user can only see what that user can see. This reduces the risk of data leakage, but it also means that agents cannot perform cross-user actions unless the user has explicit access. The trade-off is that some workflows, like a support agent triaging tickets across all customers, may require a special user account with broad permissions, which could undermine the model.
Writes Require Human Approval: The Identity Distinction
The agent sandbox distinguishes between read and write operations. Read tools run freely, but tools that create a ticket, schedule a call, edit a canvas, or send a message as the user post an approve/decline card in the thread and wait for a click. The README explains: 'The distinction is identity, not danger: acting as the bot is autonomous, acting as you needs your consent.' This is a precise and practical rule. It means that agents can act autonomously as the bot identity, but any action that impersonates a human requires explicit consent. This is a good middle ground between full autonomy and no autonomy. However, it also implies that the UI must support these approval cards in threads, and that users must be present to click approve. For fully automated workflows that run overnight, this could be a bottleneck. The documentation does not say whether approvals can be pre-authorized or scheduled, so you should plan for human-in-the-loop delays.
Limitations and Failure Modes: What the README Does Not Say
The README is strong on architecture but thin on operational details. It does not mention performance characteristics, scaling limits, or backup and recovery procedures beyond mentioning GCS for session checkpoints. There is no discussion of what happens when the gateway or the runtime crashes mid-run. The run recovery through BullMQ is mentioned, but not detailed. A genuine limitation is the complexity of the stack: you need Postgres, Redis, BullMQ, GCS, and Kata Containers. That is a heavy footprint for a small team. Another failure mode is the permission model: if a user has broad permissions, an agent acting as that user inherits those broad permissions. There is no notion of a separate agent role. The README says agents have no credentials of their own, but that also means they are only as safe as the user's permissions. If a user with admin rights invokes an agent, the agent can do everything that admin can do, subject to write approval. That is a risk to consider. The README also does not cover how to handle connector API rate limits or data sync failures. These are operational gaps that you would need to address yourself.
Alternatives: How It Compares to Other Approaches
A real alternative is to build your own context layer using a vector database and a permission framework. For example, you could use pgvector in Postgres to index documents and enforce row-level security for access control. The difference in approach is that Xyne Spaces provides a pre-built integration layer with connectors and a permission-aware API, whereas a custom build requires you to write the connectors, the normalisation logic, and the permission checks yourself. Another alternative is to use a commercial platform like Glean or Notion AI, which offer similar context retrieval but as closed SaaS products. The difference is that Xyne Spaces is self-hosted and Apache-2.0 licensed, giving you full control over data and infrastructure. However, those commercial platforms often have more polished connectors and out-of-the-box integrations. Xyne Spaces is a middle path: open source, self-hosted, but with more operational burden. The choice depends on whether you value control over convenience.
Editorial conclusion
Adopt Xyne Spaces if you need a self-hosted context store that unifies Slack, Google Workspace, and Microsoft 365 data behind a permission-aware API, and if you want agents that run real code without holding credentials. Skip it if your organization cannot commit to Node.js 22.x, pnpm 10.15.0, and Docker Compose, or if you expect a plug-and-play SaaS with no infrastructure work. Before adopting, verify that the permission model matches your existing access control policies, and confirm that the Kata Containers hypervisor setup is feasible in your deployment environment. The project is licensed under Apache-2.0, which allows commercial use, but you must review the contribution guidelines and the full license text for any obligations. The three-tier sandbox is a serious design, but it is only as strong as your ability to operate it correctly.
Frequently asked questions
How does xyne-spaces stop an agent reading what a person cannot?
Agents act as the person who invoked them, so a query is scoped to that user's permissions and there is no privileged bypass. Reads go through the same data layer as the interface, and the runtime that executes agent code holds no credentials of its own, reaching connected systems only through the gateway.
What runs a shell command for a xyne-spaces agent?
Bash runs inside a Kata Containers QEMU microVM with its own kernel, created by the gateway through sandbox control plane calls, with egress closed and no gateway credentials inside it. The setup lives in apps/xyne-claw/infra/kata/, so isolation rather than permission is what contains it.
How do I get a local Xyne Spaces environment running?
The repository ships helpers for each step: pnpm run setup installs and builds the shared packages, pnpm run doctor runs the doctor script, pnpm run secrets generates local secrets, and just services starts everything through nix run .#xyne-space-services, with just cleanup to tear it down.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/juspay-xyne-spaces)Star history chart for your README
[](https://hysenlabs.com/projects/juspay-xyne-spaces)Was this useful?