Plano: An Envoy-Based Data Plane That Moves Agent Routing Out of Your Application Code
Plano is an AI-native proxy server and data plane for agentic apps. Smart LLM routing, observability, agent orchestration, and guardrails so you stay focused on your agents core logic.
At a glance
- What is it?
- Plano is an Apache-2.0 Rust proxy server that handles agent orchestration, LLM routing, tracing and guardrail hooks outside your application process. It is useful if you are running several agents behind one endpoint; it is overkill if you have one agent and one model provider.
- Who is it for?
- Adopt Plano if you are running two or more agents behind a single endpoint and you want intent routing, model fallback and trace capture declared in YAML rather than written into each service. Do not adopt it if you have one agent and one provider, because the config file and the extra network hop buy you nothing.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
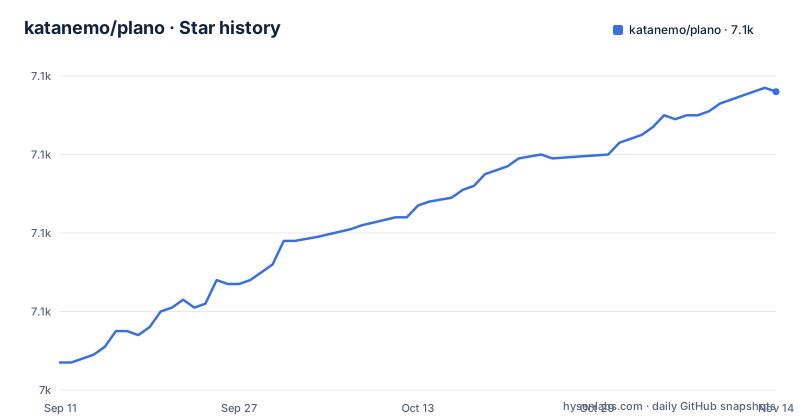
Star history
- katanemo/plano7,116 ★ · +69
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| katanemo/plano | 7k | 7.1k |
69 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Middleware You Write After the Demo Works
The README states the problem directly: building agentic demos is easy, shipping them is hard. The specific work it names is the hidden middleware that appears once a prototype meets real traffic. Routing logic that decides which agent handles a request. Guardrail hooks for safety and moderation. Evaluation and observability glue. Model and provider quirks spread across frameworks and application code. Each of those is small on its own. Together they are the reason a working demo takes months to become a service. Plano's answer is to move them out of the application process and into a separate data plane that sits in front of your agents. The intended reader is an engineer who already has agents running as HTTP servers and does not want to reimplement intent classification, provider adapters or trace instrumentation in every one of them. The README is explicit that this is framework-agnostic: the agents are ordinary servers implementing the OpenAI-compatible chat completions endpoint, in any language.
Agents as OpenAI-Compatible Endpoints Behind a Declared Listener
The architecture is a proxy in front of your own services. You declare agents by id and URL, and you attach natural-language descriptions to them. The README describes what you do not write: intent classifiers, routing logic, model fallbacks, provider adapters, tracing instrumentation. A listener of type agent binds a port and names a router. In the travel example the listener is travel_assistant on port 8001, with router plano_orc. The README says Plano uses purpose-built lightweight LLMs, such as its 4B-parameter orchestrator, for routing. Model providers are declared separately, with a model string like openai/gpt-4o or anthropic/claude-3-5-sonnet, an access_key read from an environment variable, and a default flag. Your agent code then points its OpenAI client at Plano's LLM gateway rather than at a provider. In the sample weather_agent.py the base URL is http://localhost:12001/v1 with the API key set to the literal string EMPTY. So there are two distinct hops: the orchestration listener that picks an agent, and the LLM gateway that picks a provider and model. The README also mentions Filter Chains for jailbreak protection, moderation policies and memory, documented under a separate concepts page.
planoai up and the Config Keys That Matter
Setup is one command and one file. You run planoai up config.yaml after following the prerequisites guide, which covers installing Plano and setting up the environment. The config file opens with version: v0.3.0, which is worth noting because the repository's most recent tagged release is 0.4.39. Whether that version field is validated against the binary or merely informational is something to check rather than assume. The keys that carry the design are agents (id and url), model_providers (model, access_key, default), and listeners (type, name, port, router). Access keys are referenced indirectly as $OPENAI_API_KEY and $ANTHROPIC_API_KEY, so provider credentials stay in the environment rather than in the YAML. Agent descriptions declared in YAML are the routing input, which means the quality of your routing depends on how well you write those descriptions.
The Hosted Router and What It Implies for Production
The README carries an important note: Plano and the Plano family of LLMs, including Plano-Orchestrator, are hosted free of charge in the US-central region for a first-run developer experience. To scale and run in production, you either run those LLMs locally or contact the maintainers for API keys. This is the single most consequential operational detail in the README, and it sits in a callout rather than in the quickstart. The router named in the example config is plano_orc. The practical consequence is that the path of least resistance during evaluation sends routing decisions involving your users' prompts to a hosted endpoint in a specific region. That may be fine for a prototype and unacceptable for a regulated workload. If you adopt Plano, resolving this question comes before anything else.
Where Plano Is the Wrong Tool
Plano adds a network hop and a configuration surface. For a single agent talking to a single provider, that hop buys you nothing you could not get from a client library, and the YAML becomes a second place to look when something breaks. The routing model is also a dependency you do not control: you are trusting a 4B-parameter model to classify intent from descriptions you wrote, so check how it behaves when the router picks the wrong agent. That is a real failure mode. A misrouted request in a customer-facing flow is worse than a slow one. There is also the release cadence: 0.4.37 landed on 2026-09-28, and 0.4.38 and 0.4.39 both landed on 2026-10-24. Frequent patch releases are normal for active projects, but they mean you should pin a version rather than track main. The version field in the sample config, v0.3.0, is well behind that cadence, which suggests config compatibility is not something to take for granted across upgrades.
Compared With Putting a Gateway in Front of Your Providers
The obvious alternative is a conventional LLM gateway or a plain reverse proxy that forwards to providers and handles key management, rate limits and retries. That class of tool solves model agility: one endpoint, many providers, no provider SDKs in your services. Plano does that too, through the same LLM gateway your agent points at. The difference is the orchestration listener. A conventional gateway has no concept of an agent as a routable destination with a natural-language description, so the decision about which service handles a request stays in your application. Plano moves that decision into the proxy and makes it configurable without redeploying agents, which the README frames as adding new agents without modifying app code. If your routing logic is a handful of if-statements that rarely change, the conventional gateway is the smaller dependency. If you are adding agents regularly and each addition means touching a dispatcher, Plano's model is the one that scales with the team rather than with the code.
Licence, Upgrades and What to Pin
Plano is Apache-2.0, which permits commercial use and modification and includes an explicit patent grant. It does not impose copyleft obligations on your own code. This is not legal advice, and the licence text governs. The gap between the sample config's v0.3.0 and the 0.4.x releases is the reason to care about compatibility between config versions and binary versions. Practically, pin the image tag or the binary version in your deployment, keep config.yaml in version control next to the agents it describes, and read the release notes for the versions you skip. The README also points at a Discord for API keys and a docs site for the full quickstart, so the upgrade path for the hosted router is a conversation rather than a documented procedure. That is a cost worth counting before you build on it.
Editorial conclusion
Adopt Plano if you are running two or more agents behind a single endpoint and you want intent routing, model fallback and trace capture declared in YAML rather than written into each service. Do not adopt it if you have one agent and one provider, because the config file and the extra network hop buy you nothing. Before committing, verify whether the plano_orc router from the example config resolves to the hosted US-central endpoint or to a locally run model, and confirm what that means for your data path.
Frequently asked questions
what is plano
In the context of this project, Plano is an AI-native proxy server and data plane for agentic apps, written in Rust and built on Envoy. It centralizes agent routing and orchestration, agentic signals and traces, guardrail filters for safety and moderation, and smart LLM routing APIs.
What does Plano mean for an agentic application?
It means the delivery concerns stop being bespoke code in your repository and move into an out-of-process dataplane. You declare agent URLs and descriptions in YAML; you do not write intent classifiers, routing logic, model fallbacks, provider adapters or tracing instrumentation.
Does Plano run on Envoy, and how is the version pinned?
Yes, Plano is built on Envoy. The Dockerfile sets ENVOY_VERSION to v1.37.8 and carries a comment requiring that value to be kept in sync with the ENVOY_VERSION constant in cli/planoai/consts.py.
Do I need to instrument my agents to get traces?
No. Every request is traced end to end with OpenTelemetry with no instrumentation code needed, because the dataplane sits between your services and the model and observes the hops itself. Agentic signals are captured the same way, with zero-code capture across every agent.
Is the hosted Plano orchestrator free for production use?
Not as stated. Plano and its model family are hosted free of charge in the US-central region for a first-run developer experience, and to scale and run in production you either run those models locally or contact the project for API keys.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/katanemo-plano)Star history chart for your README
[](https://hysenlabs.com/projects/katanemo-plano)Was this useful?