alphafold3-pytorch: the AlphaFold 3 architecture as a trainable PyTorch module
Implementation of Alphafold 3 from Google Deepmind in Pytorch
At a glance
- What is it?
- lucidrains' port of DeepMind's AlphaFold 3 gives you the model and the training loop, not the weights or the pipeline. It is a research component, and the README says so by omission.
- Who is it for?
- Adopt alphafold3-pytorch if you are training or modifying the AlphaFold 3 architecture itself and can supply your own featurisation, weights and compute. Do not adopt it if you want to fold a protein today: the README's usage example ends at `sampled_atom_pos = alphafold3(...)` with no released checkpoint behind it, so there is nothing to run inference with.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 98 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
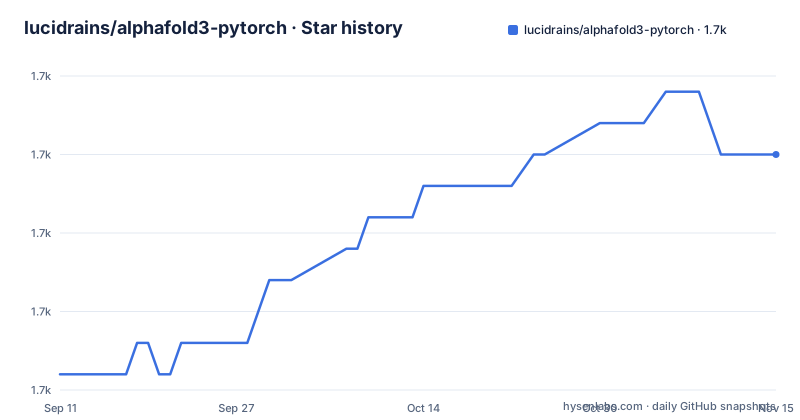
Star history
- lucidrains/alphafold3-pytorch1,700 ★ · +7
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| lucidrains/alphafold3-pytorch | 1.7k | 1.7k |
7 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What alphafold3-pytorch is for, and what it is not
The repository is a PyTorch transcription of the AlphaFold 3 paper. The README describes it plainly as an implementation of the Nature article, and the usage example is a training step, not a prediction call. That framing matters. If you want a tool that takes a sequence and returns a structure, this is not it. The usage block shows mock tensors built with `torch.randn` and `torch.randint` rather than a featuriser that reads a FASTA file or an mmCIF. The audience is researchers who want to train, ablate or extend the architecture, and engineers integrating the model into a larger pipeline they already control. The appreciation list reads like a changelog of corrections to the paper transcription, which tells you the project's centre of gravity: getting the architecture right, not wrapping it in a product.
The Alphafold3 module signature and the tensors it expects
The entry point is a single class. `Alphafold3(dim_atom_inputs = 77, dim_template_feats = 108)` returns a module that you call with a long keyword argument list. On the training path the call takes `num_recycling_steps`, `atom_inputs`, `atompair_inputs`, `molecule_ids`, `molecule_atom_lens`, `additional_molecule_feats`, `additional_msa_feats`, `additional_token_feats`, `is_molecule_types`, `is_molecule_mod`, `msa`, `msa_mask`, `templates`, `template_mask`, `atom_pos`, `distogram_atom_indices`, `molecule_atom_indices`, `distance_labels` and `resolved_labels`, and returns a loss you call `.backward()` on. The README marks `atom_pos` as required for training but omitted on inference. Two details in the example are easy to miss. The atom dimension is padded to the longest molecule with `molecule_atom_lens.sum(dim=-1).amax()`, and both `distogram_atom_indices` and `molecule_atom_indices` are offset by `exclusive_cumsum(molecule_atom_lens)` before being passed in. Getting that offset wrong is the kind of bug that trains quietly and produces a wrong distogram, and the README's own appreciation list records a past issue with molecular atom indices for the distogram loss.
Multiple chains are the default, not a special case
The mock inputs use a batch of two, and `molecule_atom_indices` has shape `(2, seq_len)`, so the model is built around a flat token sequence with per-token molecule identifiers. `is_molecule_types` and `is_molecule_mod` are boolean tensors of width 5 and 4, which is how the implementation distinguishes polymer, ligand and modified residue behaviour without branching the tensor shapes. `molecule_ids` is an integer tensor, and the appreciation list credits a fix for metal ion molecule ID assignment for `Alphafold3Inputs`. That is a small clue about scope: the code is meant to handle ions and non-standard atoms, not just protein chains. The templates tensor is five-dimensional, `(2, 2, seq_len, seq_len, 108)`, with a separate `template_mask`, and the MSA tensor is `(2, 7, seq_len, 32)` with its own mask. Those widths are configuration, not constants, since `dim_template_feats` is a constructor argument. Anyone porting features from another codebase should check the widths against the constructor rather than assuming the README's numbers.
Getting it installed and running the example
Installation is one command: `pip install alphafold3-pytorch`. The usage block imports `Alphafold3` from `alphafold3_pytorch` and `exclusive_cumsum` from `alphafold3_pytorch.utils.model_utils`. The integration surface is the Python API. The only other runnable pieces the README names are a PDB dataset preparation script, a clustering script optimised by a contributor, and a `WeightedPDBSampler` integrated into a `PDBDataset`, plus a gradio frontend contributed by another. Those are described in the appreciation list rather than documented with commands, so treat them as code to read in the repository rather than tools with a stable interface. The README also points to a fork maintained by Alex with full Lightning and Hydra support, which is the practical answer if you want configuration-driven training instead of hand-written argument lists.
Where the implementation stops short
The gap between this repository and a working structure predictor is the featurisation and the weights. The README shows the model consuming prepared tensors and never shows how those tensors are produced from a sequence, an MSA or a template file, beyond naming the PDB scripts. MSA and template parsing support is credited as initial, which is a fair description of a feature that landed through contributions rather than as a designed subsystem. The appreciation list also records several corrections to the transcribed algorithms and to hyperparameters, including inconsistencies with the paper, an issue with the atom diffusion module against the supplementary, and a discrepancy with OpenFold in distogram and template unit vector computations. Those entries are honest and useful, and they also tell you the numerical behaviour has shifted across releases. If you depend on a specific loss value, pin the version. The 0.7.10 and 0.7.11 releases landed about half an hour apart on the same day, which suggests rapid patch cycles rather than a slow, stabilised API.
Alternatives and how they differ
The README names two. MegaFold, from Hoa La and Ahan Gupta, is described as an optimised version using Triton kernels, so the difference is at the kernel level: same architecture, different execution path, aimed at throughput rather than at readability or hackability. The alphafold3-pytorch-lightning-hydra fork from Alex keeps the same model but restructures training around Lightning and Hydra, which trades a plain Python call for a configuration system. Outside the README, the obvious comparison is OpenFold, which the appreciation list mentions only in the context of a distogram and template unit vector discrepancy. That mention is worth noting because it implies the two codebases are close enough in intent that their numerical outputs were compared directly. If you need a maintained training stack with its own data pipeline, that comparison is the one to run yourself.
Licence and the cost of keeping up
The repository is MIT licensed, which permits commercial use and modification provided the copyright notice and permission notice are retained. Note that the licence covers this implementation, not the AlphaFold 3 model weights or the original paper's terms, and this article is not legal advice; check the upstream terms separately if you plan to ship anything derived from DeepMind's release. Maintenance cost is the more practical concern. The last push recorded is 2026-08-10, after the 0.7.12 release in September 2025, so the project is active. Active here means the architecture keeps moving: contributors have corrected the relative positional encoding, the distogram indices, non-standard atom handling in polymer residues, and the atom diffusion module. Each of those is a change you would need to re-validate against your own training runs. Budget for reading the diff between releases rather than treating the version number as a stability signal.
Editorial conclusion
Adopt alphafold3-pytorch if you are training or modifying the AlphaFold 3 architecture itself and can supply your own featurisation, weights and compute. Do not adopt it if you want to fold a protein today: the README's usage example ends at `sampled_atom_pos = alphafold3(...)` with no released checkpoint behind it, so there is nothing to run inference with. Before committing, verify that the PDB preparation and clustering scripts produce inputs that match the tensor shapes shown in the usage block, and check the changelog between 0.7.10 and 0.7.12 for the distogram and template unit vector corrections credited in the appreciation list, since those changed loss behaviour.
Frequently asked questions
What is alphafold3-pytorch?
An MIT-licensed PyTorch implementation of AlphaFold 3 from Google DeepMind, maintained under the lucidrains organisation and installed with pip install alphafold3-pytorch. It requires Python 3.9 or newer and torch 2.1 or newer, and it is built as source you train rather than as a set of published weights.
How is the alphafold3-pytorch model constructed?
From input dimensions rather than a checkpoint. The token-level example passes dim_atom_inputs = 77 and dim_template_feats = 108, while the molecule-level example uses dim_atom_inputs = 3, dim_atompair_inputs = 5, atoms_per_window = 27 and dim_template_feats = 108, with atom coordinates supplied through Alphafold3Input.
How do I prepare PDB data for alphafold3-pytorch training?
Download first-assembly and asymmetric unit complexes from RCSB in mmCIF format, place them under data/pdb_data/unfiltered_assembly_mmcifs/ and data/pdb_data/unfiltered_asym_mmcifs/, then run the filter and cluster scripts for the train, val and test splits. The page recommends a dated AWS snapshot such as 20240101 so the download is reproducible.
Which version of alphafold3-pytorch should I install?
Decide first, because the manifest on main declares 0.8.3 while the newest release tag is 0.7.12 from 2025-09-18, and the last push to main was 2026-08-10. The container image clones the main branch by default rather than a tag, so an image build and a tagged install are not the same code.
Are there maintained forks of alphafold3-pytorch?
The page names two. One is a fork with full Lightning and Hydra support, maintained by a contributor to this repository, and the other is MegaFold, an optimized version that uses Triton kernels. The paper itself, an illustrated guide and a review video are linked from the same page.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/lucidrains-alphafold3-pytorch)Star history chart for your README
[](https://hysenlabs.com/projects/lucidrains-alphafold3-pytorch)Was this useful?