commandcode-proxy: putting Command Code API behind OpenAI and Anthropic endpoints
Reverse proxy exposing the Command Code API as OpenAI- and Anthropic-compatible endpoints.
At a glance
- What is it?
- A single-file Node proxy that re-shapes Command Code API traffic into OpenAI Chat Completions and Anthropic Messages calls, including the device-fingerprint handshake the official CLI performs. It fits one narrow job and carries a memory cost the README quantifies itself.
- Who is it for?
- Adopt it if you already have a Command Code key and need existing OpenAI or Anthropic SDK clients to reach it without rewriting them, and if you can afford the memory headroom the README's own amplification figures imply. Skip it if you need a general-purpose gateway with per-user rate limiting, persistent storage or multi-provider routing; the proxy ships none of that.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 44 days ago.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
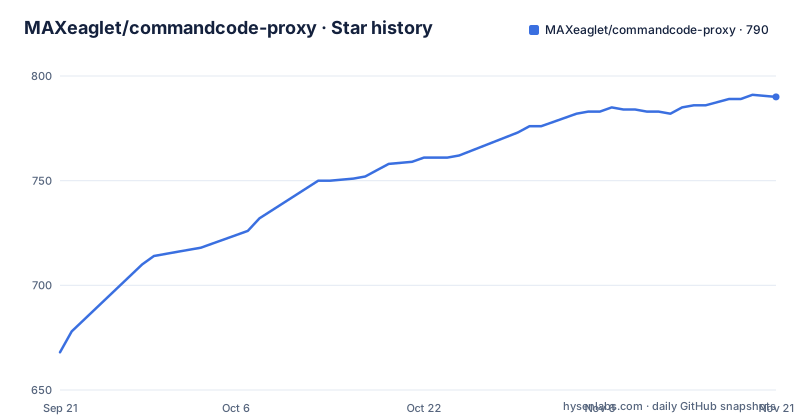
- MAXeaglet/commandcode-proxy790 ★ · +122
| Repository | 2026-09-21 | 2026-11-21 |
|---|---|---|
| MAXeaglet/commandcode-proxy | 668 | 790 |
122 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap commandcode-proxy fills between Command Code and your existing clients
Command Code speaks its own protocol. The README is explicit about why: the proxy was built by analyzing official CLI network traffic, and it replicates the Command Code request protocol including device-fingerprint and lifecycle pre-requests. That matters because an ordinary HTTP client pointed at the upstream base URL will not reproduce that handshake.
The audience is narrow and specific. You have a Command Code API key, the key must start with user_, and you want to keep using tools that already speak OpenAI Chat Completions or Anthropic Messages. Rather than porting a client to a private protocol, you run the proxy locally and change a base URL. The README's own framing is one line: a reverse proxy that converts Command Code API to OpenAI and Anthropic compatible endpoints, single file, zero external dependencies.
Zero external dependencies is a real constraint, not marketing. package.json lists no dependencies block at all, only scripts for start, dev, test and two Docker build targets, with engines requiring Node >=18.0.0. The entire proxy is proxy.mjs, roughly 1900 lines according to the file structure section. There is no framework to audit and no transitive tree to pin.
How the request path works, from Authorization header to upstream abort
The key is not stored. It arrives on each request, either as Authorization or as x-api-key for Anthropic SDKs, and the README notes the value is matched with any prefix, so Bearer token_user_xxx works. config.json does have an apiKey field, but it is described as an optional fallback, which means a shared deployment can avoid baking a key into the file.
On the way out, the proxy rewrites the call into Command Code's shape and adds the headers that shape requires, including x-project-slug, which defaults to cc-proxy. It also runs the fingerprint and lifecycle initialization requests the official CLI performs. That is the part a hand-rolled adapter usually misses.
Several behaviours exist to survive a flaky upstream rather than to transform payloads. Client disconnect detection aborts the upstream request. A zero-output response triggers a 429 auto-retry, and consecutive timeouts trigger the same. Idle timeouts are split by mode: CC_STREAM_IDLE_MS defaults to 30000 for streaming reads, CC_NONSTREAM_IDLE_MS defaults to 90000 for non-streaming. CC_MAX_INFLIGHT caps concurrent in-process requests and defaults to 0, meaning unlimited.
Model discovery is dynamic. With useProviderModels set to true, the proxy fetches the model list from the Provider API and caches it for modelRefreshIntervalMs, default 300000, which is five minutes. The README also states the ZDR header is deliberately not added to the npm version check or to the proxy's own /provider/v1/models catalog request, only to generation and initialization calls.
Installing commandcode-proxy and making a first streaming call
The repository ships a config.json that listens on http://0.0.0.0:3050, so the shortest path is to clone, install nothing, and start it. Node 18 or newer is required by package.json.
npm start        # Start (the repo ships with config.json listening on http://0.0.0.0:3050)
npm run dev      # Watch mode (auto-reload on file changes)
npm start runs node proxy.mjs. npm run dev adds --watch, which reloads on file changes and is the mode you want while editing config.json. There is also npm run test, which runs node --test test/*.test.mjs, and the repository has a test/ directory at the top level.
Once it is up, a first request needs only the key in the header. The README gives this exact example:
curl http://127.0.0.1:3050/v1/chat/completions \
  -H "Authorization: Bearer user_xxxxxxxxx" \
  -H "Content-Type: application/json" \
  -d '{"model":"deepseek/deepseek-v4-flash","messages":[{"role":"user","content":"hi"}]}'
What you should see is a chat.completion object in the OpenAI shape. Add "stream": true to the JSON body and the response becomes SSE: a chunk with delta.reasoning_content first, then delta.content, then a final chunk carrying finish_reason and a usage block that includes prompt_tokens_details.cached_tokens. That cached_tokens field is how the README surfaces cache hit metrics, and it is worth checking on a real key because a zero there tells you the upstream did not report a cache hit.
The container path is separate and does not require Node locally. The Dockerfile builds from node:22-alpine, copies package.json and proxy.mjs, exposes 3050, and sets a healthcheck against /health.
docker build -t commandcode-proxy:latest .
docker compose up
docker-compose.yml maps ${PROXY_PORT:-3050} to 3050 and sets PORT to 3050, with restart: unless-stopped and a wget healthcheck every 30s. The repository also has a GitHub Actions workflow, docker-publish.yml, which publishes multi-arch images to GHCR on v* tags, though the repository has no published GitHub releases.
The 100 MB body limit and the memory amplification the README measures
This is the sharpest limitation in the project, and the README states it plainly rather than burying it. Request bodies are capped at 100 MB independently of config.json; anything larger is rejected with HTTP 413, and the connection is drained rather than reset. CC_MAX_BODY_MB overrides the cap with a positive integer in megabytes.
The cost is amplification. The README reports that a body exists in several copies before it reaches upstream, with measured peak roughly body size times 5.1 to 7.4, giving 7 MB to about 52 MB and 20 MB to about 116 MB. A request rejected with 413 costs only about 1.05 times its size. So the default 100 MB cap implies up to roughly 550 MB for a single request, and the README notes the limit is per-request, not global. Two concurrent large requests are not bounded by that number.
CC_MAX_INFLIGHT is the lever, and its default of 0 means unlimited. On a container without a memory limit, a handful of simultaneous large multimodal payloads can push the process into the OOM killer. Setting CC_MAX_INFLIGHT to a small positive number and lowering CC_MAX_BODY_MB is the documented way to bound it. The README does not document rollback behaviour for in-flight requests when the cap is reached, and it does not describe what happens to a client whose request is queued rather than served.
There is a second, softer limitation. The fingerprint disguise is per-key and auto-refreshed, and the README frames the whole project as built by analyzing official CLI traffic. That is a compatibility bet on an upstream protocol that can change without notice. The repository has no published GitHub releases.
How commandcode-proxy differs from LiteLLM and OpenCode
The obvious alternative is LiteLLM, a Python gateway that maps many providers onto one OpenAI-shaped interface. The difference in approach is direction and scope. LiteLLM is a router: you register providers, keys and budgets, and it decides where a request goes. commandcode-proxy is a one-way adapter for a single upstream. It has no routing table, no spend tracking and no database. It also does not need LiteLLM's Python runtime, since it runs on Node 18 and up with no dependencies.
OpenCode shows up repeatedly in search data about this project, and the comparison is different again. OpenCode is a client, a coding agent that talks to providers. commandcode-proxy is infrastructure that sits underneath such a client. If your goal is to point an agent at Command Code, the proxy is the piece that makes the endpoint look familiar; it is not itself an agent.
The trade-off is honest. You get a small, auditable surface and protocol fidelity, including the fingerprint handshake. You give up the operational features a gateway accumulates: per-user keys, quotas, retries across providers, a UI. If you need those, this is the wrong tool, and no amount of configuration will add them, because there is no plugin surface in a single-file proxy.
Licence and what upgrades cost you
The project is MIT licensed, and both the LICENSE file and the license field in package.json confirm it. MIT is permissive: you can use, modify and redistribute it, including commercially, provided the copyright notice and permission notice travel with copies. That is a summary of the licence text, not legal advice, and if you are redistributing it inside a product you should read LICENSE yourself.
The upgrade cost is low by construction. There is no dependency tree to update, so a vulnerability in a transitive package cannot arrive through this repository. Node >=18.0.0 is the only runtime constraint, and the Dockerfile pins node:22-alpine, which means container users get patch updates on rebuild.
What you do carry is protocol drift. Because the proxy replicates Command Code's request protocol, an upstream change to that protocol is a breaking change here, and the fix is a code change in proxy.mjs rather than a version bump. The repository has a test/ directory and an npm test script, which helps, but the repository has no published GitHub releases, so there is no changelog to scan before pulling. Pin a commit hash if you deploy this, and re-read proxy.mjs around the fingerprint and lifecycle code when you move that pin.
Editorial conclusion
Adopt it if you already have a Command Code key and need existing OpenAI or Anthropic SDK clients to reach it without rewriting them, and if you can afford the memory headroom the README's own amplification figures imply. Skip it if you need a general-purpose gateway with per-user rate limiting, persistent storage or multi-provider routing; the proxy ships none of that. Before trusting it in production, send one streaming request with tools through /v1/chat/completions, then inspect the usage block for prompt_tokens_details.cached_tokens to confirm the upstream is returning cache metrics rather than zeros.
Frequently asked questions
What does Command Code do, and what does commandcode-proxy add to it?
Command Code is the upstream API the proxy targets, with a base URL of https://api.commandcode.ai by default. The proxy converts it to OpenAI Chat Completions and Anthropic Messages compatible endpoints so existing clients can call it.
Is commandcode-proxy legit?
It is an MIT licensed repository whose README states it was built by analyzing official CLI network traffic to replicate the Command Code request protocol. It stores no API key by default, since the key is passed per request via the Authorization or x-api-key header.
How can I use Command Code in OpenCode?
The README does not document an OpenCode integration. What it documents is an OpenAI-compatible endpoint at /v1/chat/completions, so the workable path is pointing a client that speaks that format at the proxy's address.
How do I check whether the commandcode-proxy server is running?
The Dockerfile and docker-compose.yml both define a healthcheck that runs wget --spider against http://127.0.0.1:3050/health every 30 seconds. The compose file also sets restart: unless-stopped, so the container restarts on failure.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/maxeaglet-commandcode-proxy)Star history chart for your README
[](https://hysenlabs.com/projects/maxeaglet-commandcode-proxy)Was this useful?