gpt-instruct: a Codex prompt pack with A/B/C release gates and a rollback path
A Codex jailbreak prompt and test pack for GPT.
At a glance
- What is it?
- gpt-instruct ships a stable Codex instruction file (gpt-5.6-sol-v45) and two pre-releases (gpt-6-astra-v2-rc1 and gpt-6.1-sol-v1-rc2), a Python installer that edits config.toml, and a three-tier evaluation gate. The catch is in the project's own numbers: both pre-releases fell short of the tier B hard threshold, so tier C was not run.
- Who is it for?
- Adopt gpt-instruct if you already run Codex with a custom model_instructions_file and you want a versioned prompt plus a one-command rollback; the stable line, gpt-5.6-sol-v45, is the one to start with. Do not adopt it if you need a candidate that cleared the project's own A/B/C gates, because neither pre-release did: gpt-6-astra-v2-rc1 reached 42/50 non-cloud B cases and gpt-6.1-sol-v1-rc2 reached 34/50, and C was not run for either.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 42 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
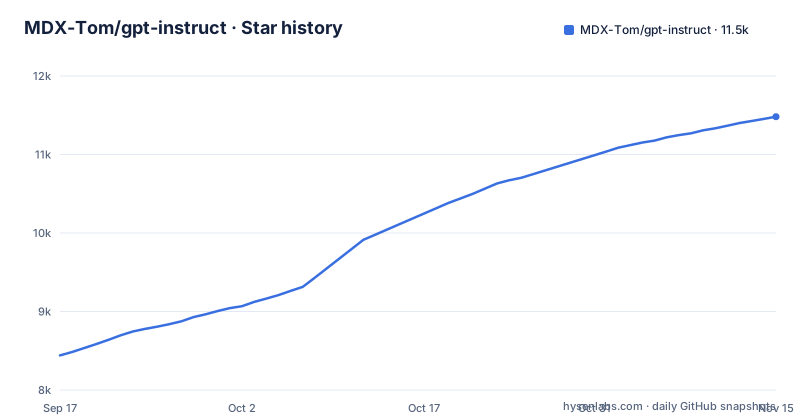
Star history
- MDX-Tom/gpt-instruct11,481 ★ · +3,040
| Repository | 2026-09-17 | 2026-11-15 |
|---|---|---|
| MDX-Tom/gpt-instruct | 8.4k | 11.5k |
3,040 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What gpt-instruct actually changes about a Codex session
Codex accepts an instruction file through configuration rather than through a patched binary. gpt-instruct is a distribution channel for those files: three prompt documents, a Python script that writes the right key into config.toml, and an evaluation harness that scores candidate prompts against fixed suites. The README states the goal plainly, saying the project targets "复杂任务的首轮执行、过程连续性、工件验证和可运行回滚" (first-pass execution on complex tasks, process continuity, artifact verification, and a workable rollback).
The audience is narrow. You need a Codex installation you are allowed to reconfigure, a Python 3 interpreter, and tolerance for the project's own warning that custom model instructions carry account risk and that it suggests using a throwaway account. The README also states the project uses Codex's official configuration mechanism and does not modify binaries, hijack network traffic, or tamper with processes. That matters for anyone evaluating it in a managed environment: the change surface is one TOML key and one Markdown file.
Three product lines ship side by side. gpt-5.6-sol-v45 is described as the current stable production version, with the original v45 prompt bytes preserved and only filenames and branding normalized. gpt-6-astra-v2-rc1 is the first pre-release of gpt-6-astra v2, byte-identical to e8b16, and gpt-6.1-sol-v1-rc2 is the second pre-release of the gpt-6.1-sol line, also byte-identical to e8b16. The superseded Astra v1 and 6.1 rc1 are archived in historical-versions/. The distinction is not cosmetic: the stable line is the one the project treats as deployable, while the two pre-release lines are still being measured.
How the installer, the prompt file and config.toml fit together
The mechanism is deliberately thin. codex-instruct.py selects a version, locates the Codex home directory, copies the corresponding Markdown prompt into place, and records the pre-deployment state so a reset is possible. The README notes that --reset restores only the model_instructions_file that this project manages, and does not overwrite provider, model, or authentication settings. A full configuration snapshot exists but is described as being for manual emergencies only, restored explicitly through --restore-snapshot.
Manual deployment is documented as two steps: unzip the release archive, copy the prompt into CODEX_HOME, and add one key at the top level of config.toml. Rollback is the inverse: delete or comment out that line, and optionally remove the Markdown file. That is the whole runtime contract. There is no daemon, no proxy, no wrapper around the Codex process.
The evaluation side is where the repository gets heavier. The A/B/C gate defines three tiers. Tier A covers 3 original samples plus 1 model-line-aware prompt_instruct probe on the current checkout, run as two fresh passes with manual review of all four cases, 2/2 technical artifacts, and zero modifications to the target. Tier B covers 66 issue-regression cases across 74 turns and requires a clean sweep. Tier C covers 120 original medium-reasoning samples and runs only after A and B both pass. Candidates advance tier by tier, and the README says each candidate must run A first, then B family by family.
One detail worth flagging: the evaluation scripts keep a gpt56_sol filename prefix for compatibility with historical results, but new development runs must pass --model gpt-6-astra or --model gpt-6.1-sol explicitly, with reasoning fixed at medium. Filenames that no longer match their contents are a real source of confusion when you are reading a results table six months later.
Installing gpt-instruct and deploying your first prompt
Clone the repository first. The README gives this as the starting point, and the installer script lives at the repository root.
git clone https://github.com/MDX-Tom/gpt-instruct.git
cd gpt-instruct
Before writing anything into your Codex configuration, run the dry-run form. The README uses the version string gpt-5.6-v45 here, which is the value the script expects for the stable line even though the file is named gpt-5.6-sol-v45.md. Running this prints what would change and leaves config.toml untouched.
python3 codex-instruct.py --apply --version gpt-5.6-v45 --dry-runWhen the preview looks right, drop the flag. The README states that --apply alone behaves identically to this command.
python3 codex-instruct.py --apply --version gpt-5.6-v45For the astra pre-release the version string is gpt-6-v2-rc1. The README notes the archive contains gpt-6-astra-v2-rc1.md.
python3 codex-instruct.py --apply --version gpt-6-v2-rc1If you prefer to place the file yourself, the manual route is documented. Extract the ZIP, copy the prompt into CODEX_HOME, and set this key at the top level of config.toml.
model_instructions_file = "./gpt-5.6-sol-v45.md"To undo a manual deployment, remove or comment out that line and delete the Markdown file. The scripted path has its own undo, which touches only the key this project manages.
python3 codex-instruct.py --resetThe README publishes SHA256 values for its three archives, c86c2c6d20a4d1155d87422f485eb37b77539132270918c002b5d8237a5adf54 for gpt-5.6-sol-v45.zip, 5c1d96f9aee25393af60245ac6c40b7850f641083a5162cad85762beedd6fc9d for gpt-6-astra-v2-rc1.zip and 007b8c5858110b809e5b90cd2c18bdc6965246aaee5af170b5487818b7055364 for gpt-6.1-sol-v1-rc2.zip. Verify them before deploying. If you want to run the harness yourself, the README extracts the script archives and then invokes the regression runner.
for archive in scripts/*.zip; do unzip -o "$archive" -d scripts; done

python3 scripts/run_gpt56_sol_issue_regression.py --dry-run \
  --model gpt-6-astra --reasoning medium
python3 scripts/verify_gpt56_sol_regression_scoring.py
python3 -m unittest discover -s unit-tests -q
The release gate that gpt-6-astra-v1 did not clear
The README is unusually candid here, and it is the single most important thing to read before deploying either pre-release. It states that gpt-6-astra-v2-rc1 is byte-identical to e8b16, that both fresh A runs scored 3/4, that tier B on the five non-cloud families reached 42/50 cases and 48/56 turns, that three repeated cloud runs reached 23/48 attempts and 29/54 turns, and that artifact gates were 16/16. gpt-6.1-sol-v1-rc2 reports non-cloud B of 34/50 cases and 40/56 turns, cloud repeats of 22/48 attempts and 28/54 turns, and artifact gates of 15/16. Tier C was not run for either. The B threshold is 66/66 cases and 74/74 turns, so both were published as pre-releases, and the README says the release decision does not rewrite a pre-release as the stable default.
Treat this as the practical limitation. If your selection criterion is "the prompt that passed the project's own regression suite," neither pre-release satisfies it. What you can rely on is the stable line's status as the production version and the pre-releases' stated scores. What you cannot rely on is a claim that either pre-release is measurably better than v45, since the README says results are comparable only under identical model, reasoning level, and method identity, and the two lines use different model identities.
Where gpt-instruct is the wrong tool
Several cases make it a poor fit. If you do not use Codex, nothing here applies: the deployment target is Codex's configuration, and the prompt files are written for that runtime. If you need a prompt you can drop into an arbitrary API call, the repository does not present itself that way.
If your environment forbids account-level experimentation, the README's own warning is disqualifying. It states that jailbreak activity and custom model instructions carry account risk and recommends throwaway accounts. That is not a caveat you can engineer around with better testing; it is a property of the activity.
If you need a candidate that cleared every gate, neither pre-release is it, and the README does not claim otherwise. And if you need deterministic, reproducible scores tied to a pinned transport and method identity, note that the maintenance principles forbid stitching results across identities, which means any number you see is only valid for the exact model, reasoning level, and transport recorded alongside it. Copying a pass rate into a different context is exactly the practice the project prohibits.
Finally, the evaluation harness runs models. The README states tests execute only in throwaway HOME, CODEX_HOME, XDG, and TMPDIR directories with synthetic fixtures. If you run the scripts outside that isolation, you are outside the documented conditions, and the results are yours to defend.
How this differs from keeping your own instruction file
The obvious alternative is a hand-maintained instruction file: write your own Markdown, point model_instructions_file at it, edit it when something breaks. The difference is not the prompt format, which is identical, but the surrounding process. gpt-instruct versions its prompts with explicit epoch naming (up to 20 betas per epoch, with evidence names formatted as gpt-6-astra-v1-e<epoch>b<attempt> for Astra and gpt-6.1-sol-e<epoch>b<attempt> for 6.1, and pre-releases such as gpt-6-astra-v2-rc1), keeps superseded releases in historical-versions, and pairs each candidate with a modification record, a diff, verification notes, and a runnable rollback.
A second alternative is a general prompt-management library that stores templates and versions them in a database or a hosted service. Those tools solve retrieval and templating; gpt-instruct solves measurement. The harness runs fixed suites and separates genuine model failures from network, capacity, account, or provider-policy interruptions. A template store will not tell you that your prompt regressed on 14 of 66 cases.
The cost of the gpt-instruct approach is that you inherit its methodology. Its rules include preserving original outputs and method SHAs, banning cross-identity score splicing, and refusing to let a single case's wording contaminate the general prompt. Those constraints are the reason the results are interpretable, and they are also why the project cannot simply declare v1 a success.
Maintenance, licensing and what an upgrade costs you
The repository is not archived, and the last push was on 2026-10-04. Release cadence is visible in the release list: gpt-5.6-instruct v42 on 2026-07-29, v45 on 2026-08-06, and gpt-6-astra v1 on 2026-09-06. That is roughly one release per week to one per month across the two lines. The README also notes a synchronization rule requiring README.md and README_EN.md to be updated together, with matching language versions of every diagram, which is a maintenance burden the maintainer has accepted in writing.
The upgrade cost is low by design. A version change is one script invocation, and the rollback is one more. The real cost sits in verification: if you want to know whether a new candidate is better, you run the A/B/C ladder, and tier B alone is 66 cases across 74 turns with declared artifacts checked.
Licensing is MIT, per the LICENSE file and the badge in the README. That permits commercial use and modification with attribution and without warranty. Separately, the README carries a statement that the project will not be used for commercialization including fundraising promotion, technology licensing, and paid technical services. That is a project statement about intent, not a license term, and the two are not the same instrument. If the distinction matters to your organization, have counsel read both documents rather than relying on either summary.
Editorial conclusion
Adopt gpt-instruct if you already run Codex with a custom model_instructions_file and you want a versioned prompt plus a one-command rollback; the stable line, gpt-5.6-sol-v45, is the one to start with. Do not adopt it if you need a candidate that cleared the project's own A/B/C gates, because neither pre-release did: gpt-6-astra-v2-rc1 reached 42/50 non-cloud B cases and gpt-6.1-sol-v1-rc2 reached 34/50, and C was not run for either. Before deploying anything, clone the repository, run the dry-run command for the version you want, and confirm the SHA256 of the ZIP you downloaded matches the value printed in the README. Then check whether your Codex setup reads model_instructions_file at the top level of config.toml, because the manual path depends on that key and nothing else.
Frequently asked questions
How do I install gpt-instruct for Codex?
Clone the repository, then run python3 codex-instruct.py --apply --version gpt-5.6-v45 for the stable line or --version gpt-6-v2-rc1 for the astra pre-release. A --dry-run flag previews the change without writing to your configuration.
What is InstructGPT and is gpt-instruct the same thing?
The README does not describe InstructGPT or claim any relationship to it. gpt-instruct is a Codex prompt pack and evaluation harness distributed under MIT, with three prompt files and a Python deployment script.
How do I instruct Codex with gpt-instruct?
Point Codex at the prompt file by setting model_instructions_file at the top level of config.toml, for example "./gpt-5.6-sol-v45.md", or let codex-instruct.py write that key for you. Running the script without arguments opens an interactive menu.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mdx-tom-gpt-instruct)Star history chart for your README
[](https://hysenlabs.com/projects/mdx-tom-gpt-instruct)Was this useful?