Meta's llama repo is deprecated: what Llama 2 inference code still offers and where to go next
GitHub describes it as Inference code for Llama models. The repository metadata lists Python as its primary language. The metadata lists the NOASSERTION license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- The original inference code for Llama 2 models is now marked as deprecated, replaced by the Llama Stack ecosystem. This review covers what the repo actually does, how to run it, and why most new projects should look elsewhere.
- Who is it for?
- Use this repo only if you need to run Llama 2 7B, 13B, or 70B weights locally with minimal dependencies and you are comfortable with the deprecated status. Do not start a new project here: the README explicitly redirects to llama-models, llama-toolchain, and llama-agentic-system for current work.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Probably not. The repository last received commits 21 months ago, on January 26, 2025.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
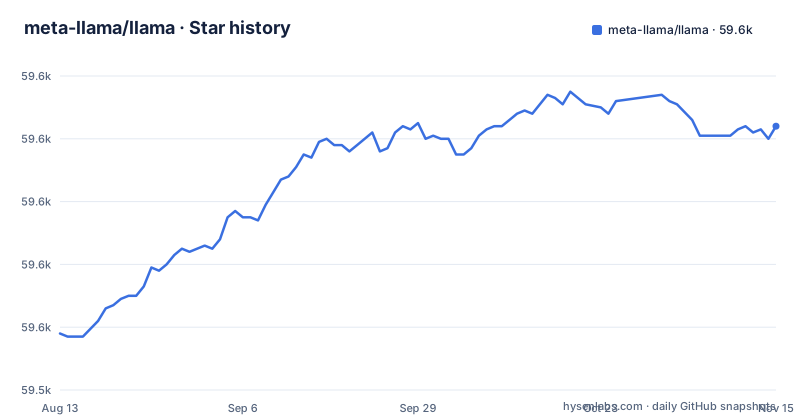
Star history
- meta-llama/llama59,624 ★ · +66
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| meta-llama/llama | 59.6k | 59.6k |
66 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A repository that announces its own end
The first thing you see in the README is not a feature list but a deprecation notice. Meta states that as part of the Llama 3.1 release, they consolidated GitHub repos and expanded Llama into an end-to-end Llama Stack. The original meta-llama/llama repo is now described as deprecated. That changes the value proposition immediately. You are not adopting a living project. You are looking at a frozen snapshot of how Llama 2 inference was done in 2023. The README still calls itself a minimal example to load Llama 2 models and run inference, but the surrounding ecosystem has moved on. For an engineer evaluating this repo, the deprecation notice is the most important fact. It tells you that maintenance, bug fixes, and new features will not come here. The repository has no GitHub releases, and the last push was on 2025-01-26, which reinforces the static nature. If you need a stable, supported inference path, this is not it.
What the code actually does: a minimal generation loop
The repository contains Python code for loading Llama 2 model weights and running two kinds of inference: text completion and chat completion. The core logic lives in llama/generation.py, which the README references when describing the chat format. The model uses a tokenizer.model file, a SentencePiece-style tokenizer, and the generation code handles the pre-allocation of a cache based on max_seq_len and max_batch_size. The inference is not a server or an API. It is a script you run with torchrun. The example_chat_completion.py and example_text_completion.py files are the entry points. The chat models require a specific formatting with INST and <<SYS>> tags, BOS and EOS tokens, and careful whitespace. The README warns that you should call strip() on inputs to avoid double-spaces. That level of detail matters because it shows the code is not a general-purpose chatbot framework. It is a narrow reference implementation for one model family.
Getting it running: exact commands and their constraints
The README gives a concrete path. First, clone the repo and run pip install -e . in a conda environment with PyTorch and CUDA available. Then you must request access to the model weights from the Meta website. After approval, you receive a signed URL by email. You run ./download.sh and paste that URL when prompted. The link expires after 24 hours and a limited number of downloads, so if you see 403: Forbidden, you need to re-request. Once the weights are downloaded, inference is a torchrun command. For the 7B chat model, the command is: torchrun --nproc_per_node 1 example_chat_completion.py --ckpt_dir llama-2-7b-chat/ --tokenizer_path tokenizer.model --max_seq_len 512 --max_batch_size 6. The nproc_per_node value must match the model-parallel (MP) value: 1 for 7B, 2 for 13B, and 8 for 70B. That means a 70B model requires 8 GPUs or nodes, which is a hard hardware constraint. The max_seq_len and max_batch_size are not free parameters; they determine the pre-allocated cache size, so you must set them according to your memory. The README also notes that all models support sequence length up to 4096 tokens, but the cache is pre-allocated, so you cannot exceed the values you pass.
The chat format is a trap for the unwary
The fine-tuned chat models are not forgiving about input formatting. The README states that to get the expected features and performance, you must follow a specific formatting defined in chat_completion, including the INST and <<SYS>> tags, BOS and EOS tokens, and the whitespaces and breaklines in between. If you just feed plain text, the model will not behave as a chat assistant. This is a genuine limitation. The repository provides example_chat_completion.py, which presumably handles the formatting, but if you want to integrate the model into your own pipeline, you have to replicate that logic. The README also mentions that you can deploy additional classifiers for filtering unsafe inputs and outputs, but it points to the llama-cookbook repo for an example, not to code in this repo. So the safety story is external. For a production system, that means you need to pull in another project. The deprecation makes this worse, because the external examples may drift from this codebase.
Where it fails: hardware, licensing, and the download wall
The biggest failure mode is the download process. You cannot just pip install and go. You must register on the Meta website, accept a license, wait for email approval, and then use a signed URL that expires in 24 hours. The README warns against using the Copy Link option and tells you to manually copy the link from the email. That is a manual, error-prone step. If you are automating model deployment, this is a blocker. GitHub's licence metadata reads NOASSERTION, but the repository contains a LICENSE file and setup.py says the software is distributed under the terms of the Llama 2 Community License Agreement. The README says you must accept the license on the Meta website to download the weights. The hardware requirement is another wall: the 70B model needs 8 GPUs for model parallelism. Even the 13B needs 2. For a single-GPU developer, only the 7B models are practical. The repository also does not include any fine-tuning code, only inference. If you need to adapt the model, this is the wrong tool.
The alternative: llama-recipes and the Llama Stack
The README itself points to the alternatives. For more detailed examples leveraging Hugging Face, it directs you to the llama-cookbook repo, which is now at github.com/meta-llama/llama-recipes. That repo contains community-driven scripts and integrations, including an example of how to add a safety checker to inference code. The difference in approach is significant: the original repo uses a custom tokenizer and a torchrun script, while llama-recipes works with Hugging Face's transformers library. The README also lists llama-models for model cards and licenses, llama-toolchain for inference and fine-tuning interfaces, and llama-agentic-system for building agentic applications. So if you want current support, you should ignore the deprecated repo entirely and start with llama-recipes. The trade-off is that llama-recipes is a broader project with more moving parts, whereas the original repo is a single, self-contained example that is easier to read.
Maintenance and upgrade cost: plan for a rewrite
Because the repo is deprecated, the maintenance cost is effectively zero from Meta's side. There will be no updates, no security patches, and no compatibility fixes for new PyTorch versions. If you build on this repo, you own the maintenance. The upgrade path is not incremental; it is a migration to a different repository. The README's deprecation notice lists five repos to use going forward, which means any code you write against this repo will need to be ported. The chat formatting logic, the tokenizer handling, and the torchrun invocation are all specific to this codebase. The license implications are also a cost. The model weights require acceptance of Meta's license on the Meta website, and the repo ships a LICENSE file and a USE_POLICY.md, so read them before commercial use. In short, the only reason to use this repo is to study how Llama 2 inference works internally or to run a quick local experiment with a 7B model. For anything else, the deprecation notice is your sign to go elsewhere.
Editorial conclusion
Use this repo only if you need to run Llama 2 7B, 13B, or 70B weights locally with minimal dependencies and you are comfortable with the deprecated status. Do not start a new project here: the README explicitly redirects to llama-models, llama-toolchain, and llama-agentic-system for current work. Before adopting, verify that your hardware can handle the model-parallel requirements (1, 2, or 8 GPUs depending on size) and that the 24-hour download link from Meta still works. If you need Hugging Face integration, safety filters, or fine-tuning support, go directly to llama-recipes or the Llama Stack repos instead.
Frequently asked questions
How do I run a Llama model locally using this repository?
Clone into a conda environment that already has PyTorch and CUDA, run `pip install -e .`, request the weights from the Meta website, pass the emailed URL to `./download.sh`, then launch an example with torchrun using the model parallel value for your model size, 1 for the 7B, 2 for the 13B, 8 for the 70B.
Should I still use the meta-llama/llama repository for new work?
The readme opens with a deprecation notice that redirects to five repositories, llama-models, PurpleLlama, llama-toolchain, llama-agentic-system and llama-cookbook, and the document itself is headed as deprecated for Llama 2, with the last push on 2025-01-26 and no GitHub releases.
What does installing the Llama inference code actually pull in?
Four unpinned packages from requirements.txt, torch, fairscale, fire and sentencepiece, installed as an editable install by a setup script that declares the name llama at version 0.0.1 and reads its install requirements from that file, on top of a PyTorch and CUDA environment you have to provide.
Why does downloading Llama 2 weights fail with 403 Forbidden?
The download URL is a signed link sent by email that the readme says expires after 24 hours and after a certain number of downloads, so the stated remedy is to re-request a link. The readme also asks that the link be copied manually from the email rather than with the browser's Copy Link option.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/meta-llama-llama)Star history chart for your README
[](https://hysenlabs.com/projects/meta-llama-llama)Was this useful?