Big List of Naughty Strings: A Practical Input Fuzzing Corpus for QA Teams
GitHub describes it as The Big List of Naughty Strings is a list of strings which have a high probability of causing issues when used as user-input data.. The repository metadata lists Python as its primary language. The metadata lists the MIT license. This article stays within the project description and details documented in the GitHub repository README.
At a glance
- What is it?
- A review of the Big List of Naughty Strings, a curated set of problematic user-input strings for automated and manual QA testing. The project provides a simple text file and JSON array, but its real value depends on how you integrate it into your test pipeline.
- Who is it for?
- Adopt this list if you own and manage the software under test and need a quick, low-cost way to surface input-handling bugs during manual or automated QA. Do not rely on it as a substitute for formal security or penetration testing, and be cautious when using it against third-party services, as some strings may indicate security vulnerabilities and could be illegal to use.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Probably not. The repository last received commits 31 months ago, on April 18, 2024.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
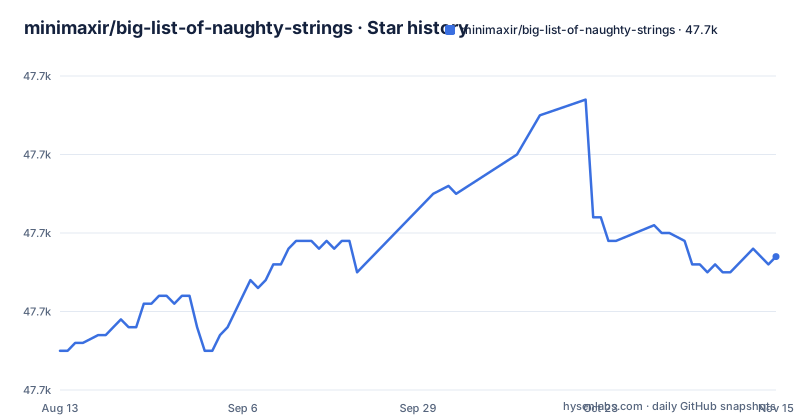
- minimaxir/big-list-of-naughty-strings47,717 ★ · +12
| Repository | 2026-08-13 | 2026-11-15 |
|---|---|---|
| minimaxir/big-list-of-naughty-strings | 47.7k | 47.7k |
12 Stars in the last 94 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What the List Actually Contains
The Big List of Naughty Strings is a curated collection of strings that are likely to cause problems when used as user input. The README describes it as an evolving list intended for automated and manual QA testing. The primary artifact is a plain text file called blns.txt, which is newline-delimited. Comments, preceded by a hash symbol, divide the strings into sections for easier manual reading. A companion file, blns.json, contains the same strings as an array with all comments stripped out, making it suitable for programmatic access. The project also includes a Python script in the scripts folder that generates the JSON from the text file. This is not a library or a framework; it is a data file with a small supporting script. The value lies in the content of the list, not in any runtime logic.
The Problem It Solves: Unexpected Input Handling
The core problem is that even well-tested software often fails on unusual input. The README gives a concrete example: trying to tweet a zero-width space (U+200B) on Twitter caused an internal server error. That error is not malicious, and typical users are not typing zero-width spaces, but it reveals a deeper issue in string validation. The list aims to help testers find such bugs before users do. It is for QA engineers and developers who want a quick way to check how their application handles unexpected input. The list is not a security tool per se, but some strings can indicate security vulnerabilities, so the README includes a disclaimer about using it only on software you own and manage.
How the Data Is Organized and Used
The blns.txt file is the source of truth. Each line is either a comment or a string. Comments start with a hash and are used to divide strings into sections for easy manual reading. For manual testing, you can open the file and copy strings directly into input forms. For automated testing, you would read the file line by line, skipping lines that start with a hash, and feed each string into your test input. Alternatively, you can parse blns.json, which is a simple array of strings, making it easy to load in any language. The Python script in the scripts folder is an example of how to generate the JSON, but you can use any tool to convert the text file. The format is deliberately simple, which is both a strength and a limitation, as discussed later.
Getting It Running: Commands and Integration
Since this is a data file, running it is more about integrating it into your test suite. The README does not provide installation commands, but the repository is on GitHub, so you can clone it with git clone https://github.com/minimaxir/big-list-of-naughty-strings.git. After cloning, you have blns.txt and blns.json. For a quick manual test, you can open blns.txt and copy a string into a form. For automated testing, you can read the JSON in Python with json.load(open('blns.json')) and iterate over the list. The README mentions that the scripts folder contains a Python script used to generate blns.json, so if you modify blns.txt, you can regenerate the JSON by running that script. However, the exact command is not specified, so you would need to inspect the script. The project also lists third-party packages for Node, .NET, PHP, and C++, which wrap the list for easier use in those ecosystems. Those packages are maintained by outside parties, so their reliability may vary.
Limitations and Failure Modes
The list has several practical limitations. First, the README explicitly states that it is not a fully comprehensive substitute for formal security or penetration testing. It is a starting point, not a complete solution. Second, the contribution guidelines impose constraints on what can be added: no strings longer than 255 characters, no EICAR test string because it can trigger antivirus software, and no null character (U+0000) because it changes the file format on GitHub to binary. These constraints are sensible for maintaining the file's usability, but they mean the list excludes some potentially useful test cases. Third, the list is static and only updates when someone submits a pull request. The last push was on 2024-04-18 and the repository has no GitHub releases, so you cannot rely on frequent updates. Finally, the disclaimer warns that using some strings against third-party software may be a crime, which is a serious legal consideration for any QA team. If your test environment includes third-party services, you must be careful about what you send.
Alternatives and How They Differ
The most direct alternative is to build your own list of edge-case strings, but that requires significant effort to cover the same breadth. A more formal alternative is to use a fuzzing framework that generates random inputs, such as AFL or libFuzzer, which are not mentioned in the README but are common in the industry. Those tools differ fundamentally in approach: they mutate inputs automatically to find crashes, whereas the Big List is a hand-curated set of known problematic strings. The curated list has the advantage of being readable and manually reviewable, but it lacks the automated discovery capability of a fuzzer. For security-focused testing, you might use a dedicated security scanner that checks for SQL injection, XSS, and similar vulnerabilities, which would be more targeted than a generic list of strings. The choice depends on whether you need comprehensive coverage (fuzzing) or a quick, human-readable checklist (this list).
Maintenance, License, and Upgrade Cost
The project is licensed under MIT, which means you can use, modify, and distribute it freely, with attribution. There are no release artifacts, so you track the master branch on GitHub. The maintenance cost is low because the list is just a text file, but you need to periodically pull updates to get new strings. The contribution guidelines require that any pull request update all files (the README says to update all files), which keeps the data consistent but adds a small burden for contributors. The README lists third-party packages for several languages, but those are maintained by others, so their update cadence may differ from the main repository. If you use the Python script to regenerate JSON, you need to ensure your Python environment is compatible. Overall, the upgrade cost is minimal: clone, copy, and test.
Editorial conclusion
Adopt this list if you own and manage the software under test and need a quick, low-cost way to surface input-handling bugs during manual or automated QA. Do not rely on it as a substitute for formal security or penetration testing, and be cautious when using it against third-party services, as some strings may indicate security vulnerabilities and could be illegal to use. Before adopting, verify that your test harness can read the newline-delimited format, handle the zero-width space and other Unicode edge cases, and that you have a process to update the list as it evolves. The list is not comprehensive, so treat it as a starting point, not a final answer.
Frequently asked questions
What is the Big List of Naughty Strings used for?
It is a list of strings with a high probability of causing issues when used as user-input data, intended for both automated and manual QA testing. The stated example is Twitter returning an internal server error when you try to Tweet a zero-width space (U+200B), a bad input that even multi-billion dollar companies with extensive automated testing miss.
How do I load the Big List of Naughty Strings in a test?
Use blns.json, an array with all the comments stripped out, and submit one element at a time as input. blns.txt is the manual form, newline-delimited with comments introduced by # that separate the strings into sections for reading and copy and paste.
Is it safe to run the Big List of Naughty Strings against other people's software?
The project states the list is intended for software you own and manage, notes that some of the strings can indicate security vulnerabilities, and says using such strings with third-party software may be a crime, with the maintainer not responsible for resulting actions. It also states the list is not a fully comprehensive substitute for formal security or penetration testing.
How do I add my own string to the Big List of Naughty Strings?
Open a pull request adding the string or a new section, and update all files in that same pull request. The project refuses strings of 255 or more characters, the EICAR test string, anything that alters the encoding of blns.txt, and a null character (U+0000) because it turns the file binary on GitHub.
How does the Big List of Naughty Strings differ from SecLists?
SecLists collects many categories of payloads for security testing, while this project is one file of user-input strings aimed at QA on your own product. The project states it is not a comprehensive substitute for formal security or penetration testing, so the two serve different steps in the same process.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/minimaxir-big-list-of-naughty-strings)Star history chart for your README
[](https://hysenlabs.com/projects/minimaxir-big-list-of-naughty-strings)Was this useful?