Bugbug: Mozilla's Bugzilla ML platform, and what it assumes about your tracker
Platform for Machine Learning projects on Software Engineering
At a glance
- What is it?
- Bugbug is a Python platform for training classifiers over Bugzilla and repository history, from assignee suggestion to test selection. Its value depends on having Mozilla-shaped data: a large Bugzilla instance and a mozilla-central clone.
- Who is it for?
- Adopt Bugbug if you run a large Bugzilla instance and can supply repository history, and you want pretrained classifiers rather than a from-scratch pipeline. Do not adopt it if your issues live in GitHub Issues, Jira, or GitLab, or if you need a supported release artifact.
- Can I use it commercially?
- Yes, with conditions. MPL-2.0 is a weak copyleft licence: you can use it inside commercial and closed-source software, but if you distribute changes to its own files, you must publish those changes under the same licence.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
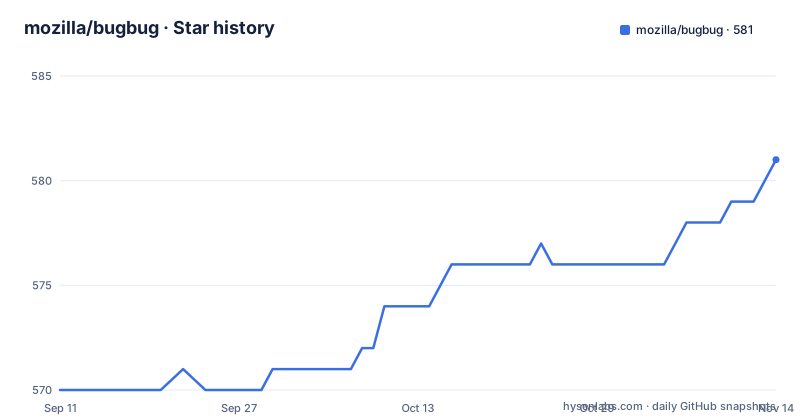
- mozilla/bugbug581 ★ · +11
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| mozilla/bugbug | 570 | 581 |
11 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The triage work Bugbug tries to remove
Bugzilla at Mozilla's scale produces a stream of incoming bugs that need an assignee, a product and component, a judgement about whether the report is a real defect or a feature request, and a decision about whether QA or developer documentation is required. Each of those is a small classification task that a human does by reading the summary and comments. Bugbug's premise is that these decisions are repetitive enough to model. The README lists classifiers for assignee suggestion, component assignment, defect versus enhancement versus task, regression detection, regressor detection, spam, steps-to-reproduce, tracking, uplift approval, and test selection, among others.
The audience is narrow. This is not a general issue-triage toolkit. Every classifier named in the README is defined over Bugzilla bug fields and Mozilla workflow concepts such as uplift approval and the regression keyword. A team running GitHub Issues has no uplift field to predict and no regression keyword to correct. The data the project generates is separable from the platform, though: the README points to docs/data.md and states that data generated by Bugbug to train the models can be used independently from Bugbug. That is the more portable artifact.
How a classifier is produced: dataset, trainer, model, CLI
The architecture visible in the README is a pipeline rather than a service. A dataset is assembled from Bugzilla records and repository history. A training script consumes it and writes a model. A separate classifier script loads a model and scores a single bug.
Training is invoked as python -m scripts.trainer, and the README warns that it takes 30 minutes or more. The defect model is documented with a concrete dataset size and result: 2110 bugs, accuracy around 93 percent, precision around 95 percent, recall around 94 percent. Those numbers are worth reading carefully. A dataset of 2110 bugs is small by modern standards, and the README does not state how the split was constructed or whether the evaluation is temporal. For a classifier whose whole purpose is to act on new incoming bugs, a random split would overstate performance.
Several classifiers are described as extensions or corrections of others. The defect versus enhancement versus task classifier is described as an extension of the defect classifier, and the regression classifier exists because the Bugzilla regression keyword is not used consistently. That last point is the honest framing of the whole project: these models are often predicting a label that humans were supposed to have applied and did not.
Getting it running: uv, Python 3.12, and two scripts
Setup uses uv. The README gives uv sync for base dependencies, uv sync --group test for test dependencies, and uv sync --extra nlp for NLP extras. Python 3.12 or newer is required, and the README says to confirm the exact version in pyproject.toml. libgit2 is listed as possibly required, with the note that you can skip it if installation fails, and the Debian install line points at the experimental repository for libgit2-dev.
Scoring a bug is a single command: python -m scripts.bug_classifier MODEL_NAME --bug-id ID_OF_A_BUG_FROM_BUGZILLA. The README notes that if you run the classifier without training first, it downloads an already trained model. That is the fastest path to evaluating whether the project is useful to you, and it does not require the training step at all.
Training the defect model is python3 -m scripts.trainer defect. The README also documents a CI path: include the line Train on Taskcluster: <model name> in a GitHub pull request description, for example Train on Taskcluster: spambug. Three constraints are stated. It works only on GitHub pull requests. The task re-runs on every push to the linked branch, so the README advises limiting pushes or temporarily removing the keyword. And the training task extracts only the model name, ignoring arguments. That last limitation matters if a classifier needs non-default parameters, because the CI path cannot express them.
Repository mining is a separate concern. The README says you only need it if you are changing the mining script, and that commits data is generated automatically otherwise. The steps given are to clone https://hg.mozilla.org/mozilla-central/, run ./mach vcs-setup in that clone, and enable certain extensions, with the README text truncated at that point.
The Bugzilla assumption is the adoption boundary
The strongest limitation is not a bug in the code. It is that Bugbug's classifiers are defined against Bugzilla's schema and Mozilla's workflow vocabulary. Assignee suggestion needs an assignee field with a history of who fixed what. Uplift prediction needs an uplift flag and an approval decision. Regression range prediction needs a regression range field. If your tracker does not record those fields, the corresponding classifier has no label to learn from, and no amount of retraining fixes a missing column.
A second constraint is the coupling between classifiers and repository history. Test selection and regressor detection are about patches, which means the models need commit and diff data, not just issue text. The README's mining instructions assume a mozilla-central clone and a mach command.
A third issue is operational. The repository has no published GitHub releases, so there is no versioned artifact to pin. The README's own interface is python -m scripts.trainer and python -m scripts.bug_classifier against a master branch. If you depend on a specific classifier's behaviour, you are depending on a commit, and you should record which one. The pre-commit hook setup (pre-commit install) is described for contributors, which tells you the project expects you to work from a clone rather than from a package.
What to compare it against
The obvious alternative is to build the classifier yourself on top of the datasets rather than the platform. The README explicitly supports this: the generated data can be used independently, with docs/data.md as the entry point. The difference in approach is real. Bugbug gives you a fixed set of classifier definitions, a training script, and a scoring CLI, all shaped around Bugzilla and Mozilla. Taking only the data gives you the labels and features without the model choices, the evaluation setup, or the CLI, which means you own the training loop and the metrics. If your tracker resembles Bugzilla but your workflow does not resemble Mozilla's, the data-only path avoids fighting the classifier definitions.
A second comparison is the Taskcluster integration against a local training run. They are not equivalent. The CI path is triggered by a pull request description keyword, re-runs on every push, and ignores arguments. The local path is python -m scripts.trainer with --help to see required and optional arguments. If your training needs anything beyond a model name, the CI path is closed to you, and the choice is made for you by that constraint rather than by preference.
Licence, maintenance, and what upgrading costs
Bugbug is MPL-2.0. That is a file-level copyleft licence: modifications to MPL-covered files stay under MPL when distributed, while larger works that combine MPL files with other code can be licensed differently. This is a general description of the licence family, not legal advice, and anyone distributing a modified Bugbug should read the licence text and the file headers rather than rely on a summary.
Maintenance cost is dominated by the training pipeline rather than by dependency upgrades. The README states that training takes 30 minutes or more, and the Taskcluster path re-runs training on every push to a linked branch. That is a recurring compute cost tied to how often you touch a branch, not a one-time setup fee. The uv sync commands make dependency installation reproducible, and the Python 3.12 floor plus the optional libgit2 requirement are the two environment details most likely to break on an older base image.
Upgrade cost is harder to estimate because the repository has no published GitHub releases. Without tagged versions, there is no changelog-driven upgrade path. The practical approach is to pin a commit, run the classifier you depend on against a fixed set of bugs, and compare outputs before moving the pin. That is a concrete verification step tied to scripts.bug_classifier, not a general recommendation.
Who should take this on
Bugbug fits an organisation that already runs Bugzilla at volume, has repository history it can mine, and wants pretrained classifiers it can evaluate immediately via python -m scripts.bug_classifier MODEL_NAME --bug-id. The download-on-first-run behaviour means the evaluation cost is low: you can check whether assignee or component suggestion is useful on your bugs before investing in the training pipeline.
It does not fit a team on GitHub Issues, Jira, or GitLab, because the label vocabulary the classifiers predict does not exist there. It also does not fit a team that needs a supported, versioned dependency, since the repository has no published GitHub releases and the documented interface is a module path against a branch.
The first thing to verify is the defect classifier's evaluation setup, because the README reports roughly 93 percent accuracy on 2110 bugs without describing the split. The second is whether the pretrained model download works for the classifier you actually want, since the README only guarantees that behaviour in general terms. The third is your mining inputs: the README's repository mining steps assume a mozilla-central clone and ./mach vcs-setup.
Editorial conclusion
Adopt Bugbug if you run a large Bugzilla instance and can supply repository history, and you want pretrained classifiers rather than a from-scratch pipeline. Do not adopt it if your issues live in GitHub Issues, Jira, or GitLab, or if you need a supported release artifact. Before committing, verify two things against your own data: that scripts.bug_classifier can download and run a pretrained model for the classifier you care about, and that your repository mining inputs match what the trainer expects, since the README's mining instructions assume a mozilla-central clone and a mach vcs-setup step.
Frequently asked questions
How many classifiers does BugBug provide?
The readme names eighteen, from assignee and component through defect, backout, testfailure, regressor, spam and uplift. Only the defect classifier carries published figures: 2110 bugs, accuracy around 93%, precision around 95% and recall around 94%.
Do I have to train a BugBug model before classifying a bug?
No. If you run the classifier script without training a model first, it downloads an already trained one automatically. The command takes a model name and a Bugzilla bug id, for example the defect model with --bug-id.
How do I train a BugBug model on Taskcluster?
Put Train on Taskcluster: followed by a model name in the pull request description. It works only in GitHub pull requests, it re-runs on every push to the linked branch, and it reads the model name only, with no arguments.
What does BugBug need before setup will work?
uv sync for dependencies, uv sync --group test for test extras and uv sync --extra nlp for the NLP extras, plus Python 3.12 or newer. libgit2 at v1.0.0 might also be required, and the step can be skipped if you cannot install it.
Can I use BugBug's training data without running BugBug?
Yes. The readme states that data generated to train the models can be used independently from BugBug, and points to docs/data.md for the details. The repository mining script is only needed if you want to change how that data is produced.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mozilla-bugbug)Star history chart for your README
[](https://hysenlabs.com/projects/mozilla-bugbug)Was this useful?