Octocode: a Rust MCP server that gives coding agents an AST graph instead of text chunks
Structural code intelligence for AI agents — semantic search, knowledge graphs, and a built-in MCP server in one Rust binary. Give Claude, Cursor, and any MCP client a deep understanding of your codebase.
At a glance
- What is it?
- Octocode builds a tree-sitter symbol graph from your working tree and exposes it to MCP clients as semantic search, graph traversal and signature lookup. The interesting part is what it refuses to embed, and the benchmark table in the repository shows where the default settings underperform.
- Who is it for?
- Adopt Octocode if your agent already speaks MCP and your pain is cross-file questions about imports, call sites and dependencies, since the graph layer works with graphrag disabled and needs no embeddings or LLM calls. Skip it if you only want better fuzzy text matching over a small repository, or if you cannot run a local embedding model for the semantic half.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
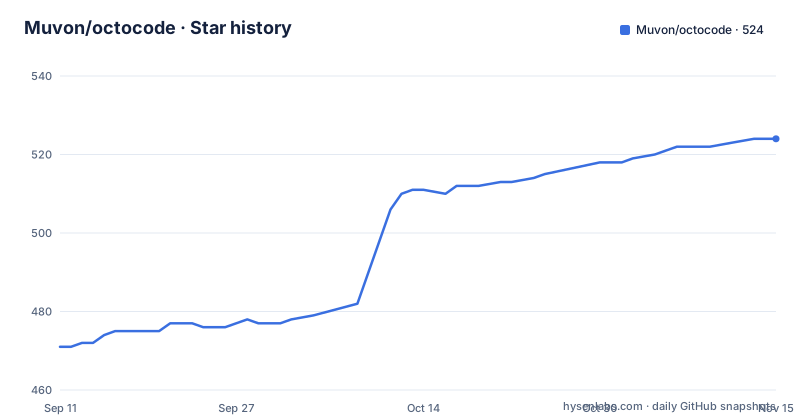
Star history
- Muvon/octocode524 ★ · +53
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Muvon/octocode | 471 | 524 |
53 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem Octocode targets: agents that cannot see file relationships
The README states the problem directly: AI assistants are blind to your codebase, unable to search files, understand dependencies, or remember context across sessions. That framing matters because most retrieval setups for code treat source as flat text chunks. A chunk of auth middleware and a chunk of JWT validation look similar to an embedding model, but nothing in that pipeline records that one imports the other, or that a router wires both into a request path. Octocode's claim is that structure is the missing signal, and it builds that structure with tree-sitter rather than with a language model. The audience is narrow and identifiable: people running Claude Desktop, Cursor, Windsurf or another MCP-compatible client who want the agent to answer questions like which files depend on the payment module, and who are willing to install a binary and point a client config at it.
Two graphs, one of them optional
The architecture diagram in the README splits the system in two. The left branch takes current source through tree-sitter into a live symbol graph, and that graph feeds the MCP graphrag tool. The right branch takes indexed code through embeddings and an optional LLM into persisted file enrichment, which overlays onto the same graph. The distinction is load-bearing. The live AST graph extracts file and symbol nodes plus deterministic contains, imports, calls, extends and implements relationships straight from the source on disk, with no index, no embeddings and no LLM. Graph lookup, relationship traversal, path finding and overview all work with graphrag disabled. Enabling indexed GraphRAG adds semantic file matching, generated descriptions and broader file-level architectural relationships. The README is explicit that symbols are never embedded or LLM-generated, so the generated layer stays at file granularity. That is a conservative design choice, and it is the reason the graph half can run offline.
The MCP surface and what each tool returns
The server exposes four tools: semantic_search, view_signatures, graphrag and structural_search. Semantic search handles meaning-based retrieval over code. View signatures returns structure without reading whole files, which is the cheap way to let an agent decide whether a file is worth opening. The graphrag tool answers relationship questions, and the README's example shows the shape of the output: querying src/middleware/auth.rs returns outgoing imports to jwt.rs and calls to user_store.rs, plus an incoming imports edge from router.rs. Path finding and overview sit alongside traversal. There is also an LSP layer offering go-to-definition, find-references and hover documentation through your language server, which is how the README's call-site example works: process_payment() reported as called from four locations across checkout.rs, refund.rs, billing.rs and a test file. LSP navigation depends on a language server being installed and configured for the language in question, and the README does not enumerate which servers it has been exercised against, so treat that as something to check against your own toolchain.
Getting it running: config keys and commands
The README shows a three-command sequence for the indexed path. First, octocode config --graphrag-enabled true. Then octocode index to build the persisted enrichment. Then octocode graphrag get-relationships --node-id src/middleware/auth.rs to query it. A plain search runs as octocode search "authentication middleware", which the README shows returning src/middleware/auth.rs with a similarity score of 0.9234. Configuration also appears in TOML form as [graphrag].enabled = false, which is the default and the setting that keeps the live graph available while skipping enrichment. The binary is published on crates.io, so cargo install octocode is the expected install path, and the README states Rust 1.95 or later. Local-first operation is the stated default, and the benchmark configuration uses jina-embeddings-v2-base-code through fastembed with no API key. The README does not document a full config file reference, which is a gap if you need to pin model paths or index locations.
What the repository's own benchmark shows
Octocode ships a retrieval benchmark under benchmark/: 127 curated code-search queries with line-range ground truth, run against octocode's own source pinned at commit b1771ba so annotations cannot drift. The published numbers use a fully local stack with jina-embeddings-v2-base-code via fastembed and no reranker, which the README calls a floor rather than a ceiling. Dense vector only and hybrid search with the default RRF weights of 0.7/0.3 produce identical results: Hit@5 0.598, Hit@10 0.717, MRR 0.485, NDCG@10 0.528, Recall@10 0.671. Tilting the fusion toward the keyword signal at 0.3/0.7 lifts those to Hit@5 0.732, Hit@10 0.835, MRR 0.572, NDCG@10 0.620 and Recall@10 0.807. The README attributes the gain to BM25 carrying disproportionate weight for code's exact identifiers. Read that table carefully: it is evidence that the default weighting is misconfigured for code search, not just that tuning helps. The same document notes that a generic local cross-encoder reranker, bge-reranker-base, does not help in this setup. The benchmark covers one repository, so the tuned weights are a starting hypothesis for yours, not a proven default.
Where Octocode is the wrong tool
The semantic half assumes you can run a local embedding model. If your environment forbids downloading model weights, or your repository is small enough that grep and your editor's symbol search already answer the question, the indexing step is pure overhead. The graph half has a different failure mode: it is only as good as tree-sitter's grammar coverage for your language mix. A repository dominated by a language without a maintained tree-sitter grammar will produce a thin graph, and the traversal answers will be correspondingly thin. There is a third constraint worth naming. Because symbols are never embedded or described by an LLM, semantic discovery operates at file granularity. If your question is about a specific function inside a large file, the semantic layer will not isolate it; you are relying on signatures, LSP or the AST graph instead. That is a deliberate trade of recall granularity for determinism, but it is a real ceiling.
How it differs from a general code search tool
Compare Octocode with a conventional vector store over code, the kind you assemble from an embedding model and a chunking script. Both can answer where authentication is handled. The difference appears on the second question. A vector store re-ranks chunks by similarity and has no representation of the fact that auth_middleware.rs imports jwt.rs and is wired into router.rs, which the README calls out as the limitation of treating code as flat text. Octocode answers that from the AST graph without an LLM in the loop. The other comparison the README draws is against documentation lookup tools: those give an agent the manual for the libraries you depend on, while Octocode describes how you assembled them. Those are complementary rather than competing, and a setup using both is coherent. The nearest functional overlap is with language-server-backed navigation, which Octocode also wraps. If your editor already gives you find-references, Octocode's contribution is putting that same capability behind an MCP tool call so the agent can use it mid-conversation.
Maintenance, licensing and what to check before adopting
The project is Apache-2.0, which permits commercial use and modification and includes an explicit patent grant. That is a permissive licence, but it is not legal advice and you should confirm obligations around notices and modified files with your own counsel if you redistribute. On cadence, the release history shows 0.23.1, 0.24.0 and 0.25.0 within roughly a week in early September 2026, and the version number is still below 1.0. A rapid pre-1.0 cadence means config keys and CLI flags can move between releases, so pin a version rather than tracking latest if you wire this into a team workflow. The persisted index is the other ongoing cost: every index run re-embeds changed files, and the README does not state a storage bound or an incremental-update guarantee, so measure index size and rebuild time on a representative repository before rolling it out. Verify language coverage against your actual file extensions, confirm which language servers the LSP features need, and re-run the benchmark's keyword-tuned weights against your own queries rather than assuming the 0.3/0.7 split transfers.
Editorial conclusion
Adopt Octocode if your agent already speaks MCP and your pain is cross-file questions about imports, call sites and dependencies, since the graph layer works with graphrag disabled and needs no embeddings or LLM calls. Skip it if you only want better fuzzy text matching over a small repository, or if you cannot run a local embedding model for the semantic half. Before committing, verify three things on your own tree: which languages tree-sitter parses in your mix, whether the retrieval benchmark's keyword-tuned RRF weights transfer to your codebase, and how large the persisted index grows for your repository, because the README describes the storage as local but does not state a size bound.
Frequently asked questions
What does octocode give an AI assistant?
Four capabilities over MCP: semantic search that finds code by meaning rather than keywords, a knowledge graph of imports, calls and dependencies, code signatures so structure can be read without opening whole files, and LSP-backed go-to-definition, find-references and hover through your language server.
Which MCP tools does octocode expose?
semantic_search, view_signatures, graphrag and structural_search. The graphrag tool builds the graph lazily from the current source tree without an index, embeddings or a language model, and structural navigation works even with GraphRAG enrichment disabled.
Does octocode need an API key or send my code anywhere?
The published retrieval numbers come from a fully local stack with no API key, using jina-embeddings-v2-base-code through fastembed and no reranker. The live AST graph needs no model at all, and symbols are never embedded or LLM-generated.
How do I install octocode?
Run the universal installer with curl piped to sh, or install the Homebrew tap with brew install muvon/tap/octocode. The crate is also published on crates.io, and the Docker image downloads a prebuilt static binary for linux amd64 and arm64 rather than compiling from source.
What did the octocode retrieval benchmark measure?
127 curated code-search queries with line-range ground truth, run against octocode's own source pinned to commit b1771ba. Hybrid fusion weighted 0.3 for vectors and 0.7 for keywords reached Hit@5 of 0.732 and Recall@10 of 0.807, against 0.598 and 0.671 for the dense-only and default-weight rows, which report identical numbers.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/muvon-octocode)Star history chart for your README
[](https://hysenlabs.com/projects/muvon-octocode)Was this useful?