StatsForecast: statistical forecasting for large collections of univariate series
Lightning ⚡️ fast forecasting with statistical and econometric models.
At a glance
- What is it?
- StatsForecast is a Python library of classical forecasting models (AutoARIMA, AutoETS, AutoCES, AutoTheta, MSTL and others) built for fitting many series at once. The judgement: it is the right tool when your problem is thousands of independent series and the wrong one when your problem is a single series with cross-series structure.
- Who is it for?
- Adopt StatsForecast if you have many independent univariate series, want classical models rather than a neural net, and can accept that each series is modelled on its own. Do not adopt it if your series are short, strongly correlated, or better served by a single global model.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
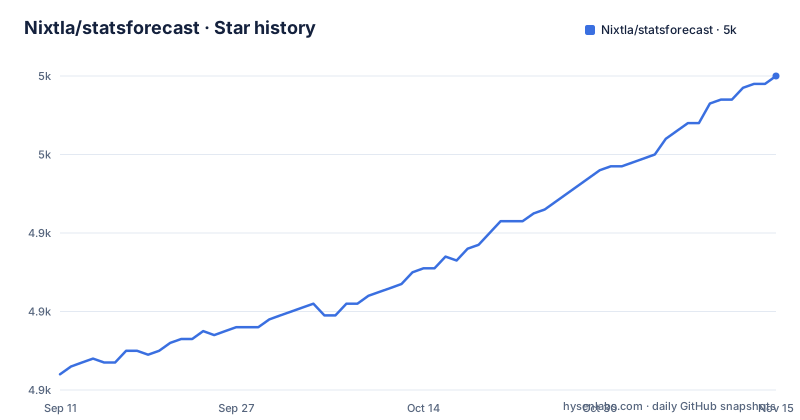
- Nixtla/statsforecast4,980 ★ · +76
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Nixtla/statsforecast | 4.9k | 5k |
76 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The problem StatsForecast is built to solve
The README states the motivation directly: existing Python alternatives for statistical models are "slow, inaccurate and don't scale well". That is the gap StatsForecast targets. The unit of work is not one series but a collection of series, often described in the documentation as millions of them, and the library is positioned both for production forecasting jobs and for benchmarking.
The audience follows from that. If you have a demand-planning table with one row per SKU per week, or an energy dataset with one column per meter, you are the intended user. If you have a single monthly revenue series and want a forecast for next quarter, the machinery here is heavier than the problem. The README frames the library as offering "a collection of widely used univariate time series forecasting models", and the word univariate matters: the models see one series at a time, with optional exogenous regressors, not a panel of related series jointly.
The fit and predict mechanics, and what the models actually are
The API follows a scikit-learn style convention, which the README lists as a feature: `.fit` and `.predict`. You construct a StatsForecast object with a list of model instances and a frequency string, call fit on a dataframe, then call predict with a horizon and confidence levels. The README's minimal example uses `freq='ME'` (month end) and `AutoARIMA(season_length=12)`, then `sf.predict(h=12, level=[95])`.
The models themselves are reimplementations of established statistical methods rather than new algorithms. The automatic forecasting table lists AutoARIMA, AutoETS, AutoCES, AutoTheta, AutoMFLES and AutoTBATS, each supporting point forecasts, probabilistic forecasts, in-sample fitted values and probabilistic fitted values. Only AutoARIMA and AutoMFLES are marked as supporting exogenous features in that table. The broader model list also includes an ARIMA family (ARIMA and AutoRegressive), and the README says the library includes a large battery of benchmarking models.
The practical consequence of the univariate design is that fitting is embarrassingly parallel. Each series has its own parameter search, so the library can distribute series across processes or across a cluster without any shared state. The README lists out-of-the-box compatibility with Spark, Dask and Ray, and links a Ray experiment claiming 1,000,000 series in 30 minutes. Those numbers come from the project's own experiment directories, not from an independent evaluation.
Getting it running: install, minimal script, and where the knobs are
Installation is a single command from PyPI or conda-forge:
pip install statsforecast
or
conda install -c conda-forge statsforecast
The README points to an installation guide for further instructions, which is where platform-specific details would live.
The minimal example is short enough to reproduce in full. Import StatsForecast and a model, load the bundled AirPassengersDF, build the object with `models=[AutoARIMA(season_length=12)]` and `freq='ME'`, call `sf.fit(df)`, then `sf.predict(h=12, level=[95])`. That is the whole surface for a first run, and the fact that a dataset ships in `statsforecast.utils` means you can exercise the pipeline without preparing your own frame.
The configuration that matters sits in the model constructors rather than in a global config file. `season_length` is the key parameter in the example, and getting it wrong on a series with a different period is a silent source of bad forecasts. The `level` argument on predict controls which prediction intervals are returned. The README also documents exogenous variables and static covariates, plus an anomaly detection workflow that uses in-sample prediction intervals rather than a separate detector. For multiple seasonalities the documented route is MSTL, covered in a dedicated tutorial.
Where the design breaks down
The univariate framing is the main limitation and it is not incidental. Every model in the automatic forecasting table fits one series in isolation. If your series share structure, for example a thousand products whose demand responds to the same promotion calendar, that shared signal has to enter through exogenous regressors, and the table shows that only AutoARIMA and AutoMFLES accept them among the automatic models. There is no global model that pools information across series, which is the approach a neural or gradient-boosted forecaster would take.
The second constraint is data length. Classical models such as ARIMA and ETS need enough observations to estimate seasonal parameters. The README includes a tutorial on intermittent demand, described as forecasting series with very few non-zero observations, which suggests the library handles sparse series, but the minimum series length per model is something to determine empirically before pointing the library at a table full of short histories.
The third is that the performance claims are self-reported. The README asserts figures such as 20x faster than pmdarima, 4x faster than statsmodels, 500x faster than Prophet, and 1.5x faster than R, with the pmdarima and statsmodels figures linked to experiments directories in the repository. Those directories are the right place to look, but a benchmark written by the library's authors on hardware of their choosing is a starting point for your own measurement, not a substitute for it.
How it compares to pmdarima and Prophet
pmdarima is the closest comparison because it solves the same problem: automatic ARIMA selection in Python. The README's claim is that StatsForecast's AutoARIMA is 20x faster, with the experiment linked in the repository. The difference in approach is scope. pmdarima is a focused auto-ARIMA package. StatsForecast wraps auto-ARIMA inside a multi-model, multi-series runner with a shared fit and predict interface, so you can put AutoARIMA, AutoETS and AutoTheta in the same list and compare them on the same cross-validation split. If you only ever need one ARIMA model on one series, the extra layer buys you little.
Prophet is the other reference point the README raises, and the framing is replacement: the project advertises swapping out FB-Prophet in two lines of code via an adapter, with the claim of better speed and accuracy. The methodological difference is real. Prophet is a curve-fitting model with a trend, seasonality and holiday components estimated by a single regression, which makes it tolerant of missing data and irregular spacing. StatsForecast's models are classical state space and ARIMA formulations that estimate parameters per series. That means StatsForecast is more sensitive to series length and to a correctly specified `season_length`, while Prophet's default behaviour is more forgiving out of the box. The adapter exists precisely because teams want to test the swap on their own data rather than take the claim on faith.
Versioning, maintenance and licence terms
The release history shows v2.1.1 in July 2026, v2.1.0 two days earlier, and v2.0.3 in October 2025. The gap between the 2.0.3 and 2.1.0 releases is roughly nine months, and the two 2.1.x releases arrived within days of each other, which is the shape of a patch following a feature release. The repository is not archived and the last push is dated 2026-10-29.
The safe assumption for a library with automatic model selection is that a minor version bump can change which model wins for a given series, because the search procedure or the model implementations may have changed. If you persist forecasts or model selections, pin the version and re-run your evaluation when you move.
The licence is Apache-2.0, which permits commercial use and modification and includes an explicit patent grant. The README also references integrations with Spark, Dask and Ray, each of which carries its own licence. This is not legal advice; check the terms against your own distribution plans.
Who should adopt it, and what to check first
StatsForecast fits teams with a large panel of independent univariate series who want classical, interpretable models and a single interface for comparing them against naive baselines. It also fits anyone who needs a fast benchmark to evaluate a more complex forecaster against, since the baselines are included in the same package.
It does not fit teams whose series are few, short, or strongly related. A single series with twenty observations will not support AutoARIMA's parameter search in any meaningful way, and a panel where cross-series information matters needs a global model that this library does not provide. It also does not fit anyone who needs a neural or gradient-boosted forecaster.
Before adopting, verify three concrete things. First, run the README's minimal example with your own `season_length` and confirm the intervals from `sf.predict(h=..., level=[95])` are plausible for your data, since a wrong seasonal period is the most likely silent failure. Second, check which backend you need and confirm the documentation covers it for your version, because the local, Ray, Spark and Dask paths are separate integration surfaces. Third, reproduce one of the experiment claims on your hardware before you build a capacity plan around it.
Editorial conclusion
Adopt StatsForecast if you have many independent univariate series, want classical models rather than a neural net, and can accept that each series is modelled on its own. Do not adopt it if your series are short, strongly correlated, or better served by a single global model. Before committing, verify three things on your own data: that the fitted values and intervals from AutoARIMA or AutoETS are sane on your seasonal period, that the backend you intend to use (local, Ray, Spark or Dask) is the one the documentation covers for your version, and that the Apache-2.0 licence and the bundled model implementations fit your redistribution plans.
Frequently asked questions
how to install statsforecast
Run pip install statsforecast, or install from conda-forge with conda install -c conda-forge statsforecast. Python 3.11 or later is required. The wheel is a compiled extension built through scikit-build-core with pybind11, so a source install needs a working toolchain, and the declared runtime dependencies include coreforecast, numpy, scipy, statsmodels, pandas and fugue.
statsforecast vs statsmodels
The highlights claim four times faster than statsmodels for ETS, with a link to the experiments directory behind that number. It also lists statsmodels 0.14.5 or newer among its own dependencies, so the two are used together rather than being alternatives in the strict sense. On capability, this project concentrates on univariate automatic models across many series and on distribution through Spark, Dask and Ray.
statsforecast vs prophet
The stated comparison is five hundred times faster than Prophet, and the project describes replacing the Prophet implementation as a two-line change with an adapter experiment linked for that purpose. Its own scope is univariate statistical and econometric models, including ARIMA, ETS, CES, Theta and MSTL, with probabilistic forecasts and exogenous regressors available on some models.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nixtla-statsforecast)Star history chart for your README
[](https://hysenlabs.com/projects/nixtla-statsforecast)Was this useful?