NeMo Guardrails: Colang Rules Between Your App and the Model
NeMo Guardrails is an open-source toolkit for easily adding programmable guardrails to LLM-based conversational systems.
At a glance
- What is it?
- NeMo Guardrails wraps an LLM call in a configurable rail layer written in Colang, so dialog paths, topic bans and tool calls are declared rather than prompted. It fits teams that need auditable conversation control, not teams that want a drop-in content filter.
- Who is it for?
- Adopt NeMo Guardrails if you are building a conversational assistant where specific dialog paths, topic restrictions and tool calls must be declared in files you can review, and you accept Python 3.10 to 3.13 plus a configuration directory as part of your deployment. Do not adopt it if you only need a single input or output classifier in front of a generic chat endpoint, because the rail layer and Colang configs add a vocabulary your team has to learn for little gain.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
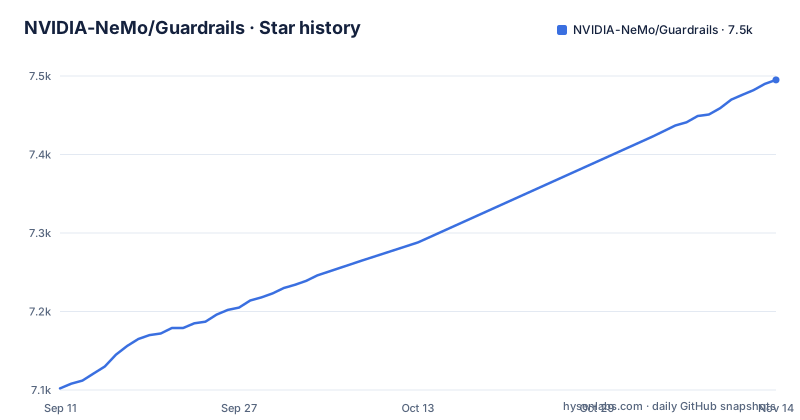
Star history
- NVIDIA-NeMo/Guardrails7,495 ★ · +393
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| NVIDIA-NeMo/Guardrails | 7.1k | 7.5k |
393 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The gap NeMo Guardrails fills between prompt instructions and application code
A system prompt that says do not discuss politics is a request, not a control. The model can still drift into the topic, and nothing in your application can tell whether it did until after the response is already on its way to a user. NeMo Guardrails targets exactly that gap. The README describes the project as an open-source toolkit for adding programmable guardrails to LLM-based conversational applications, and it defines a rail as a specific way of controlling model output: refusing a topic, responding in a fixed way to a particular request, following a predefined dialog path, holding a language style, or extracting structured data. The word programmable is the operative one. Rails live in a configuration directory that you load at runtime, so the rules are artifacts a reviewer can read, not sentences buried inside a prompt template. The intended audience is narrow enough to state plainly: developers building question answering over documents, domain-specific assistants, custom LLM endpoints, and optionally LangChain chains. If your product is a single-turn text transformation with no conversation state, the machinery here is more than you need.
How a rail layer sits in the call path
The architecture in the README is a substitution. Instead of calling the model directly, your application calls an LLMRails instance, which loads a RailsConfig from a path on disk and mediates the exchange. The README frames this as requiring only minimal changes to the code base, and the sample confirms it: construct the config, construct the rails object, then call generate with a list of messages. The input and output shape for generate is described as similar to the OpenAI Chat Completions API, so the messages list carries role and content fields and the return value is a single assistant message. What happens inside that call is the rail evaluation, and the configuration directory is where you declare it. The README lists input rails, dialog rails, retrieval rails and execution rails among the main guardrail types; read the documentation for how they are applied. One design decision is stated outright and shapes everything else: the library is async-first, with the core mechanics implemented on the Python async model, and public methods offered in both sync and async form. That matters if your request handler is already async, since generate_async is available; if your code is synchronous throughout, the sync version (generate) exists for that case.
Getting a minimal configuration running
The installation step is a single pip command, and the README lists Python 3.10, 3.11, 3.12 or 3.13 as the supported interpreters. The smallest working program loads a configuration directory and issues one call:
from nemoguardrails import LLMRails, RailsConfig
config = RailsConfig.from_path("PATH/TO/CONFIG") rails = LLMRails(config)
completion = rails.generate( messages=[{"role": "user", "content": "Hello world!"}] )
The README shows the corresponding output as a JSON object with role assistant and content "Hi! How can I help you?". The placeholder PATH/TO/CONFIG is the part that carries the work. Everything the rails do is defined in that directory, so a first integration is really two tasks: wiring the two Python calls, and authoring the configuration the path points at. For LangChain users there is an additional switch. The README states that setting the environment variable NEMOGUARDRAILS_LLM_FRAMEWORK=langchain, or calling set_default_framework("langchain"), enables the LangChain integration so a guardrails layer can wrap existing chains. That is a global default rather than a per-call argument, which is worth noting if one process serves more than one integration style.
What the rail layer does not decide for you
The toolkit gives you a place to declare behavior. It does not tell you what the behavior should be, and it does not ship a universal policy that makes an application safe. The README points to an LLM vulnerability scanning page and to a sample protection overview for the ABC Bot example, covering jailbreaks and prompt injections, but that material is presented as an evaluation of specific guardrails configurations rather than a guarantee that any configuration resists any attack. Treat the rail layer as an enforcement point you populate, not as a shield. There is a second limitation in the shape of the integration itself. Because the rails object replaces the model call, an application that talks to several providers through different clients now has one more component to keep in sync with each provider's message format. The README says the format is similar to Chat Completions, and similar is not identical. Teams that have already standardized on a provider-specific SDK with its own tool-calling and streaming semantics should expect to reconcile those semantics at the rail boundary. Finally, the async-first design is stated as a property of the core mechanics, which means synchronous callers are going through a wrapper rather than a native path. For a low-volume internal tool that is irrelevant. For a high-concurrency service, confirm how the sync wrapper behaves under load before you build on it.
Where a plain classifier or a hosted filter fits better
The obvious alternative for many teams is a content moderation endpoint or a small classifier model placed in front of the LLM. The difference in approach is structural. A classifier scores an input or an output and returns a label; you then decide, in your own code, what to do about it. NeMo Guardrails moves that decision into the rail configuration, and it also covers cases a classifier cannot express at all: following a predefined dialog path, enforcing an authentication or support procedure, and extracting structured data from a conversation. If your requirement is "block toxic inputs and toxic outputs", a classifier is a smaller dependency with a simpler failure mode, and the rail layer earns its cost only when the rules are about conversation flow rather than content labels. The LangChain integration is not really a competing alternative so much as an on-ramp, since the README presents it as a way to add a guardrails layer around existing chains rather than a replacement for them. The honest comparison is between declaring dialog rules in a configuration directory and hand-writing the same checks as conditionals around each model call. The toolkit wins when the rule set grows and more than one person has to review it. It loses when there are three rules and one developer.
Version cadence, licence metadata and the cost of staying current
The release history in the repository shows v0.23.0 on 2026-07-01, v0.24.0 on 2026-08-26 and v0.24.1 on 2026-09-16. A pre-1.0 version number at that cadence means minor releases can carry behavior changes, and the README reinforces this by distinguishing the develop branch, which tracks top of tree development, from the latest released version. The practical consequence is that pinning a version is not optional for a production deployment, and the upgrade cost is the cost of reading release notes before each bump rather than a one-time setup fee. There is a licence wrinkle worth flagging without offering legal advice: GitHub's repository metadata reports the licence as NOASSERTION, while the README displays an Apache 2.0 badge linking to opensource.org and pyproject.toml declares license = "Apache-2.0". Those two signals disagree, and the discrepancy is the kind of thing that matters if your organization runs automated licence checks or has a policy about which identifiers it accepts. Confirm the actual licence text in the repository and in the specific release you intend to depend on before that dependency reaches a compliance review, because the metadata alone will not settle it.
Who should wire this in, and what to check before committing
The toolkit is aimed at teams whose conversational product has rules that outlive any single prompt: a support flow with an authentication step, an assistant that must stay inside a domain, a question answering service that needs output moderation on top of retrieval. For those teams the configuration directory is the point, because it turns conversation policy into reviewable files and gives the application a defined place to intervene. For a team shipping a general-purpose chat surface with no domain constraints, the rail layer adds a concept, a config format and a dependency without changing much about the output. The first thing to verify is behavioral, not architectural: write the smallest config that expresses one rule you actually care about, load it through RailsConfig.from_path, and check that generate enforces it on the inputs and outputs you expect, including the ones you expect it to let through. The second is the licence question described above, since the repository metadata and the README badge point at different answers. The third is version pinning, given a pre-1.0 project that ships minor releases every couple of months and maintains a separate develop branch. If those three checks pass, the integration itself is two Python calls and a directory.
Editorial conclusion
Adopt NeMo Guardrails if you are building a conversational assistant where specific dialog paths, topic restrictions and tool calls must be declared in files you can review, and you accept Python 3.10 to 3.13 plus a configuration directory as part of your deployment. Do not adopt it if you only need a single input or output classifier in front of a generic chat endpoint, because the rail layer and Colang configs add a vocabulary your team has to learn for little gain. Verify first that the configs you write behave as intended in your own environment, and confirm the licence terms for the version you pin, since the repository metadata reports NOASSERTION while the README displays an Apache 2.0 badge.
Frequently asked questions
How do you use NeMo Guardrails?
Load a configuration directory with RailsConfig.from_path, build an LLMRails instance from it, then call LLMRails.generate or LLMRails.generate_async with a list of messages. The README says the input and output format is similar to OpenAI's Chat Completions API.
How do you install NeMo Guardrails?
pip install nemoguardrails, on Python 3.10 through 3.13. The guardrails server and the OpenTelemetry tracing pieces are optional extras in pyproject.toml, so a plain install gives you the library without either.
What is a guardrail in AI?
NeMo Guardrails calls them rails: specific ways of controlling the output of a large language model, such as not discussing a topic, answering a particular kind of request in a fixed way, or following a predefined dialog path. The library places them between your application code and the model.
How do you put guardrails on an AI application?
Send your messages to the guardrails layer instead of to the model: load a configuration, create an LLMRails instance, call generate. Input rails can reject or alter the user's message, retrieval rails can reject a retrieved chunk, and dialog rails can decide whether the model is invoked at all.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/nvidia-nemo-guardrails)Star history chart for your README
[](https://hysenlabs.com/projects/nvidia-nemo-guardrails)Was this useful?