Trustfall's workspace needs Rust 1.91 while its newest release is from 2024
A query engine for any combination of data sources. Query your files and APIs as if they were databases!
At a glance
- What is it?
- A query engine that takes GraphQL-shaped queries and plans them across any mix of APIs, files and models, shipped as a workspace of eleven crates with a WASM build and Python bindings. The two things worth reading first are in the manifest: a two tier dependency policy that explains the 0.x version, and an edition bump that postdates the last release.
- Who is it for?
- Trustfall is a serious piece of engineering and the manifest is unusually honest about its own constraints, which is both its main argument for adoption and its main cost. Two things to weigh.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 6 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
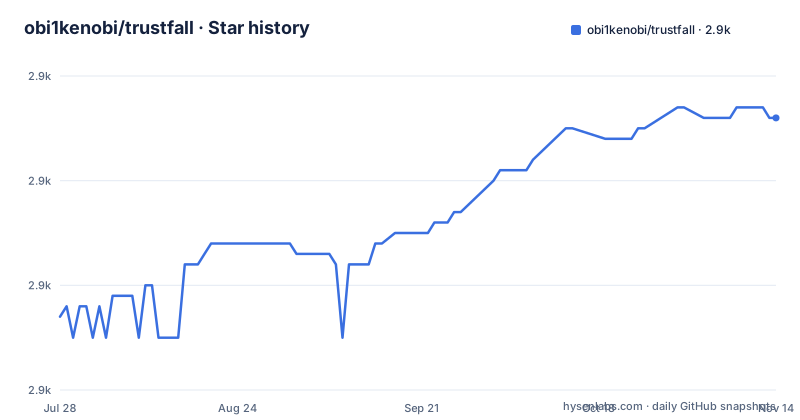
- obi1kenobi/trustfall2,896 ★ · +19
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| obi1kenobi/trustfall | 2.9k | 2.9k |
19 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The workspace needs Rust 1.91 while the newest release is from 2024
The workspace manifest declares two toolchain facts and they are both recent. The edition is 2024 and the minimum supported Rust version is 1.91, with the resolver set to the version 3 that goes with it. The release history is not recent at all: the newest tag carries a version prefix before the number, and was published on 8 November 2024, with the two before it from November 2023 and August 2023. The default branch has since received a push on 28 September 2026. So the tree you build from head needs a toolchain that did not exist when the newest release was cut, and anyone pinning to that release is on an older edition with an older floor. For a project whose selling point is a stable query language, the gap between the published artefact and the branch is the thing to look at before you decide which one your dependency should point at.
One manifest splits dependencies into a public tier and an internal tier
The workspace manifest carries comments that do the work a design document would. The first group is marked as part of the public API, and the rule stated next to it is that bumping a major version there requires the project's own major version bump: anyhow, the async GraphQL parser and value crates, serde, serde_json, thiserror and regex. The second group is marked internal only, with the note that major bumps there should be safe: itertools, ron, similar-asserts, maplit, syn, quote, proc-macro2, globset and walkdir. That single distinction explains most of the project's versioning. A parser upgrade that changes the query language surface is a breaking change for Trustfall itself, which is why the crate is still pre 1.0 rather than because the engine is unstable. The release profile is set for size and speed rather than build time, with link time optimisation on and a single codegen unit, which is the trade you accept when a library is also a WebAssembly target.
The query language is GraphQL with filter and output directives
Queries are written in a GraphQL shaped syntax, and the engine's own dependencies include a GraphQL parser and value crate. What is not stock GraphQL is the directive vocabulary. The demo query the file shows asks a question that spans three source shapes at once, which GitHub Actions are used in projects on the front page of HackerNews with at least ten points:
HackerNewsTop(max: 200) {
  ... on HackerNewsStory {
    hn_score: score @filter(op: ">=", value: ["$min_score"]) @output
A filter directive takes an operator and a value, and the value list can hold a variable rather than a literal, which is what lets the same query be reused with a different threshold. An output directive marks which fields reach the result set, so a query can traverse far more of the graph than it returns. The schema carries the same idea at its edges: a site pattern is a regular expression, so a field can declare that it only resolves for URLs matching a given host pattern. That is how one engine can treat a REST API, a YAML file and a database as parts of a single graph without the query author writing the joins by hand.
Python users are pointed at the test suite for documentation
The Python bindings exist and are built automatically on every change to the engine. How you get them is the unusual part. The most recent version is downloaded from the project's GitHub releases rather than installed from a package index, so there is no pip route in this file and the artefact is whatever the release automation produced. The documentation is thinner still, and the file says so: a getting started guide for Python is forthcoming, tracked on a specific issue, and in the meantime the best resource is the bindings' own test suite. That is an honest recommendation rather than a comfortable one, because a test suite shows correct usage but not the shape of the API. The alternative extension surface is the engine's own adapter trait, documented on the Rust documentation site, and there is a separate crate whose stated job is macros that simplify plugging in data sources.
The spec and its schemas sit outside the workspace
The top level of the repository holds twenty entries, eleven of which are workspace members. Three of the remainder matter to anyone writing a query. There is a specification document, there is a directory of concept schemas, and there is a stub generator whose purpose the name only hints at. None of those three is a workspace member, so none of them is compiled, and nothing in the build checks that the specification still matches the parser. For a language whose entire appeal is that the schema and the query compose in a predictable way, that is the most consequential thing in the tree layout. The rest of the layout is disciplined: a facade crate described as the preferred way to use the project, a core crate holding the engine internals, a WASM build, the Python bindings, a test binary, and two experimental crates that are members along with everything else.
Two experimental members are named schemaless
The workspace list ends with two experiments, one native and one built for the browser, and both are named for the thing the main design assumes away. The whole Trustfall model requires a schema: a data source declares what it can resolve, and the engine plans against that declaration, which is what lets it fan a single query across sources and compute the joins. The existence of two crates devoted to a schemaless variant, one of them built for WebAssembly alongside the main WASM crate, says the author considers the schema requirement the interesting limitation rather than the design. There is also a procedural macro crate whose job is generating test cases from files, so that a function given one file's contents is checked against a second file's, which is a snapshot approach applied to a compiler-like engine where a literal expectation would be unreadable. Both signals point the same way: the project is testing its own semantics hard while exploring what to do without a schema.
The playground compiles and runs queries inside the browser
The most unusual deployment in the file is a hosted playground that runs the engine client side. The configuration is stated plainly: Trustfall runs as WebAssembly and performs all aspects of query processing, parsing, compilation and execution, within the browser. Nothing is sent to a server to be parsed, and nothing needs a server to execute. The file is careful about what that demo does and does not show, saying it highlights the ability to be embedded in a target application and that the engine can equally be used in a more traditional client server context. Two public data sources are wired into it, a HackerNews REST interface and the generated documentation data for popular Rust crates, and the example query it links fans out across two APIs at once. The same WebAssembly build appears as a workspace member, so the playground is not a separate implementation. It is the same engine, compiled for a browser.
Editorial conclusion
Trustfall is a serious piece of engineering and the manifest is unusually honest about its own constraints, which is both its main argument for adoption and its main cost. Two things to weigh. It is still pre 1.0 because its own public dependencies force major bumps to propagate, so treat the version number as a stability signal you have to check rather than a guarantee. And the adoption story depends on which surface you use: the WASM build means a query can be parsed, compiled and executed entirely in a browser, which is the interesting property here, while the Python bindings are distributed as release artefacts rather than a package index, and the file itself points new users at the binding test suite because the getting started guide is still forthcoming. Read spec.md for the language, BasicAdapter for a new source, and the workspace manifest before you pin anything.
Frequently asked questions
What is Trustfall?
A query engine for querying almost any data source, from APIs and databases to files on disk and AI models, using GraphQL shaped queries. It can query several sources in one statement, and it also powers the cargo-semver-checks semantic versioning linter for Rust.
How do I add a new data source to Trustfall?
By implementing the engine's BasicAdapter trait, which the file names as the easiest route. A separate crate in the workspace defines macros specifically to simplify plugging in data sources. Schemas describe what each source can resolve, including regular expression site patterns for fields that depend on a particular host.
Does Trustfall have Python bindings?
Yes, and they are built automatically on every change to the engine, but they are downloaded from the project's GitHub releases rather than from a package index. The file also notes that a getting started guide is still forthcoming and that the best current resource is the bindings' own test suite.
What query language does Trustfall use?
A GraphQL shaped syntax, parsed by a GraphQL parser and value crate, extended with a filter directive that takes an operator and a value and can accept a variable, and an output directive that selects which traversed fields reach the result set.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/obi1kenobi-trustfall)Star history chart for your README
[](https://hysenlabs.com/projects/obi1kenobi-trustfall)Was this useful?