A benchmark platform with pinned dependencies and an unreleased 2.0
DANCE: a deep learning library and benchmark platform for single-cell analysis
At a glance
- What is it?
- dance is a Python library for single-cell deep learning whose real product is reproducibility: one script per published experiment, exact dataset identifiers on the command line, and a fully pinned dependency file. DANCE 2.0 promises an automated preprocessing recommender, and its three release-schedule boxes in the README are all still unchecked, with the newest tag dating from December 2023.
- Who is it for?
- Adopt dance if you want to reproduce published single-cell benchmarks under one pinned environment rather than assembling your own, and start from the example script for the paper you care about. Do not adopt it expecting the DANCE 2.0 preprocessing recommender, because the codebase release, the web platform and the API are all listed as unfinished in the README.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 13 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
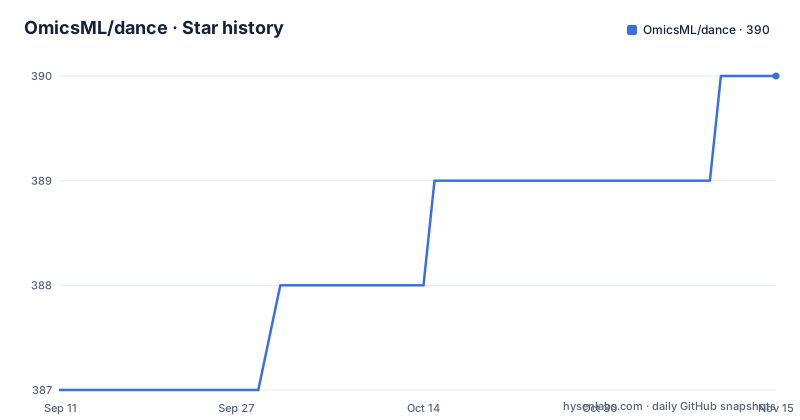
- OmicsML/dance390 ★ · +3
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| OmicsML/dance | 387 | 390 |
3 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
1.0 is a reproduction platform, 2.0 is a recommender
Two versions are described and they are not the same product. DANCE 1.0 is a Python toolkit for deep learning models over large-scale single-cell gene expression data, with the stated goal of fostering a deep learning community and establishing a benchmark platform for computational methods in the field. Its paper is published in Genome Biology.
DANCE 2.0 keeps that and adds an automated preprocessing recommendation platform. The motivation is stated plainly: preprocessing in single-cell analysis has been done by trial and error, and 2.0 is meant to turn it into a systematic, data-driven and interpretable workflow. The framing is that of turning a black box into a transparent workflow, and the corresponding paper is on bioRxiv.
Between them sits a survey paper on deep learning in single-cell analysis, published in ACM Transactions on Intelligent Systems and Technology.
That structure tells you what each version is for. 1.0 exists so that results from different papers can be compared at all. 2.0 exists so that the preprocessing in front of those results stops being the variable nobody controls.
Three modules, and two capabilities are marked 1.0 only
Both versions are described as having three modules at present.
Single-modality analysis covers cell type annotation, clustering and gene imputation. Single-cell multimodal omics covers modality prediction, modality matching and joint embedding, and this is where the annotations matter: modality prediction and modality matching are each marked as available only in DANCE 1.0, while joint embedding is not marked at all and therefore reads as shared. Spatially resolved transcriptomics covers spatial domain identification and cell type deconvolution.
So moving to 2.0, as the README describes it, appears to drop two capabilities rather than extend all three. If your project depends on predicting or matching modalities, that annotation is the first thing to check against the code.
The examples directory follows the same shape, with single_modality/, multi_modality/, spatial/ and, distinct from all three, atlas/, result_analysis/ and tuning/, the last being where the 2.0 preprocessing work lives.
The 2.0 release schedule is three unchecked boxes
This is the section to read before you plan anything around DANCE 2.0. The release schedule is a three-item checklist, and every item is unticked: the open-source release of the DANCE 2.0 codebase, the launch of the DANCE 2.0 web platform where users upload datasets and receive optimal preprocessing recommendations, and the release of the DANCE 2.0 API for programmatic access to those recommendations.
What exists instead is a paper on bioRxiv, a Method-Aware Preprocessing module described in the README, and an examples directory at examples/tuning/custom-methods for running the MAP module locally. So the recommendation logic is present in the repository in some form while the release, the hosted platform and the API are all pending.
The version history is consistent with that reading. The newest release is v1.0.1 on 2023-12-04, its title carrying a typo, DNACE 1.0.1: Bug fixes & new datasets, before v1.0.0 in June 2023 and v1.0.0rc0 in August 2022. Nearly three years of commits have landed since that tag without a release.
Practically, that means a pip install gives you the 1.0 line, and anything from 2.0 has to come from the repository.
One script per published experiment, with dataset IDs on the command line
The usage story for 1.0 is reproduction. Every computational single-cell method the project implements has a script under examples/, and each script carries the command needed to reproduce a specific experiment from the original paper.
The worked example is cell type annotation with scDeepSort. You install the package, navigate to examples/single_modality/cell_type_annotation, read the options at the end of scdeepsort.py, and run the experiment you want. For the Mouse Brain experiment that is:
python scdeepsort.py --species mouse --tissue Brain --train_dataset 753 3285 --test_dataset 2695Dataset identifiers are positional numbers rather than names, which is the honest interface for a benchmark: 753 and 3285 are training splits and 2695 is the test split, and the mapping lives with the data rather than in the prompt.
The motivation paragraph explains why this exists at all. Different studies prepare their datasets and evaluate differently, and methods may be written in different languages or against incompatible library versions, so reproducing a previous result is itself a research problem. The unified tools the project names in response are data downloading, data pre-processing and transformation including graph construction, and model training and evaluation.
Every dependency is pinned, and one pin is commented out
The requirements file is exact pins with no ranges, and reading it tells you what the benchmark environment actually is: numpy 1.26.4, pandas 2.2.2, scipy 1.13.0, scikit-learn 1.3.2, scanpy 1.10.1, anndata 0.10.8 and mudata 0.2.3 for the data layer; igraph, leidenalg and louvain for graph and clustering work; pyro-ppl 1.9.0 for probabilistic programming; wandb 0.16.3 for experiment tracking.
One line is commented out and carries its own explanation, a pandas 1.5.3 pin with a note that scib 1.1.4 requires pandas below 2. The file otherwise installs pandas 2.2.2 alongside scib 1.1.5, so the conflict that comment records has been resolved in one direction. If you hit an import or dtype error in the integration metrics code, that comment is where the answer starts.
There is also a version fork on networkx, 3.3 for Python 3.10 and newer and 3.2.1 below it, which is the single sign that the file was maintained across a Python version bump rather than generated.
At the other end of the file sit fastapi, uvicorn and python-multipart, which have nothing to do with training and are discussed below.
Tests are split into light and full, and the default skips the full set
The test configuration is explicit about which tests run by default. Pytest is invoked with --strict-markers and the marker expression not full_test, so a marker named full_test is excluded unless you ask for it. Two markers are declared, full_test and light_test, and testpaths points at tests/.
That means the default suite is the fast subset, and the expensive runs are opt-in by marker rather than by a separate command. It is a reasonable arrangement for a benchmark repository where a full evaluation can take hours, and it is also a trap if you assume a green default run means the evaluation metrics were exercised.
Tooling around it is thorough for a research package. tox.ini is present, there is a pre-commit configuration, and formatting is pinned through yapf with a pep8 base style and a 120 column limit, plus docformatter wrapping summaries at 88 characters. There is a yamllint configuration too, which is a small sign that the YAML configuration files are linted rather than edited by hand.
CI runs through a workflow that the README badges point at, named test_examples.
A FastAPI service sits next to the training code
The last three pinned dependencies, fastapi 0.115.12, uvicorn 0.34.3 and python-multipart, are web stack rather than scientific stack, and there is a matching directory in the repository tree called workflow_with_functions.
That combination is the footprint of the 2.0 direction. The pending API item in the release schedule is for programmatic access to preprocessing recommendations, and a recommendation service that accepts an uploaded dataset and returns a pipeline is exactly what those three libraries are for. python-multipart in particular is a file upload handler, which is the shape of the planned web platform.
Two more directories support that reading: docker/ and install.sh at the root, which give you a container and a script as ways to get an environment, and examples/dataset_server.json, which looks like a manifest of datasets the service can fetch.
Everything else in the tree is expected for this kind of project: notebooks/ alongside examples/, imgs/, docs/, MANIFEST.in, setup.cfg carrying the packaging metadata that setup.py delegates to, CHANGELOG.md, CODE_OF_CONDUCT.md, CONTRIBUTING.md and a licence file. The project is BSD-2-Clause.
Community channels, three citations, and a truncated 2.0 walkthrough
The README maintains an unusual set of community routes for a research library: a Slack workspace, a Twitter account, a WeChat group with a named group assistant, and a direct email address to the team. That mix suggests a project with an active user community across regions rather than a lab tool with occasional issues.
Contributions go through guidelines in CONTRIBUTING.md that describe automated quality controls and how to set up the dev environments, which is where a contributor learns that the default test run skips the full marker set described earlier.
For citation there are three BibTeX blocks, one per paper, covering the 2.0 preprint, the 1.0 Genome Biology article and the ACM survey. Citing the package or the survey paper is what the README asks for, which in practice means your methods section inherits whichever one your reviewers recognise.
One caveat on this review: the README is cut off partway through the DANCE 2.0 usage section, at the sentence introducing the instant pipeline recommendation for a new dataset, so the web platform and API instructions are not visible here. Read that section in the repository before you rely on it.
Editorial conclusion
Adopt dance if you want to reproduce published single-cell benchmarks under one pinned environment rather than assembling your own, and start from the example script for the paper you care about. Do not adopt it expecting the DANCE 2.0 preprocessing recommender, because the codebase release, the web platform and the API are all listed as unfinished in the README. Verify first that your data task is still covered, since modality prediction and modality matching are marked as available only in 1.0, and read the commented-out pandas pin before installing.
Frequently asked questions
What is DANCE 1.0?
A Python toolkit for deep learning models over large-scale single-cell gene expression data, created to establish a benchmark platform for computational methods in the field. Its paper, DANCE: a deep learning library and benchmark platform for single-cell analysis, is published in Genome Biology.
What does DANCE 2.0 add over DANCE 1.0?
An automated preprocessing recommendation platform, including a Method-Aware Preprocessing module for finding the best pipeline for a specific method, with local examples under examples/tuning/custom-methods. Its paper on transforming single-cell analysis from a black box into a transparent workflow is on bioRxiv, and its three release-schedule items in the README are all unticked.
How do I reproduce a published experiment with dance?
Go to the matching folder under examples/, for instance examples/single_modality/cell_type_annotation, and read the options at the end of the script. For scDeepSort on Mouse Brain that is python scdeepsort.py --species mouse --tissue Brain --train_dataset 753 3285 --test_dataset 2695, where the numbers are dataset split identifiers.
Which analysis tasks does dance cover?
Three modules: single-modality analysis for cell type annotation, clustering and gene imputation; single-cell multimodal omics for modality prediction, modality matching and joint embedding; and spatially resolved transcriptomics for spatial domain identification and cell type deconvolution. Modality prediction and matching are marked as available only in DANCE 1.0.
What are the installation constraints for dance?
The dependency file pins exact versions, including numpy 1.26.4, pandas 2.2.2, scanpy 1.10.1 and scikit-learn 1.3.2, and forks networkx by Python version, 3.3 for 3.10 and newer. One pandas pin is commented out with a note that scib 1.1.4 requires pandas below 2, which is worth reading before you install.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/omicsml-dance)Star history chart for your README
[](https://hysenlabs.com/projects/omicsml-dance)Was this useful?