fp-tools ships three install routes, three dependency declarations, and paper targets with nothing behind them
Command-first ATAC-seq footprinting, motif analysis, and reproducible interactive reports
At a glance
- What is it?
- fp-tools is a command-first toolkit for ATAC-seq footprinting: it corrects sequence bias, scores footprints around motifs, and writes signal tracks, tables and interactive reports, with a Python package, a desktop app and a container. The analysis entry points differ by platform in ways the install table does not spell out, and several repository-level targets point at directories the tree does not contain.
- Who is it for?
- fp-tools suits an analyst who already has coordinate-sorted BAM files with matching peaks and wants footprint calls, motif matches and a reviewable report from one command, and it states its own interpretation limit plainly: a footprint is evidence to investigate rather than proof that a transcription factor is bound.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
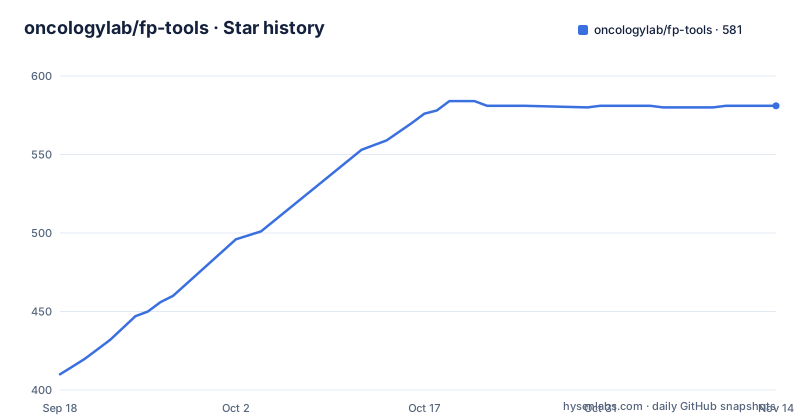
- oncologylab/fp-tools581 ★ · +171
| Repository | 2026-09-18 | 2026-11-14 |
|---|---|---|
| oncologylab/fp-tools | 410 | 581 |
171 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is fp-tools and the install line names fp-tools-bio
The repository, the documentation site and the Makefile all use fp-tools, while the distribution you install is fp-tools-bio. The Python route is a single line, and the second line in that fence is the first command most users run:
python -m pip install --upgrade fp-tools-bio
bulk-footprinting --help
`--upgrade` with no version constraint is the only unpinned step in the installation story. The project file names the distribution fp-tools-bio at version 0.2.9, the release tags on record are v0.2.7, v0.2.8 and v0.2.9, and the last of those matches the version in the project file exactly, with two of the three tags landing on the same day.
The browser interface is a separate entry point, `fp-tools-gui`, and optional de novo motif tools download themselves on first use, so a first run of those commands reaches the network even on a machine that installed from a local wheel. The command table also splits by area: core analysis commands, a Linux preprocessing command, workflows, reports, de novo motifs and single-cell utilities, and each one takes `--help` for its complete options.
Three install routes, and the container is the only one that names a version
The install table offers three routes. A desktop app for Windows or Apple Silicon macOS, downloaded from the releases page. A Python package for Windows, macOS or Linux on Python 3.11 through 3.13. And a container described as a versioned analysis environment, built from a git tag rather than a branch:
`docker build -t fp-tools:0.2.9 https://github.com/oncologylab/fp-tools.git#v0.2.9`
That fragment pins one release, so the reproducible-environment claim belongs to the container route and not to the package route, where `--upgrade` tracks whatever is newest on the index.
What the container starts is the GUI rather than a shell. Its default command is `fp-tools-gui --host 0.0.0.0 --port 8891 --no-browser --run-dir /work/fp-tools-gui-runs`, with 8891 exposed, a work directory created and handed to the non-root user the base image already defines, and an environment variable FP_TOOLS_RUNTIME set to system. No authentication flag appears in that command or anywhere in the install documentation, and a Streamlit directory sits at the top of the repository, so a container started with defaults puts an analysis interface on every interface of whatever host runs it.
Four dependencies switch on your platform, so macOS and Linux get different stacks
The runtime requirements are filtered by platform markers rather than listed once. pysam is required everywhere except Windows, where bamnostic takes its place. pyBigWig is required only on Linux with an x86_64 machine architecture, which excludes Apple Silicon and every non-x86 Linux box. pyfastx is added on Windows, and pybigtools is unconditional.
The consequence is concrete: an Apple Silicon macOS install gets pysam, pybigtools and no pyBigWig, while a Linux x86_64 install gets pyBigWig as well, and a Windows install gets neither pysam nor pyBigWig but picks up bamnostic and pyfastx. A BigWig writer is therefore present on the platform where much of the signal-track output is produced and absent on two others, with no fallback named.
The rest of the stack is shared: numpy, scipy, matplotlib, pandas, seaborn, scikit-learn, tqdm, biopython, adjustText, logomaker and a spreadsheet writer, with kneed and pyarrow in the same block. Every requirement carries an upper bound, from numpy>=1.22,<3.0 and scipy>=1.16,<2.0 to matplotlib>=3.10,<4.0 and seaborn>=0.13.2,<0.14.0, and the project file classifies the distribution as Beta with a requires-python floor of 3.11.
prepare-atac runs on Linux only, so desktop users arrive with BAM already made
FASTQ to BAM preparation is a separate command called `prepare-atac`, and it is documented for the Linux CLI and the Linux container. `bulk-footprinting`, the GUI, and native macOS and Windows installations all start from coordinate-sorted BAM files with a BAI index and a matching peak BED file. That makes the first row of the table a real difference between routes rather than a convenience: on a desktop the alignment step belongs to whatever else you already use.
The bulk workflow itself takes two tables. `samples.tsv` has one row per biological sample with the columns `sample`, `condition`, `bam` and `peaks`; `comparisons.tsv` uses `comparison`, `cond1` and `cond2` to name each comparison and its two conditions. Given those, one command runs the whole chain:
bulk-footprinting \
  --sample-table samples.tsv \
  --comparison-table comparisons.tsv \
  --genome hg38 \
  --outdir project
Inside, the workflow runs `atac-correct`, `call-footprints`, `match-motifs`, `diff-footprints` and `review-multi-comparisons`, each of which also runs on its own, and it uses all available cores by default. The hg38 and mm10 labels pull checksum-verified FASTA and blacklist files from a managed reference cache, while a custom FASTA path and an optional custom blacklist can be supplied instead.
The single-cell command wants files where the bulk command wants a label
The single-cell entry point takes genome input as paths rather than as a label. The command groups fragments, runs pseudobulk footprinting, and produces per-cell k-nearest-neighbor footprint-signature heatmaps alongside UMAP views of the cells, and it needs an AnnData count matrix plus an annotation table:
sc-footprinting \
  --fragments fragments.tsv.gz \
  --annotations cell_annotations.tsv \
  --h5ad genomic_bin_counts.h5ad \
  --group-by cell_type \
  --genome-sizes hg38.chrom.sizes \
  --genome hg38.fa.gz \
  --peaks merged_peaks.bed \
  --outdir project/single_cell
So the same hg38 reference arrives as the label hg38 in the bulk command and as two files, a FASTA and a chrom.sizes table, here, and the managed reference cache is described only for the bulk side. The pages above the command are the guidance for the annotation columns and the count matrix, and the command itself is labelled a template to be edited, with the paths replaced and the command run from the folder holding the files.
A finer analysis axis exists for the difference step: `diff-footprints --comparison-axis regions` compares matched genomic region sets within one sample or across biological replicates, which is a different question from comparing two conditions.
Three Cython modules and three dependency declarations for one package
Three modules are compiled from Cython sources rather than run as Python: sequences, ngs and signals, each under the utils package, built by setup.py with `language_level` 3 into a separate build directory. The compiler directives are the notable part. Both `boundscheck` and `wraparound` are disabled, so disabling bounds and negative-index wrapping checks can improve performance, but invalid indexing may lead to undefined behavior or a crash rather than a Python exception.
The build is not pure Python. The build-system requirements pull Cython and NumPy headers at build time, and the NumPy include directory is passed into each extension, so installing from source needs a working compiler. That is what the project file's own comment says: setuptools does the build, with Cython and NumPy headers available at build time. The Makefile assumes a local layout rather than an activated environment. Its interpreter is `.venv/bin/python` by default, overridable with a variable, and the build target changes into /tmp before invoking the build module with an absolute path to the interpreter and the source tree, writing output back into the repository's dist directory.
Dependencies are declared three ways. The project file holds the runtime list with a comment explaining that it is unified there so pip and wheel installs work without Poetry. A poetry.lock sits beside it with a poetry.toml. And an environment.yml at the top level feeds the conda route, with the Docker build copying a second environment file from the packaging directory and installing it with micromamba. So the container is assembled from a conda environment file rather than from the project file, while a pip install reads the project file, and the Poetry lockfile records a third resolution that neither of the other two paths consults.
The rest of the tree is shaped for a documentation site and a release process: mkdocs.yml with an overrides directory, a docs tree, a CITATION.cff, a RELEASE_CHECKLIST.md, a DEV_PLAN.md and an AGENTS.md. Test material has its own directory alongside tests, and examples holds a small set of projects, including gui_configs, a nutrient_stress_project, two plot-aggregate layouts named for a directory and a grid, and two prepare-atac YAML files, one of them marked legacy.
The paper targets point at a manuscript directory the tree does not contain
The Makefile declares seven phony targets. `test` runs unittest discovery over the tests directory with the default interpreter. `build` and `release-check` are straightforward, with release-check adding a twine check over the built distributions. The other three are about a paper:
`paper-pdf` and `paper-smoke` both change into a `manuscript` directory and run latexmk over main.tex, and `paper-smoke` first runs a plotting script from `manuscript/scripts`. `clean-paper` cleans latexmk output in that same directory.
The top level of the repository holds src, tests, docs, scripts, packaging, benchmarks, examples, test_data, overrides, the two dependency files, the Dockerfile, the Makefile and the policy documents. There is no manuscript directory among them, so all three paper targets fail at the change directory step on a fresh clone unless something outside version control supplies it.
That is the pattern to watch across the repository. The release checklist, the dev plan and the agents file all describe process that a checkout can read, while the manuscript, the example annotation columns and the exact options of each command are all pointed at documentation or at files you provide.
A footprint is evidence to investigate, and the project says so at the top
The opening paragraphs carry the interpretation limit before any command appears. A footprint or motif match is evidence to investigate, not proof that a specific transcription factor is bound. For CUT&Tag, signals have to be read in the context of the targeted protein and the assay controls, and the ATAC-seq examples are explicitly not a CUT&Tag protocol. Stated that early, it sets the ceiling on what the tracks, tables and interactive reports can support.
The toolchain matches that framing. The project corrects sequence-related bias, scores footprints around DNA motifs, and compares signals between samples or cell groups, so every output downstream of those three steps inherits the same caveat. A version number of 0.2.9 and a Beta classification are consistent with a tool that is still changing shape, and the two tags dated the same day as the most recent push show a release cadence measured in hours rather than months.
The verification surface, then, is the comparison itself. A footprint table with the motif, the score and the region it sits in is something you can check against your own assay controls, and the interactive report is where that check is meant to happen. Nothing in the packaging replaces that step.
Editorial conclusion
fp-tools suits an analyst who already has coordinate-sorted BAM files with matching peaks and wants footprint calls, motif matches and a reviewable report from one command, and it states its own interpretation limit plainly: a footprint is evidence to investigate rather than proof that a transcription factor is bound. Before you commit, confirm your platform gets the dependencies you need, since pyBigWig is Linux x86_64 only and the Windows path swaps pysam for bamnostic and adds pyfastx. Decide where your BAM files come from, because prepare-atac is documented for Linux only and the desktop installs start from BAM you already have. If you rely on the de novo motif tools, remember they download on first use, which means a container run is not fully offline.
Frequently asked questions
What package name do I install for the fp-tools ATAC-seq analysis?
The PyPI distribution is fp-tools-bio rather than fp-tools: python -m pip install fp-tools-bio installs version 0.2.9, and the browser interface is opened by running fp-tools-gui.
Does fp-tools run on Apple Silicon macOS or Windows?
The install table lists a desktop app for Windows or Apple Silicon macOS and a Python package for Windows, macOS or Linux on Python 3.11 through 3.13. FASTQ to BAM preparation with prepare-atac is documented for the Linux CLI and Linux container only.
Can fp-tools run in a fixed, reproducible environment?
The container route builds from a git tag with docker build -t fp-tools:0.2.9 https://github.com/oncologylab/fp-tools.git#v0.2.9, and the image installs from packaging/container/environment.yml using micromamba rather than from the project file.
What does the fp-tools container start by default?
fp-tools-gui bound to 0.0.0.0 on port 8891, with --no-browser and a run directory under /work. No authentication flag is present in that command, and the base image runs the process as its own non-root user.
Do I need a genome FASTA file to run fp-tools bulk mode?
Not if you use a label. hg38 and mm10 draw checksum-verified FASTA and blacklist files from a managed reference cache, and a custom FASTA path with an optional custom blacklist can be supplied instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/oncologylab-fp-tools)Star history chart for your README
[](https://hysenlabs.com/projects/oncologylab-fp-tools)Was this useful?