cluster-template: a Python 3.14 tool environment, four delegated just modules, and advice to publish an infrastructure repo
A template for deploying a Talos Kubernetes cluster including Flux for GitOps
At a glance
- What is it?
- A Talos and Flux Kubernetes template whose own rendering tool requires Python 3.14 with two exactly pinned dependencies, whose root task file defines three recipes and delegates the rest to four modules, and which tells you to make your infrastructure repository public while its init command generates an age key and a deploy key.
- Who is it for?
- cluster-template suits a homelab operator who already runs Talos elsewhere and wants a complete GitOps starting point rather than a bare cluster, because the component set is opinionated and complete and the configuration is one file rendered by a locked toolchain. Verify five things first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly YAML, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
Star history
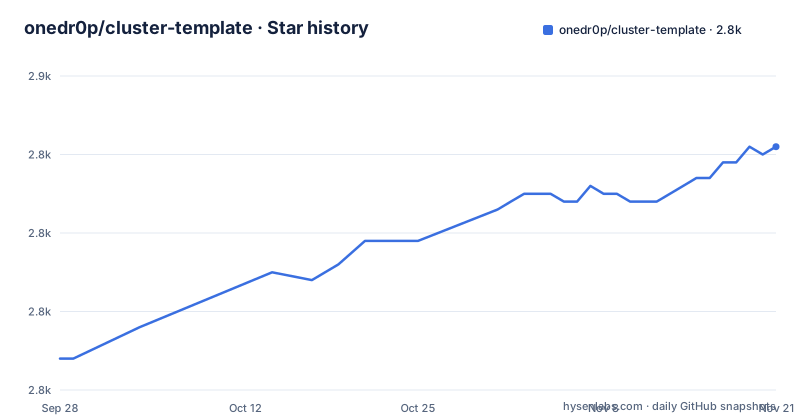
- onedr0p/cluster-template2,841 ★ · +27
| Repository | 2026-09-28 | 2026-11-21 |
|---|---|---|
| onedr0p/cluster-template | 2.8k | 2.8k |
27 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The rendering tool requires Python 3.14 and pins both of its dependencies exactly
The project renders itself with a template engine and validates its configuration with a data library, and both are pinned to an exact version in the manifest: one dependency at 2.9.1 and the other at 2.13.5. The interpreter floor is the striking part. The manifest requires Python 3.14 or newer, which is a floor high enough to exclude most distributions' default interpreters. Exact pins plus a lock file means the rendering step is reproducible, which matters for a tool that generates cluster configuration, and the version floor means it is also narrow. The manifest declares itself a non-package, with packaging switched off and a version of zero, so nothing here is installable; it exists to describe an environment. A separate development group adds a test runner on a looser constraint. The dev environment is managed by a task-and-tool manager with its own lock file rather than by hand. Three configuration files sit at the root with three different audiences: the sample a user copies and edits, the schema that describes that file to an editor, and the engine's own configuration, which the user never touches. The template output directory is tracked beside them, so the rendered artefacts are part of the repository rather than generated at first run.
The root task file defines three recipes and delegates the rest to four modules
The build entry point is a just file, and it is mostly a shim. Four module declarations sit at the top, one each for bootstrap, for kubernetes, for talos, and for the template itself, the last two marked optional. Everything the operator actually runs lives in those modules rather than on this page. What the root file defines is thin: a configure recipe that renders and validates the configuration files, an init recipe, and one private recipe for logging. That logging recipe is worth a look, because it shells out to a separate program to print a message with an RFC 3339 timestamp and a level, so that program has to be on the path before any recipe that logs will run. The file also sets its own house style, including a minimum just version, a strict bash invocation for both recipes and scripts, and quiet defaults. None of that appears in the prose guide. The file is organised as a dispatcher: each module declaration is paired with a group heading of the same name, so the four groups a user sees in the recipe list, bootstrap, kubernetes, talos and template, map one to one onto the four places the work is defined.
The init recipe generates three secrets and the same page tells you to publish the repository
The init recipe carries the most information in any single line of the task file: its own description says it initializes the configuration file, an age key, a deploy key, and a webhook token. So four artefacts are produced locally, three of which are credentials or credential material, and one of the credentials is the key that decrypts every secret the cluster holds. Stage three of the guide then carries a tip recommending that you set your repository's visibility to public, with the stated reason being that it is easier to ask for help when you are stuck. Those two facts sit about a screen apart. Publishing a repository is usually safe because its history holds no secrets; here the same repository is where the age key is generated, so whether that key is ever committed is the question to answer first. Nothing in the visible text says where the generated files are written or whether they are ignored. The age key has a counterpart named in the features section, the secret manager that the same paragraph credits with handling secrets in the repository, so the key generated by init is the one half of that arrangement and the encrypted files are the other. The same paragraph also names the tunnel client used to reach applications outside the local network, which is how a cluster avoids opening inbound ports.
Two ways to create the configuration file and no statement about which one to use
The configuration is a single TOML file, and the repository ships a sample of it beside a JSON Schema for the same file. The prose introduces the sample as the thing to read, describing it as validated and defaulted by the data library, and the rendering engine reads it to produce the cluster's configuration files. The task file, meanwhile, offers an init recipe whose description includes initializing that same configuration file. So there are two routes to the file: copy the sample and edit it, or run a command that generates it. Nothing in the visible text says which is preferred, whether init overwrites an existing file, or whether the schema and the data library agree. The schema is present mainly so an editor can validate and complete the file as you type, while the library does the real validation at render time, which means a file can pass one check and fail the other. The sample file is reached from the prose by a relative link, so the path a reader is expected to copy is visible in the text rather than inferred from the tree.
The hardware stage recommends bare metal and then qualifies it twice
Stage one is the longest prose section in the guide and it argues for a specific storage and platform choice. Solid-state drives are strongly preferred over spinning disks, and bare metal is strongly recommended over virtualised platforms, with a hypervisor named as the counter-example. Within that, enterprise drives on bare metal are described as the most reliable option even if they are used drives, while consumer drives are described as carrying risks of latency spikes, corruption, and delayed flushes, particularly in multi-node setups. Then the recommendation is qualified: the hypervisor with enterprise drives can work for testing or for carefully tuned production, at the cost of additional layers of input and output contention. A third rule covers replicated storage, which is named by two specific projects and required to use disks separate from the control plane and the etcd nodes. The section closes by telling you to test and benchmark under realistic workloads, which concedes that none of the above is a substitute for measuring. The replicated storage rule names two specific distributed storage projects as examples and restricts them to dedicated disks, and the same paragraph notes that worker nodes are the more flexible of the two roles while risky configurations should still be kept away from stateful workloads. So the storage guidance is about where data lives rather than about how much of it there is.
The minimum is per node and the high-availability guidance starts at three
A callout in stage two gives the only numeric requirement table in the guide, and it has one row. A node that is either control plane or worker gets four cores, sixteen gigabytes of memory, and a 256 gigabyte solid-state or non-volatile system disk. The role column merges the two, because the guide configures every node to be able to run workloads, which is why worker nodes are described as optional. The high-availability note is separate from the table: if you have three or more nodes, it recommends making three of them controller nodes so the control plane survives the loss of one. So there is no stated minimum node count for a working cluster, only a threshold at which the topology changes, and the per-node numbers are a floor for a node doing either job. The table does not break out memory or disk for a control plane node against a worker node, so a three-node cluster sized from the table gives every node the full requirement.
Stage two warns that extra system extensions can prevent the machine from booting
The image step sends you to the vendor's image factory with a warning attached: choose only the bare minimum system extensions, because some of them require additional configuration and will prevent the operating system from booting without it. That is an unusual admission to put in a setup guide, and it makes the extension list the most dangerous choice in the whole flow, since the failure mode is an unbootable node rather than a rejected configuration. The guide names the extensions per CPU family, giving three for one vendor including a microcontroller firmware package and two for the other. It also notes you can add extensions after installation, so the minimum is a starting point rather than a ceiling. Two further steps follow: note the schematic identifier from the factory, since it is needed later, and flash the image to a USB drive. Verification is then a single network scan for one port across your node subnet, with the subnet written as a placeholder you are told to replace.
nmap -Pn -n -p 50000 192.168.1.0/24 -vv | grep 'Discovered'The scan skips host discovery and name resolution and greps for the discovery line, which makes it a check that the nodes answer at all rather than a check of what they run. The port it looks for is the single port the vendor's API listens on, which is the only thing the guide asks you to confirm before moving on.
Six stages are promised, three are visible, and the tool lock file covers a listed set of platforms
The guide says there are six stages and asks you to follow them in order. Three are present in the text available here: hardware configuration, machine preparation, and local workstation. The third ends partway through a sentence about the tool lock file pinning downloads for the platforms listed under one configuration key, so the platform caveat is readable but its conclusion is not. Stage three also carries the only troubleshooting note in the guide, and it is specific: if the tool installation fails, unset the GitHub token environment variable and run the commands again, which implies the installer is making authenticated requests that a present token breaks. The same stage offers two ways to create your repository, a button in the page and a command line invocation, and the command line form begins by exporting the repository name as a variable before using it, which keeps the name in one place for the subsequent commands. The remaining three stages are not in the visible text at all. Two facts about the project's shape do survive, though: the release tags are calendar versions numbered by year and month, one on the first of each month, and the repository ships separate configuration files for a formatter, a hook runner, and the dependency updater. The dependency updater is named in the feature list alongside the automation workflow and the tool manager, and a fourth tool is listed for showing diffs of the two kinds of Flux resource the template emits. A developer directory is tracked for editor settings as well, so the tooling story is spread across four separate files rather than one manifest.
Editorial conclusion
cluster-template suits a homelab operator who already runs Talos elsewhere and wants a complete GitOps starting point rather than a bare cluster, because the component set is opinionated and complete and the configuration is one file rendered by a locked toolchain. Verify five things first. The tool environment needs Python 3.14 or newer with two dependencies pinned to exact versions, so it will not run on an older interpreter. The stage guide is six stages long and only the first three are visible here, the third ending mid-sentence. The advice to set your repository to public is paired with an init step that generates an age key and a deploy key, so read what lands in the tree before you publish it. The hardware section recommends bare metal and then qualifies it twice. And the root task file delegates nearly everything to modules, so the recipes you will actually run are not on the page.
Frequently asked questions
What does onedr0p/cluster-template deploy?
A single Kubernetes cluster running Talos Linux, with Flux syncing from a Git provider of your choice, sops managing secrets, and cloudflared used to reach applications outside your local network. Configuration lives in one TOML file which a template engine renders after a data library has validated and filled in its defaults.
What are the minimum hardware requirements for a cluster-template cluster?
Per node, four cores, sixteen gigabytes of memory, and a 256 gigabyte solid-state or non-volatile system disk, with one row covering both the control plane and worker roles because every node is configured to run workloads. With three or more nodes the guide recommends making three of them controller nodes for a highly available control plane.
Which components does cluster-template install?
Eight, named in the overview: Flux for GitOps, Cilium, cert-manager, spegel, Reloader, Envoy Gateway, external-dns, and cloudflared. The guide also states the prerequisites as knowledge of containers, YAML, Git, and having a domain, with a Cloudflare account needed only for clusters exposed to the public internet.
What secrets does cluster-template generate?
The init recipe is documented as initializing the configuration file, an age key, a deploy key, and a webhook token. The age key is the one that matters most, since it is what decrypts the cluster's secrets. The visible text does not say where these files are written or whether they are excluded from version control.
Which Git providers does cluster-template support?
GitHub, GitLab, Gitea, Forgejo, Codeberg, or a self-hosted server. The GitHub path uses the command line tool to create a repository from the template and clone it. Any other provider means cloning the template at depth one, re-initialising the git repository, and pushing it yourself.
Why does the tool install step fail on cluster-template?
The guide's own note says to unset the GitHub token environment variable and run the commands again, which points at an authenticated request that an existing token breaks. A second note says the tool lock file pins downloads for the platforms listed under one configuration key, so the pinned tool set is platform-limited.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/onedr0p-cluster-template)Star history chart for your README
[](https://hysenlabs.com/projects/onedr0p-cluster-template)Was this useful?